diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml
index 0a09bcc..c11b600 100644
--- a/.github/workflows/ci.yml
+++ b/.github/workflows/ci.yml
@@ -26,13 +26,13 @@ jobs:
run: dotnet tool restore
- name: Restore
- run: dotnet restore ManagedCode.LlmTck.slnx
+ run: dotnet restore ManagedCode.LlmTestServer.slnx
- name: Format
- run: dotnet format ManagedCode.LlmTck.slnx --verify-no-changes --no-restore
+ run: dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore
- name: Build
- run: dotnet build ManagedCode.LlmTck.slnx --configuration Release --no-restore
+ run: dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
- name: Test
run: bash scripts/coverage.sh
@@ -43,9 +43,6 @@ jobs:
- name: Verify installed NuGet consumer
run: python3 scripts/verify-package.py
- - name: Verify release recovery
- run: python3 scripts/test-release.py
-
- name: Upload verification evidence
if: always()
uses: actions/upload-artifact@v7.0.1
@@ -60,3 +57,31 @@ jobs:
with:
name: packages
path: artifacts/packages/*.nupkg
+
+ container-smoke:
+ runs-on: ubuntu-latest
+ steps:
+ - name: Checkout
+ uses: actions/checkout@v7.0.0
+
+ - name: Setup .NET
+ uses: actions/setup-dotnet@v5.4.0
+ with:
+ dotnet-version: 10.0.x
+
+ - name: Publish SDK container to local daemon without registry push
+ run: >-
+ dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj
+ --configuration Release --runtime linux-x64 --self-contained false
+ /t:PublishContainer -p:ContainerImageTag=ci -p:ContainerRuntimeIdentifier=linux-x64
+ -p:UseAppHost=false
+
+ - name: Verify actual container HTTP behavior
+ run: python3 scripts/verify-container.py --image managedcode/llm-test-server:ci
+
+ - name: Upload container verification evidence
+ if: always()
+ uses: actions/upload-artifact@v7.0.1
+ with:
+ name: container-verification
+ path: artifacts/container-verification
diff --git a/.github/workflows/pages.yml b/.github/workflows/pages.yml
new file mode 100644
index 0000000..4124beb
--- /dev/null
+++ b/.github/workflows/pages.yml
@@ -0,0 +1,77 @@
+name: Website
+
+on:
+ pull_request:
+ branches: [main]
+ paths: ['site/**', '.github/workflows/pages.yml']
+ push:
+ branches: [main]
+ paths: ['site/**', '.github/workflows/pages.yml']
+ workflow_run:
+ workflows: [Release]
+ types: [completed]
+ branches: [main]
+ workflow_dispatch:
+
+permissions:
+ contents: read
+
+concurrency:
+ group: pages-${{ github.ref }}
+ cancel-in-progress: false
+
+jobs:
+ validate:
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v7.0.0
+ with:
+ ref: ${{ github.event.workflow_run.head_sha || github.sha }}
+ - uses: actions/setup-node@v7.1.0
+ with:
+ node-version: 24
+ cache: npm
+ cache-dependency-path: site/package-lock.json
+ - name: Install site tooling
+ run: npm ci --prefix site
+ - name: Validate HTML, CSS and JavaScript
+ run: npm run lint --prefix site
+ - name: Build static preview
+ run: npm run build --prefix site
+
+ deploy:
+ if: github.event_name == 'workflow_run' && github.event.workflow_run.conclusion == 'success' && github.event.workflow_run.head_branch == 'main'
+ needs: validate
+ runs-on: ubuntu-latest
+ permissions:
+ contents: read
+ pages: write
+ id-token: write
+ environment:
+ name: github-pages
+ url: ${{ steps.deployment.outputs.page_url }}
+ steps:
+ - uses: actions/checkout@v7.0.0
+ with:
+ ref: ${{ github.event.workflow_run.head_sha || github.sha }}
+ # Select GitHub Actions as the repository Pages source before the first deployment.
+ - name: Require the verified release before publishing the landing page
+ env:
+ GH_TOKEN: ${{ github.token }}
+ run: |
+ version=$(python3 -c 'import xml.etree.ElementTree as e; print(e.parse("Directory.Build.props").findtext(".//Version"))')
+ gh release view "v$version" --json assets --jq '.assets[].name' | grep -qx 'nuget-published.txt'
+ - name: Configure GitHub Pages
+ id: pages
+ uses: actions/configure-pages@v6.0.0
+ - name: Build for canonical Pages URL
+ env:
+ PAGES_BASE_URL: ${{ steps.pages.outputs.base_url }}
+ run: python3 site/build.py --base-url "$PAGES_BASE_URL"
+ - name: Upload static website
+ uses: actions/upload-pages-artifact@v5.0.0
+ with:
+ path: site/dist
+ - name: Deploy website
+ id: deployment
+ uses: actions/deploy-pages@v5.0.1
diff --git a/.github/workflows/release.yml b/.github/workflows/release.yml
index 98b4dab..7f3839d 100644
--- a/.github/workflows/release.yml
+++ b/.github/workflows/release.yml
@@ -21,6 +21,7 @@ concurrency:
jobs:
pack:
+ if: github.ref == 'refs/heads/main'
runs-on: ubuntu-latest
env:
NUGET_API_KEY: ${{ secrets.NUGET_API_KEY }}
@@ -53,15 +54,15 @@ jobs:
- name: Restore
if: ${{ steps.release.outputs.should_release == 'true' }}
- run: dotnet restore ManagedCode.LlmTck.slnx
+ run: dotnet restore ManagedCode.LlmTestServer.slnx
- name: Format
if: ${{ steps.release.outputs.should_release == 'true' }}
- run: dotnet format ManagedCode.LlmTck.slnx --verify-no-changes --no-restore
+ run: dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore
- name: Build
if: ${{ steps.release.outputs.should_release == 'true' }}
- run: dotnet build ManagedCode.LlmTck.slnx --configuration Release --no-restore
+ run: dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
- name: Test
if: ${{ steps.release.outputs.should_release == 'true' }}
@@ -75,10 +76,6 @@ jobs:
if: ${{ steps.release.outputs.should_release == 'true' }}
run: python3 scripts/verify-package.py
- - name: Verify release recovery
- if: ${{ steps.release.outputs.should_release == 'true' }}
- run: python3 scripts/test-release.py
-
- name: Upload verification evidence
if: always()
uses: actions/upload-artifact@v7.0.1
@@ -88,21 +85,68 @@ jobs:
artifacts/coverage
artifacts/package-consumer
- - name: Publish container image
+ - name: Publish and verify standalone SDK container locally
+ if: ${{ steps.release.outputs.should_release == 'true' }}
+ env:
+ IMAGE_TAG: ${{ steps.release.outputs.version }}
+ run: |
+ dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --runtime linux-x64 --self-contained false \
+ /t:PublishContainer -p:ContainerRuntimeIdentifier=linux-x64 \
+ -p:ContainerImageTag="$IMAGE_TAG" -p:UseAppHost=false
+ python3 scripts/verify-container.py --image "managedcode/llm-test-server:$IMAGE_TAG"
+
+ - name: Publish versioned multi-platform SDK container
if: ${{ steps.release.outputs.should_release == 'true' }}
env:
IMAGE_TAG: ${{ steps.release.outputs.version }}
+ GHCR_TOKEN: ${{ github.token }}
run: |
- echo "${{ github.token }}" | docker login ghcr.io -u "$GITHUB_ACTOR" --password-stdin
- docker build \
- -f samples/ManagedCode.LlmTck.Service/Dockerfile \
- -t "ghcr.io/managedcode/llm-tck:$IMAGE_TAG" \
- .
- docker push "ghcr.io/managedcode/llm-tck:$IMAGE_TAG"
-
- - name: Publish packages and finalize release
+ printf '%s' "$GHCR_TOKEN" | docker login ghcr.io -u "$GITHUB_ACTOR" --password-stdin
+ dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --self-contained false /t:PublishContainer \
+ -p:ContainerRegistry=ghcr.io -p:ContainerImageTag="$IMAGE_TAG" \
+ -p:UseAppHost=false
+
+ - name: Verify anonymous public pull and actual container behavior
+ if: ${{ steps.release.outputs.should_release == 'true' }}
+ env:
+ IMAGE_TAG: ${{ steps.release.outputs.version }}
+ run: |
+ python3 scripts/verify-container.py \
+ --image "ghcr.io/managedcode/llm-test-server:$IMAGE_TAG" --anonymous-pull \
+ --require-platform linux/amd64 --require-platform linux/arm64 || {
+ echo "::error::Public container delivery failed. In the managedcode organization package settings for llm-test-server, set package visibility to Public, then rerun this release for the same version. packages:write and public repository visibility alone do not make a GHCR image public."
+ exit 1
+ }
+
+ - name: Upload container verification evidence
+ if: always()
+ uses: actions/upload-artifact@v7.0.1
+ with:
+ name: release-container-verification
+ path: artifacts/container-verification
+
+ - name: Publish packages and create release
if: ${{ steps.release.outputs.should_release == 'true' }}
env:
GH_TOKEN: ${{ github.token }}
TAG_NAME: ${{ steps.release.outputs.tag }}
run: bash scripts/release.sh publish
+
+ - name: Verify actual GitHub and NuGet publication
+ if: ${{ steps.release.outputs.should_release == 'true' }}
+ env:
+ GH_TOKEN: ${{ github.token }}
+ run: python3 scripts/verify-release.py
+
+ - name: Verify public installed NuGet consumer
+ if: ${{ steps.release.outputs.should_release == 'true' }}
+ run: python3 scripts/verify-package.py --public-feed
+
+ - name: Mark verified delivery complete
+ if: ${{ steps.release.outputs.should_release == 'true' }}
+ env:
+ GH_TOKEN: ${{ github.token }}
+ TAG_NAME: ${{ steps.release.outputs.tag }}
+ run: bash scripts/release.sh finalize
diff --git a/.gitignore b/.gitignore
index 3c05a70..34f649d 100644
--- a/.gitignore
+++ b/.gitignore
@@ -15,3 +15,7 @@ coverage.cobertura.xml
*.suo
*.swp
*.tmp
+
+# Launch production materials remain local until owner approval.
+/marketing/
+.playwright-cli
diff --git a/AGENTS.md b/AGENTS.md
index 413f5e0..5d6c1ce 100644
--- a/AGENTS.md
+++ b/AGENTS.md
@@ -1,8 +1,8 @@
-# LLM TCK Contributor Guide
+# LLM Test Server Contributor Guide
## Scope
-This repository builds `ManagedCode.LlmTck`, a deterministic Technology Compatibility Kit for LLM APIs. Treat the runtime, protocol adapters, clients, Aspire integration, docs, and samples as separate package surfaces.
+This repository builds `ManagedCode.LlmTestServer`, a deterministic LLM API mock server for LLM APIs. Treat the runtime, protocol adapters, clients, Aspire integration, docs, and samples as separate package surfaces.
Follows [MCAF](https://mcaf.managed-code.com/).
@@ -60,16 +60,16 @@ Rule format:
## Commands
-- Restore: `dotnet restore ManagedCode.LlmTck.slnx`
-- Build: `dotnet build ManagedCode.LlmTck.slnx --configuration Release --no-restore`
-- Test: `dotnet test --project tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj --configuration Release --no-build --verbosity normal`
+- Restore: `dotnet restore ManagedCode.LlmTestServer.slnx`
+- Build: `dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore`
+- Test: `dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal`
- Pack: `for project in src/*/*.csproj; do dotnet pack "$project" --configuration Release --no-build --output artifacts/packages; done`
- Release: pushing to `main` must start the release workflow; it reads the package version from `Directory.Build.props`, creates the matching `vX.Y.Z` tag and GitHub Release, attaches package artifacts, and publishes NuGet packages only when that version is not already released.
-- Format check: `dotnet format ManagedCode.LlmTck.slnx --verify-no-changes`
+- Format check: `dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes`
- Tool restore: `dotnet tool restore`
- Coverage gate: production code line coverage must stay at or above 90%; measure with coverlet/reportgenerator when coverage expectations change.
- Coverage: `bash scripts/coverage.sh` (maps deterministic CI source paths before collection and enforces 90% total production line coverage).
-- Quality gate: `dotnet format ManagedCode.LlmTck.slnx --verify-no-changes --no-restore && dotnet build ManagedCode.LlmTck.slnx --configuration Release --no-restore && dotnet test --project tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj --configuration Release --no-build --verbosity normal && git diff --check`
+- Quality gate: `dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore && dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore && dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal && git diff --check`
`global.json` opts `dotnet test` into `Microsoft.Testing.Platform`; do not add VSTest-specific logger arguments to normal test commands.
@@ -77,13 +77,33 @@ Rule format:
### Likes
+- In marketing avatar videos, keep the presenter addressing the camera in frontal shots without side profiles or sustained off-camera gaze. Preserve natural blinking, small eye movements and relaxed facial/head motion; camera contact must feel conversational rather than frozen or tense.
+- Match the avatar video's background, lighting and wardrobe colours to the actual website and product screenshots so all launch assets form one coherent visual style when edited together.
+- Ship one complete v1.0.0 launch batch on a separate branch; the owner performs the merge. Do not merge, publish intermediate versions, or trigger releases before the complete product and launch preparation are ready.
+- Publish the product landing page through GitHub Pages using the dashboard visual language and shared styles/components where practical; substantiate product sections with real server/browser screenshots and demo recordings.
+- Keep README.md product-first: what LLM Test Server is, why to use it, what to do with it, and where to go next, in plain language. Move deep technical detail into docs/ and link to it. Every code sample must use real public APIs and be compile-checked against the current packages before it ships; never invent APIs or pad the README with technical noise.
+- Lead README, landing and launch material with visually interesting captures (token flow, insights charts), not plain list or table screenshots.
+- Keep the landing page polished, clear and fully responsive: showcase every major capability (provider matrix, request inspector, token analytics, tools/conversations, streaming, faults, Aspire/Docker setup) with crafted visual elements, not plain text blocks. Review it at desktop, tablet and mobile widths after every change.
+- Make the dashboard visually rich with donut/pie charts across many dimensions of recorded traffic (providers, models, outcomes, operations, latency, tokens, cache, tool usage), each with a value-and-share legend; stable entity colors across filters.
+- Use one distinctive, symbol-only product mark (no letter monogram) consistently for the launch thumbnail, favicons, dashboard header and OG/social images. It must not resemble the owner's other brands: no brackets around a square or token (that is the Prostir.build mark), and check prostir.build and managed-code.com marks before proposing one.
+- The product website lives at https://llmtest.managed-code.com; use that canonical URL in site metadata, README, launch listings and social posts.
+- Position the product as .NET-first but usable from any stack: the prebuilt Docker image plus the management API work for teams outside .NET, so launch copy and video must say so.
+- Keep launch marketing drafts, generated images, videos, screenshots and production files under marketing/ and leave that directory uncommitted until the owner authorizes publication.
+- Deliver both NuGet packages and a publicly pullable prebuilt Docker image, configurable through the management API.
+- Build and publish container images through the .NET SDK container targets (`dotnet publish /t:PublishContainer`); do not use Dockerfile/docker build as the distribution build mechanism.
+
- Keep checked-in UI screenshots synchronized with the current rendered product; after visible dashboard changes, refresh and verify the affected images in a real browser before commit and push.
- When token usage is requested, count response tokens with `tiktoken` and include the measured usage in replies; if `tiktoken` is unavailable, report that blocker instead of guessing token counts.
- Token usage workflow changes need executable code and tests, not only contributor-guide documentation, so callers can verify usage accounting behavior directly.
### Dislikes
-- Do not introduce real-LLM toggles, external project environment variable names, or WA.Storied-specific constants into this repository; LlmTck tests and samples must remain deterministic, repo-owned, and free of cross-project naming leaks.
+- Treat ManagedCode.LlmTestServer as a completely new brand: remove all old project/package/type/configuration names, legacy aliases, and backward-compatibility paths. Do not provide a migration layer or preserve old branded diagnostic codes, fixture IDs, package identities, or release/deprecation machinery.
+
+- Do not ship template-looking or AI-generic UI: no colored left-border cards or chat bubbles, no unbalanced card compositions with lopsided visuals, no gradient-glow icon tiles, no walls of numbers where a diagram would explain more. Study high-quality references (for example Dribbble analytics dashboards) before visual work, keep every card's visual balanced and centered on one idea, and keep copy short and clear.
+- Do not mention competing products in README, documentation, source, tests, or other repository artifacts; describe our own contracts and capabilities directly.
+- Keep only integration tests that start the server and verify real HTTP/provider SDK behavior. Do not add or retain unit tests, fake clients, source/document scans, reflection-based test guards, or assertions about implementation fragments. Exercise every supported API and parameter, streaming mode, error boundary, and complete tool/conversation flow through the running server.
+- Do not introduce real-LLM toggles, external project environment variable names, or WA.Storied-specific constants into this repository; LlmTestServer tests and samples must remain deterministic, repo-owned, and free of cross-project naming leaks.
## Code Quality Skills
@@ -98,39 +118,45 @@ Rule format:
## Design Rules
+- Identify TypeSafe as the provider and Jev as its model family in user-facing documentation; name System One as the native API/protocol and make its package, route and typed client discoverable instead of hiding TypeSafe behind the protocol name.
+
+- Tool fixtures must explicitly simulate distinct errors, timeouts, internal failures or connection crashes, literal null, empty/no result, and content-filter refusals. Keep tool-result failures distinct from provider/transport failures, expose the observed outcome in diagnostics, and verify recovery plus conversation/cache state through real server integrations; expected faults must not be rejected as invalid mock configuration.
+
- Before claiming that all review findings are fixed, recheck every finding against final behavior and tests; report removed capability claims and temporary mitigations separately from implemented functionality.
- Prefer official .NET packages and abstractions before writing custom protocol code.
-- Tests that fake `IChatClient` should use the dotnet/extensions pattern: a tiny fake class with delegate callbacks, not Moq or NSubstitute.
-- Keep provider wire formats in provider packages such as `ManagedCode.LlmTck.OpenAI`; keep deterministic scenario behavior in `ManagedCode.LlmTck`.
-- Keep the provider package matrix explicit. Do not ship the TCK as only OpenAI-compatible; maintain package surfaces for OpenAI, Azure OpenAI, Microsoft Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere, Amazon Bedrock, OpenRouter, DeepSeek, and Perplexity.
+- Provider compatibility tests must use the official provider SDK clients against the running server wherever an official client exists. Raw HTTP supplements malformed-request, exact wire-format and unsupported-boundary checks; it is not sufficient proof for supported success, streaming, tool or conversation flows. Do not substitute fake `IChatClient` implementations or direct runtime/builder calls for integration behavior.
+- Keep provider wire formats in provider packages such as `ManagedCode.LlmTestServer.OpenAI`; keep deterministic scenario behavior in `ManagedCode.LlmTestServer`.
+- Keep the provider package matrix explicit. Do not ship the Test Server as only OpenAI-compatible; maintain package surfaces for OpenAI, Azure OpenAI, Microsoft Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere, Amazon Bedrock, OpenRouter, DeepSeek, and Perplexity.
- Azure OpenAI and Microsoft Foundry compatibility must be proven with official Azure SDK clients, not only raw HTTP requests.
- Azure SDK clients must select their own API version. Do not pin a dated version in consumers or SDK compatibility tests to satisfy the emulator; deployment routes must enforce their documented supported Azure versions and reject unknown versions, including syntactically valid future dates. Do not weaken server validation to make client tests pass.
-- Built-in defaults, samples, and scenario examples must use official provider model IDs such as `gpt-4.1-mini`, `text-embedding-3-small`, `gpt-image-1`, and `gpt-4o-mini-tts`; do not use synthetic `llm-tck-*` model IDs for normal fixtures.
+- Source current built-in model IDs and capability defaults from the original official provider SDK model definitions and current official model documentation. Prefer SDK model identifiers in SDK tests; do not invent models or treat stale hand-maintained string constants as an authoritative catalogue. Keep custom fixture models explicitly configurable.
- Keep custom `AddModel(...)` support, but expose typed convenience APIs for common official fixture models so callers do not have to hand-type model IDs for standard chat, embedding, image, and audio setup.
- Reasoning-capable models must carry deterministic reasoning-token usage through runtime summaries and provider response usage details; do not flatten reasoning usage into ordinary visible output tokens only.
- Prompt-cache accounting is provider-specific: expose cache read/write usage for every provider surface that has a documented cache contract, and report no cache usage for providers or operations without one.
- Compatibility tag values in C# code must come from named constants everywhere they are assigned or asserted, so `CompatibilityTags` cannot drift through inline string literals.
-- Provider `ApiContract` operation id values and behavior-evidence operation ids in C# must come from `LlmTckProviderOperationIds`; do not type raw operation-id strings such as `videos.content.retrieve`.
-- The client package must expose a universal pre-test configuration API so tests can spawn a client, reset or configure the hosted TCK, load models, auth, datasets, scenarios, scripted errors, embeddings, images, and audio fixtures without hand-authoring raw DTOs.
+- Provider `ApiContract` operation id values and behavior-evidence operation ids in C# must come from `LlmTestServerProviderOperationIds`; do not type raw operation-id strings such as `videos.content.retrieve`.
+- The client package must expose a universal pre-test configuration API so tests can spawn a client, reset or configure the hosted Test Server, load models, auth, datasets, scenarios, scripted errors, embeddings, images, and audio fixtures without hand-authoring raw DTOs.
- The browser admin panel must be served from `/`, and runtime control APIs must use `/admin-api/...` paths; do not add hidden or aliased admin/control routes for reset, configure, models, assertions, or operator UI.
-- The browser admin panel must be implemented as Blazor server-side components in `ManagedCode.LlmTck.Hosting`; do not serve it from a static HTML string endpoint, and use component state plus `StateHasChanged()` for refresh behavior instead of client-side polling fetch code.
+- The browser admin panel must be implemented as Blazor server-side components in `ManagedCode.LlmTestServer.Hosting`; do not serve it from a static HTML string endpoint, and use component state plus `StateHasChanged()` for refresh behavior instead of client-side polling fetch code.
- The browser admin panel is a full-viewport debugging surface, not a narrow landing page; show models/fixtures, actions, calls/requests, responses, provider/control API endpoints, assertions, and runtime events as separate grouped, inspectable areas so users can inspect each part without digging through one collapsed feed.
- The browser admin dashboard must be request-centric: use a scannable table with one entry per provider request, show provider and model at a glance, and let operators inspect the full request, response, multi-turn conversation, cache accounting, token usage, timing, status, and related metadata without reconstructing a call from separate feeds; keep retention explicitly bounded and visibly mark the exceptional payload that exceeds that diagnostic budget.
+- Show request and explicitly scoped conversation analytics from recorded traffic as visual token composition, not text tables and footnotes: split input tokens by system prompt, user, assistant, tool calls, tool results and tool schemas with the runtime tokenizer so the parts reconcile exactly with reported input, then show cache read/write/uncached and output/reasoning through flow (Sankey) and donut charts with value-and-share legends, plus per-request context growth for conversations. Keep reasoning/cache subsets out of double-counted totals, distinguish missing usage from zero, and disclose retention limits briefly instead of in walls of caveat text.
- Keep the request inbox visually primary and easy to scan; do not compress it beside a narrow, endlessly tall inspector. Constrain long conversations and payloads to independent scroll regions, collapse oversized system/tool content by default while keeping it expandable, and validate the resulting hierarchy with realistic long multi-turn data at desktop, tablet, and mobile sizes.
- Keep the dashboard's useful horizontal master-detail structure, but use an Apple-inspired content-first visual language rather than Material or Fluent styling: quiet system typography, generous clean surfaces, restrained separators and status color, sidebar depth only where it clarifies hierarchy, and no grid of badges or boxed metrics. Keep the filter/navigation rail visible at ordinary laptop widths and the selected response visible in the first reading-pane viewport; on narrow mobile screens use an explicit list-to-detail transition with a Back action.
-- Render JSON payloads as properly indented code with an SF Mono-style font and preserve readable Unicode characters instead of exposing serializer escape sequences such as `\u0027`.
+- Every chart mark, bar, segment and dot in the dashboard needs a styled hover tooltip with the label, value and share; do not rely on slow native title tooltips.
+- Render JSON payloads as properly indented, syntax-highlighted code (keys, strings, numbers, literals) with an SF Mono-style font, and preserve readable Unicode characters instead of exposing serializer escape sequences such as `\u0027`.
- Use Microsoft Fluent UI Blazor primitives for dashboard overlays and dismissible controls, but theme them to the dashboard's Apple-inspired visual language instead of adopting stock Fluent styling. Popovers must close on outside click, Escape, and completed actions. Blend Prostir.build's restrained glass, lime selection rail, and technical polish with managed-code.com's warm canvas, ink typography, and tiny coral-to-magenta accents without copying either site's branding or marketing-page layout.
- The browser admin panel must auto-refresh by default every 15 seconds, but do not add visible countdown UI unless the user explicitly asks for it.
-- Provider APIs must be explicitly namespaced by provider, such as `/openai`, `/anthropic`, `/gemini`, or `/azure-openai`; do not expose generic root `/v1/*` provider routes that make the TCK look like only the OpenAI API.
+- Provider APIs must be explicitly namespaced by provider, such as `/openai`, `/anthropic`, `/gemini`, or `/azure-openai`; do not expose generic root `/v1/*` provider routes that make the Test Server look like only the OpenAI API.
- Aspire examples must show endpoint retrieval from the Aspire resource (`GetEndpoint("http")` or `CreateHttpClient(...)`) and API key wiring so users see the complete integration path.
-- Aspire sample services must use `ManagedCode.LlmTck.Hosting` service-defaults methods such as `AddServiceDefaults()` and `MapDefaultEndpoints()` for health/liveness wiring; do not create a separate ServiceDefaults sample project, and do not hand-roll `app.MapGet("/health", ...)` or placeholder root status endpoints in sample `Program.cs` files.
-- Aspire integration must expose a package-owned `builder.AddLlmTck()` entry point so consumers can install the Aspire NuGet package and add the TCK without caller-supplied project paths or `Projects.*` metadata types.
-- `builder.AddLlmTck()` must be .NET/Aspire-first and must not require Docker or a container runtime by default; container-backed hosting may exist only as an explicit opt-in API.
+- Aspire sample services must use `ManagedCode.LlmTestServer.Hosting` service-defaults methods such as `AddServiceDefaults()` and `MapDefaultEndpoints()` for health/liveness wiring; do not create a separate ServiceDefaults sample project, and do not hand-roll `app.MapGet("/health", ...)` or placeholder root status endpoints in sample `Program.cs` files.
+- Aspire integration must expose a package-owned `builder.AddLlmTestServer()` entry point so consumers can install the Aspire NuGet package and add the Test Server without caller-supplied project paths or `Projects.*` metadata types.
+- `builder.AddLlmTestServer()` must be .NET/Aspire-first and must not require Docker or a container runtime by default; container-backed hosting may exist only as an explicit opt-in API.
- Aspire integration must start an Aspire AppHost in tests before a change is considered covered, with the AppHost model built directly in test code or a test fixture.
- Aspire test coverage should build the AppHost directly inside the test code or fixture; do not add a standalone `Obhost`/test AppHost file just to host Aspire for tests.
- Aspire tests and samples must resolve service/provider URLs from the Aspire resource endpoint allocated by the AppHost; do not hard-code `127.0.0.1`, `localhost`, ports, or invented provider endpoints in configuration.
-- Do not add an Aspire provider-endpoint setter to `ManagedCode.LlmTck.Aspire`; consumers must use the endpoint exposed by the `LlmTckResource`.
+- Do not add an Aspire provider-endpoint setter to `ManagedCode.LlmTestServer.Aspire`; consumers must use the endpoint exposed by the `LlmTestServerResource`.
- Do not add Aspire compatibility environment flags, sample-service config echoes, or fluent compatibility methods unless they drive real route/runtime behavior; prove compatibility through actual provider clients instead.
- Provider API compatibility must be doc-backed: every claimed provider method, route, streaming mode, modality, and API-version constraint must be represented in a checked-in contract with official documentation links and covered by tests before the provider package claims support.
- Provider API verification must cover the full claimed provider matrix: every implemented `ApiContract` operation for every provider needs behavior-test evidence, and fixes that touch provider compatibility must rerun the provider contract/evidence tests plus the full quality gate before closeout.
@@ -139,26 +165,26 @@ Rule format:
## Ownership Map
-- `src/ManagedCode.LlmTck`: provider-neutral runtime, scenarios, assertions, and model catalog.
-- `src/ManagedCode.LlmTck.SystemOne`: Jev/Kev native SystemOne decision contracts and compatibility profile.
-- `src/ManagedCode.LlmTck.Cloudflare`: Workers AI Clef/flash native decision envelopes, validation and compatibility profile.
-- `src/ManagedCode.LlmTck.OpenAI`: OpenAI-compatible request/response shapes and mapping.
-- `src/ManagedCode.LlmTck.AzureOpenAI`: Azure OpenAI compatibility profile and future Azure OpenAI wire contracts.
-- `src/ManagedCode.LlmTck.Foundry`: Microsoft Foundry compatibility profile and future Foundry wire contracts.
-- `src/ManagedCode.LlmTck.Anthropic`: Anthropic Messages compatibility profile and future Anthropic wire contracts.
-- `src/ManagedCode.LlmTck.Gemini`: Gemini compatibility profile and future Gemini wire contracts.
-- `src/ManagedCode.LlmTck.Groq`: Groq compatibility profile and future Groq wire contracts.
-- `src/ManagedCode.LlmTck.Mistral`: Mistral compatibility profile and future Mistral wire contracts.
-- `src/ManagedCode.LlmTck.Ollama`: Ollama compatibility profile and future Ollama wire contracts.
-- `src/ManagedCode.LlmTck.Cohere`: Cohere compatibility profile and future Cohere wire contracts.
-- `src/ManagedCode.LlmTck.Bedrock`: Amazon Bedrock compatibility profile and future Bedrock wire contracts.
-- `src/ManagedCode.LlmTck.OpenRouter`: OpenRouter compatibility profile and future OpenRouter wire contracts.
-- `src/ManagedCode.LlmTck.DeepSeek`: DeepSeek compatibility profile and future DeepSeek wire contracts.
-- `src/ManagedCode.LlmTck.Perplexity`: Perplexity compatibility profile and future Perplexity wire contracts.
-- `src/ManagedCode.LlmTck.Hosting`: ASP.NET Core provider and control endpoints.
-- `src/ManagedCode.LlmTck.Client`: control client and `Microsoft.Extensions.AI` clients.
-- `src/ManagedCode.LlmTck.Aspire`: Aspire AppHost extension methods.
+- `src/ManagedCode.LlmTestServer`: provider-neutral runtime, scenarios, assertions, and model catalog.
+- `src/ManagedCode.LlmTestServer.SystemOne`: Jev/Kev native SystemOne decision contracts and compatibility profile.
+- `src/ManagedCode.LlmTestServer.Cloudflare`: Workers AI Clef/flash native decision envelopes, validation and compatibility profile.
+- `src/ManagedCode.LlmTestServer.OpenAI`: OpenAI-compatible request/response shapes and mapping.
+- `src/ManagedCode.LlmTestServer.AzureOpenAI`: Azure OpenAI compatibility profile and future Azure OpenAI wire contracts.
+- `src/ManagedCode.LlmTestServer.Foundry`: Microsoft Foundry compatibility profile and future Foundry wire contracts.
+- `src/ManagedCode.LlmTestServer.Anthropic`: Anthropic Messages compatibility profile and future Anthropic wire contracts.
+- `src/ManagedCode.LlmTestServer.Gemini`: Gemini compatibility profile and future Gemini wire contracts.
+- `src/ManagedCode.LlmTestServer.Groq`: Groq compatibility profile and future Groq wire contracts.
+- `src/ManagedCode.LlmTestServer.Mistral`: Mistral compatibility profile and future Mistral wire contracts.
+- `src/ManagedCode.LlmTestServer.Ollama`: Ollama compatibility profile and future Ollama wire contracts.
+- `src/ManagedCode.LlmTestServer.Cohere`: Cohere compatibility profile and future Cohere wire contracts.
+- `src/ManagedCode.LlmTestServer.Bedrock`: Amazon Bedrock compatibility profile and future Bedrock wire contracts.
+- `src/ManagedCode.LlmTestServer.OpenRouter`: OpenRouter compatibility profile and future OpenRouter wire contracts.
+- `src/ManagedCode.LlmTestServer.DeepSeek`: DeepSeek compatibility profile and future DeepSeek wire contracts.
+- `src/ManagedCode.LlmTestServer.Perplexity`: Perplexity compatibility profile and future Perplexity wire contracts.
+- `src/ManagedCode.LlmTestServer.Hosting`: ASP.NET Core provider and control endpoints.
+- `src/ManagedCode.LlmTestServer.Client`: control client and `Microsoft.Extensions.AI` clients.
+- `src/ManagedCode.LlmTestServer.Aspire`: Aspire AppHost extension methods.
- `samples`: runnable AppHost and service sample.
-- `tests`: TUnit unit, endpoint, client, and Aspire integration coverage.
+- `tests`: TUnit server API, client SDK, and Aspire integration coverage.
- `docs`: architecture, feature specs, ADRs, and test inventory.
- `site`: static public landing page.
diff --git a/Directory.Build.props b/Directory.Build.props
index 8e6f0a5..69e8433 100644
--- a/Directory.Build.props
+++ b/Directory.Build.props
@@ -18,13 +18,13 @@
ManagedCodeManagedCode
- ManagedCode.LlmTck
+ ManagedCode.LlmTestServerGitHub
- https://github.com/managedcode/LlmTck
- https://github.com/managedcode/LlmTck
+ https://github.com/managedcode/LlmTestServer
+ https://github.com/managedcode/LlmTestServerMITREADME.md
- llm;tck;testing;aspire;openai-compatible;azure-openai;anthropic;gemini;groq;mistral;foundry;ai;dotnet;jev;typesafe;system-one;decision-models;multimodal
+ llm;test-server;testing;aspire;openai-compatible;azure-openai;anthropic;gemini;groq;mistral;foundry;ai;dotnet;jev;typesafe;system-one;decision-models;multimodaltruetruetrue
diff --git a/Directory.Packages.props b/Directory.Packages.props
index 6de6c2e..fed354e 100644
--- a/Directory.Packages.props
+++ b/Directory.Packages.props
@@ -4,6 +4,8 @@
+
+
diff --git a/ManagedCode.LlmTck.slnx b/ManagedCode.LlmTck.slnx
deleted file mode 100644
index 71cbd02..0000000
--- a/ManagedCode.LlmTck.slnx
+++ /dev/null
@@ -1,30 +0,0 @@
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
diff --git a/ManagedCode.LlmTestServer.slnx b/ManagedCode.LlmTestServer.slnx
new file mode 100644
index 0000000..6f76531
--- /dev/null
+++ b/ManagedCode.LlmTestServer.slnx
@@ -0,0 +1,30 @@
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
diff --git a/README.md b/README.md
index d1861e0..21a9d0f 100644
--- a/README.md
+++ b/README.md
@@ -1,1052 +1,275 @@
-# LLM Technology Compatibility Kit
-
-[](https://github.com/managedcode/LlmTck/actions/workflows/ci.yml)
-[](https://github.com/managedcode/LlmTck/actions/workflows/release.yml)
-[](https://www.nuget.org/packages/ManagedCode.LlmTck)
-[](https://www.nuget.org/packages/ManagedCode.LlmTck)
-[](LICENSE)
-
-`ManagedCode.LlmTck` is a deterministic Technology Compatibility Kit for LLM APIs.
-It gives tests a local provider-compatible server that can be hosted by Aspire,
-scripted with explicit scenarios, and called through regular HTTP, official SDKs,
-or `Microsoft.Extensions.AI`.
-
-The hosted surface is provider-namespaced. OpenAI-compatible routes live under
-`/openai`, Azure OpenAI under `/azure-openai`, Microsoft Foundry under
-`/microsoft-foundry`, Anthropic Messages under `/anthropic`, and every other
-provider family uses its own namespace. Provider packages carry doc-backed API
-contracts, and `ManagedCode.LlmTck.Hosting` only claims routes that are mapped by
-`MapLlmTck()` and covered by tests.
-
-Use it when a test needs to prove what an application sends to an LLM provider,
-script deterministic provider responses, exercise retry/error/model-routing paths,
-or assert that no unexpected LLM calls occurred. When a bearer token is configured,
-both provider endpoints and `/admin-api/*` control endpoints require it.
-
-## Jev / TypeSafe System One
-
-Jev is supported through its native System One API, including Jev 1.14 image assets
-and bounding boxes. The emulator accepts JSON base64 and multipart PNG/JPEG uploads,
-structured instructions and criteria, mixed `noul`/`choice`/`score`/`box` batches,
-native confidence, usage and provider-resolved model versions. Image and box requests
-require `TypeSafe-Danger-Zone-Images: true`; long-context requests can explicitly send
-`TypeSafe-Danger-Zone-Long-Context: true`. It uses deterministic fixtures and never
-calls a production model or estimates image tokens.
-
-- Native TCK route: `POST /systemone/v1/systemone`.
-- Contracts: `ManagedCode.LlmTck.SystemOne`.
-- Typed client: `LlmTckClient.CreateSystemOneClient()` from `ManagedCode.LlmTck.Client`.
-- Register `jev-1.14.0` or `jev-preview` with `AddDecisionModel(id, LlmTckDecisionProvider.TypeSafe)`.
-- [Jev 1.14 guide and limits](docs/Features/Jev114.md), [native decision fixtures](#native-decision-api-fixtures),
- [official images API](https://docs.typesafe.ai/images).
-
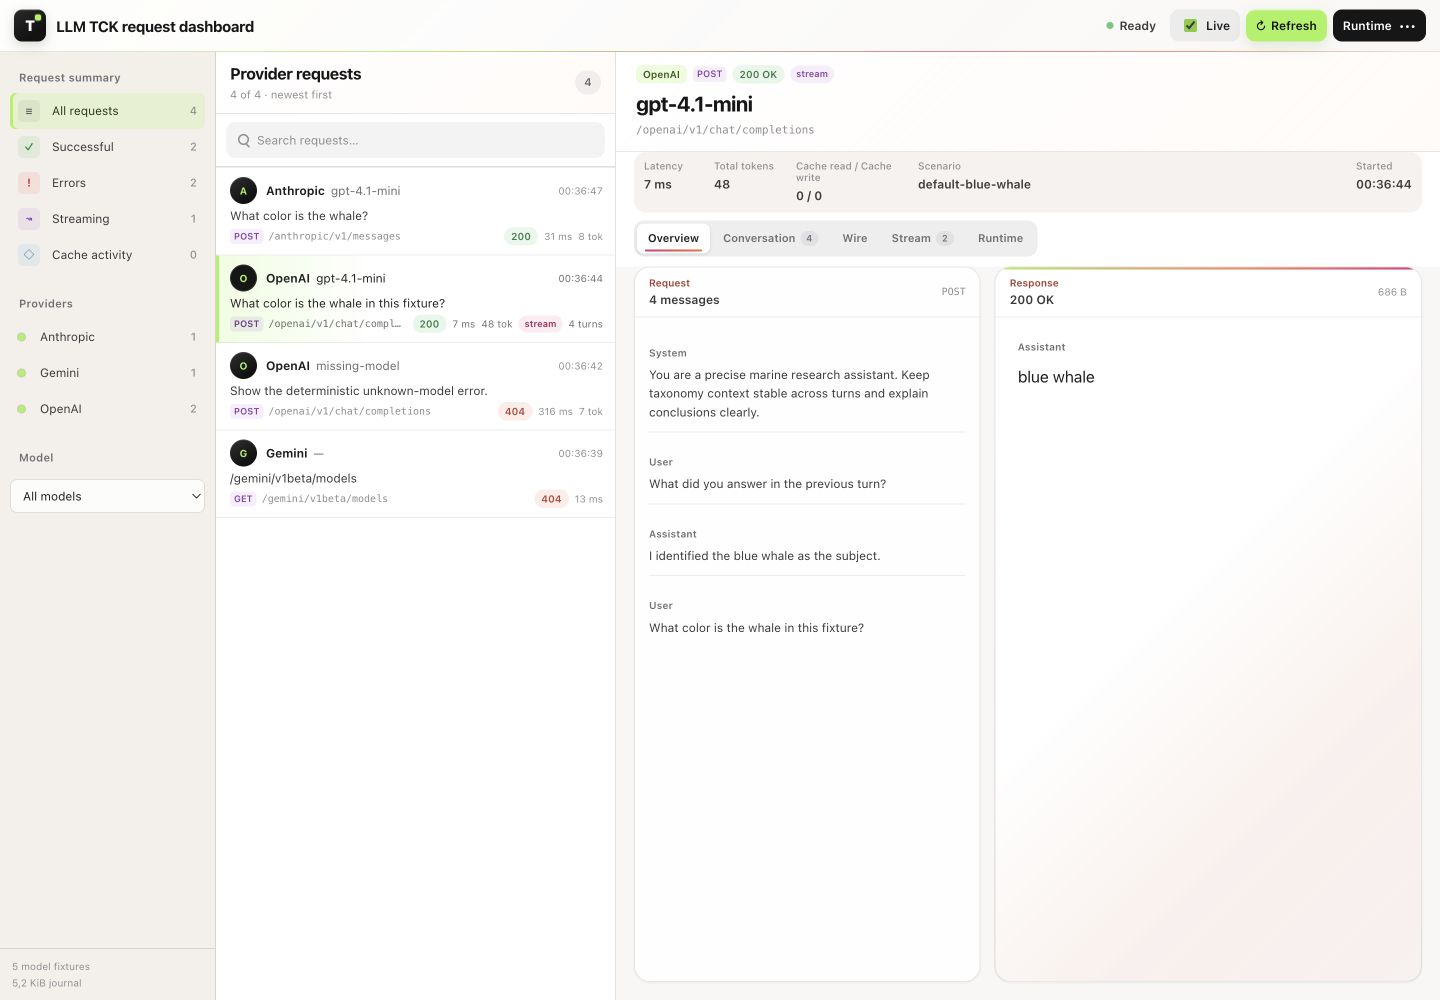
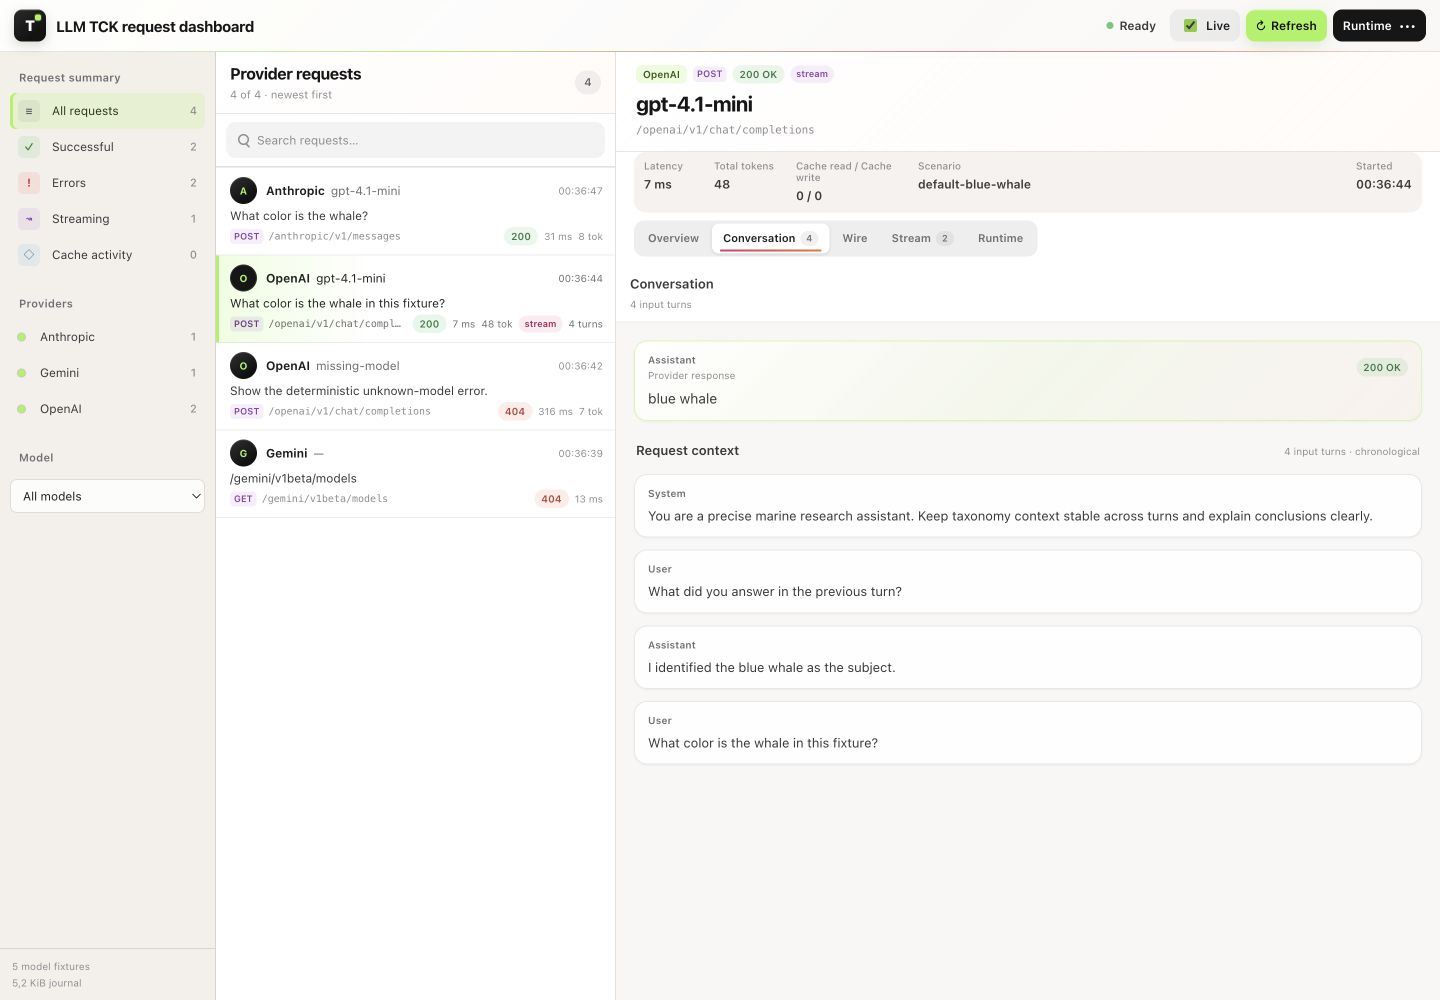
-## Request Dashboard
-
-The Blazor dashboard at `/` is an operator-focused request inbox. It keeps provider,
-model, status, latency, token/cache usage, multi-turn context, sanitized wire payloads,
-stream chunks, and the deterministic runtime result together for each request.
-
-
-
-| Conversation timeline | Runtime diagnostics |
-| --- | --- |
-|  | 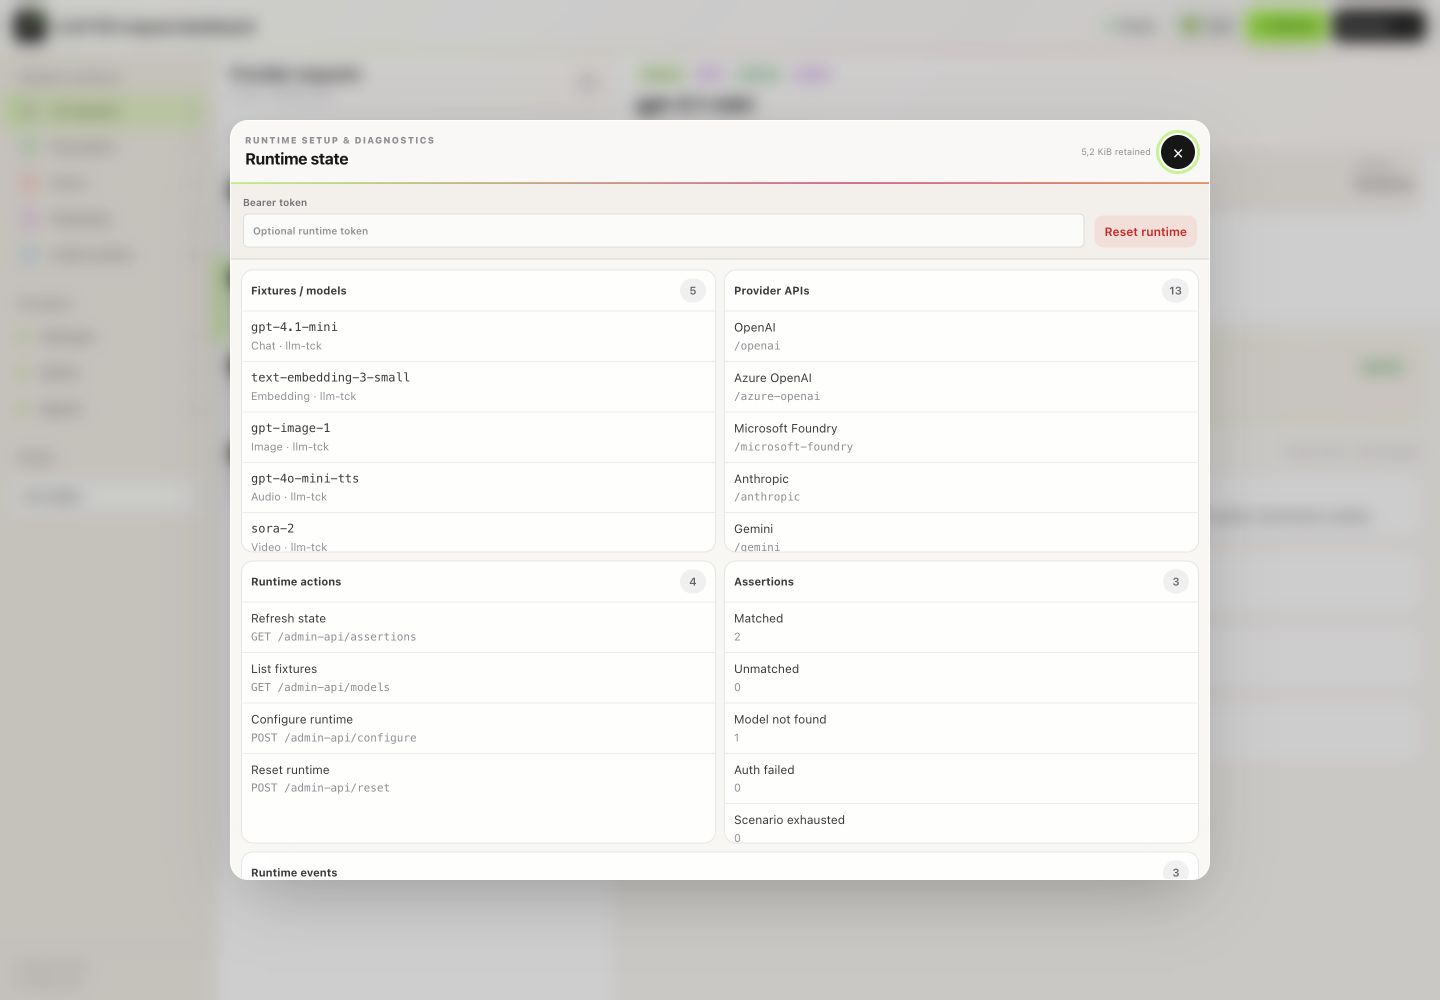 |
-
-## Packages
-
-Package links open the latest stable release on NuGet; badges update automatically.
-
-| Package | Latest version | Downloads | Description |
-| --- | --- | --- | --- |
-| [ManagedCode.LlmTck](https://www.nuget.org/packages/ManagedCode.LlmTck) | [](https://www.nuget.org/packages/ManagedCode.LlmTck) | [](https://www.nuget.org/packages/ManagedCode.LlmTck) | Provider-neutral scenario runtime and assertion state. |
-| [ManagedCode.LlmTck.OpenAI](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenAI) | OpenAI-compatible wire contracts. |
-| [ManagedCode.LlmTck.AzureOpenAI](https://www.nuget.org/packages/ManagedCode.LlmTck.AzureOpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.AzureOpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.AzureOpenAI) | Azure OpenAI compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Foundry](https://www.nuget.org/packages/ManagedCode.LlmTck.Foundry) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Foundry) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Foundry) | Microsoft Foundry compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Anthropic](https://www.nuget.org/packages/ManagedCode.LlmTck.Anthropic) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Anthropic) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Anthropic) | Anthropic Messages compatibility profile and wire contracts. |
-| [ManagedCode.LlmTck.Gemini](https://www.nuget.org/packages/ManagedCode.LlmTck.Gemini) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Gemini) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Gemini) | Gemini compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Groq](https://www.nuget.org/packages/ManagedCode.LlmTck.Groq) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Groq) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Groq) | Groq compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Mistral](https://www.nuget.org/packages/ManagedCode.LlmTck.Mistral) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Mistral) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Mistral) | Mistral compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Ollama](https://www.nuget.org/packages/ManagedCode.LlmTck.Ollama) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Ollama) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Ollama) | Ollama compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Cohere](https://www.nuget.org/packages/ManagedCode.LlmTck.Cohere) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Cohere) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Cohere) | Cohere compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Bedrock](https://www.nuget.org/packages/ManagedCode.LlmTck.Bedrock) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Bedrock) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Bedrock) | Amazon Bedrock compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.OpenRouter](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenRouter) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenRouter) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.OpenRouter) | OpenRouter compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.DeepSeek](https://www.nuget.org/packages/ManagedCode.LlmTck.DeepSeek) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.DeepSeek) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.DeepSeek) | DeepSeek compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.Perplexity](https://www.nuget.org/packages/ManagedCode.LlmTck.Perplexity) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Perplexity) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Perplexity) | Perplexity compatibility profile and future wire contracts. |
-| [ManagedCode.LlmTck.SystemOne](https://www.nuget.org/packages/ManagedCode.LlmTck.SystemOne) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.SystemOne) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.SystemOne) | Native Jev/Kev SystemOne decision contracts. |
-| [ManagedCode.LlmTck.Cloudflare](https://www.nuget.org/packages/ManagedCode.LlmTck.Cloudflare) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Cloudflare) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Cloudflare) | Cloudflare Workers AI Clef/flash decision envelopes and validation. |
-| [ManagedCode.LlmTck.Hosting](https://www.nuget.org/packages/ManagedCode.LlmTck.Hosting) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Hosting) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Hosting) | ASP.NET Core endpoint mapping. |
-| [ManagedCode.LlmTck.Client](https://www.nuget.org/packages/ManagedCode.LlmTck.Client) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Client) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Client) | Control client plus `IChatClient`, `IEmbeddingGenerator>`, and `IImageGenerator` implementations. |
-| [ManagedCode.LlmTck.Aspire](https://www.nuget.org/packages/ManagedCode.LlmTck.Aspire) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Aspire) | [](https://www.nuget.org/packages/ManagedCode.LlmTck.Aspire) | Aspire AppHost extension methods. |
-
-## Current Functionality
-
-This is the currently implemented behavior, not future intent:
-
-| Surface | What works now |
-| --- | --- |
-| Hosting | `builder.Services.AddLlmTck(...)` registers one deterministic runtime; `app.MapLlmTck()` maps the Blazor server-side browser panel at `/`, JSON control endpoints under `/admin-api`, and provider-namespaced HTTP routes. |
-| Runtime configuration | Configure at host startup, through `LlmTckClient.ConfigureAsync(...)`, or through `POST /admin-api/configure`. Configuration replaces the current runtime state and resets assertions, scenario positions, fault counters, and prompt-cache entries. |
-| Reset | `ResetAsync()` and `POST /admin-api/reset` keep the current models/scenarios/fixtures but clear assertion events, scenario response positions, rate-limit counters, and prompt-cache entries. |
-| Models | Default models use official fixture IDs for chat, embeddings, images, audio, and video. Typed helpers register broader OpenAI model families, and `AddModel(...)` supports custom deployment or provider IDs. Model kind is enforced on every route. |
-| Chat scenarios | Contains matching, exact prompt matching, queued responses, streaming chunks, scripted errors, delayed responses, cancellation-safe queues, and scenario-specific bearer tokens are implemented. |
-| Modalities | Chat, embeddings, image generation/edit/variation, audio speech/transcription/translation, OpenAI/Azure video, Gemini long-running video/file output, and Bedrock text/embedding/image invoke shapes return deterministic fixtures. |
-| Provider matrix | OpenAI, Azure OpenAI, Microsoft Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere, Amazon Bedrock, OpenRouter, DeepSeek, and Perplexity are exposed under explicit provider namespaces. Each hosted operation is represented in a provider `ApiContract` and behavior evidence tests. |
-| SDK clients | Official OpenAI, Azure OpenAI, Azure AI Inference / Foundry, Amazon Bedrock, and `Microsoft.Extensions.AI` clients can call the hosted provider routes. The client package also creates control, chat, embedding, image, and audio clients with the same bearer token. |
-| Auth | A global bearer token protects provider and `/admin-api/*` endpoints. Anthropic `x-api-key` and Azure `api-key` headers are accepted as provider-native ways to pass the same token. Scenarios can add their own bearer-token requirement. |
-| Fault simulation | Provider-neutral rate-limit and content-filter simulation flow through every provider family and return provider-shaped errors. Scripted per-scenario failures remain available for exact test paths. |
-| Assertions | `/admin-api/assertions` returns counters plus every runtime event with request preview, response/error text, model id, scenario id, event kind, and deterministic usage. |
-| Usage accounting | Input, output, reasoning, total, cached-input, and cache-write token values are computed deterministically and projected into provider-specific response envelopes when that provider surface documents usage fields. |
-| Browser panel | `/` shows models/fixtures, actions, control and provider endpoint groups, grouped runtime events, captured requests, captured responses, counters, and per-event usage. It auto-refreshes every 15 seconds using Blazor component state and `StateHasChanged()`. |
-| Aspire | `builder.AddLlmTck()` starts the packaged .NET service without Docker by default; `WithApiKey(...)` wires auth, `GetHttpEndpoint()` and provider-specific endpoint helpers expose URLs, and `AddLlmTckContainer()` is an explicit container opt-in. |
-
-## Provider Packages
-
-Provider packages keep vendor-specific protocol and compatibility metadata out of the provider-neutral runtime. The package surface exists now so applications can select a provider family explicitly; provider-specific DTOs and endpoint mappings are added inside each package as support grows.
-
-| Package | Provider ID | Protocol family | Primary hosted route |
-| --- | --- | --- | --- |
-| `ManagedCode.LlmTck.OpenAI` | `openai` | OpenAI | `/openai/v1` |
-| `ManagedCode.LlmTck.AzureOpenAI` | `azure-openai` | Azure OpenAI | `/azure-openai/openai/deployments/{deployment}/chat/completions` |
-| `ManagedCode.LlmTck.Foundry` | `microsoft-foundry` | Microsoft Foundry | `/microsoft-foundry/models/chat/completions` |
-| `ManagedCode.LlmTck.Anthropic` | `anthropic` | Anthropic Messages | `/anthropic/v1/messages` |
-| `ManagedCode.LlmTck.Gemini` | `gemini` | Gemini | `/gemini/v1beta/models/{model}:generateContent` |
-| `ManagedCode.LlmTck.Groq` | `groq` | Groq | `/groq/openai/v1/chat/completions` |
-| `ManagedCode.LlmTck.Mistral` | `mistral` | Mistral | `/mistral/v1/chat/completions` |
-| `ManagedCode.LlmTck.Ollama` | `ollama` | Ollama | `/ollama/api/chat` |
-| `ManagedCode.LlmTck.Cohere` | `cohere` | Cohere | `/cohere/v2/chat` |
-| `ManagedCode.LlmTck.Bedrock` | `bedrock` | Amazon Bedrock | `/bedrock/model/{modelId}/converse` |
-| `ManagedCode.LlmTck.OpenRouter` | `openrouter` | OpenRouter | `/openrouter/api/v1/chat/completions` |
-| `ManagedCode.LlmTck.DeepSeek` | `deepseek` | DeepSeek | `/deepseek/v1/chat/completions` |
-| `ManagedCode.LlmTck.Perplexity` | `perplexity` | Perplexity | `/perplexity/v1/sonar` |
-| `ManagedCode.LlmTck.SystemOne` | `systemone` | Jev / TypeSafe and Kev native decisions | `/systemone/v1/systemone` |
-| `ManagedCode.LlmTck.Cloudflare` | `cloudflare` | Clef / Clef Flash native decisions | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` |
-
-Each provider profile also carries a doc-backed `ApiContract` with official documentation links, retrieval date, API version or header requirements, documented operations, streaming support, and whether `ManagedCode.LlmTck.Hosting` currently maps the operation.
-
-Use a provider profile when code needs a stable package-level declaration without starting a host:
-
-```csharp
-using ManagedCode.LlmTck.AzureOpenAI;
-
-var profile = AzureOpenAiCompatibility.Profile;
-Console.WriteLine(profile.Id); // azure-openai
-```
-
-## OpenAI SDK
-
-The official OpenAI .NET SDK expects its `Endpoint` to be the API root. Use
-`/openai/v1` for this TCK, or `llmTck.GetOpenAiEndpoint()` from the Aspire
-package when wiring an AppHost resource.
-
-```csharp
-using OpenAI;
-using OpenAI.Chat;
-using System.ClientModel;
-
-var chat = new ChatClient(
- "gpt-4.1-mini",
- new ApiKeyCredential("test-key"),
- new OpenAIClientOptions
- {
- Endpoint = new Uri("http://localhost:5000/openai/v1"),
- });
-
-await foreach (var update in chat.CompleteChatStreamingAsync(
- [new UserChatMessage("What is the invoice total?")]))
-{
- Console.Write(update.ContentUpdate.Count > 0 ? update.ContentUpdate[0].Text : string.Empty);
-}
-```
-
-## Azure OpenAI And Foundry SDKs
-
-The OpenAI v1 API is available at `/azure-openai/openai/v1/` and `/microsoft-foundry/openai/v1/`, with `chat/completions`, `responses` and `embeddings`. Point the official OpenAI client endpoint at the corresponding base URL and supply the configured API key. These v1 routes accept bearer or `api-key` authentication and need no dated `api-version` query parameter. Responses supports ordinary JSON and documented SSE events. See the [September 2026 API review](docs/Features/ProviderApiReview20260907.md) for the verified SDK versions and provider contracts.
-
-Azure OpenAI deployment routes use the deployment name as the TCK model id. API keys sent through the official SDK's `api-key` header are accepted anywhere a bearer token would be accepted.
-
-```csharp
-using Azure.AI.OpenAI;
-using OpenAI.Chat;
-using OpenAI.Embeddings;
-using System.ClientModel;
+# LLM Test Server
-var azure = new AzureOpenAIClient(
- new Uri("http://localhost:5000/azure-openai/"),
- new ApiKeyCredential("test-key"));
+[](https://github.com/managedcode/LlmTestServer/actions/workflows/ci.yml)
+[](https://github.com/managedcode/LlmTestServer/actions/workflows/release.yml)
+[](https://www.nuget.org/packages/ManagedCode.LlmTestServer)
+[](LICENSE)
-ChatClient chat = azure.GetChatClient("gpt-4.1-mini");
-EmbeddingClient embeddings = azure.GetEmbeddingClient("text-embedding-3-small");
+**A local, deterministic LLM provider for .NET tests, with a dashboard that shows where every token goes.**
-var answer = await chat.CompleteChatAsync(
-[
- new UserChatMessage("What is the invoice total?"),
-]);
+[](docs/images/showcase-token-flow.jpg)
-var vector = await embeddings.GenerateEmbeddingAsync("invoice");
-```
-
-Microsoft Foundry / Azure AI Inference clients call the `/microsoft-foundry/chat/completions` and `/microsoft-foundry/embeddings` routes. The inference routes require `api-version=2024-05-01-preview`, which the official SDK supplies. Set `Model` to the model id configured in LLM TCK.
-
-```csharp
-using Azure;
-using Azure.AI.Inference;
-
-var endpoint = new Uri("http://localhost:5000/microsoft-foundry/");
-var credential = new AzureKeyCredential("test-key");
-
-var chat = new ChatCompletionsClient(endpoint, credential);
-var embeddings = new EmbeddingsClient(endpoint, credential);
-
-var completion = await chat.CompleteAsync(
- new ChatCompletionsOptions(
- [
- new ChatRequestUserMessage("What is the invoice total?"),
- ])
- {
- Model = "gpt-4.1-mini",
- });
-
-var embedding = await embeddings.EmbedAsync(
- new EmbeddingsOptions(["invoice"])
- {
- Model = "text-embedding-3-small",
- });
-```
-
-## Configuration Model
-
-LLM TCK is configured with one `LlmTckConfiguration`.
-
-You can apply that configuration in two places:
+[What it is](#what-it-is) · [Token usage and cache hits](#token-usage-and-prompt-cache-hits) · [Quick start](#quick-start) · [Capabilities](#what-you-can-do) · [Providers](#providers) · [TypeSafe / Jev](#typesafe-and-jev) · [Docs](#learn-more)
-- at host startup through `builder.Services.AddLlmTck(options => ...)`
-- at test runtime through `LlmTckClient.ConfigureAsync(...)` or `POST /admin-api/configure`
+## What it is
-Runtime configuration is a replacement, not a merge. Applying a new configuration resets scenario positions and assertion events. The runtime snapshots the configuration, so later mutations to your builder/list objects do not change the running provider.
+LLM Test Server is a small ASP.NET Core server that speaks the HTTP APIs of 13 LLM providers, each under its own
+namespace: `/openai/v1`, `/anthropic/v1`, `/gemini/v1beta`, `/azure-openai`, and so on. Your application keeps its
+official SDK or `Microsoft.Extensions.AI` client and only changes the base URL. Every answer, tool call, stream chunk
+and failure comes from a fixture your test configures, so the same test produces the same result on every run — with
+no external model calls and no production credentials. Run it from an Aspire AppHost, inside your own ASP.NET Core host,
+or as a standalone container.
-The default configuration advertises official OpenAI fixture model IDs:
+Native decision APIs are included too: **TypeSafe Jev**, Kev through System One, and Cloudflare Clef.
+Use the typed client from `ManagedCode.LlmTestServer.Client` with the contracts in
+`ManagedCode.LlmTestServer.SystemOne` — see the [TypeSafe/Jev example](docs/Reference/Clients.md#typesafe-jev-through-system-one).
-| Model ID | Kind |
-| --- | --- |
-| `gpt-4.1-mini` | Chat |
-| `text-embedding-3-small` | Embedding |
-| `gpt-image-1` | Image |
-| `gpt-4o-mini-tts` | Audio |
-| `sora-2` | Video |
-
-Model IDs and model kinds are enforced. A chat request to an embedding model, or an embedding request to an unknown model, returns `404` with `llm_tck_unknown_model`.
+## Why use it
-Use typed helpers for broader OpenAI model registration when tests need more than the defaults:
+- **Deterministic tests for LLM features.** Script answers, tool calls, multi-turn conversations, streams, rate limits
+ and content filters instead of mocking SDK internals.
+- **Your real integration code runs.** Requests travel through the same provider SDKs and wire formats your
+ application uses in production.
+- **Proof of what your application sent.** Every request is recorded with its messages, payloads, usage and outcome;
+ tests can query, export and verify that journal.
+- **Token and cache visibility.** See how much of each prompt is system text, tool schemas or tool results, and how
+ much of it the prompt cache served.
+- **Safe in parallel.** Isolated sessions give each test its own configuration, queues, cache and journal on one
+ shared server.
-```csharp
-options.AddKnownOpenAiModels(reasoningTokens: 128);
-
-// Or register only one modality family.
-options.AddCurrentOpenAiChatModels(reasoningTokens: 128);
-options.AddOpenAiEmbeddingModels();
-options.AddOpenAiImageModels();
-options.AddOpenAiAudioModels();
-options.AddOpenAiVideoModels();
-```
+## Token usage and prompt-cache hits
-Individual helpers are also available, including `AddGpt55(...)`, `AddGpt54Mini(...)`, `AddGpt5Nano(...)`, `AddGpt41()`, `AddGpt4OMini()`, `AddTextEmbedding3Large()`, `AddGptImage2()`, `AddGptImage15()`, `AddGptImage1Mini()`, `AddTts1()`, `AddTts1Hd()`, and `AddSora2Pro()`. Keep using `AddModel(...)` for custom deployment names or provider-specific IDs.
+Every chat request gets deterministic token usage from the server's tokenizer, and the provider response carries it in
+that provider's own usage fields. Three things are tracked for each request:
-### Fault Simulation
+- **What the input is made of.** Input tokens are split by role — system prompt, tool schemas, user, assistant text,
+ tool-call arguments and tool results. The parts add up exactly to the reported input and are recorded as
+ `InputComposition` on the request's usage.
+- **How the prompt cache served it.** A repeated prompt prefix reports cache reads; the first request that makes a
+ prefix cacheable reports cache writes. Thresholds follow each provider (for example 1,024 tokens in 128-token steps on
+ OpenAI-compatible routes, 2,048 on Gemini, and explicit cache markers on Anthropic and Bedrock).
+- **What the model produced.** Output tokens, with reasoning tokens for reasoning-capable fixture models reported
+ separately.
-Fault simulation is configured on the provider-neutral runtime and applies through every provider namespace. Use it when a test needs retry, moderation, or provider-error handling without scripting each provider route separately.
+Read it from a test through the request journal (`GET /admin-api/requests`):
```csharp
-builder.Services.AddLlmTck(options =>
+var journal = await control.GetRequestsAsync();
+foreach (var request in journal.Requests)
{
- // Allow two accepted runtime requests, then return 429 too_many_requests.
- options.SimulateRateLimitAfter(2);
-
- // Return 400 content_filter whenever a request text contains either term.
- options.SimulateContentFilter("blocked phrase", "unsafe fixture");
-});
+ if (request.Usage is not { InputComposition: { } parts } usage) continue;
+ Console.WriteLine($"{request.ModelId}: {usage.InputTokens} input = {parts.SystemTokens} system + " +
+ $"{parts.ToolDefinitionTokens} tool schemas + {parts.UserTokens} user + {parts.AssistantTokens} assistant + " +
+ $"{parts.ToolCallTokens} tool calls + {parts.ToolResultTokens} tool results + {parts.OtherTokens} other; " +
+ $"{usage.CachedInputTokens} read from cache, {usage.CacheCreationInputTokens} written");
+}
```
-`SimulateRateLimitAfter(0)` makes the first valid runtime request return `429` with `too_many_requests`. `SimulateContentFilter(...)` checks chat messages, embedding inputs, image prompts, audio speech input, audio transcription/translation prompts, and video prompts. `ConfigureAsync(...)` and `ResetAsync()` both reset the rate-limit counter so tests stay deterministic.
+Or open the dashboard: the **Tokens** tab draws the flow above for one request or a whole labeled conversation, with
+context-mix and prompt-cache donuts and per-request context growth. **Traffic insights** (`/?view=insights`) charts
+all recorded traffic by provider, model, outcome, latency, cache and context mix; clicking a slice filters the inbox.
-## ASP.NET Core Startup
+[](docs/images/showcase-insights.jpg)
-The simplest host config is one chat scenario:
+Details: [dashboard analytics](docs/Features/DashboardAnalytics.md) ·
+[token usage and prompt-cache accounting](docs/Reference/TokenUsageAndPromptCache.md).
-```csharp
-using ManagedCode.LlmTck.Hosting;
-using ManagedCode.LlmTck.Models;
+## Quick start
-var builder = WebApplication.CreateBuilder(args);
+> **Status:** the v1.0.0 NuGet packages and container image are not published yet. Until they are, build and pack
+> the repository (version `0.1.18`) and use the local feed — see [installation](docs/Reference/Installation.md).
-builder.Services.AddLlmTck(options =>
-{
- options.AddChatScenario(
- "blue-whale",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("largest animal")
- .Responds("blue whale", "blue ", "whale"));
-});
-
-var app = builder.Build();
-app.MapLlmTck();
-app.Run();
-```
-
-A fuller config can advertise your application's real model names while still serving deterministic fixtures:
-
-```csharp
-using ManagedCode.LlmTck.Hosting;
-using ManagedCode.LlmTck.Models;
+Install the libraries in your existing AppHost or integration-test project from the locally packed feed:
-var builder = WebApplication.CreateBuilder(args);
-
-builder.Services.AddLlmTck(options =>
-{
- options.RequireBearerToken("test-key");
-
- options.AddDefaultOpenAiModels();
-
- options.WithDefaultEmbeddingVector(0.125f, 0.25f, 0.5f, 1.0f);
- options.WithDefaultAudio(File.ReadAllBytes("fixtures/ok.wav"), "audio/wav");
-
- options.AddChatScenario(
- "invoice-total",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("invoice total")
- .Responds(
- "{\"total\":42.50}",
- "{\"total\":",
- "42.50",
- "}"));
-
- options.AddChatScenario(
- "provider-rate-limit",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("rate limit")
- .Fails(429, "rate_limit_exceeded", "Scripted rate limit from LLM TCK."));
-
- options.AddChatScenario(
- "slow-response",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("slow")
- .Responds("done")
- .DelaysBy(250));
-});
-
-var app = builder.Build();
-app.MapLlmTck();
-app.Run();
+```sh
+dotnet add package ManagedCode.LlmTestServer.Aspire --version 0.1.18 --no-restore
+dotnet add package ManagedCode.LlmTestServer.Client --version 0.1.18 --no-restore
+dotnet restore --source /absolute/path/to/LlmTestServer/artifacts/packages \
+ --source https://api.nuget.org/v3/index.json
```
-## Aspire AppHost
+### In an Aspire AppHost
-Install the Aspire integration package in the AppHost:
-
-```bash
-dotnet add package ManagedCode.LlmTck.Aspire
-```
-
-Then add the package-owned TCK resource directly:
+`AddLlmTestServer()` starts the packaged .NET service; Docker is not required.
```csharp
-using ManagedCode.LlmTck.Aspire;
+using ManagedCode.LlmTestServer.Aspire;
var builder = DistributedApplication.CreateBuilder(args);
+var llm = builder.AddLlmTestServer().WithApiKey("test-key");
-var llmTck = builder
- .AddLlmTck()
- .WithApiKey("test-key");
-
-builder
- .AddProject("consumer")
- .WithReference(llmTck)
- .WithEnvironment("LLM_PROVIDER_ENDPOINT", llmTck.GetHttpEndpoint())
- .WithEnvironment("OPENAI_ENDPOINT", llmTck.GetOpenAiEndpoint())
- .WaitFor(llmTck);
+builder.AddProject("api")
+ .WithReference(llm)
+ .WithEnvironment("OPENAI_ENDPOINT", llm.GetOpenAiEndpoint())
+ .WithEnvironment("OPENAI_API_KEY", "test-key")
+ .WaitFor(llm);
builder.Build().Run();
```
-`AddLlmTck()` creates a `LlmTckResource` backed by the packaged .NET LLM TCK service executable and exposes its `http` endpoint. It does not require a consumer service project reference, generated `Projects.*` metadata type, project path, Docker, or a container runtime. Consumer resources should reference the TCK resource, wait for it, and use `llmTck.GetHttpEndpoint()` when they need the provider-compatible base URL. `.WithApiKey("test-key")` sets `LlmTck:RequiredBearerToken` so both provider endpoints and `/admin-api/*` control endpoints require the same bearer token.
-
-Use `AddLlmTckContainer()` only when you explicitly want a container-backed resource, for example for a deployment or container-runtime smoke test. The container mode uses a `ghcr.io/managedcode/llm-tck` image tagged with the same release version as the installed `ManagedCode.LlmTck.Aspire` package; it is not the default local Aspire path.
-
-## Control Panel And Token Usage
-
-Open the TCK resource endpoint from the Aspire dashboard to inspect the running configuration at `/`. The browser admin panel is rendered by Blazor server-side rendering from `ManagedCode.LlmTck.Hosting`. If the resource was configured with `.WithApiKey("test-key")` or `RequireBearerToken("test-key")`, enter the same token in the control panel before refreshing.
-
-The panel reads `/admin-api/models` and `/admin-api/assertions`. It shows advertised models, actions, control endpoint groups, provider endpoint groups, grouped runtime events, captured requests, captured responses, assertion counters, and deterministic token usage. Auto-refresh is enabled by default and runs every 15 seconds on the server-side Blazor component; there is no client-side polling script and no visible countdown.
-
-Token usage is counted with the repo-owned tiktoken-compatible counter and reported both as summary totals and per runtime event with `inputTokens`, `cachedInputTokens`, `cacheCreationInputTokens`, `outputTokens`, `reasoningTokens`, and `totalTokens`. Provider response envelopes also receive the same deterministic usage values: OpenAI-compatible chat and Responses usage including reasoning-token and prompt-cache details when configured, Anthropic sync messages and streaming `message_start`/`message_delta`, Gemini `usageMetadata` including long-running video operation results, Cohere chat usage, Ollama prompt/eval counts, and Bedrock Converse usage.
-
-For reasoning-capable fixture models, configure a deterministic reasoning-token count on the model. LLM TCK includes those tokens in `outputTokens` and exposes the split in `reasoningTokens`; OpenAI-compatible responses also include `completion_tokens_details.reasoning_tokens` or `output_tokens_details.reasoning_tokens`.
-
-```csharp
-options.AddGpt5Nano(reasoningTokens: 128);
-```
-
-## Prompt Cache Accounting
-
-Prompt cache accounting is deterministic runtime state for testing provider usage handling. LLM TCK does not call a real cache service and does not hide prompt text; it calculates repeated prompt-prefix usage from the requests that reach the runtime.
-
-Cache entries are created only for successful chat or Responses requests on provider surfaces with a cache policy. A failed, unmatched, unauthorized, cancelled, unknown-model, or scripted-error request does not create a cache entry. `ConfigureAsync(...)` and `ResetAsync()` both clear prompt-cache entries so each test can start from a known cache state.
-
-The cache key includes provider cache policy, model id, an optional provider cache key or session id, the rounded cacheable token count, and the cumulative message prefix. The first successful request with a cacheable prefix reports cache-write tokens and zero cache-read tokens. Ollama exposes cache reads only and does not report cache-write tokens. A later successful request with the same cache key reports cache-read tokens and zero cache-write tokens for the already cached prefix.
-
-Provider cache thresholds follow the current runtime policy:
-
-| Policy | Provider routes | Minimum cacheable tokens | Increment |
-| --- | --- | ---: | ---: |
-| OpenAI-compatible | OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Perplexity, Responses API routes that use the OpenAI-compatible shape | 1024 | 128 |
-| OpenRouter | OpenRouter chat and Responses routes; `session_id` or `x-session-id` can become the cache key when no explicit prompt cache key is sent | 1024 | 128 |
-| DeepSeek | DeepSeek chat routes | 1024 | 128 |
-| Anthropic | Anthropic Messages requests that include `cache_control` markers | 1024 | 128 |
-| Mistral | Mistral chat routes | 64 | 64 |
-| Gemini | Gemini generateContent routes | 2048 | 128 |
-| Ollama | Ollama chat routes; deterministic cache reads only | 1 | 1 |
-| Bedrock | Bedrock Converse requests that include `cachePoint` or `cache_control` markers | 1024 | 128 |
-
-Cache accounting is a breakdown of input usage, not an extra billable token bucket. `totalTokens` remains `inputTokens + outputTokens`; `cachedInputTokens` and `cacheCreationInputTokens` explain how much of the input was read from, or written to, the deterministic prompt cache.
-
-Provider envelopes expose the same runtime usage through provider-native field names:
-
-| Provider surface | Cache fields returned |
-| --- | --- |
-| OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Mistral, Perplexity chat | `usage.prompt_tokens_details.cached_tokens` |
-| OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Perplexity Responses | `usage.input_tokens_details.cached_tokens` |
-| OpenRouter chat and Responses | `cached_tokens` plus `cache_write_tokens` in the matching prompt/input token details object |
-| DeepSeek chat | `usage.prompt_cache_hit_tokens` and `usage.prompt_cache_miss_tokens` |
-| Anthropic Messages | `usage.cache_creation_input_tokens` and `usage.cache_read_input_tokens` when cache usage exists |
-| Gemini generateContent | `usageMetadata.cachedContentTokenCount` |
-| Ollama chat | `prompt_eval_cached_count`, reported on the final NDJSON chunk for streaming |
-| Bedrock Converse and ConverseStream metadata | `usage.cacheReadInputTokens` and `usage.cacheWriteInputTokens` |
-
-
-
-
-
-## Chat Scenarios
-
-### Contains Match
-
-`WhenUserContains(...)` adds a user-message contains matcher. All configured match messages must be present somewhere in the actual request.
-
-```csharp
-options.AddChatScenario(
- "support-refund",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("refund")
- .Responds("I can help with a refund."));
-```
-
-### Exact Match
-
-Use exact matching when a test must prove the complete prompt contract:
-
-```csharp
-using ManagedCode.LlmTck.Scenarios;
-
-options.AddChatScenario(
- "exact-system-contract",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WithExactMatch(
- new LlmTckMessage { Role = "system", Content = "Return JSON only." },
- new LlmTckMessage { Role = "user", Content = "Give me the invoice total." })
- .Responds("{\"total\":42.50}"));
-```
-
-### Queued Responses
-
-Each matched request consumes the next response. This makes multi-turn flows deterministic:
-
-```csharp
-options.AddChatScenario(
- "two-turn-plan",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("make a plan")
- .Responds("First draft")
- .Responds("Revised draft"));
-```
-
-After the queue is exhausted, the provider returns `409` with `llm_tck_scenario_exhausted`.
-
-### Streaming Chunks
-
-The first `Responds` argument is the non-streaming response. The remaining arguments are the streaming chunks:
-
-```csharp
-options.AddChatScenario(
- "streaming-answer",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("stream this")
- .Responds("blue whale", "blue ", "whale"));
-```
-
-For `stream: true`, LLM TCK emits SSE `data:` frames and a final `data: [DONE]` marker. All chunks in one response share the same response id.
+### In a test
-### Scripted Errors
-
-Use `Fails(...)` to test client error handling without waiting for a real provider to fail:
-
-```csharp
-options.AddChatScenario(
- "content-policy-error",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("blocked fixture")
- .Fails(400, "content_filter", "The scripted request was rejected."));
-```
-
-### Delays And Cancellation
-
-Use `DelaysBy(...)` to test timeout and cancellation behavior:
+Add `ManagedCode.LlmTestServer.Aspire`, `ManagedCode.LlmTestServer.Client` and `Aspire.Hosting.Testing`, then
+configure a response and call it:
```csharp
-options.AddChatScenario(
- "timeout-path",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("slow path")
- .Responds("eventual answer")
- .DelaysBy(1_500));
-```
-
-If the caller cancels during the delay, the queued response is not consumed.
-
-### Scenario-Specific Token
-
-A scenario can require its own bearer token:
-
-```csharp
-options.AddChatScenario(
- "tenant-a-only",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .RequireBearerToken("tenant-a-key")
- .WhenUserContains("tenant secret")
- .Responds("tenant-a response"));
-```
-
-Use either a global token or per-scenario tokens. If both are configured for a scenario, the same request must satisfy both checks, so different global and scenario tokens intentionally make that scenario unreachable.
-
-## Modalities
-
-### Embeddings
-
-Configure a fixed embedding vector. Every input value receives the same deterministic vector:
-
-```csharp
-options.AddTextEmbedding3Small();
-options.WithDefaultEmbeddingVector(0.01f, 0.02f, 0.03f, 0.04f);
-```
-
-```csharp
-using ManagedCode.LlmTck.Client;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
using Microsoft.Extensions.AI;
+using ChatMessage = Microsoft.Extensions.AI.ChatMessage;
-using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
-using IEmbeddingGenerator> embeddings =
- new LlmTckEmbeddingGenerator(httpClient, "text-embedding-3-small");
+var builder = DistributedApplicationTestingBuilder.Create([]);
+builder.AddLlmTestServer("llm").WithApiKey("test-key");
+await using var app = await builder.BuildAsync();
+await app.StartAsync();
+await app.ResourceNotifications.WaitForResourceHealthyAsync("llm");
-var result = await embeddings.GenerateAsync(["alpha", "beta"]);
+var control = new LlmTestServerClient(app.CreateHttpClient("llm", "http"), "test-key");
+await control.ConfigureAsync(config => config.RequireBearerToken("test-key").UseGpt41Mini()
+ .UseChatScenario("greeting", scenario => scenario.WhenUserContains("hello").Responds("Hello from your test!")));
+using var chat = control.CreateChatClient();
+var reply = await chat.GetResponseAsync([new ChatMessage(ChatRole.User, "hello")]); // "Hello from your test!"
```
-### Images
-
-Image generation returns a deterministic base64 PNG by default:
+Your application can use its official SDK against the same server. In the Aspire test above, use its allocated
+endpoint and the same fixture key — for example with OpenAI:
```csharp
-options.AddGptImage1();
-```
-
-```csharp
-using ManagedCode.LlmTck.Client;
-using Microsoft.Extensions.AI;
-
-using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
-using IImageGenerator images = new LlmTckImageGenerator(httpClient, "gpt-image-1");
-
-var image = await images.GenerateAsync(
- new ImageGenerationRequest { Prompt = "compatibility marker" });
-```
-
-### Audio
-
-Audio speech returns deterministic bytes with a matching media type. The default fixture is a minimal WAV payload:
-
-```csharp
-options.AddGpt4OMiniTts();
-options.WithDefaultAudio(File.ReadAllBytes("fixtures/speech.wav"), "audio/wav");
-```
-
-```csharp
-var audio = await httpClient.PostAsJsonAsync(
- "/openai/v1/audio/speech",
- new { model = "gpt-4o-mini-tts", input = "hello", voice = "alloy" });
-
-audio.EnsureSuccessStatusCode();
-var bytes = await audio.Content.ReadAsByteArrayAsync();
-```
-
-## Runtime Reconfiguration
-
-Use runtime reconfiguration when each test needs a different provider script.
-
-### Configure Before A Test
-
-Use `ManagedCode.LlmTck.Client` as the universal test control surface. A test can start or discover the hosted TCK, create one `LlmTckClient`, load all required models, datasets, scripted responses, errors, embeddings, images, and audio fixtures, and then call the provider through regular clients.
-
-```csharp
-using ManagedCode.LlmTck.Client;
-using Microsoft.Extensions.AI;
-
-using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
-var tck = LlmTckClient.Create(httpClient, bearerToken: "test-key");
-
-await tck.ConfigureAsync(
- config => config
- .RequireBearerToken("test-key")
- .UseChatModel("test-chat")
- .UseEmbeddingModel("test-embedding")
- .UseImageModel("test-image")
- .UseAudioModel("test-audio")
- .UseEmbeddingVector(0.9f, 0.8f)
- .UseImageDataUri("data:image/png;base64,Zm9v")
- .UseAudio([1, 2, 3, 4], "audio/test")
- .UseDataset(
- "checkout-flow",
- dataset => dataset
- .AddChatScenario(
- "invoice-total",
- scenario => scenario
- .ForModel("test-chat")
- .WhenUserContains("invoice total")
- .Responds("{\"total\":42.50}", "{\"total\":", "42.50", "}"))
- .AddChatScenario(
- "provider-rate-limit",
- scenario => scenario
- .ForModel("test-chat")
- .WhenUserContains("rate limit")
- .Fails(429, "rate_limit_exceeded", "Scripted rate limit."))),
- resetFirst: true);
-
-using IChatClient chat = tck.CreateChatClient("test-chat");
-using IEmbeddingGenerator> embeddings =
- tck.CreateEmbeddingGenerator("test-embedding");
-using IImageGenerator images = tck.CreateImageGenerator("test-image");
-
-var response = await chat.GetResponseAsync(
-[
- new ChatMessage(ChatRole.User, "What is the invoice total?"),
-]);
-
-var vector = await embeddings.GenerateAsync(["invoice"]);
-var image = await images.GenerateAsync(new ImageGenerationRequest { Prompt = "fixture" });
-var audio = await tck.GenerateAudioAsync("test-audio", "speak this");
-var assertions = await tck.GetAssertionsAsync();
-```
-
-`resetFirst: true` clears previous assertion events and scenario positions before the new configuration is applied. Named datasets are active after configuration; they group scenarios so a test can load a whole conversation set without flattening everything by hand.
-
-### Configure With `LlmTckClient`
-
-```csharp
-using ManagedCode.LlmTck.Client;
-using ManagedCode.LlmTck.Configuration;
-using ManagedCode.LlmTck.Models;
-
-using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
-httpClient.DefaultRequestHeaders.Authorization =
- new System.Net.Http.Headers.AuthenticationHeaderValue("Bearer", "test-key");
-
-var control = new LlmTckClient(httpClient);
-
-var configuration = new LlmTckConfigurationBuilder()
- .RequireBearerToken("test-key")
- .AddModel("docs-chat", LlmTckModelKind.Chat)
- .AddModel("docs-embedding", LlmTckModelKind.Embedding)
- .AddChatScenario(
- "docs-blue-whale",
- scenario => scenario
- .ForModel("docs-chat")
- .WhenUserContains("largest animal")
- .Responds("blue whale", "blue ", "whale"))
- .WithDefaultEmbeddingVector(0.125f, 0.25f)
- .Build();
-
-await control.ConfigureAsync(configuration);
-```
-
-If the current runtime already has a bearer token, the configure request must use that current token. If the new configuration sets a different token, future provider and control requests must use the new token.
-
-### Configure With Raw JSON
-
-`POST /admin-api/configure` accepts readable enum values such as `"chat"` and `"contains"`:
-
-```bash
-curl -X POST http://localhost:5000/admin-api/configure \
- -H "content-type: application/json" \
- -H "authorization: Bearer test-key" \
- -d '{
- "requiredBearerToken": "test-key",
- "models": [
- { "id": "docs-chat", "kind": "chat" },
- { "id": "docs-embedding", "kind": "embedding" },
- { "id": "docs-image", "kind": "image" },
- { "id": "docs-audio", "kind": "audio" }
- ],
- "chatScenarios": [
- {
- "id": "docs-blue-whale",
- "modelId": "docs-chat",
- "match": {
- "mode": "contains",
- "messages": [
- { "role": "user", "content": "largest animal" }
- ]
- },
- "responses": [
- {
- "content": "blue whale",
- "streamChunks": [ "blue ", "whale" ]
- }
- ]
- }
- ],
- "defaultEmbeddingVector": [ 0.125, 0.25 ],
- "defaultAudioMediaType": "audio/wav"
- }'
-```
+using System.ClientModel;
+using OpenAI;
+using OpenAI.Chat;
-Then call the configured model:
-
-```bash
-curl -X POST http://localhost:5000/openai/v1/chat/completions \
- -H "content-type: application/json" \
- -H "authorization: Bearer test-key" \
- -d '{
- "model": "docs-chat",
- "messages": [
- { "role": "user", "content": "What is the largest animal?" }
- ]
- }'
+await control.ResetAsync(); // Reuse the configured fixture for this separate SDK example.
+using var providerHttp = app.CreateHttpClient("llm", "http");
+var openAiChat = new ChatClient("gpt-4.1-mini", new ApiKeyCredential("test-key"),
+ new OpenAIClientOptions { Endpoint = new Uri(providerHttp.BaseAddress!, "openai/v1") });
+ChatCompletion completion = await openAiChat.CompleteChatAsync([new UserChatMessage("hello")]);
+Console.WriteLine($"{completion.Usage.InputTokenCount} input tokens, " +
+ $"{completion.Usage.InputTokenDetails.CachedTokenCount} from cache");
```
-## Microsoft.Extensions.AI
-
-Use the client package when you want tests to call the fake provider through normal `Microsoft.Extensions.AI` abstractions:
-
-```csharp
-using ManagedCode.LlmTck.Client;
-using Microsoft.Extensions.AI;
-
-using var httpClient = new HttpClient
-{
- BaseAddress = new Uri("http://localhost:5000"),
-};
-httpClient.DefaultRequestHeaders.Authorization =
- new System.Net.Http.Headers.AuthenticationHeaderValue("Bearer", "test-key");
-
-using IChatClient chatClient = new LlmTckChatClient(httpClient);
+### As a standalone container
-var response = await chatClient.GetResponseAsync(
-[
- new ChatMessage(ChatRole.User, "What color is the largest animal?"),
-]);
+Build the image with the .NET SDK (use `linux-x64` in both RID arguments on amd64), run it, then configure it over
+HTTP — any language can drive it:
-Console.WriteLine(response.Text);
+```sh
+dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --runtime linux-arm64 --self-contained false \
+ /t:PublishContainer -p:ContainerRuntimeIdentifiers=linux-arm64 -p:ContainerImageTag=local -p:UseAppHost=false
+docker run --rm -p 8080:8080 -e LlmTestServer__RequiredBearerToken=local-test-key managedcode/llm-test-server:local
```
-When a bearer token is required, prefer creating the modality clients from the control client so the same token is applied consistently:
-
-```csharp
-var tck = LlmTckClient.Create(httpClient, bearerToken: "test-key");
-
-using IChatClient chatClient = tck.CreateChatClient("docs-chat");
-using IEmbeddingGenerator> embeddings =
- tck.CreateEmbeddingGenerator("docs-embedding");
-using IImageGenerator images = tck.CreateImageGenerator("docs-image");
+```sh
+curl --fail-with-body http://localhost:8080/admin-api/configure \
+ -H 'Authorization: Bearer local-test-key' -H 'Content-Type: application/json' \
+ --data '{"requiredBearerToken":"local-test-key","models":[{"id":"gpt-4.1-mini","kind":"chat"}],"chatScenarios":[{"id":"hello","modelId":"gpt-4.1-mini","responses":[{"content":"Hello from your fixture"}]}]}'
+curl --fail-with-body http://localhost:8080/openai/v1/chat/completions \
+ -H 'Authorization: Bearer local-test-key' -H 'Content-Type: application/json' \
+ --data '{"model":"gpt-4.1-mini","messages":[{"role":"user","content":"Hello"}]}'
```
-Streaming uses the same client:
-
-```csharp
-await foreach (var update in chatClient.GetStreamingResponseAsync(
- [new ChatMessage(ChatRole.User, "stream this")]))
-{
- Console.Write(update.Text);
-}
-```
-
-## Assertions And Reset
-
-The assertion summary is intentionally simple: it tells the test whether requests matched configured scenarios, missed, failed auth, used unknown models, exhausted a response queue, or returned scripted errors.
-
-```csharp
-var control = new LlmTckClient(httpClient);
-var assertions = await control.GetAssertionsAsync();
-
-if (assertions.Unmatched > 0 || assertions.ModelNotFound > 0)
-{
- throw new InvalidOperationException("The application called an unexpected LLM path.");
-}
-```
-
-Reset clears assertion events and scenario response positions without replacing the current configuration:
-
-```csharp
-await control.ResetAsync();
-```
+Open `http://localhost:8080/` for the dashboard. When a key is configured it protects provider routes and
+`/admin-api/*`. More: [Docker distribution](docs/Features/DockerDistribution.md),
+[embedding in ASP.NET Core](docs/Reference/Installation.md#aspnet-core-startup).
-## Hosted Endpoint Families
+## What you can do
-Provider endpoints are explicitly namespaced. The table below shows the route
-families and representative operations; the full method/path contract lives in
-each provider profile's `ApiContract` and is guarded by
-`ProviderApiContractTests`. See
-[`docs/Features/ProviderApiContractCoverage.md`](docs/Features/ProviderApiContractCoverage.md)
-for the current coverage rules and behavior-test inventory.
-
-| Provider | Namespace | Representative hosted operations |
+| Capability | What it covers | Guide |
| --- | --- | --- |
-| OpenAI | `/openai` | `/openai/v1/models`, `/openai/v1/decisions`, `/openai/v1/chat/completions`, `/openai/v1/responses`, `/openai/v1/embeddings`, `/openai/v1/images/*`, `/openai/v1/audio/*`, `/openai/v1/videos*` |
-| Azure OpenAI | `/azure-openai` | `/azure-openai/openai/v1/{chat/completions,responses,embeddings}`, deployment chat/embeddings/images/audio, and `/azure-openai/openai/v1/video/generations/*` |
-| Microsoft Foundry | `/microsoft-foundry` | `/microsoft-foundry/openai/v1/{chat/completions,responses,embeddings}`, `/microsoft-foundry/chat/completions`, `/microsoft-foundry/embeddings`, and `/microsoft-foundry/models/*` aliases |
-| Anthropic | `/anthropic` | `/anthropic/v1/messages` |
-| Gemini | `/gemini` | `/gemini/v1beta/models/{model}:generateContent`, streaming content, embeddings, long-running video operations, and generated files |
-| Groq | `/groq` | `/groq/openai/v1/models`, chat completions, Responses, speech, transcription, and translation routes |
-| Mistral | `/mistral` | `/mistral/v1/chat/completions`, `/mistral/v1/embeddings` |
-| Ollama | `/ollama` | `/ollama/api/chat`, `/ollama/api/embed` |
-| Cohere | `/cohere` | `/cohere/v2/chat`, `/cohere/v2/embed` |
-| Amazon Bedrock | `/bedrock` | `/bedrock/model/{modelId}/converse`, converse stream, invoke, and invoke-with-response-stream |
-| OpenRouter | `/openrouter` | `/openrouter/api/v1/models`, chat completions, Responses |
-| DeepSeek | `/deepseek` | `/deepseek/models`, `/deepseek/v1/chat/completions` |
-| Perplexity | `/perplexity` | `/perplexity/v1/sonar` |
-| SystemOne (Jev/Kev) | `/systemone` | `/systemone/v1/systemone` |
-| Cloudflare (Clef/flash) | `/cloudflare` | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef`, `clef-flash` |
-
-The Blazor server-side rendered browser control panel lives at `/`. JSON control endpoints live under
-`/admin-api`: `GET /admin-api/models`, `GET /admin-api/assertions`,
-`POST /admin-api/configure`, and `POST /admin-api/reset`.
-
-Audio speech returns a deterministic WAV fixture by default. When
-`requiredBearerToken` is configured, all provider and control endpoints require
-`Authorization: Bearer `.
-
-## Common Test Shapes
-
-### Replace Provider Calls In Integration Tests
-
-1. Start the LLM TCK service in Aspire or an ASP.NET Core test host.
-2. Configure the expected scenarios for the test.
-3. Point the application under test at the LLM TCK base URL.
-4. Run the application flow.
-5. Assert `GetAssertionsAsync()` has no unmatched, unknown-model, auth-failed, or exhausted events.
-
-### Test Retry Logic
-
-```csharp
-options.AddChatScenario(
- "retry-then-success",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WhenUserContains("retry")
- .Fails(429, "rate_limit_exceeded", "Try again.")
- .Responds("success after retry"));
-```
-
-### Test Prompt Contract Drift
-
-```csharp
-options.AddChatScenario(
- "exact-contract",
- scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
- .WithExactMatch(
- new LlmTckMessage { Role = "system", Content = "Return JSON only." },
- new LlmTckMessage { Role = "user", Content = "Summarize invoice INV-42." })
- .Responds("{\"summary\":\"paid\"}"));
-```
-
-If the application changes the prompt, the request becomes unmatched and the test can fail on the assertion summary.
-
-### Test Wrong Model Wiring
-
-Configure only the models your application is allowed to call:
-
-```csharp
-options.AddModel("approved-chat-model", LlmTckModelKind.Chat);
-```
-
-If the app calls `old-chat-model` or calls `approved-chat-model` through the embeddings endpoint, LLM TCK returns `llm_tck_unknown_model`.
-
-## Build And Test
-
-```bash
-dotnet restore ManagedCode.LlmTck.slnx
-dotnet build ManagedCode.LlmTck.slnx --configuration Release --no-restore
-dotnet test --project tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj --configuration Release --no-build --verbosity normal
-for project in src/*/*.csproj; do dotnet pack "$project" --configuration Release --no-build --output artifacts/packages; done
-```
-
-`global.json` opts `dotnet test` into `Microsoft.Testing.Platform` for .NET 10.
-
-## Compatibility boundaries and verification
-
-Tool calls and structured output use explicit deterministic fixtures: `CallsTool(...)`, `CallsTools(...)` and `RespondsJson(...)`. Provider adapters preserve tool history and streaming events; `LlmTckChatClient` supports the standard Microsoft.Extensions.AI function-invocation loop. Fixtures must satisfy tool selection, argument schemas and response schemas; mismatches return 409 without consuming the response. See [supported contracts and tests](docs/Features/ToolAndStructuredFixtures.md).
-
-OpenAI chat streaming supports `stream_options.include_usage`; the control library's `IChatClient` carries token usage and terminal updates, including reasoning and cache details. Authentication failures and scripted errors before generation do not accrue output/reasoning tokens.
-
-Video create operations retain completed fixture jobs. Retrieve/content/delete require a previously created ID, and reset or reconfiguration clears jobs. OpenAI fixtures return `status=completed` and `progress=100`; IDs remain unique within a run. Dataset-local scenario IDs are isolated, including concurrent cancellation rollback.
-
-Prompt-cache storage is bounded to 4096 prefixes by default. Use `WithPromptCacheCapacity(capacity)` to change the limit; zero disables caching. Eviction is deterministic FIFO, and reset/configure clears the cache.
-
-Legacy Azure deployment APIs accept the dated `api-version` selected automatically by the Azure SDK. Use the default `AzureOpenAIClientOptions` constructor, or omit options entirely; do not pin a version for the emulator. These routes require exactly one supported deployment API version: the documented `2024-10-21` GA or `2025-04-01-preview` contract. Missing, malformed, duplicate, and unknown versions are rejected, including valid-looking future dates. Azure/Foundry `/openai/v1` endpoints require no dated query parameter.
-
-After restore/build, run `bash scripts/coverage.sh` for the production 90% coverage gate. After packing, run `python3 scripts/verify-package.py` for an isolated NuGet consumer, test-owned Aspire host and Chromium dashboard test; this requires Python 3 and PowerShell (`pwsh`). CI installs Chromium dependencies and saves coverage/browser evidence. `python3 scripts/test-release.py` verifies partial-release recovery locally without external publication. Release delivery is marked complete only after NuGet push and GitHub artifact attachment succeed.
-
-## Native decision API fixtures
-
-Native typed clients are available through `LlmTckClient.CreateSystemOneClient()`
-and `LlmTckClient.CreateCloudflareDecisionClient(accountId)`. Clef accepts embedded
-PNG/JPEG/WebP data URLs or base64 objects; Jev accepts PNG/JPEG reference assets as
-JSON or multipart, with explicit image/long-context opt-ins. See the
-[official-contract audit and supported limits](docs/Features/DecisionVisionAudit.md).
-
-
-Jev, Kev, Cloudflare Clef/Clef Flash and OpenAI Decisions use explicit decision fixtures. The TCK hosts their native JSON shapes under provider namespaces and does not contact production providers. Declare the provider profile explicitly; model names never select an API implicitly.
-
-| Provider | TCK POST route | Production POST endpoint | Model helper | Official contract |
-| --- | --- | --- | --- | --- |
-| TypeSafe Jev | `/systemone/v1/systemone` | `https://api.typesafe.ai/v1/systemone` | `AddJevLatest()` | [OpenAPI](https://api.typesafe.ai/openapi.json), [primitives](https://docs.typesafe.ai/primitives/choice) |
-| Kev | `/systemone/v1/systemone` | `{kev-server}/v1/systemone` | `AddKevLatest()` | [native request models](https://github.com/jaredpalmer/kev/blob/main/kev/api.py), [server/auth](https://github.com/jaredpalmer/kev/blob/main/kev/serve.py) |
-| Cloudflare Clef | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` | `https://api.cloudflare.com/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` | `AddClef()` | [Clef API](https://developers.cloudflare.com/workers-ai/models/clef/), [REST envelope/auth](https://developers.cloudflare.com/workers-ai/get-started/rest-api/) |
-| Cloudflare Clef Flash | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `https://api.cloudflare.com/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `AddClefFlash()` | [Clef Flash API](https://developers.cloudflare.com/workers-ai/models/clef-flash/) |
-| OpenAI Decisions | `/openai/v1/decisions` | `https://api.openai.com/v1/decisions` | `AddOpenAiDecisionModel("gpt-6-luna")` | [create API](https://developers.openai.com/api/reference/resources/decisions/methods/create/) |
-
-Production APIs use `Authorization: Bearer `; Kev checks `KEV_API_KEY` only when configured and otherwise permits unauthenticated calls. For the TCK, `RequireBearerToken` controls the expected test token and protects both provider routes and `/admin-api/*`. Tests do not need production credentials. Resolve the hosted base URL from the Aspire resource (`GetEndpoint("http")` / `CreateHttpClient(...)`), then append the TCK route.
-
-### SystemOne: Jev and Kev
-
-Jev requires `model`, string/object/array `state`, and a nonempty question map. Kev accepts any JSON `state`, including numbers, booleans and null; instructions and criterion descriptions also accept arbitrary JSON. Kev defaults an omitted `model` to `kev-latest`; the TCK enables that default only when `AddKevLatest()` explicitly registers the Kev profile. Binary questions use `type: "noul"`; optional `criteria` maps the native `true` and `false` descriptions. Choices use an opaque ID-to-description map. Scores use an ordered criteria array.
-
-```json
-{
- "model": "kev-latest",
- "state": { "message": "Please help quickly" },
- "questions": {
- "urgent": { "type": "noul", "instructions": "Is urgent?", "criteria": { "true": "needs prompt help", "false": "can wait" } },
- "route": { "type": "choice", "instructions": "Choose the queue", "criteria": { "fast": "urgent", "regular": "routine" } },
- "severity": { "type": "score", "instructions": "Assess severity", "criteria": ["low", "medium", "high"] }
- }
-}
-```
-
-Use `model: "jev-latest"` for Jev. Native responses contain keyed `answers`: `noul`, or `choice`/`score` with `confidence` and `probabilities`; score `legend` keys are zero-based numeric strings. `usage` contains `input_tokens` and `output_tokens`. Scores are native ordinal values and can exceed one.
-
-```csharp
-using ManagedCode.LlmTck.Decisions;
-
-options.AddKevLatest().AddDecisionScenario(new LlmTckDecisionScenario
-{
- Id = "priority", ModelId = "kev-latest",
- Answers = new()
- {
- ["urgent"] = new() { Kind = LlmTckDecisionKind.Predicate, Probability = 0.95 },
- ["route"] = new() { Kind = LlmTckDecisionKind.Choice, Choice = "fast", Confidence = 0.9,
- Probabilities = new() { ["fast"] = 0.95, ["regular"] = 0.05 } },
- ["severity"] = new() { Kind = LlmTckDecisionKind.Score, Score = 1.75, Confidence = 0.625,
- Probabilities = new() { ["0"] = 0.05, ["1"] = 0.15, ["2"] = 0.8 } },
- },
- Usage = new() { InputTokens = 100, OutputTokens = 10, TotalTokens = 110 },
-});
-```
-
-Kev score legends contain rendered strings, while Jev retains string/object/array criteria. Kev responses include `latency_ms`; `LlmTckDecisionScenario.Metadata` supplies deterministic latency and optional `Truncated`, `StateTokens`, `StateTokensUsed` fields. The route echoes or generates `x-typesafe-request-id`, including on errors. Invalid SystemOne request shapes return HTTP 422 with a native `detail` validation array; runtime/admission faults retain `detail` strings. Kev bearer failures include `WWW-Authenticate: Bearer`. This compatibility surface covers `/v1/systemone`; Kev demo `/permute` and `/separate` routes are outside its scope.
-
-### Cloudflare Workers AI: Clef and Clef Flash
+| Chat scenarios | Contains or exact prompt matching, queued replies, streaming chunks, delays, scripted errors, per-scenario keys | [Configuration](docs/Reference/Configuration.md) |
+| Tool calls and structured output | Function calls validated against your schemas, JSON responses, well-known tools, tool failures | [Tools](docs/Features/ToolAndStructuredFixtures.md) · [Well-known tools](docs/Features/WellKnownFunctionTools.md) · [Tool faults](docs/Features/ToolFaultFixtures.md) |
+| Multi-turn conversations | Typed step graphs with branches, tool-result checks and terminal states | [Conversation DSL](docs/Features/ConversationDSL.md) |
+| Streaming | Provider-native SSE and NDJSON streams with usage where the provider reports it, plus delivery faults | [Stream delivery faults](docs/Features/StreamDeliveryFaults.md) |
+| Failure paths | 429 rate limits and content filters on every provider family | [Fault simulation](docs/Reference/Configuration.md#fault-simulation) |
+| More than text | Embeddings, images, speech, transcription, translation and video jobs | [Modalities](docs/Reference/Configuration.md#modalities) |
+| Native provider tools | OpenAI web search, file search and code; Anthropic web search; Responses continuation | [OpenAI web search](docs/Features/OpenAiNativeWebSearch.md) · [File/code](docs/Features/OpenAiNativeFileCode.md) · [Anthropic](docs/Features/AnthropicNativeWebSearch.md) · [Continuation](docs/Features/ResponsesContinuation.md) |
+| Parallel tests | Isolated sessions with their own configuration, queues, cache and journal | [Test sessions](docs/Features/TestSessions.md) |
+| Verification | Query and export the request journal, verify counts, order and tool arguments, fix IDs and clocks | [Verification and determinism](docs/Features/RequestVerificationAndDeterminism.md) |
+| Native decision APIs | TypeSafe Jev, Kev (System One), Cloudflare Clef, OpenAI Decisions | [Decision contracts](docs/Features/DecisionModels.md) · [Jev 1.14](docs/Features/Jev114.md) |
+| Official SDKs | OpenAI, Azure OpenAI, Foundry, Anthropic, Google Gen AI, Bedrock and `Microsoft.Extensions.AI` | [Clients and SDKs](docs/Reference/Clients.md) · [SDK compatibility](docs/Features/ProviderSdkCompatibility.md) |
+
+Everything is a fixture you choose: nothing is hidden behind retries or randomness, and the server never calls a real
+model.
+
+## Dashboard tour
+
+The dashboard at `/` is a request inbox: one row per provider call, with the full request, response, conversation,
+payloads, stream chunks, tokens and runtime result one click away.
+
+| Request overview | Conversation | Runtime diagnostics |
+| --- | --- | --- |
+| [](docs/images/showcase-overview.jpg) | [](docs/images/showcase-conversation.jpg) | [](docs/images/admin-dashboard-runtime.jpg) |
+| What was sent, what came back, and what it cost in tokens. | Each turn with its role and token share. | Fixtures, provider routes, assertions and the event timeline. |
-Send the same SystemOne question shape to the account/model route with body `model: "clef"` or `"clef-flash"` matching the route. Every question requires instructions. Binary `criteria.true` and `criteria.false` accept arbitrary JSON, including numbers, booleans and null; `criteria` itself must remain an object. State and instructions retain their documented string/object/array types, choice descriptions accept string/object/array/null, and score descriptions accept string/object/array. Responses wrap the native answer object in the Workers AI envelope:
+## Providers
-```json
-{
- "result": {
- "model": "clef",
- "answers": { "urgent": { "type": "noul", "noul": 0.95 } },
- "usage": { "input_tokens": 100, "output_tokens": 0 }
- },
- "success": true,
- "errors": [],
- "messages": []
-}
-```
+Each provider family lives under its own namespace and keeps its native request and response shapes.
-Configure `AddClef()` / `AddClefFlash()` and fixtures with the matching short model ID; native surrounding model whitespace is accepted. Runtime/auth failures remain non-success HTTP responses and use `success: false` with native numeric `errors[].code`. Explicit numeric scenario error codes are preserved, including 5004/400 (invalid input), 3007 or 3008/408 (timeout), 3036 or 3040/429 (capacity/rate limit). See [native errors](https://developers.cloudflare.com/workers-ai/platform/errors/). For native error cases, configure the explicit numeric `LlmTckScenarioError.Code`. Unmapped TCK-only errors such as fixture mismatch use the HTTP status as a synthetic code; that fallback is not a claimed Cloudflare native error code.
+| Provider | Namespace | Provider | Namespace |
+| --- | --- | --- | --- |
+| OpenAI | `/openai` | Mistral | `/mistral` |
+| Azure OpenAI | `/azure-openai` | Ollama | `/ollama` |
+| Microsoft Foundry | `/microsoft-foundry` | Cohere | `/cohere` |
+| Anthropic | `/anthropic` | Amazon Bedrock | `/bedrock` |
+| Gemini | `/gemini` | OpenRouter | `/openrouter` |
+| Groq | `/groq` | DeepSeek | `/deepseek` |
+| Perplexity | `/perplexity` | TypeSafe Jev / Kev (System One) | `/systemone` |
+| Cloudflare Clef / Clef Flash | `/cloudflare` | | |
+
+Operation coverage differs by provider and grows over time. A provider being listed does not mean every API of that
+provider is implemented — check the [operation coverage](docs/Features/ProviderApiContractCoverage.md) and
+[routes reference](docs/Reference/ProvidersAndRoutes.md) for the exact contracts.
+
+## TypeSafe and Jev
+
+**TypeSafe is the provider; Jev is its model family. System One is the native API.**
+Use `ManagedCode.LlmTestServer.SystemOne` for its request and response contracts, and
+`ManagedCode.LlmTestServer.Client` for `control.CreateSystemOneClient()`.
+The native server route is `POST /systemone/v1/systemone`.
+
+Configure deterministic answers for predicates, choices, scores and Jev 1.14 bounding boxes.
+JSON image assets and multipart uploads are supported with explicit image opt-in.
+Kev uses the same protocol package with its own compatibility profile.
+
+[Configure and call Jev from a test](docs/Reference/Clients.md#typesafe-jev-through-system-one) ·
+[Jev 1.14 images and limits](docs/Features/Jev114.md) ·
+[Native decision fixtures](docs/Features/DecisionModels.md)
-Optional `images` is an array of inline data URLs or `{ "content_type": "image/png", "base64": "..." }` objects. PNG/JPEG/WebP are supported; remote URLs are rejected. Limits: four images, 4 MiB decoded file bytes and 16 megapixels per image, 8 MiB combined decoded bytes, and 13 MiB for the complete request body. Image dimensions and file type are read as metadata; compressed pixel streams are not decoded, so full raster validity is outside this deterministic mock validation. The TCK retains supplied images in the matched input and trace. See [input schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-input.json), [output schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-output.json).
+## Packages
-### OpenAI Decisions
+| Package | Use it for |
+| --- | --- |
+| `ManagedCode.LlmTestServer.Aspire` | Add the server to an AppHost or Aspire test with `AddLlmTestServer()`. |
+| `ManagedCode.LlmTestServer.Client` | Configure, reset, query and verify from tests; `IChatClient`, embedding and image clients. |
+| `ManagedCode.LlmTestServer.Hosting` | Embed the server and dashboard in your own ASP.NET Core host. |
+| `ManagedCode.LlmTestServer` | The provider-neutral runtime: models, scenarios, usage and assertions. |
+| `ManagedCode.LlmTestServer.` | Wire contracts for each provider family listed above. |
+| `ManagedCode.LlmTestServer.SystemOne` | Native TypeSafe Jev and Kev contracts for the System One API. |
+| `ManagedCode.LlmTestServer.Cloudflare` | Native Cloudflare Clef and Clef Flash decision contracts. |
-OpenAI uses `input` and an ordered question array. Predicate questions return one probability; boolean choices can carry separate true/false descriptions. Choice values are typed strings or booleans. Score `levels` use ordered string labels and optional descriptions; responses retain the zero-based level index and original label.
+The full list with NuGet links is in [providers, packages and routes](docs/Reference/ProvidersAndRoutes.md#packages).
-```json
-{
- "model": "gpt-6-luna",
- "input": "Please help quickly",
- "questions": [
- { "type": "predicate", "name": "urgent", "instructions": "Is urgent?" },
- { "type": "choice", "name": "route", "instructions": "Choose the queue", "choices": [
- { "value": "fast", "description": "urgent" }, { "value": false, "description": "defer" }
- ] },
- { "type": "score", "name": "severity", "instructions": "Assess severity", "levels": [
- { "label": "low", "description": "low" }, { "label": "medium", "description": "medium" }, { "label": "high", "description": "high" }
- ] }
- ]
-}
-```
+## Learn more
-OpenAI fixture question IDs use `OpenAiDecisionFixtureIds.ForQuestionIndex(index)` for the zero-based position, regardless of optional native names. Choice fixture IDs use `ForChoiceValue(string/bool)` canonical JSON literals so string `"true"` differs from boolean `true`. Responses preserve names (including `null`), duplicate names and answer order.
+- [Installation and hosting](docs/Reference/Installation.md) — local feed, container, ASP.NET Core, Aspire, building from source
+- [Configuration and scenarios](docs/Reference/Configuration.md) — models, scenarios, modalities, faults, assertions
+- [Clients and SDKs](docs/Reference/Clients.md) — control client, official SDKs, `Microsoft.Extensions.AI`, TypeSafe client
+- [Token usage and prompt cache](docs/Reference/TokenUsageAndPromptCache.md) and [dashboard analytics](docs/Features/DashboardAnalytics.md)
+- [Providers, packages and routes](docs/Reference/ProvidersAndRoutes.md) and [operation coverage](docs/Features/ProviderApiContractCoverage.md)
+- [Architecture](docs/Architecture.md), [test inventory](docs/Testing/AcceptanceCriteriaTestInventory.md) and [delivery plan](docs/Features/LlmTestServerDeliveryPlan.md)
-```csharp
-using ManagedCode.LlmTck.Decisions;
-using ManagedCode.LlmTck.OpenAI;
+## Build from source
-var fast = OpenAiDecisionFixtureIds.ForChoiceValue("fast");
-var defer = OpenAiDecisionFixtureIds.ForChoiceValue(false);
-options.AddOpenAiDecisionModel("gpt-6-luna").AddDecisionScenario(new LlmTckDecisionScenario
-{
- Id = "priority-openai", ModelId = "gpt-6-luna",
- Answers = new()
- {
- [OpenAiDecisionFixtureIds.ForQuestionIndex(0)] = new() { Probability = 0.95 },
- [OpenAiDecisionFixtureIds.ForQuestionIndex(1)] = new() { Kind = LlmTckDecisionKind.Choice, Choice = fast,
- Confidence = 0.9, Probabilities = new() { [fast] = 0.9, [defer] = 0.1 } },
- [OpenAiDecisionFixtureIds.ForQuestionIndex(2)] = new() { Kind = LlmTckDecisionKind.Score, Score = 1.75,
- Confidence = 0.8, Probabilities = new() { ["0"] = 0.05, ["1"] = 0.15, ["2"] = 0.8 } },
- },
- Usage = new() { InputTokens = 100, CachedInputTokens = 4, OutputTokens = 0, TotalTokens = 100 },
-});
+```sh
+dotnet restore ManagedCode.LlmTestServer.slnx
+dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
+dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build
```
-`input` can also be an array of user messages: string content or `input_text` / `input_image` parts. Images use embedded base64 data URLs; external URLs, file IDs, audio, tools and non-user roles are rejected. Usage retains input/output/total tokens, cached/cache-write input details and reasoning output details, including zero defaults. Set `Refused = true` on an answer fixture to emit a native `{"type":"refusal","name":...}` answer in a successful HTTP response.
-
-### Limits, fixture matching and failures
-
-| Profile | Choice criteria | Score criteria | Other native constraints |
-| --- | --- | --- | --- |
-| TypeSafe Jev | Up to 255 | 1..10 | Optional instructions and binary criteria; state is string/object/array, including JSON descriptions and nullable optional instructions. |
-| Kev | 1..255 | 1..255 | Any JSON state/instructions/descriptions, empty opaque IDs; probabilities/native scores rounded to four decimals. |
-| Cloudflare Clef/Flash | 2..255 | 2..10 | 1..64 questions; ASCII letter/digit/underscore/dot/hyphen IDs, max 100 characters; required nonempty instructions; four-decimal probabilities/native scores. |
-| OpenAI | 2..255 distinct typed values | Ordered labels; no undocumented count cap | Optional names/descriptions, empty strings and repeated score labels preserved; max 128 embedded images; model/names/instructions/labels/descriptions max 1,048,576 characters; no invented choice-value length cap. |
+Packing, coverage and package verification are described in [installation](docs/Reference/Installation.md#build-and-test).
-`AddDecisionModel(id, LlmTckDecisionProvider...)` supports explicit custom model IDs; the control client mirrors it with `UseDecisionModel` and `UseDecisionScenario`. Fixtures are repeatable snapshots. Optional `ExpectedInput` matches the provider input exactly; SystemOne JSON state and OpenAI message arrays use serialized JSON. Cloudflare requests with supplied images match serialized `{state,images}`; text-only requests retain the state-only input. Question IDs, kinds and requested value domains must fit the fixture. Unknown models, unmatched inputs, mismatched fixtures, authentication, configured rate limits/content filtering and scripted errors produce observable non-success HTTP responses. Normal native choice/score fixtures require confidence and a complete probability domain, near-unit probability mass. SystemOne and Cloudflare choices must have maximal probability; OpenAI preserves any selected value in the supplied domain. Cloudflare confidence must equal the maximum probability within native rounding tolerance. Configure profile-correct explicit values: the Kev/Jev example above has score confidence 0.625; Clef uses the maximum probability 0.8. Values are validated and preserved without normalization or recomputation. Four-decimal distributions may total 0.9999 and native scores are not recomputed from rounded probabilities. For deliberate malformed-response regressions, set `AllowMalformedResponse = true` on the scenario; this explicitly bypasses native response conformance while keeping question-kind/domain mapping safe.
+## License
-See [complete native contracts and fixture details](docs/Features/DecisionModels.md) and [behavior-test evidence](docs/Testing/AcceptanceCriteriaTestInventory.md). Provider-specific limits and optional-field rules above are reconciled against the linked primary contracts.
+[MIT](LICENSE)
diff --git a/docs/ADR/ADR-0001-package-boundaries.md b/docs/ADR/ADR-0001-package-boundaries.md
index 3949a28..9f808e2 100644
--- a/docs/ADR/ADR-0001-package-boundaries.md
+++ b/docs/ADR/ADR-0001-package-boundaries.md
@@ -6,17 +6,17 @@ Accepted
## Context
-LLM TCK needs to support several provider protocols while keeping deterministic test behavior consistent. Mixing provider DTOs, runtime state, host wiring, and client abstractions in one package would make future providers harder to add and harder to test.
+LLM Test Server needs to support several provider protocols while keeping deterministic test behavior consistent. Mixing provider DTOs, runtime state, host wiring, and client abstractions in one package would make future providers harder to add and harder to test.
## Decision
Use separate packages:
-- Core runtime: `ManagedCode.LlmTck`
-- Provider wire mapping: `ManagedCode.LlmTck.OpenAI`
-- ASP.NET Core hosting: `ManagedCode.LlmTck.Hosting`
-- Typed clients and `Microsoft.Extensions.AI`: `ManagedCode.LlmTck.Client`
-- Aspire AppHost extensions: `ManagedCode.LlmTck.Aspire`
+- Core runtime: `ManagedCode.LlmTestServer`
+- Provider wire mapping: `ManagedCode.LlmTestServer.OpenAI`
+- ASP.NET Core hosting: `ManagedCode.LlmTestServer.Hosting`
+- Typed clients and `Microsoft.Extensions.AI`: `ManagedCode.LlmTestServer.Client`
+- Aspire AppHost extensions: `ManagedCode.LlmTestServer.Aspire`
## Consequences
diff --git a/docs/ADR/ADR-0002-aspire-hosted-provider-emulation.md b/docs/ADR/ADR-0002-aspire-hosted-provider-emulation.md
index 7f58170..b56e204 100644
--- a/docs/ADR/ADR-0002-aspire-hosted-provider-emulation.md
+++ b/docs/ADR/ADR-0002-aspire-hosted-provider-emulation.md
@@ -6,11 +6,11 @@ Accepted
## Context
-The library is intended for integration tests, not only unit tests. It must start as a real service under Aspire so application resources can reference an LLM-compatible endpoint during test runs.
+Verification must use integration tests against the running server. It must start as a real service under Aspire so application resources can reference an LLM-compatible endpoint during test runs.
## Decision
-Ship an Aspire extension package that adds a package-owned LLM TCK resource to an AppHost with `builder.AddLlmTck()`. The consumer AppHost should not need a service project reference, generated `Projects.*` metadata type, project path, Docker, or a container runtime. The default resource starts the packaged .NET LLM TCK service executable. Container hosting remains available through an explicit `builder.AddLlmTckContainer()` opt-in for deployment or container-runtime smoke tests. The integration test builds the AppHost model directly in test code with `Aspire.Hosting.Testing`, adds the TCK through `ManagedCode.LlmTck.Aspire`, starts the .NET resource, then calls the running service through `Microsoft.Extensions.AI`, Azure OpenAI, Microsoft Foundry, and HTTP endpoints.
+Ship an Aspire extension package that adds a package-owned LLM Test Server resource to an AppHost with `builder.AddLlmTestServer()`. The consumer AppHost should not need a service project reference, generated `Projects.*` metadata type, project path, Docker, or a container runtime. The default resource starts the packaged .NET LLM Test Server service executable. Container hosting remains available through an explicit `builder.AddLlmTestServerContainer()` opt-in for deployment or container-runtime smoke tests. The integration test builds the AppHost model directly in test code with `Aspire.Hosting.Testing`, adds the Test Server through `ManagedCode.LlmTestServer.Aspire`, starts the .NET resource, then calls the running service through `Microsoft.Extensions.AI`, Azure OpenAI, Microsoft Foundry, and HTTP endpoints.
## Consequences
diff --git a/docs/ADR/ADR-0003-isolated-test-sessions.md b/docs/ADR/ADR-0003-isolated-test-sessions.md
new file mode 100644
index 0000000..f6d4baa
--- /dev/null
+++ b/docs/ADR/ADR-0003-isolated-test-sessions.md
@@ -0,0 +1,49 @@
+# ADR-0003: Isolated test sessions
+
+Status: Implemented and locally qualified
+Date: 2026-10-20
+Related feature: [delivery plan E2](../Features/LlmTestServerDeliveryPlan.md)
+
+## Context and decision
+
+A shared server currently has one runtime and journal. Configure/reset affects every client, so parallel tests can consume each other's queues and erase history. Keep the existing default runtime for callers without session headers. Hosting owns a bounded session registry; each session owns a core runtime and HTTP journal. Request-scoped DI selects the same session for provider mapping, tracing and control endpoints.
+
+`POST /admin-api/sessions` authenticates against the default runtime and accepts an optional `configuration`. Omission clones the startup configuration. The response returns an opaque ID, a random access key and reserved state bytes. Provider/control calls must send both `X-Llm-Test-Server-Session` and `X-Llm-Test-Server-Session-Key`. These headers are independent of provider bearer/API credentials. Unknown IDs, missing/wrong keys and foreign deletion return 404 before tracing or invoking a runtime. Session keys are redacted in diagnostics and never used as provider credentials. Creation responses use `Cache-Control: no-store`.
+
+`DELETE /admin-api/sessions/{id}` requires that session's ID/key pair. It removes the registry entry and resets its runtime, invalidating pending delayed responses through the existing runtime generation contract. Reset/configure inside a session affects only that session. Default reset/configure does not delete sessions. Explicit disposal is the lifetime boundary; there is no background expiration or persistence.
+
+```mermaid
+flowchart LR
+ Client --> Headers[Session ID and access key]
+ Headers --> Registry[Bounded Hosting registry]
+ Registry --> Default[Default runtime and journal]
+ Registry --> A[Session A runtime and journal]
+ Registry --> B[Session B runtime and journal]
+ A --> StateA[Queues history cache faults video assertions]
+ B --> StateB[Queues history cache faults video assertions]
+```
+
+## Bounds and concurrency
+
+`LlmTestServerSessionOptions` sets maximum session count, aggregate reserved state bytes and serialized configuration bytes. Reservations include configured history/video limits, prompt-cache/job/response overhead, journal retention, UTF-16 event retention and the configuration snapshot. This is an admission budget for retained server state, not a measurement of managed heap/transient HTTP allocation. Oversized configuration returns 400; exhausted count/aggregate capacity returns 409. Configure builds a validated replacement runtime, checks admission, then swaps it and retires the previous runtime atomically under the registry gate; invalid configuration is rejected before admission checks. It adjusts the reservation only on success; delete releases it. Existing runtime count/byte limits remain effective within every session. Registry admission/configure/delete is serialized; independent provider requests execute against their own runtimes.
+
+The client exposes `CreateSessionAsync(...)`, a scoped `HttpClient` for official SDK transports, and `Control`. `await using` deletes server state. The wrapper applies headers per request and leaves the caller-owned underlying transport alive, so parallel session clients never mutate shared default headers.
+
+## Alternatives and consequences
+
+- A correlation header on the singleton runtime cannot isolate cursors or reset and is rejected.
+- One process per session isolates state but adds AppHost/process lifecycle costs and is rejected for shared-server tests; separate hosts remain supported.
+- Ambient mutable singleton selection is rejected because concurrent awaits could cross-contaminate sessions.
+- A request DI scope and explicit registry preserve all provider adapters and core state owners. The browser's interactive session selector remains E13 work; the default dashboard continues to inspect the default runtime.
+
+## Verification plan
+
+Use HTTP/official SDK integration tests for simultaneous identical prompts, independent queues, reset/configure/dispose, cross-key access, separate journals/history/cache/fault/video state, count and byte admission, invalid configuration atomicity, streaming/cancellation and delayed in-flight deletion. Run the full provider integration suite, formatter, canonical Release build and unchanged 90% production coverage gate. No unit/source/reflection tests.
+
+## Qualification evidence
+
+The complete integration-only suite passed 655/655 with 91.17% production line coverage. Canonical Release build
+and format verification passed with zero warnings/errors. An isolated NuGet consumer restored the repacked
+Core/Client/Hosting/Aspire artifacts, started the packaged service with Aspire and verified session API isolation,
+provider calls and the interactive Chromium dashboard (1/1). Session verification logs are retained under
+the repository-owned `artifacts` directory; public NuGet publication belongs to the combined release batch.
diff --git a/docs/ADR/ADR-0004-conversation-step-graphs.md b/docs/ADR/ADR-0004-conversation-step-graphs.md
new file mode 100644
index 0000000..4ae52f6
--- /dev/null
+++ b/docs/ADR/ADR-0004-conversation-step-graphs.md
@@ -0,0 +1,81 @@
+# ADR-0004: Typed conversation step graphs
+
+Status: Accepted; implemented and locally qualified, public delivery pending
+Date: 2026-10-20
+Related: [conversation DSL](../Features/ConversationDSL.md), [delivery E3](../Features/LlmTestServerDeliveryPlan.md),
+[test sessions](../Features/TestSessions.md), [architecture](../Architecture.md)
+
+## Decision and context
+
+Linear scenarios match historical messages and consume a linear queue. A workflow needs a condition for each
+incoming turn, explicit alternative transitions, tool-result checks, terminal behavior and readable mismatch
+reports. Add an optional typed conversation graph to the existing scenario model. Keep linear queues unchanged.
+Graphs run inside the existing runtime and inherit session configuration/reset/disposal ownership.
+
+Each step has one response, serializable match predicates and either ordered next-step IDs or an explicit
+terminal marker. Predicates cover latest role/text, normalized turn index, tool name/call ID, exact JSON arguments
+and JSON-field equality in the latest content. Branch selection uses the declared next-step order. Diagnostic
+APIs report selected/shadowed rules, mismatch field names and unvisited steps without consuming state.
+
+```mermaid
+flowchart LR
+ Start[Start step] --> Approve[Approve predicate]
+ Start --> Cancel[Cancel predicate]
+ Approve --> Tool[Tool-result predicate]
+ Tool --> Final[Terminal response]
+ Cancel --> Done[Terminal cancellation]
+```
+
+## Identity and ordering
+
+`X-Llm-Test-Server-Conversation` optionally selects independent conversations inside one session. The default
+is `default`. State is also partitioned by scenario identity, provider namespace and provider credential hash.
+A typed conversation client applies its header per request without changing the shared transport's headers.
+
+Logical turn index is one plus the number of consecutive assistant-message groups in the normalized input,
+ignoring system/developer messages. Parallel function-call items in Responses form one assistant group. HTTP
+attempts do not increment this index. Clients provide full history or use stored Responses continuation.
+
+An identical retry of the last successful normalized request replays the same runtime result and does not
+advance the graph. Streaming mode does not create a new logical request. Scripted error steps can explicitly
+transition to a recovery step at the same logical turn. Older/changed input at an already successful turn is
+rejected. Graphs allow one in-flight step; cancellation and fixture/history-capacity failures roll back their
+reservation. Reset/configure/delete invalidate pending work through the runtime generation/lifetime contract.
+
+## Bounds and exhaustion
+
+Runtime configuration bounds conversation count and retained state bytes; admission and response reservations
+fail explicitly without eviction. Graphs have bounded step count and execution limits. Terminal policies are
+Reject, RepeatLastResponse and Restart. Restart clears execution and visited-step counters for a new run;
+the execution limit guards cycles within a run. Normal successful-request replay is independently configurable
+and precedes terminal handling. Only the latest successful normalized request is retained for replay.
+Unvisited alternative branches are diagnostic information, not proof that an expected active branch was skipped.
+
+## Consequences and implementation
+
+The graph, predicates and responses share the existing configuration snapshot/HTTP contract. Core owns matching,
+bounded admission and transition commit/rollback; Hosting passes request identity and exposes diagnostics;
+Client owns the typed header wrapper. No new package, persistence layer or executable configuration delegates
+are required. Linear scenarios remain unchanged. Graph state and last-result retention add explicit runtime
+admission budgets, including sessions' aggregate reservation accounting.
+
+Retained responses enable deterministic runtime replay without promising identical provider-generated wire
+IDs or timestamps. State persists until reset/configure/session disposal; local conversation-client disposal
+only releases its transport wrapper. Tests must manage that session lifetime explicitly.
+
+Implementation sequence: graph DTO/builders and validation; runtime selection/reservation/replay; hosted identity
+and control routes; typed client and diagnostics; HTTP/SDK qualification and installed-consumer verification.
+The implementation is locally qualified: the full server integration suite passed 722/722, production line coverage is 91.34%, and the independent installed-package consumer passed 1/1. Public release remains pending the combined delivery batch.
+
+## Alternatives
+
+- Matching every request against all historical user messages cannot identify the current workflow step.
+- Embedding server delegates in configuration cannot survive HTTP configuration or fixture export.
+- A separate workflow process/store duplicates runtime/session ownership and is unnecessary.
+
+## Verification plan
+
+Run HTTP/provider SDK tool loops and branches, retry/error/terminal flows, JSON predicates, malformed graphs,
+capacity, cancellation/reset and credential/provider/conversation isolation. Verify explanations through control
+APIs and event metadata. Run the unchanged full integration/coverage gate and installed-package consumer.
+The exact commands and acceptance boundaries are maintained in [Conversation DSL](../Features/ConversationDSL.md#verification-and-completion-criteria).
diff --git a/docs/ADR/ADR-0005-request-evidence-and-wire-determinism.md b/docs/ADR/ADR-0005-request-evidence-and-wire-determinism.md
new file mode 100644
index 0000000..c088457
--- /dev/null
+++ b/docs/ADR/ADR-0005-request-evidence-and-wire-determinism.md
@@ -0,0 +1,95 @@
+# ADR-0005: Request evidence and seeded wire metadata
+
+Status: Accepted; implemented and locally qualified, public delivery pending
+Date: 2026-10-20
+Related: [feature contract](../Features/RequestVerificationAndDeterminism.md),
+[delivery E4](../Features/LlmTestServerDeliveryPlan.md), [architecture](../Architecture.md),
+[session ownership](ADR-0003-isolated-test-sessions.md), [conversation graphs](ADR-0004-conversation-step-graphs.md).
+
+## Context and decision
+
+Tests need machine-readable request evidence, assertions about complete tool/conversation/retry flows, and
+repeatable generated IDs/time. The dashboard already has a bounded request journal. Reusing that journal
+keeps UI, query, export and verification aligned; explicit retention counters prevent missing evidence from
+being interpreted as a successful assertion.
+
+Keep request evidence in the existing session-owned Hosting journal. Move public trace/query DTOs into core
+`Diagnostics`; put serializable expectation DTOs and the pure evaluator in core `Verification`. Hosting captures
+real HTTP behavior and exposes authenticated query/export/verify endpoints. Client wraps those contracts.
+No second store, new package or recorded-byte cassette format is introduced by this decision.
+
+```mermaid
+flowchart LR
+ Session[Session runtime] --> Wire[Seeded wire metadata]
+ Session --> Events[Real runtime observations]
+ HTTP[Provider HTTP requests] --> Journal[Existing bounded trace journal]
+ Events --> Journal
+ Journal --> Snapshot[Snapshot with retention evidence]
+ Snapshot --> Query[Query and versioned export]
+ Snapshot --> Verify[Serializable verification]
+ Graph[Conversation status] --> Verify
+```
+
+## Evidence ownership and completeness
+
+Journal sequence identifies observed request ordering, while an attempt ID correlates runtime and HTTP evidence.
+Explicit retry-group IDs group attempts without replacing their IDs. Query/export/verification share snapshot
+filter semantics. Export version 1 includes query and retention metadata; NDJSON starts with a metadata record.
+It is a diagnostic export of retained evidence, not full-fidelity recording.
+
+Eviction, truncation, selected pending requests or omitted matching pages prevent `Passed`, even if retained
+requests happen to match expectations. This conservative rule applies to the selected journal and is reset
+with its session. Tool assertions use structured request history and response calls, including call/result IDs;
+JSON previews are bounded display data and cannot substitute for missing evidence.
+
+Terminal evidence is recorded after a protocol's final marker is successfully written/flushed. Transport EOF
+alone is insufficient. Bedrock InvokeModel currently has no explicit marker, so terminal-marker expectations
+are inapplicable to that operation. Assertions still inspect its request count, outcome and other available data.
+
+Retry verification uses real monotonic start/completion timestamps for spacing, independently of wall-clock
+changes. HTTP-date Retry-After values are interpreted using the observed UTC completion time; elapsed waiting
+is compared monotonically. Missing or invalid timing fails completeness. Scripted Retry-After fixtures advertise
+policy; the application or real provider SDK performs the retry.
+
+## Wire metadata and lifecycle
+
+Each session runtime owns provider-local request ordinals and optional `LlmTestServerDeterminism` configuration.
+At provider request entry it derives immutable `LlmTestServerResponseMetadata` from seed, provider namespace
+and ordinal. Domain-derived IDs preserve native provider prefixes. Results and stream chunks reuse that
+metadata; stored responses and successful conversation replay retain it. Reset/configure clear counters along
+with scenario state. Control reads do not reserve provider ordinals.
+
+Fixed mode controls generated wire fields and HTTP Date. Explicit fixture fields, model dictionaries and video
+configuration retain their own values. Event/trace observation timestamps and elapsed/monotonic timing remain
+real. Traces expose `WireClockMode`, `WireCreatedAt` and `WireSequence` so callers can distinguish those clocks;
+replay enrichment reports retained result metadata rather than the new attempt's initial reservation.
+Session identifiers and access keys remain random security credentials. The seed is not a credential.
+
+## Alternatives and consequences
+
+- A second assertion store would introduce separate retention/ordering semantics and duplicate capture.
+- A process-global seeded random generator or clock would couple independent sessions and providers.
+- Replacing observation time with fixture time would invalidate retry and cancellation evidence.
+- Inferring complete assertions from previews or successful EOF would conceal evidence loss and absent markers.
+
+The chosen design provides one bounded evidence source, repeatable fixture identity and observable clock policy.
+Its limits are explicit: eviction invalidates complete verification, request entry determines ordering within a
+provider under concurrency, and diagnostic exports do not preserve unretained bytes. Tests should use fresh
+sessions and adequate retention. Fixed metadata adds no persistence, upstream call or additional executable
+configuration mechanism.
+
+## Implementation and verification
+
+Implement core DTO/query/verification contracts; extend the existing journal with sequence/retention counters,
+structured tools and real monotonic timing; expose query/export/verify and typed clients; thread wire metadata
+through runtime/provider adapters; qualify complete real HTTP/SDK flows and installed-package use.
+
+Verification must prove positive and negative counts/order/tools/graph/retry outcomes, auth/session isolation,
+incomplete retention/paging/pending evidence, terminal applicability, fixed seed/reset/replay IDs and independent
+session/provider counters. Wire timestamps and real observation timestamps must be independently asserted.
+The feature's [verification commands](../Features/RequestVerificationAndDeterminism.md#verification-and-completion-criteria)
+include the full integration/format/Release build/coverage gates. Local E4 qualification passed 812/812
+integration tests, 91.66% production line coverage, final Release build with zero warnings/errors, all 19 package
+builds and the independent clean installed Aspire/official SDK/Chromium consumer (1/1). Evidence is recorded
+in the [delivery ledger](../Features/LlmTestServerDeliveryPlan.md#11-журнал-реалізації). E4 branch CI and public
+publication remain pending; local package acceptance is not public-release evidence.
diff --git a/docs/ADR/ADR-0006-ordered-native-tool-output.md b/docs/ADR/ADR-0006-ordered-native-tool-output.md
new file mode 100644
index 0000000..d7d3b9f
--- /dev/null
+++ b/docs/ADR/ADR-0006-ordered-native-tool-output.md
@@ -0,0 +1,150 @@
+# ADR-0006: Ordered native tool fixtures on the existing conversation engine
+
+Status: Accepted; bounded OpenAI web/file/code contracts locally qualified; public delivery pending
+Date: 2026-10-20
+Related: [native tool inventory](../Features/NativeBuiltInToolContractInventory.md),
+[delivery plan](../Features/LlmTestServerDeliveryPlan.md),
+[conversation graphs](ADR-0004-conversation-step-graphs.md),
+[request evidence](ADR-0005-request-evidence-and-wire-determinism.md).
+
+## Context and decision
+
+A hosted provider tool returns provider-native call items, citations and lifecycle events. Treating it as a
+function call loses its contract and can cause a client to attempt an external function invocation. Separate
+text/function/native lists also lose the order of mixed response items and break continuation history.
+
+Add a typed ordered output plan to the existing scenario/conversation response, chat result and retained
+assistant history. Keep the current reservation, cancellation, graph progression, replay and session ownership.
+The first qualified contract targets completed OpenAI Responses web searches. Bounded completed file-search
+and code-interpreter contracts now use the same engine and are locally qualified. Other native
+families, broader options and providers remain in E5/E10 and require their own adapters and evidence.
+The expanded contract is documented in [OpenAI native file/code fixtures](../Features/OpenAiNativeFileCode.md).
+
+```mermaid
+flowchart LR
+ HTTP[Provider request] --> Adapter[Provider declaration validation]
+ Adapter --> Request[Typed declarations and history]
+ Request --> Engine[Existing scenario and conversation engine]
+ Engine --> Validate[Fixture validation before reservation]
+ Validate --> Plan[Ordered typed output plan]
+ Plan --> History[Existing bounded history and replay]
+ Plan --> Wire[Provider JSON and streaming mapping]
+ Plan --> Evidence[Existing bounded runtime and HTTP journals]
+```
+
+## Boundaries and data
+
+Core owns message/function/web-search/file-search/code fixture data, immutable snapshots, declaration options, semantic validation,
+ordering, usage accounting and capacity admission. The provider package owns its request and output unions,
+include projection, citation wire fields and streaming events. Hosting enables native contracts only on the
+qualified route, reads the request, calls the runtime and writes the mapped response.
+
+`LlmTestServerNativeToolSurface.OpenAiResponses` identifies the qualified route independently from each declaration's
+`Contract` (`LlmTestServerNativeToolContract`). The ordered output union includes message, function call, web search, file search and
+code interpreter. A separate ordered annotation union retains URL, file and container-file citations without
+regrouping annotations by kind. Control JSON uses `kind`; the provider adapter emits the corresponding API
+`type` discriminators. Native results remain outside function-call counters.
+
+Explicit output plans and ordinary Content/ToolCalls/StreamChunks are mutually exclusive in configuration.
+The engine projects a selected plan once into the existing text/function fields needed by matchers and clients,
+while retaining its authoritative ordered items. Ordinary fixtures keep their existing result fields and provider fallback mapping. This avoids two
+independently mutable representations in configuration JSON.
+
+Native declarations remain distinct from function definitions. A native result requires a matching declaration
+and qualified route/model contract. Named choices, none/required and parallel-call limits are checked against
+the complete selected plan before queue or graph consumption. Search domain restrictions apply to scripted
+sources and citations. Context/location options are retained for request identity and diagnostics; no live search
+is performed. Newer unimplemented native options are rejected explicitly rather than silently discarded.
+
+## History, identity and accounting
+
+All native items and the final assistant message belong to one logical assistant response. Explicit prior output
+items and stored-response continuation preserve their types, order, sources and citations. Native items never
+become synthetic user JSON or client tool-result messages. Stored-response access retains the existing provider
+namespace and credential boundary inside its session runtime. Conversation labels remain correlation/graph
+identities; an explicit previous_response_id selects the parent history.
+
+Deep-copy nested collections at configuration, history, replay and journal boundaries. Include native payloads
+in existing conversation/history byte limits and journal character budgets. Capacity rejection must not advance
+a response/step or mutate the prompt cache. Native declaration options participate in request fingerprints,
+cache identity and normalized input usage; native history/result payloads participate in normalized token counts.
+Cache and reasoning remain subsets of input/output totals.
+
+Explicit fixture IDs and existing seeded wire metadata preserve deterministic response identities. Native
+stream progress, output-item completion, citations and final completion must agree with ordinary JSON output.
+The terminal marker is observed only after the final response event has been written and flushed.
+
+## Bounded file/code extension
+
+The current independent model pairings are web search with `gpt-4.1-mini`, file search with `gpt-4o-mini`,
+and code interpreter with `gpt-4.1`. Model checks apply to current declarations/choices, while completed prior
+outputs remain history on the qualified surface. No common supported model is inferred for mixed native
+families from SDK serialization alone.
+
+File search preserves declared store IDs, max-result count, ranker, threshold and bounded comparison/compound
+filter trees. Configured results must already meet the count/score/filter restrictions; an admission mismatch
+returns 409 without consumption rather than silently rewriting fixture results. Strings compare ordinally;
+accepted numbers compare by decimal value, preserving precision in their JSON representation. Missing or
+mismatched attribute kinds do not match. Boolean ordering, hybrid ranking and unsupported option fields are
+rejected. The filter depth/node limits are explicit fixture limits, not claims about upstream limits.
+
+Code fixtures carry explicit container, input-file and generated-file references, nullable code/outputs and
+optional code chunks. Automatic request mode matches the configured input asset set and resolves to the
+configured container identity; it does not provision a container. Container-file citations reference that
+container and its input or explicitly generated references. Zero-length container citation ranges are permitted;
+the existing URL citation boundary remains positive-length. Cited text remains ASCII in this subset.
+
+Results/outputs include projection is provider-owned and leaves authoritative retained data intact. File/code
+JSON/SSE, structured diagnostic copies, native cache identity and explicit/stored continuation use the same
+bounded state paths. Memory/network controls, actual file retrieval and resource lifecycle remain pending.
+The initial 150 HTTP/SDK cases passed; expanded regression and final combined qualification remain pending.
+
+## First contract and remaining breadth
+
+The initial OpenAI contract uses gpt-4.1-mini, completed search actions, typed source URLs, URL citations and
+JSON/SSE Responses. The web-search guide reserves open_page/find_in_page for reasoning models; they require
+separate model-qualified implementation. The upstream citation schema does not establish an encoding convention
+for non-ASCII indexes. The initial cited-text fixture subset is explicitly ASCII, preserving supplied indexes;
+uncited text retains normal Unicode support. This boundary is visible in the feature/support inventory and does
+not remove Unicode qualification or other native tools from the delivery plan.
+
+No network search, code executor, file downloader, second work queue or unbounded resource registry is added.
+Files, vector stores, containers and generated-artifact lifecycle will reuse the appropriate session-owned
+bounded state when their E9 contracts are implemented.
+
+## Alternatives and consequences
+
+- A function-name shim would emit the wrong SDK item/event types and misrepresent hosted execution.
+- Provider JSON embedded as arbitrary core strings would bypass typed validation, budgets and history semantics.
+- A separate native scenario queue would split consumption, cancellation and replay ownership.
+- Mapping validation after CompleteChatAsync would reject a fixture only after consuming its queue/graph step.
+
+The chosen model adds explicit union/snapshot handling to existing state paths. Its cost is additional typed
+mapping and budget coverage; it keeps one engine and permits later native contracts to reuse ordering and
+ownership without pretending they share a provider wire format.
+
+## Verification
+
+Use running ASP.NET endpoints and the installed official Responses SDK. NativeWebSearch*IntegrationTests must
+prove typed JSON and streaming, mixed output order, include gating, explicit/stored continuation, named choices,
+invalid declarations and atomic configure failure, domain mismatch without consumption, route/model boundaries,
+reset/cancellation/replay, credential/session isolation and capacity limits. `NativeFileCodeIntegrationTests` must independently prove file/code models, typed SDK results and citations,
+nullable include behavior, filter operators/precision/bounds, explicit/auto resource matching, ordered streaming,
+malformed-ID/history rejection and no-consumption behavior. Provider contract/evidence suites and existing
+function/structured-output integrations remain mandatory regressions.
+
+Run the repository format check, canonical Release build, complete integration suite and coverage gate; pack
+all packages and qualify a clean installed-package consumer before claiming delivery. Qualification results are
+recorded in the delivery ledger only after the actual commands pass. Public publication remains the single
+owner-approved v1.0.0 launch batch.
+
+## References
+
+- [OpenAI web search](https://developers.openai.com/api/docs/guides/tools-web-search)
+- [Responses create](https://developers.openai.com/api/reference/resources/responses/methods/create)
+- [Responses streaming schema](https://developers.openai.com/api/reference/resources/responses/streaming-events)
+
+- [OpenAI file search](https://developers.openai.com/api/docs/guides/tools-file-search)
+- [OpenAI code interpreter](https://developers.openai.com/api/docs/guides/tools-code-interpreter)
+- [File-search model pairing](https://developers.openai.com/cookbook/examples/file_search_responses)
+- [Code-interpreter model pairing](https://developers.openai.com/cookbook/examples/mcp/mcp_tool_guide)
diff --git a/docs/Architecture.md b/docs/Architecture.md
index b868c97..4b77715 100644
--- a/docs/Architecture.md
+++ b/docs/Architecture.md
@@ -1,24 +1,24 @@
-# LLM TCK Architecture
+# LLM Test Server Architecture
## Purpose
-LLM TCK provides deterministic provider emulation for integration tests. Test suites can host a local compatibility server, script exact responses and failures, call it through normal client abstractions, and inspect assertion summaries after execution.
+LLM Test Server provides deterministic provider emulation for integration tests. Test suites can host a local compatibility server, script exact responses and failures, call it through normal client abstractions, and inspect assertion summaries after execution.
## Package Boundaries
-- `ManagedCode.LlmTck` owns provider-neutral runtime state: models, scenarios, match rules, deterministic modality fixtures, auth checks, and assertion events.
-- `ManagedCode.LlmTck.OpenAI` owns OpenAI-compatible DTOs and mapping from runtime results to wire responses.
-- `ManagedCode.LlmTck.AzureOpenAI`, `ManagedCode.LlmTck.Foundry`, `ManagedCode.LlmTck.Anthropic`, `ManagedCode.LlmTck.Gemini`, `ManagedCode.LlmTck.Groq`, `ManagedCode.LlmTck.Mistral`, `ManagedCode.LlmTck.Ollama`, `ManagedCode.LlmTck.Cohere`, `ManagedCode.LlmTck.Bedrock`, `ManagedCode.LlmTck.OpenRouter`, `ManagedCode.LlmTck.DeepSeek`, `ManagedCode.LlmTck.Perplexity`, `ManagedCode.LlmTck.SystemOne`, and `ManagedCode.LlmTck.Cloudflare` own provider compatibility profiles and provider-specific wire contracts as they are implemented.
-- `ManagedCode.LlmTck.Hosting` exposes the runtime through ASP.NET Core endpoints and serves the browser admin panel as Blazor server-side rendered components.
-- `ManagedCode.LlmTck.Client` exposes a control client and `Microsoft.Extensions.AI` clients.
-- `ManagedCode.LlmTck.Aspire` adds a package-owned Aspire resource with `builder.AddLlmTck()`.
-- `samples/ManagedCode.LlmTck.Service` is the runnable HTTP provider emulator.
-- `samples/ManagedCode.LlmTck.AppHost` shows the consumer AppHost shape for the Aspire package.
+- `ManagedCode.LlmTestServer` owns provider-neutral runtime state: models, scenarios, conversation step graphs, match rules, deterministic modality fixtures, auth checks, and assertion events.
+- `ManagedCode.LlmTestServer.OpenAI` owns OpenAI-compatible DTOs and mapping from runtime results to wire responses.
+- `ManagedCode.LlmTestServer.AzureOpenAI`, `ManagedCode.LlmTestServer.Foundry`, `ManagedCode.LlmTestServer.Anthropic`, `ManagedCode.LlmTestServer.Gemini`, `ManagedCode.LlmTestServer.Groq`, `ManagedCode.LlmTestServer.Mistral`, `ManagedCode.LlmTestServer.Ollama`, `ManagedCode.LlmTestServer.Cohere`, `ManagedCode.LlmTestServer.Bedrock`, `ManagedCode.LlmTestServer.OpenRouter`, `ManagedCode.LlmTestServer.DeepSeek`, `ManagedCode.LlmTestServer.Perplexity`, `ManagedCode.LlmTestServer.SystemOne`, and `ManagedCode.LlmTestServer.Cloudflare` own provider compatibility profiles and provider-specific wire contracts as they are implemented.
+- `ManagedCode.LlmTestServer.Hosting` exposes the runtime through ASP.NET Core endpoints and serves the browser admin panel as Blazor server-side rendered components.
+- `ManagedCode.LlmTestServer.Client` exposes a control client and `Microsoft.Extensions.AI` clients.
+- `ManagedCode.LlmTestServer.Aspire` adds a package-owned Aspire resource with `builder.AddLlmTestServer()`.
+- `samples/ManagedCode.LlmTestServer.Service` is the runnable HTTP provider emulator.
+- `samples/ManagedCode.LlmTestServer.AppHost` shows the consumer AppHost shape for the Aspire package.
## Runtime Flow
-1. Tests configure the runtime through `AddLlmTck(...)` at host startup, through `LlmTckClient.ConfigureAsync(config => ...)`, or through `POST /admin-api/configure`.
-2. Provider requests arrive through `/v1/*` endpoints.
+1. Tests configure the runtime through `AddLlmTestServer(...)` at host startup, through `LlmTestServerClient.ConfigureAsync(config => ...)`, or through `POST /admin-api/configure`.
+2. Provider requests arrive through explicit namespaces such as `/openai/v1/*`, `/anthropic/v1/*` and `/gemini/*`.
3. Hosting maps provider requests into provider-neutral runtime requests.
4. The runtime checks bearer-token requirements, configured model IDs, model modality kind, and scenario match rules.
5. The provider adapter maps success or failure to the expected wire shape.
@@ -26,20 +26,65 @@ LLM TCK provides deterministic provider emulation for integration tests. Test su
Control endpoints use the same bearer-token requirement when one is configured, so tests can expose the service without leaving runtime reset or reconfiguration open to unauthenticated callers.
+## Isolated test sessions
+
+Hosting owns a bounded registry of independent core runtimes and request journals. Request-scoped DI selects a
+session using its ID/key headers before provider/control execution; no header selects the default runtime.
+Session credentials are independent of provider credentials. Reset/configure/delete affect only their owning
+session. See [Test sessions](Features/TestSessions.md) for the HTTP/client contract and
+[ADR-0003](ADR/ADR-0003-isolated-test-sessions.md) for bounds, ownership and concurrency decisions.
+
+## Request evidence and fixture clocks
+
+Hosting retains bounded HTTP evidence in the session's existing trace journal. Core `Diagnostics` supplies the
+shared query/export DTOs, and core `Verification` evaluates serializable count/order/tool/conversation/retry
+expectations. Retention loss and incomplete pages prevent successful complete verification. Runtime-owned,
+provider-local seeded metadata controls generated wire IDs/time while real event/trace and monotonic timing
+remain observational. See [Request verification and determinism](Features/RequestVerificationAndDeterminism.md)
+and [ADR-0005](ADR/ADR-0005-request-evidence-and-wire-determinism.md). E4 branch CI is green;
+public delivery remains pending.
+
+The [dashboard analytics](Features/DashboardAnalytics.md) derives token/cache/function observations from one
+atomic bounded journal snapshot. Explicit conversation labels group requests only within the selected session
+and provider namespace. Cache and reasoning are subsets of input/output usage; missing measurements and
+retention loss remain visible rather than becoming zero or complete totals.
+
+## Native output plans
+
+Typed ordered message/function/native output plans reuse the same queue/conversation engine, snapshots and
+capacity limits. Provider adapters own declarations, native wire items, citations and progress events; validation
+occurs before fixture consumption. See [ADR-0006](ADR/ADR-0006-ordered-native-tool-output.md) for the ownership,
+history and qualification contract. Native implementation is in progress; the support inventory remains the
+capability boundary.
+
## Stored response continuation
-The runtime owns bounded provider/model/credential-isolated chat-response snapshots. Provider adapters map
+The runtime owns bounded provider/credential-isolated chat-response snapshots. Provider adapters map
Responses storage/parent fields into this neutral state and reuse its response identity for streaming and normal
output. See [Responses continuation](Features/ResponsesContinuation.md) for limits, reset semantics and regressions.
+## Conversation step graphs
+
+The core conversation slice adds serializable predicates and ordered transitions to existing scenarios. Hosting
+passes the conversation selector and provider namespace into the runtime request scope; state remains owned
+by the selected test session and is partitioned by scenario, provider and credential. A typed client adds the
+selector without changing shared transport headers. Control APIs expose bounded conversation status and
+side-effect-free match explanations. See [Conversation DSL](Features/ConversationDSL.md) for the contract and
+[ADR-0004](ADR/ADR-0004-conversation-step-graphs.md) for identity, reservation, replay and lifecycle decisions.
+This extension is locally qualified through server integrations and an installed-package consumer; public
+delivery remains pending.
+
## Determinism
-Chat scenarios are queued. Each matched request consumes the next response. Streaming responses use explicit chunks. Datasets are named groups of active scenarios so tests can load conversation sets before a run. Embeddings return configured vectors. Image, audio, and video endpoints return fixed fixture content.
+Linear chat scenarios consume queued responses. Conversation graphs select an active step and advance only
+after its fixture commits; identical successful retries can replay the last result. Streaming responses use
+explicit chunks. Datasets are named groups of active scenarios and graphs so tests can load conversation sets
+before a run. Embeddings return configured vectors. Image, audio, and video endpoints return fixed fixture content.
Audio transcription fixtures carry explicitly configured duration or complete audio/text/output token usage
through runtime results and OpenAI-compatible JSON, verbose JSON and final streaming events. Configure it
-with `WithDefaultTranscriptionUsage(LlmTckTranscriptionUsage.ForDuration(seconds))` at startup or
-`UseTranscriptionUsage(LlmTckTranscriptionUsage.ForTokens(audio, text, output))` through the control client.
+with `WithDefaultTranscriptionUsage(LlmTestServerTranscriptionUsage.ForDuration(seconds))` at startup or
+`UseTranscriptionUsage(LlmTestServerTranscriptionUsage.ForTokens(audio, text, output))` through the control client.
The default fixture duration is one second; it is deterministic fixture data, never inferred from input bytes.
Azure OpenAI and Microsoft Foundry expose `/openai/v1/audio/transcriptions` with no required query version;
explicit `v1` and `preview` are accepted and unknown or duplicate versions are rejected. Official SDK tests
@@ -48,7 +93,7 @@ and [OpenAI usage contract](https://developers.openai.com/api/reference/resource
## Client Configuration Surface
-`ManagedCode.LlmTck.Client` owns the universal pre-test configuration API. A test can create one `LlmTckClient`, optionally bind a bearer token, call `ConfigureAsync(config => ...)`, and then create `Microsoft.Extensions.AI` chat, embedding, and image clients from the same control client. Audio and video fixtures are reachable through `LlmTckClient.GenerateAudioAsync(...)` and `LlmTckClient.GenerateVideoAsync(...)` until first-party `Microsoft.Extensions.AI` abstractions exist.
+`ManagedCode.LlmTestServer.Client` owns the universal pre-test configuration API. A test can create one `LlmTestServerClient`, optionally bind a bearer token, call `ConfigureAsync(config => ...)`, and then create `Microsoft.Extensions.AI` chat, embedding, and image clients from the same control client. Audio and video fixtures are reachable through `LlmTestServerClient.GenerateAudioAsync(...)` and `LlmTestServerClient.GenerateVideoAsync(...)` until first-party `Microsoft.Extensions.AI` abstractions exist.
The client builder wraps the provider-neutral configuration builder; it does not create a separate runtime model. This keeps startup configuration, control endpoint configuration, and raw JSON configuration on the same contract.
@@ -56,7 +101,7 @@ The client builder wraps the provider-neutral configuration builder; it does not
OpenAI compatibility is the first implemented provider endpoint surface. The hosted surface also maps Azure OpenAI deployment routes, Microsoft Foundry / Azure AI Inference chat and embedding routes, and the native Anthropic Messages route. The provider matrix is explicit: OpenAI, Azure OpenAI, Microsoft Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere, Amazon Bedrock, OpenRouter, DeepSeek, and Perplexity each have a package-level compatibility profile. Each profile carries a doc-backed `ApiContract` so claimed routes, methods, streaming modes, modalities, and version requirements can be checked against official provider documentation. Provider-specific DTOs and mapping belong in the matching provider package; provider-neutral scenario behavior stays in the core runtime.
-Aspire integration adds the TCK through `builder.AddLlmTck()` without requiring consumer AppHosts to reference a service project, generated `Projects.*` metadata type, project path, Docker, or a container runtime. The package-owned resource starts the packaged .NET LLM TCK service executable and exposes its `http` endpoint. Consumers that explicitly want container hosting can opt in with `builder.AddLlmTckContainer()`, which uses the versioned `ghcr.io/managedcode/llm-tck` image. Consumer resources reference the `LlmTckResource`, wait for it, and read its `http` endpoint through `GetHttpEndpoint()` or Aspire's `GetEndpoint("http")`.
+Aspire integration adds the Test Server through `builder.AddLlmTestServer()` without requiring consumer AppHosts to reference a service project, generated `Projects.*` metadata type, project path, Docker, or a container runtime. The package-owned resource starts the packaged .NET LLM Test Server service executable and exposes its `http` endpoint. Consumers that explicitly want container hosting can opt in with `builder.AddLlmTestServerContainer()`, which uses the versioned `ghcr.io/managedcode/llm-test-server` image. Consumer resources reference the `LlmTestServerResource`, wait for it, and read its `http` endpoint through `GetHttpEndpoint()` or Aspire's `GetEndpoint("http")`.
Native decision fixtures live under the core `Decisions` slice; model profile metadata selects documented SystemOne limits and rounding. OpenAI wire contracts stay in OpenAI, SystemOne Jev/Kev contracts share their native protocol package, and Cloudflare owns Workers AI envelopes and native Clef validation. Hosting delegates the new native routes to the same authenticated/fault-injected runtime and request tracing.
diff --git a/docs/Features/AnthropicNativeWebSearch.md b/docs/Features/AnthropicNativeWebSearch.md
new file mode 100644
index 0000000..d9236f2
--- /dev/null
+++ b/docs/Features/AnthropicNativeWebSearch.md
@@ -0,0 +1,108 @@
+# Anthropic native web search
+
+The basic `web_search_20250305` contract is implemented for `claude-sonnet-5-5` on
+`POST /anthropic/v1/messages`, with `anthropic-version: 2023-06-01` and the configured
+`x-api-key`. The current model and wire subset passed **76 real HTTP/SSE integration cases**
+(`artifacts/delivery/anthropic-official-sdk-strict-wire-regression.log`). Official `Anthropic` 12.58.0
+passed **8 real SDK integration cases with `ResponseValidation: true`**, covering JSON, typed SSE,
+assistant history, all six native error variants and rejection of a programmatic caller without consuming
+the next queued response (`artifacts/delivery/anthropic-official-sdk-strict-focused-batch.log`).
+The isolated Release build completed with zero warnings/errors. The combined final quality gate and
+installed-package consumer remain separate checks; this page does not claim the full E5 scope.
+
+Responses are deterministic fixtures. No search, network retrieval, code execution or external service runs.
+
+## Request contract
+
+```json
+{
+ "model": "claude-sonnet-5-5",
+ "max_tokens": 1024,
+ "tools": [{
+ "type": "web_search_20250305",
+ "name": "web_search",
+ "max_uses": 2,
+ "allowed_domains": ["example.com/articles"],
+ "user_location": {"type": "approximate", "country": "US"}
+ }],
+ "tool_choice": {"type": "auto"},
+ "messages": [{"role": "user", "content": "Find the configured release notes."}]
+}
+```
+
+Supported declaration options are nullable `max_uses`, `allowed_domains`, `blocked_domains` and
+`user_location`. Both non-null domain lists are invalid, including two empty lists. Domains are scheme-less
+DNS names with optional paths; subdomains, path prefixes and path wildcards participate in result matching.
+Approximate location needs at least one non-empty city, region, supported ISO country or IANA timezone.
+Ordinary function declarations/calls remain separate from native tools. For Claude Sonnet 5.5,
+`auto` and `none` are accepted; forced `any` and named `tool` choices return 400 for both ordinary
+and native tools, following the model-specific contract. `disable_parallel_tool_use` remains available.
+
+Local fixture bounds are `max_uses` 0–128, up to 128 domain entries, result entries, citations or content
+blocks per native assistant message, and non-empty IDs up to 128 characters. These are Test Server bounds,
+not a claim about upstream maxima. Invalid raw shapes/options return 400. An incompatible configured
+fixture, missing declaration, exhausted budget or domain mismatch returns 409 before scenario consumption.
+An explicitly configured `max_uses_exceeded` result is the supported way to represent budget exhaustion.
+
+## Ordered response and continuation
+
+A configured response preserves the order of text, ordinary function calls, native calls and native results:
+
+- `server_tool_use`: `id`, `name: "web_search"`, `input: {"query": "..."}`.
+- `web_search_tool_result`: matching `tool_use_id` and `content`, either a results array or typed error.
+- Results: `type: "web_search_result"`, `url`, `title`, `encrypted_content`, optional nullable `page_age`.
+- Text citations: `type: "web_search_result_location"`, `url`, `encrypted_index`, `cited_text`, optional nullable `title`.
+
+Native calls/results carry `caller: {"type":"direct"}`; ordinary function calls also emit their direct caller.
+An omitted or null history caller normalizes to direct invocation. Programmatic/nested callers are rejected.
+Opaque encrypted strings are retained unchanged. Citations reference configured result URLs; no local
+cryptographic verification or decryption is performed. Successful searches can return an empty result list.
+Each native call must have exactly one following matching result in the same assistant message.
+Completed mixed function/native messages can be sent back as assistant history; they remain one ordered
+message and retain native identity, result content and citations. Provider, session and credential scopes
+continue to apply. A conversation ID groups requests and does not grant authorization.
+
+## Errors, usage and streaming
+
+A native tool error is still an HTTP 200 Messages response. Its result content is
+`{"type":"web_search_tool_result_error","error_code":"unavailable"}`.
+The supported codes are `invalid_tool_input`, `unavailable`, `max_uses_exceeded`, `too_many_requests`,
+`query_too_long` and `request_too_large`. These differ from top-level HTTP/provider failures.
+
+`usage.server_tool_use.web_search_requests` counts the configured completed call/result pairs, excluding
+`max_uses_exceeded` pairs that did not execute a search. Result count does not multiply call count.
+The required `web_fetch_requests` field is zero because this subset performs no web-fetch calls.
+This deterministic accounting does not claim upstream billing parity and adds no code-execution counter.
+Native calls remain separate from ordinary function-call analytics. Token usage is normalized fixture
+accounting: opaque encrypted result content, encrypted citation indexes and result/citation metadata are
+retained for inspection without being tokenized as retrieved plaintext. The server cannot recover the
+underlying plaintext from these opaque values, so it does not claim upstream retrieved-content input
+usage or billing parity.
+
+With `stream: true`, standard Anthropic SSE emits `message_start`, indexed block starts/deltas/stops,
+`message_delta` and `message_stop`. Server calls begin with empty input followed by `input_json_delta`;
+native result content arrives whole in its block start. Text uses `text_delta`, citations use
+`citations_delta`, and final usage is cumulative. JSON and the reconstructed stream preserve the same
+ordered content. There is no synthetic `[DONE]` marker.
+
+Typed native declarations, output items and history are inspectable through bounded request diagnostics,
+query/export and replay. Retention limits and truncation remain explicit. Options contribute to request
+identity and cache behavior; wire determinism does not replace real trace observation timestamps.
+
+## Deferred boundaries
+
+Pending calls, result-only continuation, `pause_turn`, programmatic/nested invocation, newer web-search
+versions, web fetch, code execution and native file-search claims are outside this subset.
+Declaration `allowed_callers`, `cache_control`, `defer_loading`, `strict` and other unsupported options are
+rejected explicitly. Existing system/message cache controls remain available. Official SDK tests use `Anthropic.Models.Messages.Model.ClaudeSonnet5_5` directly, including SDK
+streaming unions and assistant-history types, with response schema validation enabled.
+
+Sources: [official web-search guide](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-search-tool),
+[server-tool mechanics and domains](https://platform.claude.com/docs/en/agents-and-tools/tool-use/server-tools),
+[streaming](https://platform.claude.com/docs/en/build-with-claude/streaming),
+[versioned declaration](https://github.com/anthropics/anthropic-sdk-python/blob/main/src/anthropic/types/web_search_tool_20250305_param.py),
+[result schema](https://github.com/anthropics/anthropic-sdk-python/blob/main/src/anthropic/types/web_search_result_block.py),
+[citation schema](https://github.com/anthropics/anthropic-sdk-python/blob/main/src/anthropic/types/citations_web_search_result_location.py).
+
+Current model references: [Sonnet 5.5 official model contract](https://platform.claude.com/docs/en/models/sonnet-5-5/overview),
+[official SDK pinned model enum](https://github.com/anthropics/anthropic-sdk-csharp/blob/Anthropic-v12.58.0/src/Anthropic/Models/Messages/Model.cs).
diff --git a/docs/Features/ConversationDSL.md b/docs/Features/ConversationDSL.md
new file mode 100644
index 0000000..985676c
--- /dev/null
+++ b/docs/Features/ConversationDSL.md
@@ -0,0 +1,162 @@
+# Typed conversation step graphs
+
+Status: Locally qualified through running-server integrations and an installed-package consumer. This document describes the E3 contract;
+public-package delivery remains pending.
+Related: [architecture](../Architecture.md), [ADR-0004](../ADR/ADR-0004-conversation-step-graphs.md),
+[sessions](TestSessions.md), [structured/tool fixtures](ToolAndStructuredFixtures.md),
+[Responses continuation](ResponsesContinuation.md).
+
+## Purpose and ownership
+
+A conversation adds conditions to each step of a deterministic chat workflow. A step can reply with text,
+structured JSON, one or several tool calls, or a scripted error, then transition to ordered alternative steps.
+The graph is serializable configuration owned by the provider-neutral runtime. Provider packages continue to
+normalize their own wire messages and render their own responses. Existing linear scenario queues remain available.
+
+```mermaid
+flowchart LR
+ Request[Provider HTTP request] --> Normalize[Provider adapter]
+ Normalize --> Identity[Session and conversation identity]
+ Identity --> Match[Active step predicates]
+ Match --> Reserve[Reserve bounded state]
+ Reserve --> Result[Validate and execute fixture]
+ Result --> Commit[Commit transition and diagnostics]
+ Result --> Rollback[Rollback cancelled or rejected work]
+```
+
+## Configuration and client flow
+
+Configure through the core builder's `AddConversation`, a dataset's `AddConversation`, or the control client's
+`UseConversation`. Every step needs exactly one response and either `Then(...)` or `Complete()`. The first
+declared step is the start unless `StartAt(...)` selects another. The default model is `gpt-4.1-mini`.
+
+```csharp
+await server.ConfigureAsync(config => config
+ .UseGpt41Mini()
+ .UseConversation("approval", graph => graph
+ .Step("ask", step => step
+ .WhenLatestUserEquals("Start").WhenTurn(1)
+ .Responds("Approve or cancel?").Then("approve", "cancel"))
+ .Step("approve", step => step
+ .WhenLatestUserEquals("Approve").WhenTurn(2)
+ .Responds("Approved").Complete())
+ .Step("cancel", step => step
+ .WhenLatestUserEquals("Cancel").WhenTurn(2)
+ .Responds("Cancelled").Complete())));
+
+using var conversation = server.ForConversation("approval-test");
+using var chat = conversation.Control.CreateChatClient();
+// Send Start, then the returned assistant message and Approve as full chat history.
+var states = await conversation.Control.GetConversationsAsync();
+```
+
+`ForConversation` exposes `Id`, `HttpClient` and `Control`. Supply its `HttpClient` to official provider SDKs
+with the server's allocated provider endpoint and provider credentials. The wrapper adds the conversation
+header per request and keeps the parent transport usable after disposal. Disposing this wrapper does not
+delete server state; reset/configure or disposal of the owning test session clears it.
+
+## Rules and predicates
+
+1. Identity is partitioned by owning test session, scenario identity, provider namespace, conversation ID and
+ provider credential hash. The optional `X-Llm-Test-Server-Conversation` header defaults to `default`;
+ an explicit value must be nonblank, at most 128 characters, and appear once. It selects state and is not
+ an authorization credential. Session and provider authentication still apply.
+2. Scenarios retain their configured precedence. A graph starts only when its start-step predicates match;
+ once it has state for this identity, its active transition owns subsequent matching scenario requests.
+ An active-step mismatch does not consume a response or fall through to a later scenario.
+3. All predicates on a step must pass. `Then("first", "second")` selects the first matching target in that
+ order. Step identifiers are case-sensitive. Text equality and contains predicates use ordinal matching.
+4. `WhenLatestRole`, `WhenLatestTextContains`, `WhenLatestUserContains` and `WhenLatestUserEquals` inspect the
+ final normalized message. They do not search historical user text. `WhenTurn` uses the logical turn index.
+5. Logical turn is one plus the number of consecutive assistant-message groups in normalized history,
+ ignoring system/developer messages. Parallel assistant function-call items form one group. HTTP attempts
+ do not add turns. Clients supply full history or use supported stored Responses continuation.
+6. `WhenToolResult(name, callId)` requires a final tool-result message and resolves its originating call ID
+ in history. `WithToolArgumentsJson` compares that call's complete arguments by JSON structural equality.
+ The call ID argument is optional; the originating tool name remains checked.
+7. `WhenLatestJson(path, expectedJson)` and `WhenLatestJsonValue(path, value)` compare fields of the latest
+ content by JSON structural equality. Paths support `$`, JSON Pointer including `~0`/`~1`, and the subset
+ `$.property.items[0]`. Paths are limited to 256 characters. Wildcards, filters and recursive selectors are
+ unsupported. Missing fields or malformed incoming JSON fail the predicate.
+8. `Responds`, `RespondsJson`, `CallsTool`, `CallsTools`, `Fails` and `DelaysBy` reuse the existing fixture
+ contracts. Tool choice, structured-output and streaming constraints are validated before advancement.
+
+## Replay, errors and lifecycle
+
+`ReplaySuccessfulRequests` defaults to true. Repeating the last successful normalized request returns its
+retained runtime result without advancing the graph. Request ID, streaming mode and `previous_response_id`
+are excluded from the fingerprint; restored history and the remaining normalized request determine identity.
+Provider adapters still apply their wire formatting, so replay is not a byte-for-byte HTTP response guarantee.
+Only the latest successful result is replayable. Fixture constraints remain validated on replay.
+
+With replay disabled, changed or repeated input cannot advance an already successful logical turn. A later
+turn must contain the additional assistant history. A committed scripted error can transition to an explicitly
+configured recovery step at the same logical turn. Only one step can be in flight for an identity; cancellation
+rolls back its reservation. Rejected fixtures and history/state admission failures do not advance the graph.
+Reset/configure/session deletion clear conversation state and supersede pending work through the existing
+runtime generation/retirement contract.
+
+| Boundary | HTTP result/code |
+| --- | --- |
+| Another step is in flight | 409 `conversation_busy` |
+| No active target matches | 409 `conversation_step_mismatch` |
+| Changed/stale input after a successful turn | 409 `conversation_turn_not_advanced` |
+| Terminal graph with Reject policy | 409 `conversation_completed` |
+| Execution limit reached | 409 `conversation_exhausted` |
+| Conversation admission budget exceeded | 409 `conversation_capacity_exceeded` |
+| Incompatible response fixture | 409 `llm_test_server_fixture_mismatch` |
+| Reset/configure/retirement during pending work | 409 `llm_test_server_request_superseded` |
+| Invalid graph or selector header | 400; configuration remains unchanged |
+
+The terminal policy defaults to `Reject`. An identical successful replay takes precedence over terminal
+handling. `RepeatLastResponse` reuses the final successful fixture for later inputs; `Restart` begins again
+at the start step and clears that run's execution/visited-step counters. `WithMaxSteps` limits committed
+executions within a run, including error steps and cycles, rather than HTTP attempts or successful replays.
+
+## Bounds
+
+`UseConversationCapacity(maximumConversations, maximumBytes)` on the control builder, or
+`WithConversationCapacity(...)` on the core builder, sets runtime admission budgets. Defaults are 256
+conversations and 16 MiB retained state. Zero capacity rejects new state. Reservations include bounded identity,
+step metadata and the retained response; growth is checked before a delayed fixture starts. Completed states
+remain until reset/configure/session disposal. There is no timer eviction, persistence or heap-size measurement.
+
+A graph contains 1–256 uniquely identified steps and `MaxSteps` is 1–4096, default 64. Scenario, step and tool
+identifiers are limited to 128 characters. A step must terminate or reference distinct known next steps.
+Graphs cannot also contain the linear response queue. Invalid configuration is rejected atomically.
+
+## Control APIs and diagnostics
+
+Both endpoints use the selected runtime's control authorization and test-session headers.
+
+| API | Contract |
+| --- | --- |
+| `GET /admin-api/conversations` | Status entries with scenario/provider/conversation IDs, busy/terminal state, executed steps, last turn, next and unvisited steps |
+| `POST /admin-api/match/explain` | Body: `LlmTestServerMatchExplanationRequest` containing normalized `request` and `providerNamespace`; response explains candidate predicates and precedence without advancing state |
+
+The conversation header filters the status list or selects the identity to explain. Without it the status API
+lists the selected runtime's states and explanation uses `default`. The client exposes `GetConversationsAsync`
+and `ExplainMatchAsync`. Explanations include logical turn, selected scenario/step, matched candidates,
+shadowed candidates and mismatch field names. They do not execute a provider call, reserve a step, increment
+fault counters or populate caches. Unvisited alternatives are diagnostics, not an assertion that a required
+branch failed. Runtime events and request traces carry conversation ID, step ID, logical turn and replay metadata.
+
+## Verification and completion criteria
+
+Qualification must start the HTTP server and drive real HTTP/provider SDK requests. Required flows are ordered
+branches, latest-message and turn matching, parallel tool calls/results, JSON paths, replay and error recovery,
+all terminal policies, cycles, invalid graphs, count/byte limits, fixture rejection, cancellation and in-flight
+reset/configure/delete. Verify isolation across sessions, providers, credentials and conversation IDs. Read
+explanations/status/events to prove selection and no advancement from diagnostics. Keep linear scenario and
+provider-contract regressions green. No direct runtime tests or source scans establish these behaviors.
+
+```sh
+dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore
+dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
+dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal
+bash scripts/coverage.sh
+```
+
+Completion requires the focused HTTP/SDK cases, full integration suite, at least 90% production line coverage,
+canonical Release build and independent installed-package consumer to pass. Results belong in the delivery
+implementation ledger. The E3 checkpoint passed 722/722 with 91.34% production line coverage; the independent installed-package Aspire/SDK/Chromium consumer passed 1/1. Public package publication remains pending the combined delivery batch.
diff --git a/docs/Features/DashboardAnalytics.md b/docs/Features/DashboardAnalytics.md
new file mode 100644
index 0000000..bafb5c2
--- /dev/null
+++ b/docs/Features/DashboardAnalytics.md
@@ -0,0 +1,70 @@
+# Dashboard analytics
+
+The request inspector has a **Tokens** tab that shows what a request, or an explicitly labeled conversation, is made of and how its tokens are billed. The default scope is the selected request. Conversation scope is available only when the caller supplied `X-Llm-Test-Server-Conversation`; it combines retained requests with that label, session and provider namespace. Models may differ inside that group. An automatically assigned or default conversation identity does not join unrelated requests.
+
+
+
+## What the tab shows
+
+- **Total, input, output and cached input** at the top, with reasoning shown as part of output.
+- **Where the tokens go**: a flow (Sankey) chart. On the left, the input split by origin (system prompt, tool schemas, user, assistant, tool-call arguments, tool results) plus generated output. In the middle, the request total. On the right, the billing categories: cache read, cache write, uncached input, visible response and reasoning. Each node carries its token count and share.
+- **Context mix**: a donut of the input composition with a value-and-share legend.
+- **Prompt cache**: a donut of cache read, cache write and uncached input, plus how many requests read from the cache.
+- **Context growth** (conversation scope with two or more requests): one stacked bar per request, oldest first, so context growth and cache reuse are visible turn by turn. Clicking a bar selects that request.
+- **Function tools**: schema, call-argument and result tokens, then returned calls and in-context results per function name.
+
+Each request row in the inbox also carries a small composition strip with the same colors, so a request dominated by its system prompt or tool results stands out before you open it.
+
+## Traffic insights
+
+The **Insights** button above the request inbox (and **Traffic insights** in the rail) switches the reading pane to charts over every retained request that matches the current filters. Open it directly with `/?view=insights`.
+
+
+
+- **Recent requests**: one column per request, oldest to newest; height is total tokens and color is the outcome. Clicking a column opens that request.
+- **Delivery**: a 10 × 10 dot grid of streaming versus single responses (each dot is 1% of requests).
+- **Providers**, **Outcomes**, **Prompt cache**, **Tokens by model** and **Context mix**: donuts with a value-and-share legend.
+- **Models** and **Operations**: labeled capsule bars.
+- **Latency** and **Conversation depth**: columns for duration bands and messages per request.
+
+Clicking a provider, model, outcome, delivery mode or operation applies the matching inbox filter; clicking it again clears it. Provider and model colors are assigned from the whole journal, so filtering never repaints the entries that remain. Entries past the seventh color slot fold into **Other**.
+
+## Input composition
+
+The runtime records `LlmTestServerTokenUsage.InputComposition` for chat-style requests on every provider surface. It counts each normalized message and tool schema with the same tokenizer that produces the reported input, so the parts add up exactly to `InputTokens`:
+
+| Part | Source |
+| --- | --- |
+| System prompt | `system` and `developer` messages, including provider-level system fields |
+| Tool schemas | function tool definitions: name, description and parameter schema |
+| User | `user` messages |
+| Assistant | assistant or model text from earlier turns |
+| Tool calls | function-call identifiers, names and arguments inside assistant turns |
+| Tool results | tool-result messages and blocks |
+| Other roles | any other normalized role |
+
+The composition is part of the request journal returned by `/admin-api/requests`, so tests can assert it directly. Usage without a reconciling composition, such as embeddings or media prompts, is shown as **Not itemized** rather than guessed.
+
+## Tokens and cache
+
+- Input tokens include cache-read and cache-write tokens.
+- Output tokens include reasoning tokens.
+- Total tokens equal input plus output; cache and reasoning subsets are never added again.
+- Cached input share is summed cache-read tokens divided by summed input tokens.
+- The cache-read request rate counts requests whose cached input is positive, divided by requests reporting usage. It does not claim that every request was eligible for its provider's cache.
+
+Cache-write values come from normalized runtime accounting. A provider may expose only cache-read details on the wire; provider-specific mapping stays in the adapter. For example, Anthropic wire input usage can report uncached tokens separately from cache read and write, while the normalized trace input includes all three.
+
+Conversation totals sum each retained request. Repeated prompt context counts again on each request, so the totals do not estimate unique conversation text, billing cost or external provider activity. Ratios use summed counts rather than averaging per-request percentages.
+
+Requests without usage, such as model discovery, stay in the request count but contribute no invented measurements: figures show an em dash, ratios show `N/A`, and the flow chart shows an empty state.
+
+## Function tools
+
+**Calls returned** counts function calls in provider responses, including a replayed response returned for another request. **Results in context** counts tool-result messages supplied by callers. A later request may contain the same earlier result again, so results can exceed the number of distinct result call IDs. Result IDs are associated with preceding calls in the retained history; when that context is unavailable the dashboard shows an unknown-tool label. Neither calls nor results prove that an external function ran. These metrics cover function-tool contracts, not native hosted tools.
+
+## Retention
+
+Analytics use the same bounded request snapshot as the inspector. Short notices appear above the charts when earlier conversation requests were evicted, requests are still pending, usage is missing, or payloads were shortened; token counts stay complete when only payload previews were shortened. The dashboard adds no analytics endpoint; callers can inspect the underlying journal through the existing [query/export/verification APIs](RequestVerificationAndDeterminism.md).
+
+See [architecture](../Architecture.md), [conversation DSL](ConversationDSL.md) and [delivery plan](LlmTestServerDeliveryPlan.md). Running-server dashboard HTTP tests and browser tests provide the integration evidence.
diff --git a/docs/Features/DecisionModels.md b/docs/Features/DecisionModels.md
index 7132f1d..59a968a 100644
--- a/docs/Features/DecisionModels.md
+++ b/docs/Features/DecisionModels.md
@@ -2,9 +2,9 @@
Official native decision/vision contracts re-audited 2026-10-20; see [vision audit](DecisionVisionAudit.md). Provider DTOs live in their owning SystemOne, Cloudflare and OpenAI packages; deterministic fixtures live in core and routes in Hosting.
-Jev, Kev, Cloudflare Clef/Clef Flash and OpenAI Decisions use explicit decision fixtures. The TCK hosts their native JSON shapes under provider namespaces and does not contact production providers. Declare the provider profile explicitly; model names never select an API implicitly.
+Jev, Kev, Cloudflare Clef/Clef Flash and OpenAI Decisions use explicit decision fixtures. The Test Server hosts their native JSON shapes under provider namespaces and does not contact production providers. Declare the provider profile explicitly; model names never select an API implicitly.
-| Provider | TCK POST route | Production POST endpoint | Model helper | Official contract |
+| Provider | Test Server POST route | Production POST endpoint | Model helper | Official contract |
| --- | --- | --- | --- | --- |
| TypeSafe Jev | `/systemone/v1/systemone` | `https://api.typesafe.ai/v1/systemone` | `AddJevLatest()` | [OpenAPI](https://api.typesafe.ai/openapi.json), [primitives](https://docs.typesafe.ai/primitives/choice) |
| Kev | `/systemone/v1/systemone` | `{kev-server}/v1/systemone` | `AddKevLatest()` | [native request models](https://github.com/jaredpalmer/kev/blob/main/kev/api.py), [server/auth](https://github.com/jaredpalmer/kev/blob/main/kev/serve.py) |
@@ -12,19 +12,19 @@ Jev, Kev, Cloudflare Clef/Clef Flash and OpenAI Decisions use explicit decision
| Cloudflare Clef Flash | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `https://api.cloudflare.com/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `AddClefFlash()` | [Clef Flash API](https://developers.cloudflare.com/workers-ai/models/clef-flash/) |
| OpenAI Decisions | `/openai/v1/decisions` | `https://api.openai.com/v1/decisions` | `AddOpenAiDecisionModel("gpt-6-luna")` | [create API](https://developers.openai.com/api/reference/resources/decisions/methods/create/) |
-Production APIs use `Authorization: Bearer `; Kev checks `KEV_API_KEY` only when configured and otherwise permits unauthenticated calls. For the TCK, `RequireBearerToken` controls the expected test token and protects both provider routes and `/admin-api/*`. Tests do not need production credentials. Resolve the hosted base URL from the Aspire resource (`GetEndpoint("http")` / `CreateHttpClient(...)`), then append the TCK route.
+Production APIs use `Authorization: Bearer `; Kev checks `KEV_API_KEY` only when configured and otherwise permits unauthenticated calls. For the Test Server, `RequireBearerToken` controls the expected test token and protects both provider routes and `/admin-api/*`. Tests do not need production credentials. Resolve the hosted base URL from the Aspire resource (`GetEndpoint("http")` / `CreateHttpClient(...)`), then append the Test Server route.
### SystemOne: Jev and Kev
Jev 1.14's JSON image assets and `box` questions are covered by the
[Jev 1.14 compatibility profile](Jev114.md). Register `jev-1.14.0` or `jev-preview`
-with `AddDecisionModel(..., LlmTckDecisionProvider.TypeSafe)` and opt each image/box
+with `AddDecisionModel(..., LlmTestServerDecisionProvider.TypeSafe)` and opt each image/box
request in through `TypeSafe-Danger-Zone-Images: true`. Structured score legends
and the optional fixture `ResolvedModelId` retain native values and version attribution.
Long-context headers pass through; deterministic scenarios define usage and scripted
context-limit failures. The emulator does not tokenize images or estimate model context.
-Jev requires `model`, string/object/array `state`, and a nonempty question map. Kev accepts any JSON `state`, including numbers, booleans and null; instructions and criterion descriptions also accept arbitrary JSON. Kev defaults an omitted `model` to `kev-latest`; the TCK enables that default only when `AddKevLatest()` explicitly registers the Kev profile. Binary questions use `type: "noul"`; optional `criteria` maps the native `true` and `false` descriptions. Choices use an opaque ID-to-description map. Scores use an ordered criteria array.
+Jev requires `model`, string/object/array `state`, and a nonempty question map. Kev accepts any JSON `state`, including numbers, booleans and null; instructions and criterion descriptions also accept arbitrary JSON. Kev defaults an omitted `model` to `kev-latest`; the Test Server enables that default only when `AddKevLatest()` explicitly registers the Kev profile. Binary questions use `type: "noul"`; optional `criteria` maps the native `true` and `false` descriptions. Choices use an opaque ID-to-description map. Scores use an ordered criteria array.
```json
{
@@ -41,24 +41,24 @@ Jev requires `model`, string/object/array `state`, and a nonempty question map.
Use `model: "jev-latest"` for Jev. Native responses contain keyed `answers`: `noul`, or `choice`/`score` with `confidence` and `probabilities`; score `legend` keys are zero-based numeric strings. `usage` contains `input_tokens` and `output_tokens`. Scores are native ordinal values and can exceed one.
```csharp
-using ManagedCode.LlmTck.Decisions;
+using ManagedCode.LlmTestServer.Decisions;
-options.AddKevLatest().AddDecisionScenario(new LlmTckDecisionScenario
+options.AddKevLatest().AddDecisionScenario(new LlmTestServerDecisionScenario
{
Id = "priority", ModelId = "kev-latest",
Answers = new()
{
- ["urgent"] = new() { Kind = LlmTckDecisionKind.Predicate, Probability = 0.95 },
- ["route"] = new() { Kind = LlmTckDecisionKind.Choice, Choice = "fast", Confidence = 0.9,
+ ["urgent"] = new() { Kind = LlmTestServerDecisionKind.Predicate, Probability = 0.95 },
+ ["route"] = new() { Kind = LlmTestServerDecisionKind.Choice, Choice = "fast", Confidence = 0.9,
Probabilities = new() { ["fast"] = 0.95, ["regular"] = 0.05 } },
- ["severity"] = new() { Kind = LlmTckDecisionKind.Score, Score = 1.75, Confidence = 0.625,
+ ["severity"] = new() { Kind = LlmTestServerDecisionKind.Score, Score = 1.75, Confidence = 0.625,
Probabilities = new() { ["0"] = 0.05, ["1"] = 0.15, ["2"] = 0.8 } },
},
Usage = new() { InputTokens = 100, OutputTokens = 10, TotalTokens = 110 },
});
```
-Kev score legends contain rendered strings, while Jev retains string/object/array criteria. Kev responses include `latency_ms`; `LlmTckDecisionScenario.Metadata` supplies deterministic latency and optional `Truncated`, `StateTokens`, `StateTokensUsed` fields. The route echoes or generates `x-typesafe-request-id`, including on errors. Invalid SystemOne request shapes return HTTP 422 with a native `detail` validation array; runtime/admission faults retain `detail` strings. Kev bearer failures include `WWW-Authenticate: Bearer`. This compatibility surface covers `/v1/systemone`; Kev demo `/permute` and `/separate` routes are outside its scope.
+Kev score legends contain rendered strings, while Jev retains string/object/array criteria. Kev responses include `latency_ms`; `LlmTestServerDecisionScenario.Metadata` supplies deterministic latency and optional `Truncated`, `StateTokens`, `StateTokensUsed` fields. The route echoes or generates `x-typesafe-request-id`, including on errors. Invalid SystemOne request shapes return HTTP 422 with a native `detail` validation array; runtime/admission faults retain `detail` strings. Kev bearer failures include `WWW-Authenticate: Bearer`. This compatibility surface covers `/v1/systemone`; Kev demo `/permute` and `/separate` routes are outside its scope.
### Cloudflare Workers AI: Clef and Clef Flash
@@ -77,12 +77,12 @@ Send the same SystemOne question shape to the account/model route with body `mod
}
```
-Configure `AddClef()` / `AddClefFlash()` and fixtures with the matching short model ID; native surrounding model whitespace is accepted. Runtime/auth failures remain non-success HTTP responses and use `success: false` with native numeric `errors[].code`. Explicit numeric scenario error codes are preserved, including 5004/400 (invalid input), 3007 or 3008/408 (timeout), 3036 or 3040/429 (capacity/rate limit). See [native errors](https://developers.cloudflare.com/workers-ai/platform/errors/). For native error cases, configure the explicit numeric `LlmTckScenarioError.Code`. Unmapped TCK-only errors such as fixture mismatch use the HTTP status as a synthetic code; that fallback is not a claimed Cloudflare native error code.
+Configure `AddClef()` / `AddClefFlash()` and fixtures with the matching short model ID; native surrounding model whitespace is accepted. Runtime/auth failures remain non-success HTTP responses and use `success: false` with native numeric `errors[].code`. Explicit numeric scenario error codes are preserved, including 5004/400 (invalid input), 3007 or 3008/408 (timeout), 3036 or 3040/429 (capacity/rate limit). See [native errors](https://developers.cloudflare.com/workers-ai/platform/errors/). For native error cases, configure the explicit numeric `LlmTestServerScenarioError.Code`. Unmapped Test Server-only errors such as fixture mismatch use the HTTP status as a synthetic code; that fallback is not a claimed Cloudflare native error code.
-Optional `images` is an array of inline data URLs or `{ "content_type": "image/png", "base64": "..." }` objects. PNG/JPEG/WebP are supported; remote URLs are rejected. Limits: four images, 4 MiB decoded file bytes and 16 megapixels per image, 8 MiB combined decoded bytes, and 13 MiB for the complete request body. Image dimensions and file type are read as metadata; compressed pixel streams are not decoded, so full raster validity is outside this deterministic mock validation. The TCK retains supplied images in the matched input and trace. See [input schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-input.json), [output schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-output.json).
+Optional `images` is an array of inline data URLs or `{ "content_type": "image/png", "base64": "..." }` objects. PNG/JPEG/WebP are supported; remote URLs are rejected. Limits: four images, 4 MiB decoded file bytes and 16 megapixels per image, 8 MiB combined decoded bytes, and 13 MiB for the complete request body. Image dimensions and file type are read as metadata; compressed pixel streams are not decoded, so full raster validity is outside this deterministic mock validation. The Test Server retains supplied images in the matched input and trace. See [input schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-input.json), [output schema](https://developers.cloudflare.com/workers-ai/models/clef/schema-output.json).
The typed client is available through
-`new LlmTckClient(httpClient, bearerToken).CreateCloudflareDecisionClient(accountId)`.
+`new LlmTestServerClient(httpClient, bearerToken).CreateCloudflareDecisionClient(accountId)`.
Pass `CloudflareDecisionRequest` with either `CloudflareDecisionImage.DataUrl` or
`Embedded = new CloudflareBase64Image { ContentType = ..., Base64 = ... }`.
`EvaluateAsync` selects the native route from the explicit `clef`/`clef-flash` model,
@@ -112,20 +112,20 @@ OpenAI uses `input` and an ordered question array. Predicate questions return on
OpenAI fixture question IDs use `OpenAiDecisionFixtureIds.ForQuestionIndex(index)` for the zero-based position, regardless of optional native names. Choice fixture IDs use `ForChoiceValue(string/bool)` canonical JSON literals so string `"true"` differs from boolean `true`. Responses preserve names (including `null`), duplicate names and answer order.
```csharp
-using ManagedCode.LlmTck.Decisions;
-using ManagedCode.LlmTck.OpenAI;
+using ManagedCode.LlmTestServer.Decisions;
+using ManagedCode.LlmTestServer.OpenAI;
var fast = OpenAiDecisionFixtureIds.ForChoiceValue("fast");
var defer = OpenAiDecisionFixtureIds.ForChoiceValue(false);
-options.AddOpenAiDecisionModel("gpt-6-luna").AddDecisionScenario(new LlmTckDecisionScenario
+options.AddOpenAiDecisionModel("gpt-6-luna").AddDecisionScenario(new LlmTestServerDecisionScenario
{
Id = "priority-openai", ModelId = "gpt-6-luna",
Answers = new()
{
[OpenAiDecisionFixtureIds.ForQuestionIndex(0)] = new() { Probability = 0.95 },
- [OpenAiDecisionFixtureIds.ForQuestionIndex(1)] = new() { Kind = LlmTckDecisionKind.Choice, Choice = fast,
+ [OpenAiDecisionFixtureIds.ForQuestionIndex(1)] = new() { Kind = LlmTestServerDecisionKind.Choice, Choice = fast,
Confidence = 0.9, Probabilities = new() { [fast] = 0.9, [defer] = 0.1 } },
- [OpenAiDecisionFixtureIds.ForQuestionIndex(2)] = new() { Kind = LlmTckDecisionKind.Score, Score = 1.75,
+ [OpenAiDecisionFixtureIds.ForQuestionIndex(2)] = new() { Kind = LlmTestServerDecisionKind.Score, Score = 1.75,
Confidence = 0.8, Probabilities = new() { ["0"] = 0.05, ["1"] = 0.15, ["2"] = 0.8 } },
},
Usage = new() { InputTokens = 100, CachedInputTokens = 4, OutputTokens = 0, TotalTokens = 100 },
@@ -143,6 +143,6 @@ options.AddOpenAiDecisionModel("gpt-6-luna").AddDecisionScenario(new LlmTckDecis
| Cloudflare Clef/Flash | 2..255 | 2..10 | 1..64 questions; ASCII letter/digit/underscore/dot/hyphen IDs, max 100 characters; required nonempty instructions; four-decimal probabilities/native scores. |
| OpenAI | 2..255 distinct typed values | Ordered labels; no undocumented count cap | Optional names/descriptions, empty strings and repeated score labels preserved; max 128 embedded images; model/names/instructions/labels/descriptions max 1,048,576 characters; no invented choice-value length cap. |
-`AddDecisionModel(id, LlmTckDecisionProvider...)` supports explicit custom model IDs; the control client mirrors it with `UseDecisionModel` and `UseDecisionScenario`. Fixtures are repeatable snapshots. Optional `ExpectedInput` matches the provider input exactly; SystemOne JSON state and OpenAI message arrays use serialized JSON. Cloudflare requests with supplied images match serialized `{state,images}`; text-only requests retain the state-only input. Question IDs, kinds and requested value domains must fit the fixture. Unknown models, unmatched inputs, mismatched fixtures, authentication, configured rate limits/content filtering and scripted errors produce observable non-success HTTP responses. Normal native choice/score fixtures require confidence and a complete probability domain, near-unit probability mass. SystemOne and Cloudflare choices must have maximal probability; OpenAI preserves any selected value in the supplied domain. Cloudflare confidence must equal the maximum probability within native rounding tolerance. Configure profile-correct explicit values: the Kev/Jev example above has score confidence 0.625; Clef uses the maximum probability 0.8. Values are validated and preserved without normalization or recomputation. Four-decimal distributions may total 0.9999 and native scores are not recomputed from rounded probabilities. For deliberate malformed-response regressions, set `AllowMalformedResponse = true` on the scenario; this explicitly bypasses native response conformance while keeping question-kind/domain mapping safe.
+`AddDecisionModel(id, LlmTestServerDecisionProvider...)` supports explicit custom model IDs; the control client mirrors it with `UseDecisionModel` and `UseDecisionScenario`. Fixtures are repeatable snapshots. Optional `ExpectedInput` matches the provider input exactly; SystemOne JSON state and OpenAI message arrays use serialized JSON. Cloudflare requests with supplied images match serialized `{state,images}`; text-only requests retain the state-only input. Question IDs, kinds and requested value domains must fit the fixture. Unknown models, unmatched inputs, mismatched fixtures, authentication, configured rate limits/content filtering and scripted errors produce observable non-success HTTP responses. Normal native choice/score fixtures require confidence and a complete probability domain, near-unit probability mass. SystemOne and Cloudflare choices must have maximal probability; OpenAI preserves any selected value in the supplied domain. Cloudflare confidence must equal the maximum probability within native rounding tolerance. Configure profile-correct explicit values: the Kev/Jev example above has score confidence 0.625; Clef uses the maximum probability 0.8. Values are validated and preserved without normalization or recomputation. Four-decimal distributions may total 0.9999 and native scores are not recomputed from rounded probabilities. For deliberate malformed-response regressions, set `AllowMalformedResponse = true` on the scenario; this explicitly bypasses native response conformance while keeping question-kind/domain mapping safe.
-See [complete native contracts and fixture details](../../README.md#native-decision-api-fixtures) and [behavior-test evidence](../Testing/AcceptanceCriteriaTestInventory.md). Provider-specific limits and optional-field rules above are reconciled against the linked primary contracts.
+See [the provider route table](../Reference/ProvidersAndRoutes.md#native-decision-api-fixtures) and [behavior-test evidence](../Testing/AcceptanceCriteriaTestInventory.md). Provider-specific limits and optional-field rules above are reconciled against the linked primary contracts.
diff --git a/docs/Features/DecisionVisionAudit.md b/docs/Features/DecisionVisionAudit.md
index 1b9ea48..ecb878a 100644
--- a/docs/Features/DecisionVisionAudit.md
+++ b/docs/Features/DecisionVisionAudit.md
@@ -25,7 +25,7 @@ reference-keyed PNG/JPEG assets, JSON or multipart, the explicit images header,
sides, 16 MiB per file and a 32 MiB physical body budget. Box needs Jev 1.14 or preview.
Long-context opt-in remains an explicit per-call header.
-This deterministic TCK validates transport/file metadata and preserves scripted answers/usage.
+This deterministic Test Server validates transport/file metadata and preserves scripted answers/usage.
It does not emulate provider inference, tokenization or image re-encoding; processed/expanded
image-memory and context-limit failures use explicit scripted provider errors. Do not infer
post-processing budgets from compressed input sizes. TypeSafe's GET models API is outside
@@ -42,5 +42,5 @@ confidence is retained by both scenario configuration/runtime validation and
`SystemOneNativeJson.Options`, without adding confidence to Noul responses.
Release delivery still requires a successful GitHub workflow and verified NuGet
-availability before any consuming package reference is changed. The TCK never
+availability before any consuming package reference is changed. The Test Server never
contacts production Cloudflare/TypeSafe inference APIs during these tests.
diff --git a/docs/Features/DockerDistribution.md b/docs/Features/DockerDistribution.md
new file mode 100644
index 0000000..f9e8cd7
--- /dev/null
+++ b/docs/Features/DockerDistribution.md
@@ -0,0 +1,125 @@
+# Standalone Docker distribution
+
+Status: Distribution code and verification are being prepared for the complete v1.0.0 release. Public GHCR
+availability must be established by the release workflow; these commands do not assert that a release is already published.
+Canonical image: `ghcr.io/managedcode/llm-test-server`.
+
+The image runs the complete HTTP backend: provider routes, authenticated management API, Blazor dashboard,
+health and liveness. It includes the published service and browser assets; it does not require a .NET SDK or
+NuGet restore on the consuming machine. The release builds Linux amd64 and arm64 images. The process runs
+as the .NET runtime image's non-root app user and listens on container port 8080.
+
+## Run and configure
+
+After the verified v1.0.0 release is public:
+
+```sh
+docker pull ghcr.io/managedcode/llm-test-server:1.0.0
+docker run --rm --name llm-test-server \
+ -p 8080:8080 \
+ -e LlmTestServer__RequiredBearerToken=local-test-key \
+ ghcr.io/managedcode/llm-test-server:1.0.0
+```
+
+Open `http://localhost:8080/` for the dashboard. `GET /health` and `GET /alive` expose readiness/liveness.
+The configured bearer key protects provider and `/admin-api/*` routes. The dashboard page is available at `/`;
+provider URLs remain namespaced, such as `/openai/v1` and `/anthropic/v1`.
+
+Configure deterministic fixtures through the same management API as the .NET client:
+
+```sh
+curl --fail-with-body http://localhost:8080/admin-api/configure \
+ -H 'Authorization: Bearer local-test-key' \
+ -H 'Content-Type: application/json' \
+ --data '{
+ "requiredBearerToken": "local-test-key",
+ "models": [{"id": "gpt-4.1-mini", "kind": "chat"}],
+ "chatScenarios": [{
+ "id": "greeting",
+ "modelId": "gpt-4.1-mini",
+ "responses": [{"content": "Hello from LLM Test Server", "streamChunks": ["Hello from ", "LLM Test Server"]}]
+ }]
+ }'
+
+curl --fail-with-body http://localhost:8080/openai/v1/chat/completions \
+ -H 'Authorization: Bearer local-test-key' \
+ -H 'Content-Type: application/json' \
+ --data '{"model":"gpt-4.1-mini","messages":[{"role":"user","content":"Hello"}]}'
+```
+
+Configure replaces the selected runtime configuration. Include the bearer requirement in the replacement when
+retaining authentication. Test sessions provide independent configurations inside one container;
+[the session API](TestSessions.md) and [typed client](RequestVerificationAndDeterminism.md) use the same HTTP
+transport. Runtime state is in memory; container replacement starts from the built-in startup configuration.
+Map a different host port as needed. Prefer a version tag or verified digest for reproducible consumers.
+
+## Build and exercise locally
+
+From the repository root:
+
+```sh
+dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --runtime linux-arm64 --self-contained false \
+ /t:PublishContainer -p:ContainerRuntimeIdentifier=linux-arm64 \
+ -p:ContainerImageTag=local -p:UseAppHost=false
+python3 scripts/verify-container.py --image managedcode/llm-test-server:local
+```
+
+Use `linux-x64` in both RID arguments on an amd64 machine. The .NET SDK builds the image from published
+service output using its built-in `PublishContainer` target. The service project declares the canonical
+repository, ASP.NET 10 base image, port/environment, OCI labels, non-root user and both supported runtime IDs.
+It does not require a separate container-builder toolchain. Docker is used only to load/run/inspect/pull images.
+Published runtime output includes the dashboard assets; source, repository metadata and marketing files are not
+added as a build context. Provider credentials are supplied only at container startup/configuration.
+
+To generate the multi-platform OCI image index locally, omit the single RID arguments:
+
+```sh
+dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --self-contained false /t:PublishContainer \
+ -p:ContainerImageTag=local-multi -p:UseAppHost=false
+```
+
+The project's `RuntimeIdentifiers` and `ContainerRuntimeIdentifiers` both specify `linux-x64;linux-arm64`.
+The SDK publishes each RID and combines them into one OCI index. An optional
+`-p:ContainerArchiveOutputPath=/absolute/repository/artifacts/container-sdk/image.tar.gz` exports an archive
+instead of loading a daemon; `docker load --input ...` can import it. See Microsoft's
+[SDK publish guide](https://learn.microsoft.com/en-us/dotnet/core/containers/sdk-publish) and
+[container configuration reference](https://learn.microsoft.com/en-us/dotnet/core/containers/publish-configuration).
+
+The verifier launches a real container on an allocated loopback host port, waits for health, loads dashboard
+HTML and Blazor assets, tests missing-credential rejection, configures fixtures through HTTP, verifies JSON/SSE,
+unknown-model validation, actual assertion counters and reset. It checks the image uses a non-root account.
+It stops only the container it created and stores sanitized logs/evidence under `artifacts/container-verification`.
+This is API/container verification; it does not establish interactive browser qualification.
+On 2026-10-20 the installed .NET SDK 10.0.401 generated and loaded a combined Linux amd64/arm64 OCI index
+with `PublishContainer`; both architecture variants passed the listed HTTP checks (amd64 through Docker Desktop
+emulation). SDK publish logs are under `artifacts/container-sdk`; runtime evidence is under
+`artifacts/container-verification`. Public pull and registry publication remain pending owner-merged release.
+
+## CI, publication and public access
+
+PR CI builds and runs the image without pushing it. The release workflow is restricted to `main`, follows the
+owner's merge, and uses the canonical package version. Its order is existing quality/package gates → local
+SDK container HTTP acceptance → version-tagged multi-platform SDK publish → anonymous pull and HTTP acceptance → NuGet
+publication and public-consumer verification → delivery marker. Publication does not run from this branch.
+A failed gate keeps delivery incomplete; retry the same version rather than creating an intermediate release.
+
+The release job grants `packages: write`, authenticates with `GITHUB_TOKEN`, and calls `dotnet publish
+/t:PublishContainer -p:ContainerRegistry=ghcr.io` with both configured RIDs. It links the image to its source
+repository with the OCI source label. **Those settings do not make a new GHCR package public.** GitHub documents
+new container packages as private by default. A package administrator must open the managedcode organization's
+`llm-test-server` container package, choose **Package settings → Change visibility → Public**, and confirm the
+change. Organization policies may restrict that permission. After the first push creates the package, change
+visibility and rerun the same release if its anonymous check failed.
+
+The supported visibility setup is documented by GitHub's
+[container registry guide](https://docs.github.com/en/packages/working-with-a-github-packages-registry/working-with-the-container-registry)
+and [package access/visibility guide](https://docs.github.com/en/packages/learn-github-packages/configuring-a-packages-access-control-and-visibility).
+The workflow does not invoke an undocumented visibility mutation API.
+
+The public-access gate runs `verify-container.py --anonymous-pull` with a newly created Docker configuration
+containing no registry credentials. It must pull the published version and pass the same HTTP checks.
+The published manifest must also include Linux amd64 and arm64. A push succeeding under the workflow token is insufficient. Public delivery remains blocked by missing GHCR
+permissions, organization visibility policy, unavailable registry access or failed anonymous acceptance until
+that specific condition is resolved. No public-availability claim should precede this gate.
diff --git a/docs/Features/GeminiBatchEmbeddings.md b/docs/Features/GeminiBatchEmbeddings.md
new file mode 100644
index 0000000..9768ef3
--- /dev/null
+++ b/docs/Features/GeminiBatchEmbeddings.md
@@ -0,0 +1,33 @@
+# Gemini embeddings through the official SDK
+
+`Google.GenAI` 1.26.1 uses `batchEmbedContents` for both its single-input and multiple-input
+`Models.EmbedContentAsync` overloads. The server exposes the distinct documented operation
+`POST /gemini/v1beta/models/{model}:batchEmbedContents`; the existing `embedContent` operation
+remains its own API.
+
+Each request contains 1–128 entries in `requests` (a local fixture bound). Each entry supplies
+`model: "models/"`, a non-empty text-only `content`, and optional
+`outputDimensionality`. The current embedding fixture uses the documented stable
+[`gemini-embedding-2`](https://ai.google.dev/gemini-api/docs/models/gemini-embedding-2) ID.
+The SDK accepts model strings; it has no closed model enum to copy.
+
+Reduced output dimensions are bounded to 128–3072 for this contract. The runtime validates all
+requested dimensions against the configured fixture vector under the same admission lock before
+recording success or evaluating scripted provider faults. A fixture with too few coordinates
+returns 409 instead of silently returning a shorter vector. Successful batches preserve input
+order and project each fixture vector to its requested prefix. The server does not pad vectors
+or perform embedding inference.
+
+Malformed or unsupported request shapes return 400. Model/path mismatches, missing or oversized
+batches, non-text parts and unsupported `taskType`/`title` options are rejected explicitly.
+Authentication, unknown model, configured rate limits, content filters and scripted errors use the
+normal provider/runtime paths. One batch is one runtime operation; it does not partially record
+successful entries before another entry fails.
+
+The REST response contains ordered `embeddings[].values` and `usageMetadata.promptTokenCount`.
+The pinned SDK does not expose this usage field, so SDK tests prove vectors and request behavior;
+normalized REST token accounting is a separate observation, not provider billing parity.
+
+Sources: [batch API](https://ai.google.dev/api/embeddings#method:-models.batchembedcontents),
+[official SDK](https://github.com/googleapis/dotnet-genai),
+[SDK model routing](https://github.com/googleapis/dotnet-genai/blob/c071e7d18f779bf166a66c0a7ff715ab24035273/Google.GenAI/Models.cs#L4635).
diff --git a/docs/Features/GeminiFunctionContinuation.md b/docs/Features/GeminiFunctionContinuation.md
new file mode 100644
index 0000000..e4089ba
--- /dev/null
+++ b/docs/Features/GeminiFunctionContinuation.md
@@ -0,0 +1,29 @@
+# Gemini function-call continuation metadata
+
+The qualified `gemini-3.8-flash` GenerateContent JSON and SSE routes preserve a fixture tool call's
+opaque `ContinuationToken` as the function part's base64 `thoughtSignature`. Forward the original
+signed candidate parts through the official Google SDK when sending function results.
+
+Each current-turn model step requires a signature on its first function call. Parallel siblings
+may omit it. Earlier steps in the same turn must retain their signatures; unsigned history before
+the latest ordinary user turn remains valid. Missing or malformed signatures return HTTP 400
+before scenario consumption. A changed signature for the last response retained in the local
+conversation returns a fixture mismatch (409), allowing an explicit retry with the original parts.
+
+Signatures count toward bounded history and diagnostic retention and participate in cache identity.
+They do not inflate visible text-token usage. The local maximum is 16,384 base64 characters; it is
+an explicit fixture retention policy, not a claimed Google limit.
+
+This contract preserves function-call metadata only. Arbitrary text-part signatures, signature-only
+streaming text parts and general signed multimodal history remain outside this slice. The server
+does not authenticate Google's private cryptographic signatures. Exact local comparison covers
+the last retained response; older current-turn signatures receive structural validation only.
+
+Sources: [Google thought signatures](https://ai.google.dev/gemini-api/docs/generate-content/thought-signatures),
+[Gemini 3.8 Flash](https://ai.google.dev/gemini-api/docs/models/gemini-3.8-flash),
+[official .NET SDK](https://github.com/googleapis/dotnet-genai).
+
+The official Google.GenAI 1.26.1 running-server suite covers JSON/SSE signed rounds, missing and
+changed metadata with recovery, parallel/sequential calls, prior turns, malformed input and atomic
+retention rejection. All 36 Google SDK integration cases pass. Raw HTTP supplements malformed
+base64 cases; successful continuation and public SDK errors use the original SDK.
diff --git a/docs/Features/Jev114.md b/docs/Features/Jev114.md
index deb723e..dc01c87 100644
--- a/docs/Features/Jev114.md
+++ b/docs/Features/Jev114.md
@@ -19,7 +19,7 @@ References: [API](https://docs.typesafe.ai/api), [images](https://docs.typesafe.
- [x] Support multipart with the JSON request first, one unique part per asset,
PNG/JPEG content validation and bounded physical-body/file reads.
- [x] Adapt the Storied native client to send image assets as multipart; retain
- base64 JSON inputs and expose a typed native client from the TCK client package.
+ base64 JSON inputs and expose a typed native client from the Test Server client package.
- [x] Advertise verified Jev/SystemOne support in README, NuGet tags and GitHub topics.
- [x] Run formatting, Release build, full tests and provider contract/evidence checks for the expanded batch.
- [ ] Review the combined batch, increment one patch version, push once and verify
@@ -34,7 +34,7 @@ The 2026-10-15 combined repair targets one `0.1.15` release.
## Typed client
-`LlmTckClient.CreateSystemOneClient()` uses the TCK host's SystemOne route and
+`LlmTestServerClient.CreateSystemOneClient()` uses the Test Server host's SystemOne route and
inherits its bearer credential. `EvaluateAsync` sends JSON; `EvaluateMultipartAsync`
sends the JSON request first, then `SystemOneImageUpload` values as file parts.
The caller owns the shared `HttpClient`; upload memory is caller-owned and the
diff --git a/docs/Features/LlmTestServerDeliveryPlan.md b/docs/Features/LlmTestServerDeliveryPlan.md
new file mode 100644
index 0000000..34afe52
--- /dev/null
+++ b/docs/Features/LlmTestServerDeliveryPlan.md
@@ -0,0 +1,292 @@
+# ManagedCode.LlmTestServer: план розвитку та доставки
+
+Статус: **погоджено власником; реалізація триває, весь roadmap E0–E13 у scope**.
+Дата плану: 20 жовтня 2026 року.
+Основа: [архітектура](../Architecture.md), [контракти провайдерів](ProviderApiContractCoverage.md),
+[tool fixtures](ToolAndStructuredFixtures.md), [Responses continuation](ResponsesContinuation.md).
+
+## 1. Мета
+
+**LLM Test Server** — **Deterministic LLM API mocking for .NET and Aspire.**
+Продукт має одну ідентичність: GitHub `managedcode/LlmTestServer`, NuGet/namespace сім’ю
+`ManagedCode.LlmTestServer.*`, типи `LlmTestServer*` і image `ghcr.io/managedcode/llm-test-server`.
+План охоплює багатокрокові розмови, well-known built-in tools, розширення provider API, fault simulation,
+record/replay та повну інтеграційну перевірку опублікованих пакетів.
+
+Підтримка доводиться через запущений сервер: HTTP, офіційні SDK, streaming і помилки.
+Unit-тести, fake clients, читання source/docs та reflection guards не є прийнятними перевірками.
+Оцінювання якості live моделей і реальне навчання не входять у deterministic mock runtime.
+
+## 2. Поточні поверхні
+
+19 пакетів: core, Hosting, Client, Aspire та 15 provider packages; 22 проєкти з двома samples і тестовим проєктом.
+Provider packages: OpenAI, AzureOpenAI, Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere,
+Bedrock, OpenRouter, DeepSeek, Perplexity, SystemOne і Cloudflare.
+
+Є linear response queues, scripted errors/delays, function tool loops, structured output, Responses continuation,
+streaming, embeddings/image/audio/video fixtures, cache/reasoning/token accounting, Blazor dashboard, bounded
+request journal, rate-limit/content-filter simulation і package-owned Aspire без Docker. Test sessions локально
+кваліфіковані. E3 conversation graph та E4 request verification/query/export/fixed wire metadata локально
+кваліфіковані; наступні етапи не є завершеними support claims.
+
+E4 fixed-clock/seed режим задає generated wire IDs/time через session-owned provider-local ordinals; reset
+відтворює послідовність, conversation replay зберігає response metadata. Live режим лишається доступним.
+Explicit fixture timestamps/model dictionaries зберігають власні значення; runtime/trace observations та
+monotonic retry timing залишаються реальними. Це не гарантія byte-for-byte однакових довільних HTTP bytes.
+
+## 3. Цільові можливості
+
+| Напрям | Результат | Інтеграційна перевірка |
+| --- | --- | --- |
+| Test sessions | Незалежні config, queues, history, cache, faults, journal | Паралельні клієнти, reset/dispose isolation |
+| Conversations | Typed turns, branches, tool results, terminal policy | Повні HTTP/SDK loops у JSON і streaming |
+| Built-in tools | Typed fixtures, native declarations/results, citations/events | SDK parsing, success/error, mixed tool loops |
+| Reliability | Retry-After, timing, transport і semantic faults | Реальний HTTP/stream failure і результат повтору |
+| Replay | Versioned cassettes, bytes/frames, strict offline | Відтворення без upstream при miss |
+| Provider APIs | Moderation/rerank/count/discovery, lifecycle, media, realtime | Кожен claimed method/parameter/mode через сервер |
+| Developer experience | Typed client, validation/import/export, diagnostics, installed Aspire | Чистий installed consumer, Chromium, SDK |
+| Agent protocols | MCP/A2A/AG-UI та retrieval fixtures | Реальні protocol clients до hosted endpoints |
+
+## 4. Ідентичність і випуск
+
+Public API: `AddLlmTestServer`, `MapLlmTestServer`, `AddLlmTestServerContainer`; configuration key
+`LlmTestServer:RequiredBearerToken` / `LlmTestServer__RequiredBearerToken`; diagnostic prefix
+`llm_test_server_`. Усі package IDs, dependencies, targets, service assets, docs і screenshots використовують
+один бренд і використовують наведені публічні ідентифікатори.
+
+Погоджена версія combined batch — `1.0.0`; canonical version bump виконується один раз, коли весь batch
+готовий. Порядок: branch changes → local quality gate → pack/installed consumer → release preflight →
+owner merge через чинні gates → GitHub release/GHCR/NuGet → чистий consumer з public feed.
+Часткову publication відновлювати для тієї самої версії. Не публікувати окрему версію на кожну зміну.
+Release завершений лише після перевіреної публікації всіх 19 пакетів та container image і реального consumer flow.
+
+## 5. Multi-turn і тестові сесії
+
+Потрібно розширити вже наявну історію та tool loops, а не реалізовувати їх повторно.
+
+1. **Session scope**: окремі configuration, scenario cursors, faults, assertions, cache, response/video/file/job stores. Session identity відокремлена від bearer authorization. Provider/credential isolation усередині history зберігається.
+2. **Typed conversation DSL**: turns з умовами latest role/text, turn index, tool name/call ID/result, exact arguments/JSON path; explicit переходи, branches, terminal state, max steps і exhaustion policy.
+3. **Семантика порядку**: turn index рахується з normalized conversation, retries того самого turn не стають автоматично новим turn; queued HTTP attempts і logical turns — різні поняття.
+4. **Match explanations**: selected scenario/step, mismatch fields, shadowed/ambiguous rules, unused expectations. Пріоритет правил має бути документований і стабільний.
+5. **Assertions**: count/order, tool arguments/results, no unexpected calls, all expected steps consumed, bounded retry attempts, Retry-After compliance, terminal stream marker.
+6. **Без споживання при помилці**: validation/schema/authorization/session mismatch не пересувають сценарій. Cancellation/reset у межах session мають визначений результат для in-flight requests.
+7. **Bounded lifetime**: кількість sessions, state bytes, journal retention та dispose/reset; переповнення повертає явну помилку. Тест однієї session не очищає іншу.
+
+Control endpoints E2: `POST /admin-api/sessions`, `DELETE /admin-api/sessions/{id}` та session-scoped
+configure/reset локально кваліфіковані. `GET /admin-api/requests` доступний із paging/filter. E3 додає
+`GET /admin-api/conversations` і `POST /admin-api/match/explain`; інтеграційна кваліфікація пройшла.
+E4 `POST /admin-api/verify`, розширений request query та `GET /admin-api/requests/export` локально
+кваліфіковані. Наступні control API: fixture import/export/validate. Session headers і client factory описані
+в [ADR-0003](../ADR/ADR-0003-isolated-test-sessions.md), conversation DSL — у [контракті](ConversationDSL.md).
+Control routes залишаються під `/admin-api`, provider routes — у своїх namespaces.
+
+```mermaid
+flowchart LR
+ Test[Тест і typed fixtures] --> Session[Ізольована тестова сесія]
+ SDK[Офіційний provider SDK] --> Adapter[Provider adapter]
+ Adapter --> Session
+ Session --> Match[Conversation matcher]
+ Match --> Fixture[Response або tool fixture]
+ Fixture --> Wire[Provider response або stream]
+ Wire --> SDK
+ Session --> Journal[Bounded journal і assertions]
+ Journal --> Test
+```
+
+## 6. Well-known та provider-native built-in tools
+
+Цей блок додано за уточненням власника. Потрібні два різні рівні з єдиними fixtures/journal, але коректними provider wire contracts.
+
+### 6.1. Готові function-tool fixtures
+
+Реалізовано [typed function-tool catalogue](WellKnownFunctionTools.md) із дванадцятьма presets, input/output/error schemas та scripted success/error fixtures. Focused HTTP qualification: 40/40; combined server suite 852/852, production line coverage 91,79%, Release build 0 warnings/errors; 19 packages packed. Clean installed NuGet/Aspire/official SDK/Chromium consumer пройшов 1/1, включно з typed Calculator tool round. Це частина E5: native built-ins, dashboard discovery та розширена provider qualification залишаються відкритими.
+
+Repo-owned presets: `Calculator`, `CurrentTime`, `Weather`, `WebSearch`, `FetchUrl`, `FileSearch`, `ReadFile`, `WriteFile`, `ListFiles`, `RunCode`, `Shell`, `ApplyPatch`. Це наші зручні test presets, а не універсальний міжпровайдерний стандарт назв function tools.
+
+Кожен має typed argument/result schema, явні success/error fixtures, predictable call IDs, optional delay, expected-call verification та repeat/exhaustion rules. Час береться з fixture clock. Пошук і файли беруться із заданих test data. Tool loop може виконувати тестовий delegate через `Microsoft.Extensions.AI` function invocation; зовнішні побічні ефекти не входять у preset. Calculator не повинен виконувати довільний код через eval.
+
+### 6.2. Нативні інструменти провайдерів
+
+| Provider family | Кандидати до реалізації | Обов’язкові деталі |
+| --- | --- | --- |
+| OpenAI Responses | web search, file search, code interpreter, image generation, computer, shell/local shell, apply patch, tool search, remote MCP | Native tool types та output items, citations/annotations, call/result identity, lifecycle events, tool errors, approval items де застосовно |
+| Anthropic | web search/fetch, code execution, tool search; client tools bash, text editor, computer/browser, memory | Точні versioned tool types, client/server execution distinction, block/event shapes, pause/resume, errors і required headers |
+| Gemini | Google Search/Maps grounding, URL context, File Search, Code Execution | Native tool config, executableCode/codeExecutionResult, grounding/citation metadata, restrictions на combination/model/API |
+| Azure/Foundry/Bedrock та інші | Лише native tool contracts, доступні на конкретній операції й версії | Не успадковувати всі OpenAI/Anthropic built-ins автоматично через схожий wire format |
+
+Первинні джерела: [OpenAI tools](https://developers.openai.com/api/docs/guides/tools), [Anthropic tool reference](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-reference), [client/server tool lifecycle](https://platform.claude.com/docs/en/agents-and-tools/tool-use/how-tool-use-works), [Gemini tools](https://ai.google.dev/gemini-api/docs/tools). Перелік — ціль аудиту контрактів; не кожна модель чи endpoint підтримує кожен інструмент.
+
+Well-known catalogue повинен бути discoverable у C# та dashboard: provider, exact type/version, input/output schema, fixture examples, JSON/stream support, обмеження, evidence tests. Спочатку web search + file search + code execution для трьох головних wire families; далі computer/browser/shell/patch/memory/tool-search/MCP. Усі відповіді scripted; mock не стає реальним браузером, shell executor або пошуковиком.
+
+Негативні fixtures model output вводити явним fault API. Звичайні `CallsTool`/`RespondsJson` продовжують відхиляти некоректні arguments/schema; їхню чинну валідацію не послаблювати заради fault simulation.
+
+## 7. Реєстр API-прогалин
+
+Шляхи нижче показують запропонований hosted namespace. Точні operation IDs, versions, request/response та streaming режими додаються до `ApiContract` тільки разом з реалізацією й evidence. Provider lifecycle моделюється bounded fixtures, а не реальним inference/training.
+
+| Пріоритет / група | Відсутні API або частина контракту | Контракт / межа |
+| --- | --- | --- |
+| P1 moderation | `POST /openai/v1/moderations` | [Official API](https://developers.openai.com/api/reference/resources/moderations/methods/create); configured classifications |
+| P1 rerank | `POST /cohere/v2/rerank`; Voyage rerank окремим provider surface | [Cohere](https://docs.cohere.com/reference/rerank); configured scores та порядок |
+| P1 token counting | Anthropic `/anthropic/v1/messages/count_tokens`, Gemini `:countTokens`, Bedrock CountTokens | [Anthropic](https://platform.claude.com/docs/en/api/messages/count_tokens), [Gemini](https://ai.google.dev/api/tokens); наявний accounting розширити endpoints |
+| P1 model discovery | Anthropic/Gemini list/get, OpenAI get-model, Ollama tags/show | Provider metadata, pagination, unknown-model errors |
+| P1 Ollama generate | `POST /ollama/api/generate` | [Official API](https://docs.ollama.com/api/generate); нині є chat/embed |
+| P1 built-in tools | Native tool declarations/results/events у Responses/Messages/generateContent | Розділ 6; розширення існуючих API |
+| P2 Responses lifecycle | GET/DELETE response, input items, cancel/background, Conversations CRUD/items | Створення/continuation у нас уже є; перевірити SDK lifecycle |
+| P2 Files | upload/list/retrieve/content/delete, metadata/purpose, paging; Anthropic/Gemini variants | Поточний generated-video download не дорівнює загальному Files API |
+| P2 Batches | create/list/retrieve/cancel/results; OpenAI JSONL, Anthropic batches, Gemini batch subset | Partial failures, poll states, output files, per-session limits |
+| P2 Vector stores | CRUD/search/file attach/file batches | Scripted search hits, bounded storage та lifecycle |
+| P2 fine-tuning | jobs create/list/get/cancel/events/checkpoints | Scripted job lifecycle без навчання |
+| P2 native model formats | Bedrock InvokeModel Nova/Llama/Titan variants; OpenResponses profile | Окремі SDK/wire contracts для кожного body format |
+| P2 new provider families | Vertex AI, xAI/Grok, Voyage AI, ElevenLabs, BytePlus Ark, fal.ai; OrcaRouter як candidate | Окремий контракт та SDK evidence для кожного |
+| P2 media completeness | Provider-specific image/audio/video variants, queue/status/content/cancel, voice design | Розширити наявні fixtures, не дублювати реалізоване |
+| P3 realtime | OpenAI Realtime/GPT-Live, Responses WebSocket, Gemini Live/Interactions | Event protocols, session state, cancellations, errors, audio/tool events |
+| P3 agent protocols | MCP initialize/tools/resources/prompts/call, notifications/session/auth; A2A cards/tasks/messages/SSE/cancel; AG-UI streams | Окремі packages/ADR; LLM tool call та MCP server мають окремі контракти |
+| P3 retrieval dependencies | Pinecone/Qdrant/ChromaDB subsets, Tavily search | Fixtures/filter/query/upsert у погодженій матриці |
+
+Додатково: simulated usage/cost budgets з explicit pricing fixtures, imported provider-reported cost і rate-limit headers; це не актуальний billing calculator. SDK contract drift checks, route/OpenAPI catalogue, fixture lint, import/export, CLI або .NET tool для serve/validate/replay — частина developer experience backlog. Existing `ApiContract` можна використати для route catalogue, не заводячи друге джерело правди.
+
+Для API з P2/P3 цей документ фіксує цільові API й proposed subset, а не завершений аудит upstream специфікації кожного методу. Перший крок відповідного етапу — закріпити точні official docs/version/SDK і method-level inventory; unresolved cells залишаються видимими й не потрапляють у support claims.
+
+## 8. Reliability, transport та replay
+
+- Deterministic timing: TTFT, інтервали/затримки кожного chunk, timeout/stall, cancellation; clock/seed ізольовані за session, без незадокументованої випадковості.
+- Transport faults: connection abort, early clean end, malformed JSON/SSE, missing terminal event, invalid envelope/header; окремо від звичайного provider-shaped HTTP error.
+- Semantic faults: invalid tool JSON/schema, unknown tool, duplicate call IDs, refused/empty/reasoning-only output, length stop. Catalogue має support applicability за provider/mode та journal evidence.
+- Retry: scripted 429 + Retry-After → success, 5xx → fallback provider, non-retryable failure; assertions перевіряють фактичні timestamps/attempts. Production timings не підміняти фальшивими успішними результатами тесту.
+- Record/replay: versioned cassette schema для request, provider/version, exact response bytes/headers, timed frames; matcher normalization і collision diagnostics; replay speed та offline strict mode.
+- Recording лише explicit opt-in із дозволеним upstream і redaction secrets/PII перед записом. Default test/replay не має network fallback при miss. CI використовує repo-owned fixtures без live credentials.
+- Одна cassette може містити кілька conversation steps і tool rounds; replay із session isolation, deterministic clock/IDs, unused fixture detection.
+
+## 9. Етапи, залежності та оцінка
+
+Оцінка — **людино-дні повноцінної інженерної роботи**, включно з tests/docs/self-review. Це planning range, не обіцянка календарного строку чи часу роботи агента. Exact upstream breadth, SDK обмеження й release permissions можуть її змінити. Після кожного етапу уточнювати залишок за фактичним diff і verification evidence.
+
+| Етап | Результат | Залежність | Оцінка |
+| --- | --- | --- | --- |
+| E0 | Зафіксувати baseline checks, public API/route manifest, release preflight, scope decisions | Погодження плану | 1–2 |
+| E1 | Єдина ідентичність 19 packages, GitHub/GHCR/docs, verified published consumer | E0 | 3–5 |
+| E2 | Session isolation, bounded stores/lifecycle, typed session client | E1 | 6–10 |
+| E3 | Conversation DSL, branches, matching explanations, tool-round semantics | E2 | 5–8 |
+| E4 | [Request query/export, assertions, retry verification, stable clock/IDs](RequestVerificationAndDeterminism.md) | E2–E3 | 4–7 |
+| E5 | [Well-known presets](WellKnownFunctionTools.md) + основні native search/file/code tools | E3–E4; file-search lifecycle узгодити з E9 | 10–16 |
+| E6 | Timing, transport faults, semantic misbehavior catalogue | E2–E4 | 6–10 |
+| E7 | P1 API: moderation/rerank/count/model discovery/Ollama generate | E2, contract inventory | 6–10 |
+| E8 | Fixture validation/import/export та record/replay | E3–E4, E6 | 7–12 |
+| E9 | Stateful platform: Files/Batches/Responses lifecycle/vector stores/fine-tune fixtures | E2, E7 | 12–20 |
+| E10 | New providers/media/native formats; решта built-in tool families | E5, E7, E9 | 15–25 |
+| E11 | Realtime/WebSocket/Live/Interactions | E2–E6, exact protocol spec | 12–20 |
+| E12 | MCP/A2A/AG-UI/vector DB/search ecosystem | E2–E4, окремі ADR/contracts | 15–25 |
+| E13 | Фінальні recipes/support matrix, packaged quickstart, screenshots, delivery acceptance | Кожен погоджений етап; тут підсумкова інтеграція | 3–5 |
+
+Повний перелічений обсяг: **105–175 людино-днів**, до резерву. Резерв 25% на protocol/SDK/release
+невизначеність: приблизно **130–220 людино-днів**. Погоджено весь E0–E13 roadmap. Етапи є контрольними
+точками одного узгодженого delivery batch; support claims додаються лише після відповідних server checks.
+
+## 10. Acceptance і перевірка
+
+| ID | Потік | Критерій |
+| --- | --- | --- |
+| A1 | Clean consumer | Встановлює нову Aspire NuGet з public feed, стартує packaged service без Docker, SDK виклик і assertion проходять; Blazor assets завантажуються |
+| A2 | Product identity | Кожен із 19 пакетів доступний; metadata/dependencies/targets використовують ManagedCode.LlmTestServer; GitHub/origin/GHCR перевірені |
+| A3 | Public configuration | Приклади використовують лише LlmTestServer configuration keys, API names і diagnostic IDs; installed consumer підтверджує їхню поведінку |
+| A4 | Multi-turn | user → tool → tool result → другий tool → final; text/stream; повтор user prompt і approve/cancel branch дають правильний результат |
+| A5 | Parallel sessions | Два клієнти з однаковими model/prompt/credential мають незалежні cursors/journals; reset/dispose однієї session не змінює іншу |
+| A6 | Failure boundaries | Невірна schema/tool/session/auth не споживає fixture; capacity overflow та in-flight reset/cancellation мають явний результат |
+| A7 | Built-ins | Позитивний/негативний native tool flow, citations/result/error/stream events, змішаний function + built-in loop для кожного claimed contract |
+| A8 | Resilience | 429/Retry-After → success; malformed/aborted/stalled stream; invalid tool args; negative outcome відрізняється від помилки mock configuration |
+| A9 | Replay | Recorded/hand-authored cassette offline відтворює bytes, steps, usage і timing policy; secrets не зберігаються; miss не йде у network |
+| A10 | Stateful API | Paging, cancel, partial failure, foreign session ID, max count/bytes, delete/reset перевірені через реальні SDK там, де існують |
+| A11 | Provider support | Кожен новий method/mode/version має official reference, operation constant, hosting route та виконувану behavior evidence; negative cases теж покриті |
+| A12 | UI/docs | Desktop/tablet/mobile з довгою розмовою та tool payload; оновлені screenshots, видимі session/step/fault metadata, збережена bounded retention |
+| A13 | Reproducibility | У fixed-clock/seed режимі scripted wire повторюється; паралельні sessions не змінюють чужу sequence; diagnostics мають зрозумілу clock policy |
+
+На кожному behavior change: focused regressions; для provider changes — provider contract/evidence tests і повний quality gate; Aspire behavior — AppHost реально запускається з test fixture. Production line coverage не нижче 90%.
+
+Canonical verification commands:
+
+```bash
+dotnet tool restore
+dotnet restore ManagedCode.LlmTestServer.slnx
+dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore
+dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
+dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal
+bash scripts/coverage.sh
+python3 scripts/verify-package.py
+python3 scripts/verify-release.py
+git diff --check
+```
+
+Також pack усі `src/*/*.csproj`, перевірити nupkg contents/dependencies, запустити installed consumer на чистому restore із публічного NuGet feed; container path перевірити окремо. Після останніх code/format changes повторити canonical Release build. Publication complete лише після успішного release workflow, наявності всіх пакетів у intended feed та installed-consumer acceptance.
+
+Validation skills під час реалізації: `mcaf-testing`, `run-tests`/`tunit` для focused regressions → provider/Aspire checks → `format` і canonical build/full tests → `coverlet`/`reportgenerator` coverage → package/release checks → `mcaf-code-review` фінального diff; frontend skills для змінених browser assets. Нові dependencies/boundaries потребують ADR, не створювати їх до вибору реалізації.
+
+## 11. Журнал реалізації
+
+Погоджено весь E0–E13 план. Етапи не скорочують objective до першої хвилі.
+
+| Етап | Стан | Докази / залишок |
+| --- | --- | --- |
+| E0 | Baseline зафіксовано | `ddbf171`, Release build 0 warnings/errors; baseline suite 669/669 |
+| E1 | Product identity локально реалізовано; public delivery pending | 19 package surfaces/22 проєкти; Release build, format, local pack та installed consumer пройшли. GitHub `managedcode/LlmTestServer`, origin і default branch `main` перевірені. Branded IDs/config повністю очищено; 19 nupkg metadata/entries перевірено без старих назв |
+| E2 | Реалізовано й локально кваліфіковано | Незалежні runtime/journals, session ID/key, typed client, bounded admission, atomic configure/reset/dispose та retirement pending work. 655/655 integration tests, coverage 91,17%; installed consumer/Aspire/Chromium 1/1. [Контракт](TestSessions.md), [ADR-0003](../ADR/ADR-0003-isolated-test-sessions.md) |
+| E3 | Реалізовано й локально кваліфіковано | [Conversation DSL](ConversationDSL.md), [ADR-0004](../ADR/ADR-0004-conversation-step-graphs.md); 722/722 integration tests, coverage 91,34%; format/Release build 0 warnings/errors; all 19 packages packed, independent installed Aspire/SDK/Chromium consumer 1/1 |
+| E4 | Реалізовано й локально кваліфіковано | [Request evidence/verification/determinism](RequestVerificationAndDeterminism.md), [ADR-0005](../ADR/ADR-0005-request-evidence-and-wire-determinism.md); full suite 812/812, production line coverage 91,66%; final Release build 0 warnings/errors; 19 packages packed; independent clean installed NuGet/Aspire/official SDK/Chromium consumer 1/1. E4 branch CI [39455691575](https://github.com/managedcode/LlmTestServer/actions/runs/39455691575) успішний для `894d844` |
+| E5 | Частково реалізовано | [12 typed function-tool presets](WellKnownFunctionTools.md), явні success-root/error-envelope schemas, existing queue/graph lifecycle; 40/40 focused HTTP cases, combined suite 852/852, coverage 91,79%, Release build 0 warnings/errors, 19 packages packed (`artifacts/delivery/presets-coverage.log`). Clean installed NuGet/Aspire/official SDK/Chromium consumer 1/1 (`artifacts/delivery/presets-consumer.log`), включно з Calculator tool round; native built-ins, dashboard discovery і provider qualification не завершено |
+| E6–E13 | Не завершено | Увесь погоджений функціональний обсяг активний; support claims не розширюються наперед |
+
+Гілка `codex/llm-test-server`, [PR1](https://github.com/managedcode/LlmTestServer/pull/1).
+E3 CI [39446187097](https://github.com/managedcode/LlmTestServer/actions/runs/39446187097) успішний для
+head `3aae4db`. E4/presets CI [39455691575](https://github.com/managedcode/LlmTestServer/actions/runs/39455691575)
+та website validation [39455691773](https://github.com/managedcode/LlmTestServer/actions/runs/39455691773) успішні для `894d844`.
+Локальні E4 evidence logs: `artifacts/delivery/e4-build-final.log`, `e4-coverage-final.log`, `e4-pack.log` та
+`e4-consumer.log`. Consumer встановив local NuGet artifacts у незалежний clean project/cache і реально
+запустив packaged Aspire service, official SDK та Chromium; це не public-feed publication acceptance.
+Public NuGet/GHCR publication, E5–E13 і GitHub Pages launch залишаються незавершеними.
+
+Інтеграційні перевірки виявили й виправили model-list authorization, trace error metadata та browser dialog
+layout. Docs screenshots і site hero отримано з реального browser run. Sessions доведені для 13 chat provider
+families і native Jev/Kev/Clef/OpenAI decisions: JSON/SSE, cache/history/video/fault/journal isolation, auth,
+count/byte/config boundaries, cancellation та in-flight reset/configure/delete.
+
+## Launch preparation
+
+The release target is v1.0.0, delivered as one complete batch on the current branch. The owner will merge when ready; do not merge or publish intermediate releases. The launch includes a GitHub Pages landing page in the dashboard visual language with shared styles/components, real screenshots and demo videos, a detailed mc-compact guide, the supplied launch content plan, and a public prebuilt Docker image configurable through the management API. Marketing production materials live in ignored marketing/ until the owner authorizes their publication.
+
+Launch content reference: https://claude.ai/artifact/HHRF9Y8dzTbN8TJnaTKxnj
+
+## Request analytics checkpoint
+
+[Dashboard analytics](DashboardAnalytics.md) adds request/conversation token, cache-read/write and function observations with explicit label/session/provider grouping and bounded-evidence warnings. The genuine installed NuGet/Aspire/SDK/Chromium consumer passed 1/1 (`artifacts/delivery/analytics-consumer-final.log`), including cache miss → hit, function-result continuation, repeated context accounting and unlabeled-request isolation. Running-server analytics tests passed 3/3; query/export tests passed 14/14 after replacing a timing window with a gated real HTTP request and startup readiness. Combined suite passed 855/855 with 91.84% production line coverage (12170/13251) and a clean final Release build (`artifacts/delivery/query-readiness-coverage.log`, `query-readiness-final-build.log`). This is local qualification; the additional cache-admission regression batch is still in progress.
+
+## Cache correctness batch
+
+Code-only checkpoint `d990e06` fixes stored-response admission before cache mutation, provider-namespace isolation, and lookup of all retained prefixes before FIFO insertion/eviction. Ten new running-server HTTP regressions passed, together with the full current analytics/cache snapshot: 865/865, line coverage 91.86%, branch coverage 77.11% (`artifacts/delivery/cache-batch-coverage.log`). The final canonical Release build passed with 0 warnings/errors. Later parallel visual/token-composition changes were included only in that final build, not in the preceding coverage snapshot; their behavior qualification remains separate. The commit deliberately excludes the owner's in-progress visual and token-composition changes.
+
+## First native-tool code checkpoint
+
+[OpenAI native web-search fixtures](OpenAiNativeWebSearch.md) and [ADR-0006](../ADR/ADR-0006-ordered-native-tool-output.md) add typed ordered native/function/message output, provider-qualified declarations/options, URL citations, native SSE lifecycle, explicit/stored continuation, existing queue/graph/replay semantics and bounded structured query/export evidence. The initial completed search/ASCII-citation contract is qualified for gpt-4.1-mini; the preview SDK choice is not silently aliased. File search, code interpreter, broader native options/models/actions and the other E5 provider families remain active work.
+
+Native focused tests passed 99/99; existing provider namespace/evidence passed 85/85. The current working-tree snapshot passed 966/966 with 91.94% production line coverage; format and final canonical Release build passed. All 19 packages were packed, the clean installed NuGet/Aspire/SDK/Chromium consumer passed 2/2 (including native JSON/SSE and a complete mixed function round), and a .NET SDK-built linux/arm64 image passed actual native HTTP smoke. Logs: `artifacts/delivery/native-web-*`; container evidence: `artifacts/container-verification/2cd0409b3d183025`. Parallel owner visual/token-composition work is not part of the upcoming code-only checkpoint, whose exact-head qualification is recorded separately. Cache checkpoint `d990e06` CI [39462950086](https://github.com/managedcode/LlmTestServer/actions/runs/39462950086) and website validation [39462950106](https://github.com/managedcode/LlmTestServer/actions/runs/39462950106) passed.
+
+The independent code-only checkout passed 965/965 server integrations after the ordinary-response regression fix, with 91.96% production line coverage, 77.38% branch coverage and 94.38% method coverage. Canonical formatting and Release build passed with 0 warnings/errors. These results exclude the parallel owner analytics/visual work. Evidence: `artifacts/delivery/native-isolated-final-{format,build,coverage}.log`.
+
+The same code-only checkout packed all 19 packages; the fresh installed NuGet/Aspire/official SDK/Chromium consumer passed 2/2. Its .NET SDK-built linux/arm64 image passed actual HTTP native JSON/SSE and terminal-evidence acceptance. Evidence: `artifacts/delivery/native-isolated-{pack,consumer,container-publish,container-smoke}.log`; container evidence `artifacts/native-code-validation/artifacts/container-verification/220fcd85c2a76ed5`. No public package/image publication is claimed.
+
+## Native file-search and code checkpoint
+
+The bounded [OpenAI file-search/code fixture contract](OpenAiNativeFileCode.md) adds completed native calls, ordered file/container citations, include projections, code deltas, explicit/automatic container references and file filter/result admission. It uses the same queue/graph, history, cache, replay and evidence paths. File search is independently qualified for gpt-4o-mini and code interpreter for gpt-4.1; no retrieval or code execution occurs.
+
+Focused running-server HTTP/SDK tests passed 191/191, including 24 exact-numeric regressions and 17 normalization cases. Existing web-search regressions passed 105/105. Exact numeric comparison corrects a demonstrated HTTP false match between 1e-29 and 2e-29; ID-shape and ordinary-group handling prevent normalization errors without weakening native history bounds. The code-only final qualification is recorded below. Other E5 families and E6–E13 remain unfinished.
+
+### File/code code-only qualification
+
+- Focused file/code HTTP/official SDK: 191/191, including 24 exact-number and 17 normalization cases.
+- Existing web-search regression: 105/105.
+- Full isolated server suite: 1158/1158; production line coverage 92.21%, branch coverage 78.21%, method coverage 94.55%.
+- Canonical format verification and final Release build passed with 0 warnings/errors.
+- All 19 packages packed. A .NET SDK `PublishContainer` linux/arm64 image passed actual web/file/code JSON/SSE, includes, citations, code deltas, management/auth/reset and terminal-evidence smoke.
+
+Evidence: `artifacts/delivery/native-file-code-*`; container record: `artifacts/native-code-validation/artifacts/container-verification/bb0d14644caef9d4`. This checkout excludes the concurrent owner analytics/visual changes. Public package/image publication, owner merge and remaining E5–E13 work are not asserted by these local results.
+
+The clean installed NuGet/Aspire/official SDK/Chromium consumer passed 3/3 from an isolated package cache, including independent file/code JSON/SSE and stored continuation. Evidence: `artifacts/delivery/native-file-code-consumer.log`.
diff --git a/docs/Features/LlmTckScenarioRuntime.md b/docs/Features/LlmTestServerScenarioRuntime.md
similarity index 100%
rename from docs/Features/LlmTckScenarioRuntime.md
rename to docs/Features/LlmTestServerScenarioRuntime.md
diff --git a/docs/Features/NativeBuiltInToolContractInventory.md b/docs/Features/NativeBuiltInToolContractInventory.md
new file mode 100644
index 0000000..dc49823
--- /dev/null
+++ b/docs/Features/NativeBuiltInToolContractInventory.md
@@ -0,0 +1,151 @@
+# Native built-in tool contract inventory
+
+Status: **Bounded OpenAI completed web/file/code contracts locally qualified: file/code 191/191, web regressions 105/105, full server suite 1158/1158; remaining contracts proposed.**
+Audit date: **2026-10-20**.
+Scope: first E5 native search, file retrieval and code execution contracts for OpenAI Responses,
+Anthropic Messages and Gemini generateContent. The bounded OpenAI completed-search subset is described in [its feature contract](OpenAiNativeWebSearch.md).
+The additional [bounded file/code contract](OpenAiNativeFileCode.md) is implemented and locally qualified; public delivery remains pending.
+Unresolved cells and other providers below remain prerequisites/proposed contracts, not support claims.
+Related: [delivery plan](LlmTestServerDeliveryPlan.md), [conversation DSL](ConversationDSL.md),
+[request verification](RequestVerificationAndDeterminism.md), [existing function-tool fixtures](ToolAndStructuredFixtures.md).
+
+## Implementation boundaries
+
+Provider packages must own declarations, validation, native output items/blocks, citations and streaming events.
+Core may own typed deterministic fixture data and ordered native tool results within conversation steps.
+A native hosted tool is not equivalent to a user-defined function. Responses remain scripted: this work does
+not execute searches, programs or external side effects. Every claimed option requires positive/negative
+running-server HTTP and SDK evidence. Unknown or unresolved cells remain outside support claims.
+
+```mermaid
+flowchart LR
+ Request[Native tool declaration] --> Validate[Provider contract validation]
+ Validate --> Fixture[Typed deterministic tool fixture]
+ Fixture --> Items[Provider call and result items]
+ Items --> Citation[Text and native citations]
+ Items --> Stream[Provider stream lifecycle]
+ Citation --> SDK[Actual HTTP and SDK consumers]
+ Stream --> SDK
+```
+
+## OpenAI Responses
+
+Endpoint: upstream `POST /v1/responses`; hosted namespace `/openai/v1/responses`. Standard Bearer authentication.
+Request-level `tools`, `tool_choice`, `include` and `stream` interact with each native tool.
+
+| Contract | Proposed request support | Native result and citation contract |
+| --- | --- | --- |
+| `web_search` | `search_context_size`: low/medium/high; approximate `user_location`; domain filters; `external_web_access`; `return_token_budget`: default/unlimited | `web_search_call` with ID/status/action; search/open_page/find_in_page actions; output-text `url_citation` with URL/title/start/end; optional action sources via `include` |
+| `file_search` | Required `vector_store_ids`; `max_num_results` 1–50; attribute filters; ranking options | `file_search_call` and queries; optional included results; `file_citation` containing file ID, filename and index |
+| `code_interpreter` | Required container ID or auto container object; optional auto file IDs/memory tier | Code-interpreter call ID/container/code/outputs; generated artifacts cited as `container_file_citation` |
+
+Web return-token budget applies to GPT-5+ reasoning web search; location is inapplicable to deep research.
+Preview tool variants have different option applicability. Native prefixes and citation offsets must be preserved.
+References: [web tool](https://developers.openai.com/api/docs/guides/tools-web-search),
+[file tool](https://developers.openai.com/api/docs/guides/tools-file-search),
+[request schema](https://developers.openai.com/api/reference/resources/responses/methods/create),
+[code tool](https://developers.openai.com/api/docs/guides/tools-code-interpreter).
+
+Streaming adds output-item lifecycle and `response.web_search_call.{in_progress,searching,completed}`,
+`response.file_search_call.{in_progress,searching,completed}`,
+`response.code_interpreter_call.{in_progress,interpreting,completed}` and
+`response.code_interpreter_call_code.{delta,done}`. Each carries the relevant item/output index and sequence;
+text/citations and final response completion must remain consistent with ordinary JSON output.
+Reference: [streaming events](https://developers.openai.com/api/reference/resources/responses/streaming-events).
+
+| Unresolved prerequisite | Required resolution before support claim |
+| --- | --- |
+| Tool-specific errors | Completed results are the implemented subset; failed/incomplete result/error relationships remain pending |
+| File-search result spelling | Resolved as `results`; no alternate field is emitted. Bounded implementation is locally qualified |
+| Expanded ranking options | Bounded ranker/threshold and comparison/compound filters implemented; hybrid weights remain unsupported pending separate qualification |
+| Model applicability | Current independent pairings: web/gpt-4.1-mini, file/gpt-4o-mini, code/gpt-4.1; broader combinations remain pending |
+| Containers/artifacts | Pin memory tiers, file download contracts, container reuse and bounded fixture ownership; coordinate with E9 lifecycle |
+| SDK | Completed subset qualified through official .NET SDK JSON/SSE and a fresh installed-package consumer; broader native contracts still need independent qualification |
+
+## Anthropic Messages
+
+Endpoint: upstream `POST /v1/messages`; hosted namespace `/anthropic/v1/messages`. Standard `x-api-key` and
+`anthropic-version` apply. Request includes model, max_tokens, messages, tools and optional stream.
+
+### Web search
+
+Types: `web_search_20250305`, `web_search_20260209`, `web_search_20260318`; fixed name `web_search`.
+Options include max_uses, mutually exclusive domain allow/block lists, approximate location and allowed_callers.
+The newest version adds response_inclusion; dynamic filtering starts with the 20260209 contract and depends on
+model/code-execution capability. Results contain server_tool_use and web_search_tool_result blocks;
+web_search_result_location citations identify URL/title and encrypted citation identity. Usage includes search count.
+Tool failures can remain HTTP 200 with typed result errors; empty results are an empty list. Streaming carries
+server-tool starts, input JSON deltas, result blocks and final message lifecycle.
+Reference: [web-search contract](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-search-tool).
+
+### Code execution
+
+Types: `code_execution_20250825`, `code_execution_20260120`, `code_execution_20260521`; fixed name
+`code_execution`. These versions do not require a beta header. The base contract supports Bash/file operations;
+newer versions add programmatic calls/REPL behavior. Native sub-tool calls/results cover bash_code_execution and
+text_editor_code_execution; outputs include stdout/stderr/return_code or typed file-operation results. Container
+identity/expiry and explicit reuse are part of the contract. Streaming sends input_json_delta and whole result
+blocks. Sonnet 4.5 is included in the documented code-execution model list.
+References: [code contract](https://platform.claude.com/docs/en/agents-and-tools/tool-use/code-execution-tool),
+[version directory](https://platform.claude.com/docs/en/agents-and-tools/tool-use/tool-reference).
+
+### File retrieval and citations
+
+An Anthropic Messages native `file_search` declaration was **not confirmed** in the tool directory. Do not invent
+one. Documented retrieval uses a custom tool or supplied search_result content with source/title/text blocks
+and citations.enabled. Output search_result_location citations carry source/index/block ranges. This is an
+independent retrieval/citation capability, not a hosted file-search-tool claim.
+Reference: [search-result contract](https://platform.claude.com/docs/en/build-with-claude/search-results).
+
+| Unresolved prerequisite | Required resolution before support claim |
+| --- | --- |
+| Exact errors | Pin complete version-specific error codes and result unions for web/Bash/file operations |
+| Version/model matrix | Validate newer tool versions, allowed_callers and programmatic capability per model |
+| Nested execution | Pin caller envelopes, response_inclusion full/excluded and their interaction with direct calls |
+| Continuation | Implement documented pause_turn/resumption and mixed client/server parallel-call behavior |
+| Artifacts | Pin generated-file retrieval, container lifecycle and ownership without claiming unimplemented Files APIs |
+| Streaming/SDK | Pin citation deltas, block indexes, tool-error streams and actual SDK parsing; verify complete native/function loops |
+
+## Gemini generateContent
+
+Use the generateContent-specific references below. Generic Gemini tool guides now also describe Interactions;
+its `tools:[{type:...}]` declarations must not be copied into generateContent requests.
+Endpoints: upstream `POST /v1beta/models/{model}:generateContent` and `:streamGenerateContent?alt=sse`;
+hosted paths add `/gemini`. Standard `x-goog-api-key` authentication applies.
+
+| Tool object | Request/output schema |
+| --- | --- |
+| `googleSearch` | Optional timeRangeFilter/searchTypes; candidate grounding metadata with search queries, sources, supports and searchEntryPoint |
+| `fileSearch` | Required fileSearchStoreNames; optional metadataFilter/topK; retrieved grounding chunks/citations |
+| `codeExecution` | Empty declaration; executableCode and codeExecutionResult content parts, matching optional IDs; PYTHON code and explicit execution outcome/output |
+
+There are no date-versioned type IDs in these tool objects. The code outcomes are OUTCOME_OK,
+OUTCOME_FAILED and OUTCOME_DEADLINE_EXCEEDED. Grounding streams must preserve incremental metadata semantics.
+Reference: [generateContent REST schema](https://ai.google.dev/api/generate-content).
+
+Search citations connect text segments to grounding chunks and web URI/title; searchEntryPoint carries search
+suggestions. [GenerateContent search guide](https://ai.google.dev/gemini-api/docs/generate-content/google-search).
+File-search model applicability includes Gemini 2.5 Pro/Flash-Lite and documented Gemini 3 models; do not infer
+Gemini 2.5 Flash support from older examples. Upload/import/store lifecycle is separate from the generation
+fixture. [File-search guide](https://ai.google.dev/gemini-api/docs/generate-content/file-search),
+[code-execution guide](https://ai.google.dev/gemini-api/docs/generate-content/code-execution).
+
+| Unresolved prerequisite | Required resolution before support claim |
+| --- | --- |
+| Model/tool combinations | Pin exact combinations, structured-output interaction and code-capable model list |
+| File-search options | Pin metadata-filter grammar, topK bounds and invalid/foreign store behavior |
+| Citation shapes | Pin the full retrievedContext and support/index schemas, including streamed incremental chunks |
+| Tool errors | Pin search/file error shapes separately from execution outcome parts and top-level provider errors |
+| Streaming | Exercise native results in actual SSE and supported JSON streaming response modes; do not invent named Responses-style events |
+| SDK | Verify installed official SDK native parsing and mixed function/native flow before expanding package capability claims |
+
+## Qualification and completion
+
+For each selected operation/tool/version, check in the precise supported option/result/error subset alongside
+official links and provider operation evidence. Run the server and test ordinary JSON, streaming, every claimed
+parameter boundary, native errors, citations, identity consistency, mixed function/native conversation flows,
+session isolation and fixture-capacity failure. Preserve deterministic wire metadata and real observations.
+
+File/container/store references require explicit fixtures and ownership rules; unimplemented lifecycle APIs
+remain visible E9 dependencies. No unresolved cell becomes a capability claim merely because a permissive DTO
+accepts its JSON. No qualification result is asserted by this document.
diff --git a/docs/Features/OpenAiNativeFileCode.md b/docs/Features/OpenAiNativeFileCode.md
new file mode 100644
index 0000000..6cc4c65
--- /dev/null
+++ b/docs/Features/OpenAiNativeFileCode.md
@@ -0,0 +1,187 @@
+# OpenAI Responses native file-search and code fixtures
+
+Status: implemented bounded contracts. **191 running-server HTTP/official SDK cases passed**, including exact numeric-filter and normalization regressions; the web-search regression suite passed **105/105**. Release build has zero warnings/errors. Full-suite/package/container qualification is recorded below; this is not a full E5 completion or publication claim.
+
+These fixtures serve `POST /openai/v1/responses`. They return configured native output items, citations and SSE events without retrieving files, executing code, fetching image URLs or starting containers. File/container/store IDs are explicit fixture references. They do not imply working resource upload, download, creation or deletion APIs.
+
+## Independent model contracts
+
+| Native declaration | Current fixture model | Primary-source pairing |
+| --- | --- | --- |
+| `web_search` | `gpt-4.1-mini` | [Existing web contract](OpenAiNativeWebSearch.md) |
+| `file_search` | `gpt-4o-mini` | [Official file-search cookbook](https://developers.openai.com/cookbook/examples/file_search_responses) |
+| `code_interpreter` | `gpt-4.1` | [Official tool cookbook](https://developers.openai.com/cookbook/examples/mcp/mcp_tool_guide) |
+
+The pairings are separate. A current request cannot declare multiple native families whose supported model sets have no common member. Raw model checks apply to current declarations and named choices; completed prior tool outputs and include selectors alone do not re-qualify a past tool against the current model. The core independently checks the qualified native surface and selected fixture. Other provider namespaces and Chat Completions reject native declarations/history.
+
+## Configure a file-search fixture
+
+The following uses a control client connected to the running server:
+
+```csharp
+using System.Text.Json;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+
+await control.ConfigureAsync(config => config.UseGpt4OMini()
+ .UseChatScenario("file-search", scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt4OMini)
+ .RespondsWithItems(
+ new LlmTestServerResponseFileSearchItem
+ {
+ Id = "fs_fixture",
+ VectorStoreIds = ["vs_fixture"],
+ Queries = ["Paris fixture facts"],
+ Results = [new()
+ {
+ FileId = "file_source", Filename = "source.txt",
+ Text = "Scripted Paris source", Score = 0.9,
+ Attributes = new()
+ {
+ ["category"] = JsonSerializer.SerializeToElement("fixture"),
+ ["year"] = JsonSerializer.SerializeToElement(2026),
+ },
+ }],
+ },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = "msg_file", Content = "Paris fixture.",
+ Citations = [new LlmTestServerFileCitation
+ { FileId = "file_source", Filename = "source.txt", Index = 5 }],
+ })));
+```
+
+Every fixture store must appear in the request's `vector_store_ids`. The request may declare additional stores. Configured resource-reference lists are distinct. Duplicate declaration IDs are accepted and preserved; matching treats resource references as sets. An empty declaration array is syntactically valid but cannot satisfy a fixture requiring stores. Missing/foreign stores produce a 409 fixture mismatch without consuming the queued response or graph step.
+
+`max_num_results` is an integer from 1 to 50. The configured result count must already fit that limit; the engine does not silently cut the fixture down. A supplied `score_threshold` must be finite and between zero and one; every configured result then needs a score meeting it. Each result must also satisfy the requested attribute filter. `ranker` accepts `auto` and `default-2024-11-15`, and is retained in normalized declarations and request identity; it does not run a ranking algorithm. These request/result fields follow the [Responses schema](https://developers.openai.com/api/reference/resources/responses/methods/create) and [file-search guide](https://developers.openai.com/api/docs/guides/tools-file-search).
+
+## Configure a code-interpreter fixture
+
+```csharp
+await control.ConfigureAsync(config => config.UseGpt41()
+ .UseChatScenario("code", scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41)
+ .RespondsWithItems(
+ new LlmTestServerResponseCodeInterpreterItem
+ {
+ Id = "ci_fixture", ContainerId = "cntr_fixture",
+ InputFileIds = ["file_input"],
+ GeneratedFileIds = ["file_plot"],
+ Code = "print(42)\n", CodeChunks = ["print(", "42)\n"],
+ Outputs = [
+ new LlmTestServerCodeInterpreterLogsOutput { Logs = "42\n" },
+ new LlmTestServerCodeInterpreterImageOutput
+ { Url = "https://example.com/fixture.png" },
+ ],
+ },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = "msg_code", Content = "42 fixture.",
+ Citations = [new LlmTestServerContainerFileCitation
+ {
+ ContainerId = "cntr_fixture", FileId = "file_plot",
+ Filename = "plot.png", StartIndex = 0, EndIndex = 0,
+ }],
+ })));
+```
+
+An explicit request container must equal the configured `ContainerId`. In automatic mode, the distinct requested `file_ids` set must equal the fixture's `InputFileIds`; declaration order/duplicates remain preserved in normalized request data. Auto mode returns the configured container identity. It does not provision a container.
+
+Container-file citations must reference that exact container and one of its configured `InputFileIds` or `GeneratedFileIds`. Generated references are explicit ownership metadata, not a side effect of evaluating `Code`. A mismatch returns 409 before fixture consumption. Nullable `Code` and nullable/empty `Outputs` remain distinct scripted states; configured chunks must concatenate exactly to non-null code. Only logs and explicit HTTP(S) image URLs are implemented. The [code-interpreter guide](https://developers.openai.com/api/docs/guides/tools-code-interpreter) documents the native container/code/output and generated-file citation contracts; lifecycle/download behavior remains outside this slice.
+
+## Official .NET SDK options
+
+Use `OpenAI` 2.14.0 `ResponsesClient` with its endpoint resolved from the running server's `/openai/v1/` surface and its real HTTP transport. For the file fixture above:
+
+```csharp
+using OpenAI.Responses;
+
+var fileOptions = new CreateResponseOptions
+{
+ Model = "gpt-4o-mini",
+ InputItems = { ResponseItem.CreateUserMessageItem("Use the file fixture") },
+ Tools = { ResponseTool.CreateFileSearchTool(
+ ["vs_fixture"], 2,
+ new FileSearchToolRankingOptions
+ { Ranker = FileSearchToolRanker.Auto, ScoreThreshold = 0.5f },
+ BinaryData.FromString("""{"type":"eq","key":"category","value":"fixture"}""")) },
+ ToolChoice = ResponseToolChoice.CreateFileSearchChoice(),
+ IncludedProperties = { IncludedResponseProperty.FileSearchCallResults },
+};
+var fileResponse = (await sdk.CreateResponseAsync(fileOptions)).Value;
+var search = fileResponse.OutputItems.OfType().Single();
+```
+
+For the independently configured code fixture:
+
+```csharp
+var container = new CodeInterpreterToolContainer(
+ CodeInterpreterToolContainerConfiguration.CreateAutomaticContainerConfiguration(["file_input"]));
+// An explicit container uses: new CodeInterpreterToolContainer("cntr_fixture").
+var codeOptions = new CreateResponseOptions
+{
+ Model = "gpt-4.1",
+ InputItems = { ResponseItem.CreateUserMessageItem("Use the code fixture") },
+ Tools = { ResponseTool.CreateCodeInterpreterTool(container) },
+ ToolChoice = ResponseToolChoice.CreateRequiredChoice(),
+ IncludedProperties = { IncludedResponseProperty.CodeInterpreterCallOutputs },
+};
+var codeResponse = (await sdk.CreateResponseAsync(codeOptions)).Value;
+var execution = codeResponse.OutputItems.OfType().Single();
+```
+
+Raw HTTP additionally supports named `{"type":"code_interpreter"}` choice. The installed SDK's typed surface has no corresponding named-code factory; use its required choice for this example. Existing `auto`, `none`, `required`, named native and named function choices are checked against the actual ordered fixture. Native items do not become client function calls.
+
+## Filters and bounded input
+
+The supported filter operators are `eq`, `ne`, `gt`, `gte`, `lt`, `lte`, `in`, `nin`, `and`, `or`. This is an explicit bounded fixture contract:
+
+- `eq`/`ne` compare matching scalar kinds: strings, finite JSON numbers or booleans.
+- Ordering compares strings ordinally or numbers numerically. Boolean ordering is rejected with 400.
+- `in`/`nin` require a nonempty homogeneous string or number array. Boolean/mixed/null arrays are rejected.
+- Missing attributes and mismatched kinds do not match, including `ne` and `nin`.
+- Compound filters evaluate all/any child matches. Root depth is one; maximum depth is eight and the entire tree has at most 128 nodes. Comparison/member arrays and compound child arrays have at most 128 entries.
+- Attribute keys are nonblank and at most 64 characters. Results have at most 16 scalar attributes; attribute string values have at most 512 characters.
+
+Numeric comparisons use normalized decimal digits/exponents rather than rounding both operands to a binary floating-point value. JSON values must still satisfy finite-number admission. The HTTP suite verifies distinct tiny and large numbers, numeric ordering, membership, signed zero and equivalent number representations. A pre-fix HTTP regression demonstrated a false match for `1e-29` versus `2e-29`; the exact comparator fixes it without expanding exponent powers.
+
+Native item/resource IDs are bounded to 128 characters. File queries, results, store and input/generated file references and code outputs/chunks have at most 128 entries; file queries are nonempty. A file-search fixture owns at least one store; request store arrays may be empty. Native assistant groups contain at most 128 ordered items, with distinct effective nonempty output IDs. Citation lists are also bounded to 128. These collection/identity limits belong to our fixture contract, rather than being attributed to arbitrary upstream limits.
+
+`filters` may be omitted/null; an actual filter object must match its comparison/compound shape. `ranking_options` may be omitted or `{}` but not null. Optional ranker/threshold/max-result fields reject explicit null. Code `container` is required: a nonempty ID or `{ "type":"auto", "file_ids":[...] }`; absent `file_ids` and `[]` are valid, while null is not. Unknown tool/filter/result fields are rejected. Hybrid ranking, auto-container memory/network controls and additional native tool options remain pending and return 400 instead of being accepted and ignored.
+
+## Ordered control data and provider output
+
+Control configuration uses `kind` for output items and annotations; the wire API uses provider `type` values:
+
+| Control `kind` | API representation |
+| --- | --- |
+| `file_search` | `file_search_call` with ID/status/queries and optional `results` |
+| `code_interpreter` | `code_interpreter_call` with container ID, nullable code and nullable outputs |
+| Message citation `file` | `file_citation`: file_id, filename, insertion index |
+| Message citation `container_file` | `container_file_citation`: container/file IDs, filename, start/end |
+| Code output `logs` / `image` | `type: logs` with logs / `type: image` with url |
+
+One ordered citation union retains URL, file and container-file annotation order. A file citation references a configured file-search result and its filename when that result supplies one. Citation text is ASCII in this initial subset. File insertion indexes are between zero and text length. Container ranges allow `start == end`, matching documented zero-range examples; URL ranges retain the existing positive-length boundary. Uncited text retains Unicode support.
+
+Results are included by `file_search_call.results`; without it, the optional field is omitted. Code outputs use `code_interpreter_call.outputs`; excluded or unavailable outputs are null, while an included scripted empty output list remains `[]`. Include projection does not remove citations or mutate stored fixture data. File result fields retain their optionality, including absent metadata; the field is `results`, with no alternative spelling.
+
+SSE retains output-item added/done and final response completion. File calls emit in_progress/searching/completed events. Code calls emit in_progress, configured code deltas and code.done when code is non-null, interpreting and completed. Logs/images are completed output data, with no invented logs/image delta events. The existing annotation-added event carries each ordered citation. The final JSON output agrees with nonstreaming output; terminal evidence is recorded only after final completion is written/flushed. See the [official streaming schemas](https://developers.openai.com/api/reference/resources/responses/streaming-events).
+
+## History, evidence and remaining qualification
+
+Explicit prior native output items and `previous_response_id` use the existing history/replay/capacity engine. Past native calls retain their kinds; they are not synthetic user JSON. Provider namespace and credential ownership apply inside the session runtime. A conversation header labels graph/correlation scope and does not create another history authorization boundary. Reset/configure invalidates existing retained history through generation ownership.
+
+Request queries and JSON/NDJSON exports retain typed declarations, results, citations and assistant output groups within the existing diagnostic budgets. Nested data is copied; omitted evidence is marked truncated. Function `ResponseToolCalls` stays separate. Native declaration/filter/resource options remain preserved in fingerprints, provider-scoped prompt-cache identity and normalized usage. Cache reads/writes and reasoning remain subsets of input/output totals.
+
+The local qualification below covers the focused suites, full server/coverage gate, clean installed-package Aspire/SDK consumer and actual container smoke. Public delivery remains pending. Native failed/incomplete results, unqualified model pairings, other providers and resource lifecycle remain in [the contract inventory](NativeBuiltInToolContractInventory.md) and [delivery plan](LlmTestServerDeliveryPlan.md). Related design: [ADR-0006](../ADR/ADR-0006-ordered-native-tool-output.md).
+
+## Code-only qualification
+
+- Focused file/code HTTP/official SDK: 191/191, including 24 exact-number and 17 normalization cases.
+- Existing web-search regression: 105/105.
+- Full isolated server suite: 1158/1158; production line coverage 92.21%, branch coverage 78.21%, method coverage 94.55%.
+- Canonical format verification and final Release build passed with 0 warnings/errors.
+- All 19 packages packed; a fresh installed NuGet/Aspire/official SDK/Chromium consumer passed 3/3, including independent file/code JSON/SSE and stored continuation. A .NET SDK `PublishContainer` linux/arm64 image passed actual web/file/code JSON/SSE, includes, citations, code deltas, management/auth/reset and terminal-evidence smoke.
+
+Evidence: `artifacts/delivery/native-file-code-*`; container record: `artifacts/native-code-validation/artifacts/container-verification/bb0d14644caef9d4`. This checkout excludes the concurrent owner analytics/visual changes. Public package/image publication, owner merge and remaining E5–E13 work are not asserted by these local results.
diff --git a/docs/Features/OpenAiNativeWebSearch.md b/docs/Features/OpenAiNativeWebSearch.md
new file mode 100644
index 0000000..229d6ed
--- /dev/null
+++ b/docs/Features/OpenAiNativeWebSearch.md
@@ -0,0 +1,155 @@
+# OpenAI Responses native web-search fixtures
+
+The first native-tool slice implements a **scripted completed search** for `gpt-4.1-mini` on
+`POST /openai/v1/responses`. Its focused suite passes **99 running-server HTTP and official SDK cases** with a Release build containing
+**zero warnings and zero errors**. Local qualification and the independent code-only checkpoint are recorded below and in the [delivery plan](LlmTestServerDeliveryPlan.md).
+
+The server returns native `web_search_call` items, assistant text, URL citations and native streaming events.
+Search queries, source URLs and answer text come from configuration. No URL is fetched and no search is executed.
+The provider-neutral [function-tool presets](WellKnownFunctionTools.md) remain a separate fixture surface.
+
+## Configure through the control client
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Scenarios;
+
+await control.ConfigureAsync(config => config.UseGpt41Mini()
+ .UseConversation("research", graph => graph
+ .Step("search", step => step.RespondsWithItems(
+ new LlmTestServerResponseWebSearchItem
+ {
+ Id = "ws_fixture",
+ Queries = ["Paris fixture facts"],
+ Sources = [new() { Url = "https://example.com/source" }],
+ },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = "msg_fixture",
+ Content = "Paris fixture.",
+ StreamChunks = ["Paris ", "fixture."],
+ Citations = [new LlmTestServerUrlCitation()
+ {
+ StartIndex = 0,
+ EndIndex = 5,
+ Url = "https://example.com/source",
+ Title = "Fixture source",
+ }],
+ }).Complete())));
+```
+
+`RespondsWithItems(...)` also works on a queued chat scenario. Its item order is the response order;
+`LlmTestServerResponseFunctionCallItem` permits mixed client function calls, native searches and messages.
+A function item in a mixed native plan requires its own explicit `Id`, distinct from its tool-call correlation ID
+and from every other output item ID.
+Existing delays, conversation transitions, replay, reset and capacity settings apply to the same engine.
+An error or legacy response fields cannot be combined with ordered output items in the same fixture.
+
+Fixture configuration validates item identities, HTTP(S) source/citation URLs, query counts, ASCII citation ranges,
+message chunk concatenation and bounded collections. A malformed HTTP configuration returns 400 and leaves the
+previous configuration active. The initial citation contract accepts ASCII output text when citations are present.
+
+## Send through the official .NET SDK
+
+Use the installed `OpenAI` 2.14.0 Responses client with the HTTP endpoint allocated by the host:
+
+```csharp
+using OpenAI.Responses;
+using System.ClientModel;
+using System.ClientModel.Primitives;
+
+using var conversation = control.ForConversation("research-example");
+var sdk = new ResponsesClient(new ApiKeyCredential("test-key"), new ResponsesClientOptions
+{
+ Endpoint = new Uri(conversation.HttpClient.BaseAddress!, "/openai/v1/"),
+ Transport = new HttpClientPipelineTransport(conversation.HttpClient),
+});
+var options = new CreateResponseOptions
+{
+ Model = "gpt-4.1-mini",
+ InputItems = { ResponseItem.CreateUserMessageItem("Search the configured fixture") },
+ Tools = { ResponseTool.CreateWebSearchTool(null, WebSearchToolContextSize.Low, null) },
+ ToolChoice = ResponseToolChoice.CreateRequiredChoice(),
+ IncludedProperties = { IncludedResponseProperty.WebSearchCallActionSources },
+};
+var response = (await sdk.CreateResponseAsync(options)).Value;
+var search = response.OutputItems.OfType().Single();
+```
+
+The installed SDK's `CreateWebSearchChoice()` factory emits the distinct preview tool choice, so this
+non-preview example uses `CreateRequiredChoice()`; named `web_search` selection is exercised through HTTP.
+
+The native call parses as `WebSearchCallResponseItem` with a `WebSearchSearchAction`. Included sources parse as
+`WebSearchActionUriSource`; output-text citations parse as `UriCitationMessageAnnotation`. Native calls do not
+become function calls. `CreateResponseStreamingAsync(options)` emits typed native progress updates, annotation
+updates and a final completed response containing the same ordered items.
+
+## Supported request subset
+
+| Field | Accepted contract |
+| --- | --- |
+| Model and route | `gpt-4.1-mini`, `/openai/v1/responses` |
+| Tool declaration | One active scripted `type: web_search` contract; function tools may accompany it |
+| `search_context_size` | Omitted, `low`, `medium` or `high`; explicit null is invalid |
+| `user_location` | Optional/null approximate-location object; optional city, region, country and timezone fields; nullable fields follow the provider schema |
+| Country/timezone | Known two-letter country code, case insensitive; a supplied timezone must identify a valid IANA timezone |
+| `filters.allowed_domains` | Optional/null list, up to 100 bare DNS hostnames; empty list is unrestricted; URLs, paths, IP addresses and wildcards are invalid |
+| `tool_choice` | `auto`, `none`, `required`, named web search or existing named function choice |
+| `include` | `web_search_call.action.sources`; repeated entries are permitted |
+| Continuation | Explicit prior native output items in an input array, or `previous_response_id` |
+
+Without the sources include, search sources are omitted from the wire response; text citations remain present.
+A configured source or citation outside a declared domain allowlist produces a 409 fixture mismatch. Missing, repeated or
+disabled declarations also produce 409 before the queued response or graph step is consumed. Changing native
+declaration options changes the normalized request and prompt-cache prefix identity.
+
+Stored history retains ordered native outputs as one assistant response. Provider namespace and credential
+ownership apply within the session runtime. A conversation header selects graph/correlation scope; it does not
+create an additional stored-response access boundary. Reset invalidates stored response IDs; `store: false`
+creates no stored parent. Native payloads contribute to existing history and conversation byte budgets.
+
+Public request queries and JSON/NDJSON export expose typed `NativeTools`, `ResponseOutputItems` and retained
+message output items. Function-only `ResponseToolCalls` continue to contain client function calls. Diagnostic
+retention remains bounded and explicitly marks omitted payload evidence.
+
+## Remaining E5 scope
+
+This slice makes no support claim for `web_search_preview`, open/find actions, native tool failures,
+non-ASCII citation-offset semantics, external-web-access/return-token-budget controls,
+resource lifecycle or native tools on other provider namespaces. File search and code interpreter use their
+separate [bounded fixture contract](OpenAiNativeFileCode.md). Remaining contracts are tracked in the
+[native contract inventory](NativeBuiltInToolContractInventory.md) and delivery plan.
+
+## Contract sources and integration evidence
+
+Official references: [web-search guide](https://developers.openai.com/api/docs/guides/tools-web-search),
+[Responses create contract](https://developers.openai.com/api/reference/resources/responses/methods/create),
+[streaming events](https://developers.openai.com/api/reference/resources/responses/streaming-events).
+The web-search guide explicitly lists `gpt-4.1-mini`; the implemented subset is narrower than the full upstream API.
+
+Running-server coverage:
+
+- [JSON, SDK, mixed output and continuation](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchJsonIntegrationTests.cs)
+- [SDK and raw SSE lifecycle](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchStreamIntegrationTests.cs)
+- [Request options, schema boundaries and namespace guards](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchValidationIntegrationTests.cs)
+- [Atomic configuration and native payload budgets](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchConfigurationIntegrationTests.cs)
+- [Cancellation, reset, replay, ownership and domain mismatch](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchLifecycleIntegrationTests.cs)
+- [Native declaration options and real prompt-cache usage](../../tests/ManagedCode.LlmTestServer.Tests/OpenAI/NativeWebSearchCacheIntegrationTests.cs)
+
+## Local qualification
+
+- Native HTTP/official SDK suite: 99/99.
+- Existing provider behavior/contract namespace: 85/85.
+- Full current working-tree integration snapshot: 966/966, production line coverage 91.94%.
+- Canonical format verification and final Release build: passed, 0 warnings/errors.
+- All 19 packages packed; independent clean NuGet/Aspire/SDK/Chromium consumer: 2/2, including the separate native JSON/SSE and mixed-function round.
+- .NET SDK `PublishContainer` image: actual native JSON/source gating/citations/SSE/terminal evidence smoke passed on linux/arm64.
+
+Evidence logs are repository-owned under `artifacts/delivery/native-web-*`; container evidence is in
+`artifacts/container-verification/2cd0409b3d183025`. The full working-tree count includes parallel owner analytics
+work; a code-only checkpoint and its exact-head CI are tracked separately in the delivery plan. No NuGet/GHCR
+release or main merge is asserted by these local results.
+
+The independent code-only checkout passed 965/965 server integrations after the ordinary-response regression fix, with 91.96% production line coverage, 77.38% branch coverage and 94.38% method coverage. Canonical formatting and Release build passed with 0 warnings/errors. These results exclude the parallel owner analytics/visual work. Evidence: `artifacts/delivery/native-isolated-final-{format,build,coverage}.log`.
+
+The same code-only checkout packed all 19 packages; the fresh installed NuGet/Aspire/official SDK/Chromium consumer passed 2/2. Its .NET SDK-built linux/arm64 image passed actual HTTP native JSON/SSE and terminal-evidence acceptance. Evidence: `artifacts/delivery/native-isolated-{pack,consumer,container-publish,container-smoke}.log`; container evidence `artifacts/native-code-validation/artifacts/container-verification/220fcd85c2a76ed5`. No public package/image publication is claimed.
diff --git a/docs/Features/OutputPolicyFixtures.md b/docs/Features/OutputPolicyFixtures.md
new file mode 100644
index 0000000..08a511c
--- /dev/null
+++ b/docs/Features/OutputPolicyFixtures.md
@@ -0,0 +1,207 @@
+# Output policy fixtures
+
+The qualified text output-policy mappings below passed **79/79 focused running-server SDK cases**
+and **1,438/1,438 full integration cases**, with **92.58% production line coverage**. Tests use
+OpenAI 2.14.0, Anthropic 12.58.0 with strict response validation, Google.GenAI 1.26.1 and the
+package's `Microsoft.Extensions.AI` client. Other E6 outcomes and provider families remain open.
+
+## Configure an explicit output outcome
+
+`LlmTestServerScenarioResponse.OutputDisposition` accepts an immutable
+`LlmTestServerOutputDisposition` from `ManagedCode.LlmTestServer.Scenarios`. `Kind` is
+`LlmTestServerOutputDispositionKind.Filtered` or `.Refused`. Optional `Category` and `Explanation`
+carry bounded outcome metadata. A null disposition preserves the ordinary completion behavior.
+
+Scenario and conversation-step builders expose `WithOutputDisposition(...)`, applied after a response:
+
+```csharp
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+
+await control.ConfigureAsync(config => config
+ .UseGpt55()
+ .UseChatScenario("policy-and-recovery", scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt55)
+ .Responds("I cannot provide that response.", "I cannot ", "provide that response.")
+ .WithOutputDisposition(new()
+ {
+ Kind = LlmTestServerOutputDispositionKind.Refused,
+ Category = "general_harms",
+ Explanation = "Explicit deterministic refusal fixture.",
+ })
+ .Responds("Explicit next attempt.")));
+```
+
+Use `.Filtered` instead for a filtering fixture and configure an explicit generated prefix or empty
+content. `Content` and `StreamChunks` supply deterministic fixture output, including refusal text;
+the disposition selects its native representation. The server does not generate a refusal explanation,
+execute a policy service or call an upstream model. Existing configure/reset APIs remain the control surface.
+
+`WithOutputDisposition` requires a preceding response. JSON configuration accepts the same typed shape:
+
+```json
+{
+ "content": "Explicit refusal text.",
+ "streamChunks": ["Explicit ", "refusal text."],
+ "outputDisposition": {
+ "kind": "Refused",
+ "category": "general_harms",
+ "explanation": "Explicit fixture metadata."
+ }
+}
+```
+
+This is a response entry inside the existing configuration, not a complete configuration document.
+
+## Bounds and admission
+
+- `Kind` must be one of the two named values; the default/unknown enum value is invalid.
+- `Category` is optional and limited to 256 C# string characters; `Explanation` is optional and limited
+ to 4,096. These are local fixture bounds, not advertised upstream limits.
+- Explicit chunks must concatenate exactly to `Content`. Empty output is supported.
+- A policy response cannot also contain a scripted `Error`, `StreamDelivery`, ordinary `ToolCalls`
+ or ordered/native `OutputItems`.
+- Invalid configuration is rejected atomically with HTTP 400, leaving the previous configuration usable.
+- A valid fixture selected by an unsupported route/kind pair, tool declaration or tool-bearing/native
+ history, native includes or structured-output request is rejected with a fixture-mismatch HTTP 409
+ before queue/graph consumption and cache population.
+
+For Anthropic refusal, `Category` must be null or `cyber`, `bio`, `frontier_llm`, `reasoning_extraction`
+or `general_harms`. A different bounded generic category is rejected at Anthropic fixture admission;
+the strict SDK's declared category contract is the reference. Other surfaces retain generic metadata
+in diagnostics rather than inventing provider fields. See the official
+[RefusalStopDetails type](https://github.com/anthropics/anthropic-sdk-csharp/blob/Anthropic-v12.58.0/src/Anthropic/Models/Messages/RefusalStopDetails.cs).
+
+## Qualified native mappings
+
+These are normal HTTP 200 output outcomes. Inspect their native fields; do not infer an exception
+from the policy outcome alone.
+
+| Exact provider route | `Filtered` | `Refused` |
+| --- | --- | --- |
+| `/openai/v1/chat/completions` | Final `finish_reason: content_filter`; explicit content/prefix | `message.refusal`, null ordinary content; streamed `delta.refusal`, then normal stop/terminal sequence |
+| `/deepseek/v1/chat/completions` | Final `finish_reason: content_filter`; explicit content/prefix | Unsupported pairing: fixture mismatch |
+| `/openai/v1/responses` | `status: incomplete`, `incomplete_details.reason: content_filter`; SSE ends with `response.incomplete` | Typed `refusal` content part; refusal delta/done events; completed response |
+| `/anthropic/v1/messages` | Unsupported pairing: fixture mismatch | `stop_reason: refusal` and `stop_details` with type `refusal` and required nullable category/explanation; final `message_stop` |
+| `/gemini/v1beta/models/{model}:generateContent` and `:streamGenerateContent` | Terminal candidate `finishReason: SAFETY`; terminal content omitted | Unsupported pairing: fixture mismatch |
+
+The OpenAI mappings follow the official [Chat completion contract](https://developers.openai.com/api/reference/resources/chat/subresources/completions/methods/create)
+and [Responses streaming events](https://developers.openai.com/api/reference/resources/responses/streaming-events).
+Anthropic refusal is a returned outcome distinct from an SSE error event; see
+[refusals and fallback](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback)
+and [streaming](https://platform.claude.com/docs/en/build-with-claude/streaming).
+Gemini output `SAFETY` is separate from prompt blocking with `promptFeedback`; this fixture implements
+only the candidate output case described by the [GenerateContent API](https://ai.google.dev/api/generate-content).
+
+Both ordinary JSON responses and text SSE are qualified. Gemini's existing JSON-array streaming
+transport also accepts this policy outcome; its separate post-header delivery-fault restriction to
+`alt=sse` does not apply here. A filtered Gemini JSON/final candidate has no `content`, so its SDK
+`Text` can be empty. Earlier SSE candidates can already have delivered the explicitly configured
+prefix. Runtime usage describes the configured generated fixture text; omitted final JSON content
+does not retroactively erase generated prefix tokens. This is deterministic fixture accounting,
+not a claim of upstream billing or inference equivalence.
+
+## DeepSeek Chat streaming
+
+The exact `/deepseek/v1/chat/completions` route accepts `Filtered`; it does not accept `Refused`.
+The original OpenAI SDK verifies its compatible JSON/SSE responses against the running server.
+The [DeepSeek Chat contract](https://api-docs.deepseek.com/api/create-chat-completion/) specifies
+`content_filter` as a native finish reason and a distinct usage layout: the final chunk always has one
+choice, a non-null finish reason and usage, followed by `[DONE]`. No separate usage-only chunk is emitted.
+With `include_usage: true`, intermediate chunks carry `usage: null`; false or omitted leaves that
+field absent until the final chunk. This applies to both ordinary and filtered DeepSeek completions.
+Other provider routes retain their own streaming behavior.
+
+Nineteen additional real-server cases cover empty and prefix output, the three usage options,
+unsupported refusal admission without consumption, recovery, graph replay and cache evidence.
+Non-streaming requests with a non-null `stream_options` object return HTTP 400 before fixture
+consumption, including explicit false and omitted `stream`. Together with the initial policy slice,
+the focused result is **79/79**, including three successful raw JSON configuration cases.
+The full integration result is **1,438/1,438**; a fresh installed-package consumer passed **16/16**, and the .NET SDK-built linux/arm64
+container passed native DeepSeek JSON/SSE, usage, invalid-options and recovery acceptance.
+
+## Policy completion, input rejection and broken delivery
+
+`SimulateContentFilter(...)` retains its existing request/history filtering behavior: a matching input
+fails with HTTP 400 and `content_filter` before generation. `Fails(...)` remains an explicit provider
+HTTP failure. Neither is a substitute for the native HTTP 200 output outcomes above.
+
+A policy outcome has a valid protocol ending. OpenAI Chat still finishes its SSE sequence; Responses
+uses `response.incomplete` for filtering or `response.completed` for refusal; Anthropic emits
+`message_stop`; Gemini emits its terminal `SAFETY` candidate. Once the final sequence is actually
+flushed, `TerminalMarkerObserved` is true and terminal-marker verification can pass. Responses
+`incomplete` describes the logical output, not a missing transport terminal.
+
+Use [stream delivery faults](StreamDeliveryFaults.md) for early EOF, post-frame delay or connection
+abort. Combining a delivery plan with a policy outcome is rejected rather than assigning an
+unqualified precedence. This slice does not simulate Responses `failed`, a provider SSE `error`
+event, Gemini prompt blocking, or a native tool's own error result.
+
+## Queue, graph, cache and history semantics
+
+A native policy outcome uses the existing successful inference commit path. It consumes the selected
+queued response or graph step, records actual explicit output usage, populates the normal qualified
+prompt cache and retains an eligible stored response. No separate queue, executor, retry service or
+history store is introduced. An explicit next attempt against a flat queue selects its next fixture.
+Graph replay returns the committed policy outcome without executing another step; session/provider/
+credential scope continues to use the existing owners.
+
+Anthropic `max_tokens: 0` remains cache-population-only. It returns before response selection and
+produces a new planless result: no output disposition is selected, no queued policy response is
+consumed and no graph step executes. A subsequent nonzero generation still selects the configured
+policy fixture.
+
+History preserves the input representation available in the native protocol:
+
+- An OpenAI refusal is retained as assistant `Content` plus
+ `LlmTestServerMessage.OutputDisposition.Kind = Refused`. In history, category and explanation are
+ stripped because native refusal input parts do not carry them.
+- Filtered visible text is retained as ordinary assistant prefix input. The prior output-envelope
+ filter status is not an input-part field, so history has no invented `Filtered` marker.
+- The original result, runtime event and request trace retain the full configured outcome metadata.
+ Input history is not a replacement for that output diagnostic evidence.
+
+This canonical projection is shared by stored-response restoration, history snapshots, cache keys,
+conversation fingerprints and message matching. Automatic `previous_response_id` continuation and
+canonical manual SDK history therefore replay the same graph turn. Bounds/enums are validated before
+projection. Metadata is excluded from model text tokens while retained objects/strings remain charged
+to their graph/history/event/trace budgets; exceptional diagnostic truncation remains visibly marked.
+
+OpenAI Chat accepts pure native refusal fields or pure typed refusal content parts, including empty
+refusal text. Responses accepts its native refusal part. Mixed ordinary text/refusal history and
+ambiguous simultaneous refusal representations are outside this qualified subset and are rejected;
+do not flatten them into an unmarked assistant answer. Native ordered output items are unchanged.
+
+## Microsoft.Extensions.AI client
+
+The package-owned `LlmTestServerChatClient` returns refusal text as `ErrorContent` with
+`ErrorCode = "Refusal"`, preserving it separately from ordinary `TextContent`. A streamed refusal is
+accumulated into that typed content, and a follow-up request maps it back to native refusal history.
+Filtering retains the native `content_filter` finish reason. HTTP 200 policy outcomes do not become
+fabricated HTTP failures or automatic thrown exceptions in this wrapper.
+
+`ErrorContent` is an official AI-content abstraction; this client uses it for the refusal convention above. See its
+[upstream source](https://github.com/dotnet/extensions/blob/main/src/Libraries/Microsoft.Extensions.AI.Abstractions/Contents/ErrorContent.cs).
+Applications can choose their own handling of that returned content. This wrapper convention does
+not replace the official SDK's distinct native refusal and filtering types.
+
+## Evidence and remaining E6 scope
+
+Focused tests under `tests/ManagedCode.LlmTestServer.Tests/Policy` start Kestrel and exercise real
+HTTP/SDK behavior: typed JSON/SSE outcomes, valid terminal evidence, empty/prefix text, strict refusal
+details, explicit recovery, graph replay, session/cache isolation, manual/stored canonical history,
+metadata bounds, unsupported combinations and the existing input-filter distinction. Raw HTTP
+supplements configuration and Gemini array boundaries. SDK automatic retries are disabled; Google
+automatic continuation is also disabled. The focused result is 79/79, including malformed refusal-history admission, bounded diagnostic
+retention, native DeepSeek usage and successful named-enum JSON configuration. The full suite passed
+1,438/1,438 with 92.58% line coverage. All 19 packages were packed; a fresh
+installed-package consumer passed 16/16, and the .NET SDK-built linux/arm64 container passed
+standalone health, dashboard, authorization, management, JSON/SSE, native-tool and DeepSeek
+policy/options/recovery acceptance.
+
+The larger E6 objective remains open for additional provider-specific outcomes and transports,
+including in-stream API error events and separately qualified semantics for other provider families.
+This document does not claim output-policy support for Azure OpenAI, Foundry, Bedrock, Groq, Mistral,
+Ollama, Cohere, OpenRouter, Perplexity, System One decision profiles, Cloudflare decision
+profiles or media/native-tool/structured-output combinations. Shared mapper code alone is not
+qualification. See [the delivery plan](LlmTestServerDeliveryPlan.md) for the remaining work.
diff --git a/docs/Features/ProviderApiContractCoverage.md b/docs/Features/ProviderApiContractCoverage.md
index e382740..7ab13d3 100644
--- a/docs/Features/ProviderApiContractCoverage.md
+++ b/docs/Features/ProviderApiContractCoverage.md
@@ -4,13 +4,13 @@ Current review: [2026-09-07 provider and dependency refresh](ProviderApiReview20
## Goal
-LLM TCK provider packages must not claim provider compatibility from memory or from an OpenAI-compatible shortcut. Every claimed provider method, route, streaming mode, modality, and API-version/header requirement is represented in the package profile's `ApiContract`.
+LLM Test Server provider packages must not claim provider compatibility from memory or from an OpenAI-compatible shortcut. Every claimed provider method, route, streaming mode, modality, and API-version/header requirement is represented in the package profile's `ApiContract`.
The current contract covers the generative API surface claimed by the provider profiles: chat/messages, streaming chat, embeddings, image generation or image inference, audio/speech, video generation where documented, model listing where claimed. Tool calls and structured output have [explicit fixture contracts and regression evidence](ToolAndStructuredFixtures.md); schema or tool-selection mismatches return 409 without consuming a scenario. Provider account administration, billing, files, fine-tuning, batches, and unrelated platform management APIs are outside the profile surface until a package explicitly claims them.
## Contract Shape
-Each `LlmTckProviderProfile` has:
+Each `LlmTestServerProviderProfile` has:
- `Capabilities`: the provider capabilities this package claims.
- `ApiContract.DocumentationUrl`: the official source used for the provider.
@@ -18,7 +18,7 @@ Each `LlmTckProviderProfile` has:
- `ApiContract.DocumentationVersion`: the API version, preview marker, or required version header when the provider publishes one.
- `ApiContract.Operations`: documented HTTP operations with method, path, docs URL, streaming support, required header or version, and `ImplementedByHosting`.
-`ImplementedByHosting` is deliberately separate from provider capability. It means `ManagedCode.LlmTck.Hosting` currently maps that exact method/path. For this supertest surface, every operation in a provider profile must be implemented. Do not add future or exploratory provider methods to `ApiContract.Operations` until `MapLlmTck()` exposes the route and a behavior test proves the shape.
+`ImplementedByHosting` is deliberately separate from provider capability. It means `ManagedCode.LlmTestServer.Hosting` currently maps that exact method/path. For this supertest surface, every operation in a provider profile must be implemented. Do not add future or exploratory provider methods to `ApiContract.Operations` until `MapLlmTestServer()` exposes the route and a behavior test proves the shape.
## Sync Rules
@@ -32,13 +32,12 @@ When provider docs change or a new route is added:
6. Update the test inventory when the acceptance surface changes.
7. Refresh `DocumentationRetrievedOn`; contract tests fail when the docs review is older than 180 days.
-## Guard Tests
+## Integration evidence
-`ProviderApiContractTests.ProviderApiContracts_AreDocBackedAndCoverClaimedCapabilitiesAsync` fails when a provider profile claims a capability without a documented operation, uses a non-official docs URL, omits a retrieval date or version, has docs older than 180 days, duplicates a method/path row, keeps an unimplemented operation in the profile, or marks streaming without a streaming capability.
-
-`ProviderApiContractTests.HostingProviderRoutes_AreCoveredByImplementedDocumentedOperationsAsync` fails when `MapLlmTck()` exposes a public provider route that is not represented by an implemented documented operation, or when a documented implemented operation has no matching route.
-
-`ProviderApiContractTests.ProviderApiContracts_UseExplicitProviderNamespacesAsync` fails when a provider profile exposes a hosted route outside its provider namespace, for example an OpenAI route outside `/openai`, an Anthropic route outside `/anthropic`, or an Azure OpenAI route outside `/azure-openai`.
+Provider support is verified by running the server and calling every claimed operation through HTTP and official
+SDKs. Cover supported parameters and streaming modes, version/auth validation, success/error envelopes and state
+transitions. Contract metadata and official documentation guide these tests; source/doc scans and reflection-based
+test guards are not used as evidence. See the [server integration inventory](../Testing/AcceptanceCriteriaTestInventory.md).
`AnthropicEndpointTests` prove the first native non-OpenAI provider route: `/anthropic/v1/messages` accepts Anthropic text messages, requires `anthropic-version: 2023-06-01`, accepts the provider-owned `x-api-key` header, returns Anthropic message/error JSON with deterministic usage, and streams Anthropic-named SSE events with usage on `message_start` and cumulative output usage on `message_delta`.
@@ -46,7 +45,7 @@ When provider docs change or a new route is added:
The same test class proves the OpenAI-compatible Responses API routes: OpenAI `/openai/v1/responses`, Groq `/groq/openai/v1/responses`, and OpenRouter `/openrouter/api/v1/responses`, including string input, structured message input with text and image parts, response output text shape, deterministic input/output usage, and Responses-style SSE streaming events.
-OpenAI image coverage now follows the current official image surface for this profile under the TCK provider namespace: `/openai/v1/images/generations`, `/openai/v1/images/edits`, and `/openai/v1/images/variations`. `OpenAiEndpointTests.ImageRoutes_ReturnDocumentedEditVariationAndStreamingShapesAsync` proves JSON generation streaming with `image_generation.partial_image` and `image_generation.completed`, multipart edit output and `image_edit.*` streaming, multipart variation input for the DALL-E 2 route, deterministic base64 fixture output, and documented option validation.
+OpenAI image coverage now follows the current official image surface for this profile under the Test Server provider namespace: `/openai/v1/images/generations`, `/openai/v1/images/edits`, and `/openai/v1/images/variations`. `OpenAiEndpointTests.ImageRoutes_ReturnDocumentedEditVariationAndStreamingShapesAsync` proves JSON generation streaming with `image_generation.partial_image` and `image_generation.completed`, multipart edit output and `image_edit.*` streaming, multipart variation input for the DALL-E 2 route, deterministic base64 fixture output, and documented option validation.
OpenAI audio transcription is covered through `/openai/v1/audio/transcriptions` with multipart form input, JSON output, plain-text output, and documented `transcript.text.delta` / `transcript.text.done` SSE events for `stream=true`. Groq `/groq/openai/v1/audio/transcriptions` is covered with multipart input and Groq's `x_groq.id` response metadata. Azure OpenAI `/azure-openai/openai/deployments/{deployment}/audio/transcriptions?api-version=2024-10-21` is covered with deployment-owned model resolution, `api-key` auth, multipart input, and verbose JSON output. Audio translation is covered through OpenAI `/openai/v1/audio/translations`, Groq `/groq/openai/v1/audio/translations`, and Azure OpenAI `/azure-openai/openai/deployments/{deployment}/audio/translations?api-version=2024-10-21` with multipart input, JSON/text or verbose JSON output as documented, Groq metadata, Azure deployment-owned model resolution, and no unsupported streaming flag. Groq speech is covered through `/groq/openai/v1/audio/speech` with the documented `voice` requirement, Groq-specific response formats, and deterministic audio bytes.
@@ -72,4 +71,4 @@ Legacy Azure deployment routes accept exactly one supported `api-version`: `2024
`AzureSdkCompatibilityTests.AzureOpenAiClient_CanUseDeploymentChatAndEmbeddingsAsync` proves chat, streaming and embeddings with the installed SDK default. `ReviewHttpRegressionTests.AzureLegacyVersion_AcceptsDocumentedStableAndPreviewVersionsAsync` covers the supported stable and preview contracts; the negative queue-preservation test covers invalid inputs and unknown date-shaped versions. The [official SDK options source](https://github.com/Azure/azure-sdk-for-net/blob/main/sdk/openai/Azure.AI.OpenAI/src/Custom/AzureOpenAIClientOptions.cs) owns automatic service-version selection. Supported deployment contracts are documented in the [GA reference](https://learn.microsoft.com/en-us/azure/foundry/openai/reference) and [dated preview reference](https://learn.microsoft.com/en-us/azure/foundry/openai/reference-preview).
-The [OpenAI chat reference](https://developers.openai.com/api/reference/resources/chat/subresources/completions/methods/create) defines `stream_options.include_usage`: the final usage chunk has empty choices and precedes `[DONE]`. The TCK preserves provider-specific cache shapes in that chunk. See the [Azure version lifecycle](https://learn.microsoft.com/en-us/azure/foundry/openai/api-version-lifecycle) for the separate v1 contract.
+The [OpenAI chat reference](https://developers.openai.com/api/reference/resources/chat/subresources/completions/methods/create) defines `stream_options.include_usage`: the final usage chunk has empty choices and precedes `[DONE]`. The Test Server preserves provider-specific cache shapes in that chunk. See the [Azure version lifecycle](https://learn.microsoft.com/en-us/azure/foundry/openai/api-version-lifecycle) for the separate v1 contract.
diff --git a/docs/Features/ProviderSdkCompatibility.md b/docs/Features/ProviderSdkCompatibility.md
new file mode 100644
index 0000000..bdaaa2a
--- /dev/null
+++ b/docs/Features/ProviderSdkCompatibility.md
@@ -0,0 +1,40 @@
+# Official provider SDK integration
+
+Supported success, streaming, tool and conversation flows must be exercised through the official
+provider SDK against a running Test Server. Raw HTTP supplements malformed input and exact wire
+assertions. A custom HTTP transport still sends real requests to the hosted server; it does not
+replace SDK serialization, parsing, streaming or error handling.
+
+| Client | Pinned package | Added running-server evidence |
+| --- | --- | --- |
+| Anthropic | `Anthropic` 12.58.0 | Native web search JSON/SSE, citations, assistant history and all six native search errors |
+| Google Gemini | `Google.GenAI` 1.26.1 | GenerateContent JSON/SSE, signed function rounds, batch embeddings, dimensions, auth, filters and error recovery (36 cases) |
+| Amazon Bedrock | `AWSSDK.BedrockRuntime` 4.0.101.11 | Converse, ConverseStream, InvokeModel, InvokeModelWithResponseStream, tool rounds and rate-limit recovery |
+| OpenAI-compatible routes | `OpenAI` 2.14.0 | Groq, OpenRouter, Mistral and DeepSeek function rounds, JSON/SSE, provider errors and explicit recovery |
+
+The last row proves compatibility with the official **OpenAI client** at those route roots. It does
+not claim that the OpenAI package is a provider-owned SDK for those providers. Existing OpenAI,
+Azure OpenAI and Microsoft Foundry SDK integration suites remain part of the full gate. Other
+provider SDK families and all remaining roadmap capabilities still require their own qualification.
+
+## Current model provenance
+
+Anthropic fixtures use the original SDK identifier `Anthropic.Models.Messages.Model.ClaudeSonnet5_5`.
+The provider-neutral contract uses the corresponding documented wire ID `claude-sonnet-5-5`.
+Sonnet 5.5 accepts automatic tool choice and rejects forced `any`/named tool choice. Sources:
+[official SDK](https://github.com/anthropics/anthropic-sdk-csharp),
+[Sonnet 5.5](https://platform.claude.com/docs/en/models/sonnet-5-5/overview).
+
+Google's SDK accepts a model string and does not expose a closed model enum. Its current fixtures use
+[`gemini-3.8-flash`](https://ai.google.dev/gemini-api/docs/models/gemini-3.8-flash) and
+[`gemini-embedding-2`](https://ai.google.dev/gemini-api/docs/models/gemini-embedding-2), taken from the
+current official model pages. Do not invent SDK constants that do not exist.
+
+The added OpenAI-client compatibility fixtures explicitly configure the documented
+[`gpt-5.5`](https://developers.openai.com/api/docs/models/gpt-5.5) fixture ID. A configured model is
+local deterministic test data; this is not a claim that every compatible remote provider hosts it.
+
+Native decision wire identifiers live separately in `LlmTestServerDecisionModelIds`, with original
+provider/source links. They are opt-in decision profiles and are not registered as default chat
+models. Account-specific live model availability still belongs to each provider's authenticated
+Models API; the test server does not pretend to discover a live account catalogue.
diff --git a/docs/Features/RequestVerificationAndDeterminism.md b/docs/Features/RequestVerificationAndDeterminism.md
new file mode 100644
index 0000000..373cf7e
--- /dev/null
+++ b/docs/Features/RequestVerificationAndDeterminism.md
@@ -0,0 +1,194 @@
+# Request evidence, verification and wire determinism
+
+Status: Implemented and locally qualified through running-server integrations and an independent installed-package
+consumer. E4 branch CI and public release remain pending.
+Related: [architecture](../Architecture.md), [ADR-0005](../ADR/ADR-0005-request-evidence-and-wire-determinism.md),
+[delivery E4](LlmTestServerDeliveryPlan.md), [conversations](ConversationDSL.md), [sessions](TestSessions.md).
+
+## Purpose and boundaries
+
+Tests query the same bounded request journal used by the dashboard, export retained evidence, and submit
+serializable expectations to the running server. Core owns public diagnostic/verification DTOs, matching and
+wire metadata. Hosting owns request capture, retention and authenticated control endpoints. Client exposes
+typed APIs without a dependency on Hosting. All evidence belongs to the selected test session.
+
+```mermaid
+flowchart LR
+ Provider[Provider HTTP request] --> Runtime[Session runtime and fixture]
+ Provider --> Capture[Bounded request journal]
+ Runtime --> Capture
+ Capture --> Snapshot[One snapshot and retention counters]
+ Snapshot --> Query[Query and export]
+ Snapshot --> Verify[Verification evaluator]
+ Runtime --> Graph[Conversation status]
+ Graph --> Verify
+ Clock[Seed and fixed fixture clock] --> Runtime
+```
+
+## Query and export
+
+`GET /admin-api/requests` returns a JSON array. `GET /admin-api/requests/export` uses the same query against
+one captured snapshot and returns `LlmTestServerRequestExport`. Both enforce control authorization and session
+selection. Querying and exporting do not execute provider operations or consume scenario responses.
+
+| Query parameter | Meaning |
+| --- | --- |
+| `provider`, `model`, `requestId`, `status` | Exact provider ID, model ID, server attempt ID, HTTP status |
+| `operation`, `scenario`, `conversation`, `step` | Exact operation/scenario/conversation/step ID |
+| `streaming`, `completed`, `success` | Boolean filters; an in-progress request has no success outcome |
+| `errorCode` | Exact retained provider error code |
+| `from`, `to` | Inclusive real request-start timestamps |
+| `order` | `desc` by default, or `asc`, ordered by journal sequence |
+| `offset`, `limit` | Nonnegative offset; limit 1–500, default 500 |
+| `format` on export | `json` by default, or `ndjson` |
+
+Duplicate or blank supplied values, malformed values, invalid ranges and unsupported order/format return 400.
+Status must be 100–599 and `from` must not follow `to`. String comparisons are exact. Control authorization
+failure returns 401. Configure/reset clear the selected runtime's journal and evidence counters.
+
+The array response also carries `X-Total-Count`, `X-Total-Observed`, `X-Evicted-Count`,
+`X-Retained-Byte-Count` and `X-Retention-Truncated`. Total count is the filtered count before pagination.
+The conversation selector header alone does not filter this endpoint; use its `conversation` query parameter.
+
+`LlmTestServerRequestSnapshot` contains requests, `TotalMatched`, `TotalObserved`, `EvictedCount`,
+`RetentionTruncated`, retained bytes and first/last retained sequence. Observed and eviction counters describe
+the selected journal as a whole. Truncation is sticky until reset, including payload-preview truncation.
+Sequence increases for each observed provider attempt; updates retain its original sequence. Default retention
+is 500 entries and 16 MiB, with 64 KiB previews. Export is a bounded diagnostic snapshot, not a complete byte
+recording or record/replay cassette.
+
+The JSON export envelope has `schemaVersion: 1`, `query` and `evidence`. NDJSON sends one `type: metadata`
+line with that version, query and evidence metadata, followed by `type: request` lines carrying each retained
+entry. Metadata contains no duplicate request array. Pagination applies equally to both formats.
+
+The client methods are `GetRequestsAsync`, `ExportRequestsAsync` and `ExportRequestsNdjsonAsync`, accepting
+`LlmTestServerRequestQuery` from `ManagedCode.LlmTestServer.Diagnostics`. C# order values are
+`LlmTestServerRequestOrder.Ascending` and `Descending`.
+
+## Verification
+
+`POST /admin-api/verify` accepts `LlmTestServerVerificationRequest`; `LlmTestServerClient.VerifyAsync` exposes
+the same contract. A valid assertion returns HTTP 200 with `Passed`, `EvidenceComplete`, structured `Failures`
+and `MatchedRequestIds`. A failed expectation is a verification result; malformed expectations return 400.
+The conversation header scopes verification to that conversation before the body query is applied. Session
+credentials and control authorization remain required. Verification does not change queues or graph state.
+
+| Request property | Behavior |
+| --- | --- |
+| `Scope` | Shared request query applied before expectations |
+| `Requests` | Named `LlmTestServerRequestExpectation` entries with query, minimum/maximum count, tools and optional terminal-marker requirement |
+| `InOrder` | Each request expectation's matched sequence range follows the previous expectation's range |
+| `NoUnexpectedCalls` | Every request in scope must be accounted for by a request or retry expectation |
+| `Conversations` | Match scenario plus optional provider/conversation; require visited step IDs and/or terminal state |
+| `Retries` | Match retry group and query; require attempt bounds, exact optional status sequence and Retry-After behavior |
+
+The request supports at most 256 combined request/conversation/retry expectations. At least one expectation or
+`NoUnexpectedCalls` is required. Request/tool count defaults are exactly one; a nullable maximum permits an
+unbounded upper count within retained evidence. Each request expectation permits at most 64 tool expectations.
+Tool-result expectations permit at most 64 JSON-field predicates; a conversation permits at most 256 required
+step IDs. Invalid JSON and invalid count ranges are rejected before evaluation.
+
+`LlmTestServerToolExpectation.Kind` selects `ResponseCall`, `RequestCall` or `Result`. Response calls come from
+structured runtime response metadata. Request calls come from normalized assistant history. Tool results are
+linked to preceding calls by call ID. Predicates cover name, call ID, structurally equal arguments, structurally
+equal result JSON and JSON fields using the conversation selector syntax. Counts apply per matched request;
+historical calls repeated across request histories remain observable in each history.
+
+```csharp
+var result = await session.Control.VerifyAsync(new LlmTestServerVerificationRequest
+{
+ Requests =
+ [
+ new()
+ {
+ Name = "completed chat",
+ Query = new() { Provider = "openai", Success = true },
+ MinimumCount = 1,
+ MaximumCount = 1,
+ },
+ ],
+ NoUnexpectedCalls = true,
+});
+```
+
+## Incomplete evidence and terminal applicability
+
+Verification cannot pass after journal eviction, retained/preview payload truncation, selected pending requests,
+or pagination that excludes matching entries. `EvidenceComplete` is false and failures identify incomplete
+journal/page/timing evidence. This rule is conservative across the selected journal, even if an expectation
+filters to a smaller subset. A matched subset never proves that no other calls occurred after evidence loss.
+Use a fresh session or reset and sufficient configured retention for a complete test flow.
+
+Request traces preserve bounded structured tool calls and tool-result IDs in addition to payload previews.
+`RequireStreamingTerminalMarker` requires both streaming classification and a successfully written/flushed
+protocol terminal marker. Supported terminal shapes include OpenAI `[DONE]`/Responses completion, Anthropic
+message stop, Cohere message end, Ollama `done`, Gemini final finish reason and Bedrock Converse stop/metadata,
+plus image/transcription completion events. Exceptions and interrupted writes do not create terminal evidence.
+Bedrock InvokeModel's current chunk format ends at EOF without an explicit terminal marker; do not request
+terminal-marker verification for that operation. Successful transport completion alone is insufficient.
+
+## Retry evidence
+
+Set `X-Llm-Test-Server-Retry-Group` on each attempt in one logical retry flow. It is separate from the server's
+unique request/attempt ID and selects evidence rather than granting access. The header must occur once, be
+nonblank and contain at most 128 characters. Configure `.Fails(...).RetryAfter(seconds)` on a scenario or step
+to emit deterministic `Retry-After` seconds for a scripted error. The delay is nonnegative and requires a
+preceding error fixture. The application or real provider SDK performs the retry.
+
+`LlmTestServerRetryExpectation` specifies group ID, query, minimum/maximum attempts (defaults 1–3), optional
+exact status sequence, minimum advertised Retry-After and `RespectRetryAfter`. Retry checks examine 429/503
+attempts. A retry expectation also accounts for its requests under `NoUnexpectedCalls`.
+
+Trace start/completion store real UTC observations and independent `StartedMonotonicSeconds` /
+`CompletedMonotonicSeconds` from `Stopwatch`. Retry spacing is measured from the preceding completion to the
+next start with monotonic timestamps. Missing/nonfinite/reversed timing produces incomplete evidence.
+`Retry-After` seconds are used directly; an HTTP-date is converted to a delay against the observed completion
+UTC timestamp. The actual spacing comparison remains monotonic. Fixed fixture time never satisfies a real wait.
+
+## Seeded wire metadata
+
+Configure core with `WithDeterminism(seed, fixedUtc)` or the client with `UseDeterminism(seed, fixedUtc)`.
+The serializable `LlmTestServerDeterminism` holds seed and UTC time. Seeds are nonblank and at most 256
+characters. Without configuration, wire metadata uses live IDs/time.
+
+The runtime reserves a provider-local request ordinal at provider request entry inside each session. Seed,
+provider namespace and ordinal derive one metadata identity; `IdFor(domain)` derives IDs for response,
+message and other wire fields. Each result carries `WireMetadata` with creation time, clock mode and sequence;
+all chunks reuse it. Reset/configure restart provider counters. Provider requests, including failed attempts,
+consume ordinals; control queries/explanations do not. Concurrent calls within one provider follow request-entry
+ordering. Parallel sessions have independent counters, and calls to another provider do not advance this one.
+
+Stored Responses and successful conversation replay retain response metadata, preserving fixture identity
+across JSON and streaming. Provider prefixes and native field names remain provider-specific. Fixed mode also
+sets the HTTP Date header from fixture time. This controls generated wire IDs/timestamps, not arbitrary fixture
+fields: explicit model metadata, dictionaries and configured video timestamps retain their configured values.
+
+Traces expose `WireClockMode`, `WireCreatedAt` and `WireSequence` alongside real observations. Initial request
+metadata is enriched with actual runtime result metadata, including the retained metadata of a replay.
+Runtime event timestamps, trace UTC observations, elapsed durations and monotonic retry evidence remain real.
+Session IDs/access keys remain cryptographically random; seeds are fixture configuration, not credentials.
+The mode does not introduce network calls or relax provider wire validation.
+
+## Verification and completion criteria
+
+Use running-server HTTP and official SDK tests for every query boundary, export format, auth/session scope,
+count/order/unexpected-call assertion, tool history/result predicate, graph visited/terminal assertion, retry
+status/delay and incomplete-evidence failure. Verify seeded reset/replay and JSON/stream identity across provider
+families, media timestamps, independent sessions/provider counters and real diagnostic time.
+
+Relevant suites include `RequestQueryExportIntegrationTests`, `VerificationIntegrationTests`,
+`DeterminismIntegrationTests` and `NativeDeterminismIntegrationTests`. Completion additionally requires the full
+integration suite, canonical Release build/format, at least 90% production line coverage and installed consumer.
+Local qualification on 2026-10-20 passed 812/812 integration tests with 91.66% production line coverage;
+the final Release build had zero warnings/errors. All 19 packages packed, and an independent clean NuGet
+consumer exercised packaged Aspire, official SDKs, query/export/verification/fixed metadata and Chromium (1/1).
+Evidence: `artifacts/delivery/e4-build-final.log`, `e4-coverage-final.log`, `e4-pack.log`, `e4-consumer.log`.
+These local package checks do not establish public-feed availability. E4 branch CI has not run yet.
+See the [delivery ledger](LlmTestServerDeliveryPlan.md#11-журнал-реалізації) for subsequent delivery status.
+
+```sh
+dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore
+dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
+dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal
+bash scripts/coverage.sh
+```
diff --git a/docs/Features/ResponsesContinuation.md b/docs/Features/ResponsesContinuation.md
index ba1be93..ee00203 100644
--- a/docs/Features/ResponsesContinuation.md
+++ b/docs/Features/ResponsesContinuation.md
@@ -32,15 +32,12 @@ flowchart LR
Output --> SDK
```
-Acceptance:
+Integration acceptance:
-1. An ordinary or streamed official SDK tool loop reaches its scripted final response and the runtime journal
- contains the original text/image input plus the actual tool result (`LlmTckResponsesContinuationTests`).
-2. Another provider or credential cannot read a parent; reset/configure invalidates every parent
- (`LlmTckChatHistoryTests`).
-3. Stored input snapshots survive caller mutation and do not carry old instructions into a new request
- (`LlmTckChatHistoryTests`).
-4. Changing the model preserves original user and assistant messages and selects the new model in ordinary
- and streaming official SDK calls (`LlmTckChatHistoryTests`, `LlmTckResponsesContinuationTests`).
-5. Disabled/full count or byte capacity fails visibly without consuming a fixture; `store=false` remains
- stateless (`LlmTckChatHistoryTests`, existing OpenRouter provider regressions).
+1. Ordinary and streaming official SDK tool loops reach scripted final responses with the original input and
+ actual tool results visible through `/admin-api/assertions` (`LlmTestServerResponsesContinuationTests`).
+2. Model changes preserve history in ordinary and streaming official SDK calls
+ (`LlmTestServerResponsesContinuationTests`).
+3. Foreign provider/credential parents, unknown/reset identities, disabled/full count/byte capacity, instruction
+ replacement and `store=false` must be verified through server HTTP/SDK requests. Qualification results are
+ recorded in the [delivery plan](LlmTestServerDeliveryPlan.md); this contract alone does not establish coverage.
diff --git a/docs/Features/StreamDeliveryFaults.md b/docs/Features/StreamDeliveryFaults.md
new file mode 100644
index 0000000..a17d92f
--- /dev/null
+++ b/docs/Features/StreamDeliveryFaults.md
@@ -0,0 +1,171 @@
+# Stream delivery faults
+
+Status: **E6 text SSE delivery faults qualified through 42/42 running-server integration cases** across
+OpenAI Chat Completions, OpenAI Responses, Anthropic Messages and Gemini. Delivery and cancellation cases
+use the official OpenAI 2.14.0, Anthropic 12.58.0 (strict response validation) and Google.GenAI 1.26.1 clients
+over real Kestrel/TCP. Replay identity also uses official SDKs against hosted ASP.NET Core HTTP routes;
+raw HTTP supplements transport boundaries, admission and invalid-configuration checks. A fresh installed-package Aspire consumer
+passed **9/9** cases. The SDK-built container also passed acceptance using the README's SDK publish command.
+The combined code-only integration gate passed **1,359/1,359**, with **92.52%** production line coverage.
+Canonical formatting and the final Release build passed with no warnings or errors.
+
+## Configure an explicit delivery plan
+
+`LlmTestServerScenarioResponse.StreamDelivery` accepts a `LlmTestServerStreamDelivery` from the
+`ManagedCode.LlmTestServer.Scenarios` namespace. Scenario and conversation-step builders expose
+`WithStreamDelivery(...)`, applied to the preceding response:
+
+```csharp
+config.UseChatModel(LlmTestServerKnownModelIds.Gpt55)
+ .UseChatScenario("partial-text", scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt55)
+ .Responds("First second.", "First ", "second.")
+ .WithStreamDelivery(new()
+ {
+ Mode = LlmTestServerStreamDeliveryMode.EarlyCleanEnd,
+ AfterContentFrames = 1,
+ })
+ .Responds("Explicit next attempt."));
+```
+
+The plan belongs to the fixture, not to an upstream request option. It does not introduce a provider
+header, environment toggle or alternate endpoint.
+
+| Mode | Behavior after the selected content frame has been written and flushed |
+| --- | --- |
+| `EarlyCleanEnd` | End the HTTP response normally, omitting remaining content and the selected protocol's terminal sequence |
+| `DelayThenContinue` | Pause once for `DelayMilliseconds`, then resume the remaining content and ordinary terminal sequence if the request remains active |
+| `AbortConnection` | Abort the server request transport, omitting remaining content and protocol-terminal frames |
+
+`AfterContentFrames` defaults to 1. It must be 1–128 and cannot exceed the configured content-frame
+count of nonempty text chunks. Empty chunks do not count; an empty response or unreachable boundary
+is rejected at configuration. A nonempty response without explicit chunks has one frame. Delay mode requires 1–60,000 milliseconds;
+other modes require zero delay. These are bounded local fixture policies. Explicit chunks must
+concatenate exactly to the response content. Invalid plans fail configuration atomically.
+
+A plan applies only to plain-text responses. Scripted provider errors, ordinary function calls and
+ordered/native output items cannot share that response. The qualified contract admits these exact routes:
+
+| Surface | Request | Counted text frame | Ordinary successful protocol ending |
+| --- | --- | --- | --- |
+| OpenAI Chat Completions | `POST /openai/v1/chat/completions`, `stream: true` | Nonempty content chunk | Finish-reason chunk, requested usage chunk, `[DONE]` |
+| OpenAI Responses | `POST /openai/v1/responses`, `stream: true` | Nonempty `response.output_text.delta` | Text/content/output done events, then `response.completed` |
+| Anthropic Messages | `POST /anthropic/v1/messages`, `stream: true` | Nonempty `content_block_delta` text delta | Content-block stop, message delta, `message_stop` |
+| Gemini | `POST /gemini/v1beta/models/{model}:streamGenerateContent?alt=sse` | Nonempty text candidate payload | Final candidate `finishReason: STOP` and usage |
+
+Start/progress/empty frames do not advance the delivery boundary. Gemini requires exactly one `alt=sse`;
+its JSON-array streaming transport is excluded. Non-streaming requests, other provider roots, media
+streaming, tool declarations/native includes/tool-bearing history and structured-output requests are rejected
+as fixture mismatches before the selected response is consumed. Native capability metadata alone does not
+mean a request declared a tool. Do not infer support for another route because it shares a mapper.
+Anthropic cache-population-only requests (`max_tokens: 0`) return before response selection: they warm
+prompt-cache state without consuming a queued response or executing a graph step. Their planless response
+emits no text and applies no delivery fault. A subsequent generation still selects the configured fault fixture.
+
+## Inference commit and delivery are different boundaries
+
+The runtime computes and commits the complete deterministic inference result before the HTTP writer
+starts delivering it. The selected queue entry or conversation step, retained response and successful
+prompt-cache effects are therefore already committed when the delivery plan fires. A delivery failure
+can leave the client with only a prefix while the runtime retains the full logical answer.
+
+An explicit retry against a flat response queue selects its next response. The server does not retry or
+roll back the committed answer because a terminal marker was lost. A repeated request that qualifies
+for existing conversation replay returns the retained result and reapplies its delivery plan without
+executing the step again. Replay therefore reproduces the fault rather than repairing the first
+transport. A new valid conversation turn advances according to the configured graph.
+
+Request ID, streaming transport flag, delivery-surface marker and previous-response lookup ID are excluded
+from the logical inference fingerprint. Changing only JSON/SSE delivery therefore does not create a new
+logical turn; replay still validates the selected fixture against the requested transport. A delivery fault
+cannot be replayed through an unsupported JSON/array transport to bypass its SSE applicability rule.
+
+Conversation ownership includes the provider namespace, conversation label and credential hash inside the
+owning test session. Keep the same SDK credential when comparing SDK and raw HTTP requests or replaying a
+turn, even when the host does not require authentication. A different supplied credential selects a different
+conversation owner; the conversation label alone is not authorization.
+
+This differs from pre-inference `.DelaysBy(...)`: cancellation before the existing runtime commit can
+release a reservation. Cancellation during the new delivery pause happens after inference commit.
+The delivery delay uses real elapsed time even when provider wire metadata uses a fixed fixture clock.
+
+## Transport completion and protocol completion
+
+An HTTP 200 and clean response-body EOF do not prove a complete chat stream. OpenAI Chat Completions
+uses data-only SSE; a normal stream has its final finish-reason chunk and `data: [DONE]`. Requested
+usage appears in a separate final chunk before `[DONE]`; interrupted streams can omit it.
+[Official streaming guide](https://developers.openai.com/api/docs/guides/streaming-responses),
+[Chat Completions streaming contract](https://developers.openai.com/api/reference/resources/chat/subresources/completions/methods/create).
+
+The pinned OpenAI .NET 2.14.0 API exposes `CompleteChatStreamingAsync` and typed
+`StreamingChatCompletionUpdate.ContentUpdate`, `FinishReason` and `Usage`. Its SSE enumerator can
+finish on either `[DONE]` or clean EOF, without itself requiring a finish reason. Thus the expected
+clean-end test observes a prefix and missing terminal evidence; it must not assume an SDK exception.
+Running-server tests confirm clean EOF produces a partial result without a finish reason, while the
+real Kestrel abort interrupts the official client. Tests forward unchanged bytes and coordinate the
+first actual SDK content update before releasing the server flush, avoiding a scheduling race.
+[Package-pinned SDK parser](https://github.com/openai/openai-dotnet/blob/2e77b08828145f658ec04e49aec87abb1543c553/OpenAI/src/Utility/AsyncSseUpdateCollection.cs),
+[pinned chat client](https://github.com/openai/openai-dotnet/blob/2e77b08828145f658ec04e49aec87abb1543c553/OpenAI/src/Custom/Chat/ChatClient.cs).
+
+### Qualified SDK parser boundaries
+
+The official OpenAI 2.14 Responses client also uses the common SSE collection. A frame-aligned clean
+EOF can therefore end typed update enumeration without `response.completed`; assert the typed text prefix
+and missing completion, rather than assuming an exception or requiring a Chat-style `[DONE]`.
+[Responses client source](https://github.com/openai/openai-dotnet/blob/2e77b08828145f658ec04e49aec87abb1543c553/OpenAI.Responses/src/Custom/ResponsesClient.cs).
+
+Anthropic 12.58 strict response validation validates each event, but raw typed stream enumeration does
+not require `message_stop` before EOF. Its separate official `.Aggregate()` helper requires a stop event
+and throws for a partial message. Normal message completion ends with `message_stop`.
+[Streaming contract](https://platform.claude.com/docs/en/build-with-claude/streaming),
+[SDK event reader](https://github.com/anthropics/anthropic-sdk-csharp/blob/Anthropic-v12.58.0/src/Anthropic/Core/Sse.cs),
+[SDK aggregator](https://github.com/anthropics/anthropic-sdk-csharp/blob/Anthropic-v12.58.0/src/Anthropic/Helpers/MessageContentAggregator.cs).
+
+Google.GenAI 1.26.1 accepts EOF with no buffered partial SSE frame and does not enforce a finish reason.
+A remaining incomplete JSON segment instead causes a parser error. A missing `finishReason` means the
+model has not stopped generating; for this text fixture, successful continuation ends with `STOP`.
+These faults flush whole SSE frames, so clean early end differs from byte truncation.
+[Gemini contract](https://ai.google.dev/api/generate-content#method:-models.streamgeneratecontent),
+[pinned HTTP parser](https://github.com/googleapis/dotnet-genai/blob/c071e7d18f779bf166a66c0a7ff715ab24035273/Google.GenAI/HttpApiClient.cs).
+
+The focused integrations confirm clean EOF returns the observed text without a terminal event on all four
+routes, real connection abort interrupts the clients, and delay continuation/cancellation preserves the
+recorded prefix and transport outcome. Tests disable ordinary SDK retries and Google's
+`GenerateContentConfig.AutomaticContinuation` to prove individual attempts. They also cover the boundary
+after **all text** has arrived: complete text alone still does not imply protocol completion when the final
+finish/completion/stop event is missing, and `stream.terminal` verification fails.
+
+## Public evidence and qualification boundary
+
+Request diagnostics expose `StreamDelivery`, `StreamDeliveryApplied` and `EmittedContentFrames`
+alongside the existing transport state, status, response preview, timing and
+`TerminalMarkerObserved`. A configured plan and a reached trigger are distinct observations.
+An ordinary response EOF can have completed transport with no protocol terminal; an aborted transport
+must not acquire a terminal marker. Query/export preserves this structured evidence under its existing
+retention bounds. Runtime events describe committed inference; transport traces describe actual delivery.
+Neither record alone proves the client received the full answer.
+
+The verification API's `stream.terminal` check can detect missing protocol completion. Consumer retry
+policies should be disabled when proving individual attempts. Test the same configured plan through
+the applicable official provider client over a running Kestrel server, verify the actual emitted prefix and
+finish/usage behavior, inspect request evidence, exercise explicit retry and graph replay, and confirm
+that a subsequent health/provider request still works. Delay/cancellation tests must coordinate actual
+first-frame delivery rather than rely on a scheduling race.
+
+Malformed SSE/JSON, byte-level truncation, tool/native/media streams, output-stage content filtering,
+provider families outside the four listed routes and resource/process termination remain separate unqualified delivery-fault
+contracts. This bounded text slice does not claim all E6 capabilities.
+
+The cache regression confirms that a partial stream retains its already committed prompt-cache entry:
+the explicit next request with identical input reports positive cached tokens in both the official SDK
+and public request trace. Test hosts warm health/endpoint metadata over real HTTP before starting the
+stream watchdog. Cancellation starts after the first real SDK text update, and tests drain completion
+traces before cleanup/next assertions. Health warmup and trace draining synchronize test lifecycle; they
+neither retry inference nor change provider behavior, fault boundaries or committed state.
+
+The 42-case focused evidence is recorded in `artifacts/delivery/e6-multi-stable-sdk.log`. All 19 NuGet
+packages were packed, and `artifacts/delivery/e6-multi-installed-consumer.log` records the fresh Aspire
+consumer's 9/9 cases, including delivery through the official clients and the TypeSafe/Jev example.
+Standalone acceptance used an image built by the .NET SDK's `PublishContainer` target with the README's
+single-platform command. These are local qualification results; public package/image publication remains
+part of the owner-merged release gate.
diff --git a/docs/Features/TestSessions.md b/docs/Features/TestSessions.md
new file mode 100644
index 0000000..cedc91e
--- /dev/null
+++ b/docs/Features/TestSessions.md
@@ -0,0 +1,67 @@
+# Isolated test sessions
+
+Status: Implemented and locally qualified; public-package release pending.
+Architecture: [ADR-0003](../ADR/ADR-0003-isolated-test-sessions.md).
+
+A shared server can run independent tests concurrently. Each session owns its configuration, scenario queues,
+response history, prompt cache, fault counters, video jobs, assertions and bounded request journal. A reset or
+configure call changes the selected session only. Calls without session headers use the existing default runtime.
+
+```csharp
+var server = new LlmTestServerClient(httpClient, "management-key");
+await using var session = await server.CreateSessionAsync(config => config
+ .RequireBearerToken("provider-key")
+ .UseGpt41Mini()
+ .UseChatScenario("greeting", scenario => scenario.Responds("Hello from this test")));
+
+using var chat = session.Control.CreateChatClient();
+var reply = await chat.GetResponseAsync("Hello");
+var assertions = await session.Control.GetAssertionsAsync();
+```
+
+The supplied `httpClient` remains caller-owned and usable after session disposal. Different session clients
+share its transport without changing its default headers. Use `session.HttpClient` as the transport for official
+SDKs; configure their endpoint from the server's actual allocated endpoint and supply the provider API key as
+usual. The transport adds session ID/key headers to every request, including streaming and multipart operations.
+
+## HTTP contract
+
+| Request | Result |
+| --- | --- |
+| `POST /admin-api/sessions` with `{}` | Clone startup configuration; return 201, Location, Cache-Control: no-store, ID/key/reservation |
+| `POST /admin-api/sessions` with `configuration` | Create an independent runtime with that configuration |
+| Existing provider/control routes with both session headers | Operate on the selected runtime and journal |
+| `DELETE /admin-api/sessions/{id}` with that session's headers | Release capacity, retire the runtime and return 204 |
+| Missing/unknown/foreign/duplicate session ID or key | 404 `session_not_found`, without invoking or journaling the default runtime |
+| Session count/state budget exhausted | 409 `session_capacity_exceeded` |
+| Invalid/oversized configuration | 400; preserve the previous configuration, counters and reservation |
+
+Headers are `X-Llm-Test-Server-Session` and `X-Llm-Test-Server-Session-Key`. They select and authorize the session;
+provider bearer/API-key authentication remains independent. The session access key is returned only at creation
+and is redacted from provider diagnostics. To change the provider key through configure, use
+`session.Control.WithBearerToken(newKey)` for subsequent control calls. Session credentials remain unchanged.
+
+Creation uses the default runtime's management bearer requirement and rejects session selector headers with 400; create through the root management client. Deletion uses the session's own ID/key, so
+changing the default provider token does not prevent cleanup. Deleting a session invalidates in-flight delayed
+work with 409 `llm_test_server_request_superseded`; subsequent calls return 404. Cancelling a request keeps the existing
+queue rollback contract. Deleting an already absent session returns 404; typed disposal accepts that response.
+
+## Bounds
+
+Configure hosting with `services.Configure(...)`. Defaults are maximum 32 sessions,
+512 MiB aggregate reserved state and 1 MiB serialized configuration per session. The reservation uses configured
+history/video capacities, fixed event/diagnostic retention and bounded cache/job metadata; capacity may be
+exhausted before the session-count limit. It is an admission budget, not a managed-heap measurement. Configure
+can shrink or grow the reservation within that budget; deletion releases it. Explicit `await using` disposal is
+the lifetime boundary. There is no timer expiration or persistence.
+
+The default browser dashboard continues to inspect the default runtime. A session selector and session/step
+visualization remain part of the later dashboard work in the delivery plan.
+
+## Verification
+
+`SessionIsolationIntegrationTests`, `SessionStateIntegrationTests`, `SessionBoundaryIntegrationTests` and `SessionProviderIntegrationTests` start a
+server and exercise HTTP, MEAI and official OpenAI SDK calls. They cover parallel identical prompts, credentials,
+queue/reset/configure/dispose, admission limits, history/video/fault/cache isolation, journal retention, streaming
+and deletion during an active delayed response. Full-suite and coverage results are recorded in the delivery
+implementation ledger; this document alone is not test evidence.
diff --git a/docs/Features/ToolAndStructuredFixtures.md b/docs/Features/ToolAndStructuredFixtures.md
index b3e3a31..5632a98 100644
--- a/docs/Features/ToolAndStructuredFixtures.md
+++ b/docs/Features/ToolAndStructuredFixtures.md
@@ -1,6 +1,6 @@
# Deterministic tool and structured-output fixtures
-The runtime stores explicit tool calls and JSON responses. It does not invent tool arguments or generate JSON from a schema. The selected fixture must satisfy the request; otherwise the operation returns `409 / llm_tck_fixture_mismatch` without consuming the response. Malformed wire options return a provider-shaped 400 before runtime execution.
+The runtime stores explicit tool calls and JSON responses. It does not invent tool arguments or generate JSON from a schema. The selected fixture must satisfy the request; otherwise the operation returns `409 / llm_test_server_fixture_mismatch` without consuming the response. Malformed wire options return a provider-shaped 400 before runtime execution.
```csharp
builder.AddChatScenario("weather", scenario => scenario
@@ -8,7 +8,7 @@ builder.AddChatScenario("weather", scenario => scenario
.RespondsJson("""{"forecast":"sunny"}"""));
```
-`CallsTools(...)` configures multiple calls in one response. Each call carries its ID, function name and JSON arguments. Tool declarations and arguments flow through provider adapters into typed provider-neutral records. Assistant tool calls and tool results remain in conversation history, exact scenario matching, diagnostic retention, token accounting and prompt-cache identity. `LlmTckChatClient` maps `AIFunctionDeclaration`, tool modes, `FunctionCallContent`, `FunctionResultContent`, and `ChatResponseFormatJson`; it works with the standard `UseFunctionInvocation()` middleware.
+`CallsTools(...)` configures multiple calls in one response. Each call carries its ID, function name and JSON arguments. Tool declarations and arguments flow through provider adapters into typed provider-neutral records. Assistant tool calls and tool results remain in conversation history, exact scenario matching, diagnostic retention, token accounting and prompt-cache identity. `LlmTestServerChatClient` maps `AIFunctionDeclaration`, tool modes, `FunctionCallContent`, `FunctionResultContent`, and `ChatResponseFormatJson`; it works with the standard `UseFunctionInvocation()` middleware.
## Supported contracts
@@ -16,14 +16,14 @@ builder.AddChatScenario("weather", scenario => scenario
| --- | --- | --- | --- |
| OpenAI Chat; Azure deployment and v1 Chat; Foundry Chat; Groq, Mistral, OpenRouter, DeepSeek Chat | `tools[].function`, `tool_calls`, `tool_call_id`; auto/none/required/named choice | `response_format`: json_object or json_schema | [OpenAI Chat](https://developers.openai.com/api/reference/resources/chat/subresources/completions/methods/create/), [Azure](https://learn.microsoft.com/en-us/azure/foundry/openai/how-to/structured-outputs) |
| OpenAI, Azure v1, Foundry v1, Groq and OpenRouter Responses | flat function tools; function_call and function_call_output items | `text.format` | [OpenAI Responses](https://developers.openai.com/api/reference/resources/responses/methods/create/), [OpenRouter](https://openrouter.ai/docs/api/reference/responses/overview) |
-| Anthropic Messages | tools/input_schema; tool_use and tool_result blocks; auto/none/any/tool choice | `output_config.format.schema` | [Tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/implement-tool-use), [Structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) |
+| Anthropic Messages | tools/input_schema; tool_use and tool_result blocks; auto/none; forced any/tool choice is rejected for Sonnet 5.5 | `output_config.format.schema` | [Tool use](https://platform.claude.com/docs/en/agents-and-tools/tool-use/implement-tool-use), [Structured outputs](https://platform.claude.com/docs/en/build-with-claude/structured-outputs) |
| Gemini generateContent / streamGenerateContent | functionDeclarations, functionCall/functionResponse; functionCallingConfig | responseJsonSchema or responseSchema, application/json | [Functions](https://ai.google.dev/gemini-api/docs/function-calling), [Structured output](https://ai.google.dev/gemini-api/docs/structured-output) |
| Ollama chat | tools[].function; object-valued function arguments; tool_name results | format: json or schema object | [Chat](https://docs.ollama.com/api/chat) |
| Cohere v2 chat | tools[].function, tool_calls/tool_call_id; REQUIRED/NONE choice | response_format: json_object, optional schema | [Chat](https://docs.cohere.com/v2/reference/chat), [Tool streaming](https://docs.cohere.com/v2/docs/tool-use-streaming) |
| Bedrock Converse / ConverseStream | toolConfig, toolUse/toolResult blocks | outputConfig.textFormat.structure.jsonSchema.schema | [Converse](https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_Converse.html), [Schema](https://docs.aws.amazon.com/bedrock/latest/APIReference/API_runtime_JsonSchemaDefinition.html) |
| Perplexity Sonar | Function tools are not claimed and are rejected | response_format: json_schema | [Structured output](https://docs.perplexity.ai/docs/sonar/features) |
-Legacy Azure deployment routes accept the SDK-selected `api-version` for the documented `2024-10-21` GA and `2025-04-01-preview` contracts and reject unknown versions; Foundry inference routes require `api-version=2024-05-01-preview`; OpenAI v1 routes do not require a dated version. The operation contracts retain these constraints. Provider/model availability restrictions in the upstream services still apply; the TCK proves the listed fixture wire contracts, not every provider-hosted tool or model feature. Bedrock InvokeModel retains its existing model-specific fixture contract and rejects tool/schema options; tool support is claimed on Converse only. Legacy `functions` / `function_call` request options and server-hosted tools are explicitly rejected.
+Legacy Azure deployment routes accept the SDK-selected `api-version` for the documented `2024-10-21` GA and `2025-04-01-preview` contracts and reject unknown versions; Foundry inference routes require `api-version=2024-05-01-preview`; OpenAI v1 routes do not require a dated version. The operation contracts retain these constraints. Provider/model availability restrictions in the upstream services still apply; the Test Server proves the listed fixture wire contracts, not every provider-hosted tool or model feature. Bedrock InvokeModel retains its existing model-specific fixture contract and rejects tool/schema options; tool support is claimed on Converse only. Legacy `functions` / `function_call` request options are explicitly rejected. Server-hosted tools are limited to the qualified OpenAI Responses web-search/file-search/code-interpreter fixtures and [Anthropic native web search](AnthropicNativeWebSearch.md); other native tool declarations remain outside those contracts.
## Schema and streaming behavior
@@ -36,8 +36,8 @@ Streams carry provider-native tool events: OpenAI indexed tool-call deltas and t
- `ToolFixtureEndpointTests`: positive full conversation and schema mismatch recovery for each claimed tool operation; native streaming events; mapped tool-result history.
- `ToolFixtureClientTests`: OpenAI Chat and Responses SDK parsing, Azure SDK, Microsoft.Extensions.AI automatic function invocation in ordinary and streaming modes.
- `ToolFixtureValidationTests`: malformed wire options, tool selection mismatch, argument validation, local/external schema references and inconsistent JSON chunks.
-- `ToolFixtureStateTests`: parallel calls, mixed text/tool output, configuration snapshot isolation, exact history matching and prompt-cache identity.
-- `ProviderApiContractTests`: capabilities must be represented in the doc-backed operation matrix, and every implemented operation retains behavior evidence.
+- HTTP/SDK state flows must cover parallel calls, mixed text/tool output, configuration isolation, exact history matching and prompt-cache identity; replacement of removed internal state tests is in progress.
+- `ProviderCapabilityEvidenceTests`: operation variants execute through HTTP with success, rejection and queue recovery; operation contracts retain official documentation references.
## Request constraints and diagnostics
@@ -49,12 +49,12 @@ Every fixture mismatch produces an `ErrorReturned` runtime event with request/sc
`WithExactMatch` now compares tool-call IDs and the complete ordered tool-call collection, including null/empty values. Callers that used empty expected tool metadata as a wildcard must select Contains matching instead. Contains retains the existing optional tool metadata behavior.
-Wire tool validation lives in the corresponding provider package, returning `LlmTckRequestValidationResult`. Hosting selects a provider validator and maps invalid results to the provider's HTTP error shape. Provider-independent JSON primitives are linked from `src/Shared`; the neutral runtime has no provider DTO dependencies.
+Wire tool validation lives in the corresponding provider package, returning `LlmTestServerRequestValidationResult`. Hosting selects a provider validator and maps invalid results to the provider's HTTP error shape. Provider-independent JSON primitives are linked from `src/Shared`; the neutral runtime has no provider DTO dependencies.
`ProviderCapabilityEvidenceTests` executes a positive and negative fixture for each `(provider, operation, Tools/StructuredOutput, JSON/stream)` case supported by the checked-in contracts. Its guard also requires executable provider arguments and named nullable/limit/anyOf and parallel-option regression cases. This supplements operation-level evidence; it is not a claim of exhaustive upstream API coverage.
## Bounded video jobs
-`WithVideoCapacity(maxJobs, maxBytes)` configures a shared runtime budget across stored provider video jobs. Defaults are 256 jobs and 64 MiB of retained payload bytes. Zero jobs disables storage. New jobs exceeding either bound return 409 / `llm_tck_video_capacity_exceeded`; existing jobs remain available and failed stores do not advance IDs. Delete releases capacity; reset/configure clear jobs and byte accounting. OpenAI and Azure video job endpoints propagate the failure. This budget applies to stored jobs, separately from configured modality fixture bytes and the event-journal budget.
+`WithVideoCapacity(maxJobs, maxBytes)` configures a shared runtime budget across stored provider video jobs. Defaults are 256 jobs and 64 MiB of retained payload bytes. Zero jobs disables storage. New jobs exceeding either bound return 409 / `llm_test_server_video_capacity_exceeded`; existing jobs remain available and failed stores do not advance IDs. Delete releases capacity; reset/configure clear jobs and byte accounting. OpenAI and Azure video job endpoints propagate the failure. This budget applies to stored jobs, separately from configured modality fixture bytes and the event-journal budget.
-Schema validation uses the MIT-licensed JsonSchema.Net 8.0.5 package so installed TCK binaries do not introduce the separate binary maintenance terms from later releases. Keep fixture validation and external-reference rejection covered when changing this dependency.
+Schema validation uses the MIT-licensed JsonSchema.Net 8.0.5 package so installed Test Server binaries do not introduce the separate binary maintenance terms from later releases. Keep fixture validation and external-reference rejection covered when changing this dependency.
diff --git a/docs/Features/ToolFaultFixtures.md b/docs/Features/ToolFaultFixtures.md
new file mode 100644
index 0000000..f7b36a7
--- /dev/null
+++ b/docs/Features/ToolFaultFixtures.md
@@ -0,0 +1,59 @@
+# Tool outcomes and failures
+
+A function call and its result belong to different requests. The server returns the scripted call;
+the application invokes its function and sends a tool-result message on the next request. The
+well-known presets construct data for that flow and never execute searches, files or processes.
+
+```csharp
+var weather = LlmTestServerWellKnownTools.Weather;
+var arguments = new LlmTestServerWeatherArguments { Location = "Paris" };
+var nullFixture = weather.NullResult(arguments, "call_weather");
+// nullFixture.Result.Content is the JSON literal "null".
+var failedFixture = weather.Failure(arguments, new()
+{
+ Code = "timeout",
+ Message = "The application could not obtain the tool result in time.",
+ Retryable = true,
+}, "call_weather");
+```
+
+`CreateNullResult(callId)` creates just the correlated tool message. The explicit null factory
+bypasses the successful result schema intentionally; `CreateResult` still requires a non-null,
+schema-valid typed result. An empty list or empty string remains its own result. To simulate no
+result, omit the tool-result message entirely. Do not replace absence with an empty message or null.
+A graph can require the exact call ID and JSON root before advancing:
+
+```csharp
+config.AddConversation("weather", graph => graph
+ .Step("call", step => step.CallsTools(nullFixture.Call).Then("result"))
+ .Step("result", step => step.WhenToolResult(nullFixture.Call.Name, nullFixture.Call.Id)
+ .WhenLatestJson("$", "null").Responds("No weather data available.").Complete()));
+```
+
+A `Failure` fixture returns the explicit `{ "error": { "code", "message", "retryable" } }`
+data envelope. `IsError` labels that fixture; it does not throw, retry or set an HTTP status.
+`DelayMilliseconds` is fixture metadata and must be applied explicitly to the selected scenario
+or application invocation. The application can throw an exception, cancel a real invocation at
+its deadline, or catch a failure and send the chosen envelope. A local exception that is never
+sent back cannot appear as a server-observed tool result.
+
+Provider request failures use the existing scenario engine. `.Fails(500, code, message)` consumes
+one scripted attempt, allowing the next graph step to recover. `.DelaysBy(milliseconds)` delays
+the response before runtime commit; cancellation releases that reservation so the same call can
+be returned on retry. `SimulateContentFilter(term)` rejects matching request content, including
+tool-result text, with a provider-shaped `content_filter` error before consuming the next step.
+These failures do not warm the successful-response prompt cache. The host remains available.
+Disable SDK automatic retries when testing individual observed attempts.
+
+Native tools retain their provider-specific result contracts. Anthropic web search can return an
+empty result list or a documented search error inside a successful Messages response; these do
+not become application function calls or automatic provider errors.
+
+Mid-stream stalls, socket aborts, malformed output, missing terminal frames and output-stage
+content-filter events remain separate delivery-fault work in E6. A scripted HTTP 500 does not
+terminate the process and does not prove a real socket abort.
+
+The running-server regression suite is `WellKnownToolFaultIntegrationTests`: official OpenAI SDK
+and Extensions.AI function loops, null/empty/missing result distinction, controlled exceptions and
+cancellation, explicit recovery, provider 500, delayed response cancellation, filtered tool results,
+cache accounting, retained history and health checks.
diff --git a/docs/Features/WellKnownFunctionTools.md b/docs/Features/WellKnownFunctionTools.md
new file mode 100644
index 0000000..4aed216
--- /dev/null
+++ b/docs/Features/WellKnownFunctionTools.md
@@ -0,0 +1,110 @@
+# Well-known function-tool fixtures
+
+`ManagedCode.LlmTestServer.Tools.WellKnown` provides twelve provider-neutral, typed function-tool presets.
+They supply scripted calls and results to the existing scenario/conversation engine. They never evaluate an
+expression, read a clock, fetch a URL, access files or execute code, commands or patches. This is the function-tool
+portion of E5; provider-native built-in tools and dashboard discovery remain separate, unfinished work.
+
+## Catalogue and contracts
+
+`LlmTestServerWellKnownTools.All` is a read-only descriptor catalogue. Each descriptor exposes `Name`,
+`Description`, `ParametersJson`, `ResultSchemaJson` and `ErrorSchemaJson`. Strongly typed properties on the same
+class expose `LlmTestServerWellKnownTool`; names are constants in
+`LlmTestServerWellKnownToolNames`. Argument/result types follow `LlmTestServer{Preset}Arguments` /
+`LlmTestServer{Preset}Result`.
+
+| Preset | Function name | Scripted arguments → result |
+| --- | --- | --- |
+| Calculator | `calculator` | Expression → decimal value |
+| CurrentTime | `current_time` | Time zone → explicit `DateTimeOffset` and time zone |
+| Weather | `weather` | Location, celsius/fahrenheit → temperature and condition |
+| WebSearch | `web_search` | Query, limit → title/URL/snippet hits |
+| FetchUrl | `fetch_url` | URL → status, content type and content |
+| FileSearch | `file_search` | Query, limit → file ID/path/snippet hits |
+| ReadFile | `read_file` | Path, offset, optional length → content and truncation flag |
+| WriteFile | `write_file` | Path, content, append → bytes-written receipt |
+| ListFiles | `list_files` | Path, recursive → file/directory entries |
+| RunCode | `run_code` | Language, code → stdout, stderr and exit code |
+| Shell | `shell` | Command, optional working directory → stdout, stderr and exit code |
+| ApplyPatch | `apply_patch` | Patch text → updated-path receipt |
+
+Search limits are 1–100. Read offsets/lengths and write/file byte counts are nonnegative. Weather units are
+`celsius` or `fahrenheit`. Schemas reject unknown properties. Nullable optional fields are omitted during
+serialization. `CurrentTime` requires the caller to supply its timestamp; use the same explicit timestamp as
+your test's fixed fixture clock when that is the intended contract.
+
+`CreateCall(arguments, callId)`, `CreateResult(result, callId)` and `CreateError(error, callId)` return existing
+`LlmTestServerToolCall` / tool-role `LlmTestServerMessage` records. `Definition` returns the existing
+`LlmTestServerToolDefinition`. Arguments and result payloads are checked against their catalogue schemas.
+The default call ID is `call_` followed by the function name; supply distinct IDs for multiple simultaneous calls.
+Explicit IDs must be nonblank and at most 128 characters.
+
+## Typed fixture and tool round
+
+`Success(...)` combines a definition, call and result into a fixture. Its delay is metadata: apply it through
+`DelaysBy` when configuring the existing response or step. This example uses the typed control client already
+connected to a running server:
+
+```csharp
+using ManagedCode.LlmTestServer.Tools.WellKnown;
+
+var weather = LlmTestServerWellKnownTools.Weather.Success(
+ new() { Location = "Paris", Unit = "celsius" },
+ new() { Location = "Paris", Temperature = 21m, Unit = "celsius", Condition = "sunny" },
+ callId: "call_paris", delayMilliseconds: 20);
+
+await control.ConfigureAsync(config => config.UseConversation("weather", graph => graph
+ .Step("call", step => step.WhenLatestUserEquals("weather")
+ .CallsTools(weather.Call).DelaysBy(weather.DelayMilliseconds).Then("answer"))
+ .Step("answer", step => step.WhenToolResult(weather.Call.Name, weather.Call.Id)
+ .WithToolArgumentsJson(weather.Call.ArgumentsJson)
+ .WhenLatestJson("$", weather.Result.Content)
+ .Responds("Paris is sunny, 21 C.").Complete())));
+
+using var conversation = control.ForConversation("weather-test");
+```
+
+Offer `weather.Definition` through the provider's function-tool wire shape. For OpenAI Chat Completions, map
+`Name`, `Description` and parsed `ParametersJson` to `tools[].function`. Send the initial user message, retain the
+returned assistant/tool call, and append a provider tool-result message with `tool_call_id = weather.Result.ToolCallId`
+and `content = weather.Result.Content`. Use `conversation.HttpClient` for those requests or as the transport of a
+real provider SDK. Normalized core records require the provider adapter's field names; they are not OpenAI wire DTOs.
+The HTTP tests linked below show the complete request/response round.
+
+Arguments/results match structurally as JSON. A changed argument or result rejects the next graph step without
+consuming it. Linear queues retain their normal exhaustion behavior; graphs retain their configured
+`Reject`, `RepeatLastResponse`, `Restart`, step limits and cancellation semantics. Presets introduce no additional
+cursor, repeat policy or executor. Existing `VerifyAsync` tool expectations inspect names, call IDs, argument JSON
+and result JSON; see [request verification](RequestVerificationAndDeterminism.md).
+
+## Explicit result shapes
+
+Success results retain their typed root. A calculator success is `{"value":42}`, and a weather success is
+`{"location":"Paris","temperature":21,"unit":"celsius","condition":"sunny"}`. There is no implicit success envelope.
+
+`Failure(arguments, error, callId, delayMilliseconds)` explicitly selects a tool error fixture:
+
+```csharp
+var unavailable = LlmTestServerWellKnownTools.Weather.Failure(
+ new() { Location = "Paris" },
+ new() { Code = "fixture_unavailable", Message = "Scripted weather failure", Retryable = true });
+```
+
+Its result content is `{"error":{"code":"fixture_unavailable","message":"Scripted weather failure","retryable":true}}`.
+This is the documented `LlmTestServerToolFixtureErrorResult` envelope, described by `ErrorSchemaJson`.
+It is tool-result content, not a provider HTTP error or automatic retry instruction. Configure the next graph step
+and the application's handling explicitly. `IsError` identifies the selected fixture kind.
+
+## Server evidence
+
+The combined server suite passed **852/852** with **91.79%** production line coverage; Release build passed
+with zero warnings/errors and all 19 packages packed. The preset-focused HTTP cases passed **40/40**.
+Evidence: `artifacts/delivery/presets-coverage.log`. A clean installed NuGet/Aspire/official SDK/Chromium consumer passed 1/1, including the typed Calculator tool round (`artifacts/delivery/presets-consumer.log`);
+these results do not establish public-feed publication or completion of the remaining E5 work.
+
+- [WellKnownToolIntegrationTests](../../tests/ManagedCode.LlmTestServer.Tests/Tools/WellKnownToolIntegrationTests.cs): all twelve presets, success/error tool rounds, offered input schemas, typed output schemas and request verification.
+- [WellKnownToolBoundaryTests](../../tests/ManagedCode.LlmTestServer.Tests/Tools/WellKnownToolBoundaryTests.cs): catalogue-driven HTTP calls, linear exhaustion, incompatible schemas without consumption, exact argument/result matching.
+- [WellKnownToolLifecycleTests](../../tests/ManagedCode.LlmTestServer.Tests/Tools/WellKnownToolLifecycleTests.cs): existing repeat policy, stable call identity, optional delay and cancellation without consumption.
+
+These tests start the server and use real HTTP. The current preset qualification uses OpenAI function-tool wire
+requests; it does not establish support for provider-native search, file-search or code-execution built-ins.
diff --git a/docs/Reference/Clients.md b/docs/Reference/Clients.md
new file mode 100644
index 0000000..a7e8a0e
--- /dev/null
+++ b/docs/Reference/Clients.md
@@ -0,0 +1,249 @@
+# Clients and SDKs
+
+Calling LLM Test Server from tests: the control client, official provider SDKs, `Microsoft.Extensions.AI`, and the native TypeSafe client. Back to the [README](../../README.md).
+
+## First passing test
+
+In a .NET 10 TUnit test project, add `ManagedCode.LlmTestServer.Aspire`, `ManagedCode.LlmTestServer.Client`
+and `Aspire.Hosting.Testing`. This starts the packaged server without Docker, configures a response, calls it
+through `IChatClient` and verifies the recorded request:
+
+```csharp
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using Microsoft.Extensions.AI;
+
+public sealed class AiIntegrationTests
+{
+ [Test]
+ public async Task ApplicationReceivesScriptedResponse(CancellationToken cancellationToken)
+ {
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer("llm-test-server").WithApiKey("test-key");
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync("llm-test-server", cancellationToken);
+
+ using var http = app.CreateHttpClient("llm-test-server", "http");
+ var control = new LlmTestServerClient(http, "test-key");
+ await control.ConfigureAsync(config => config.RequireBearerToken("test-key").UseGpt41Mini()
+ .UseChatScenario("greeting", scenario => scenario.WhenUserContains("hello").Responds("Hello from your test!")),
+ cancellationToken);
+ using var chat = control.CreateChatClient();
+ var response = await chat.GetResponseAsync([new ChatMessage(ChatRole.User, "hello")],
+ cancellationToken: cancellationToken);
+
+ await Assert.That(response.Text).IsEqualTo("Hello from your test!");
+ await Assert.That((await control.GetAssertionsAsync(cancellationToken)).Matched).IsEqualTo(1);
+ }
+}
+```
+
+See [provider operation coverage](../Features/ProviderApiContractCoverage.md) for the exact supported contracts.
+
+## Parallel tests on a shared server
+
+Create a separate session for each test. Each one owns its configuration, response queues, history, prompt cache,
+fault counters, video jobs and request journal. Disposal removes its server state; the shared transport stays usable.
+
+```csharp
+await using var session = await control.CreateSessionAsync(config => config
+ .RequireBearerToken("test-key")
+ .UseChatScenario("isolated", scenario => scenario.Responds("This test's response")));
+using var chat = session.Control.CreateChatClient();
+var response = await chat.GetResponseAsync([new ChatMessage(ChatRole.User, "hello")]);
+```
+
+Use `session.HttpClient` as the transport for official provider SDKs. See [test sessions](../Features/TestSessions.md)
+for credentials, capacity limits, configure/reset semantics and HTTP routes.
+
+## TypeSafe: Jev through System One
+
+**TypeSafe is the provider, Jev is its model family, and System One is the native API/protocol.**
+`ManagedCode.LlmTestServer.SystemOne` contains the native DTOs; `ManagedCode.LlmTestServer.Client`
+provides `LlmTestServerSystemOneClient`. The package name remains `SystemOne` because it also hosts the Kev profile.
+
+Jev is supported through its native System One API, including Jev 1.14 image assets
+and bounding boxes. The emulator accepts JSON base64 and multipart PNG/JPEG uploads,
+structured instructions and criteria, mixed `noul`/`choice`/`score`/`box` batches,
+native confidence, usage and provider-resolved model versions. Image and box requests
+require `TypeSafe-Danger-Zone-Images: true`; long-context requests can explicitly send
+`TypeSafe-Danger-Zone-Long-Context: true`. It uses deterministic fixtures and never
+calls a production model or estimates image tokens.
+
+- Native test-server route: `POST /systemone/v1/systemone`.
+- Contracts: `ManagedCode.LlmTestServer.SystemOne`.
+- Typed client: `LlmTestServerClient.CreateSystemOneClient()` from `ManagedCode.LlmTestServer.Client`.
+- Register `jev-1.14.0` or `jev-preview` with `AddDecisionModel(id, LlmTestServerDecisionProvider.TypeSafe)`.
+- [Jev 1.14 guide and limits](../Features/Jev114.md), [native decision fixtures](ProvidersAndRoutes.md#native-decision-api-fixtures),
+ [official images API](https://docs.typesafe.ai/images).
+
+Using the `control` client and Aspire-allocated HTTP transport from the first test above, configure a TypeSafe
+fixture and call the native typed client:
+
+```csharp
+using System.Text.Json;
+using ManagedCode.LlmTestServer.Decisions;
+using ManagedCode.LlmTestServer.SystemOne;
+
+await control.ConfigureAsync(config => config
+ .RequireBearerToken("test-key")
+ .UseDecisionModel(TypeSafeRequestValidation.Jev114Model, LlmTestServerDecisionProvider.TypeSafe)
+ .UseDecisionScenario(new LlmTestServerDecisionScenario
+ {
+ Id = "typesafe-priority",
+ ModelId = TypeSafeRequestValidation.Jev114Model,
+ Answers = new()
+ {
+ ["urgent"] = new() { Kind = LlmTestServerDecisionKind.Predicate, Probability = 0.95 },
+ },
+ }));
+
+var jev = control.CreateSystemOneClient();
+var decision = await jev.EvaluateAsync(new SystemOneDecisionRequest
+{
+ Model = TypeSafeRequestValidation.Jev114Model,
+ State = JsonSerializer.SerializeToElement("Please help quickly"),
+ Questions = new()
+ {
+ ["urgent"] = new()
+ {
+ Type = SystemOneDecisionTypes.Predicate,
+ Instructions = JsonSerializer.SerializeToElement("Does this need urgent attention?"),
+ },
+ },
+});
+Console.WriteLine(decision.Answers["urgent"].Probability); // 0.95
+```
+
+The client sends `POST /systemone/v1/systemone` using the control client's transport and configured test key.
+For image/box fixtures, use `EvaluateAsync(..., enableImages: true)` or `EvaluateMultipartAsync(...)`;
+see the [Jev 1.14 guide](../Features/Jev114.md) for explicit assets and native limits.
+
+## OpenAI SDK
+
+The official OpenAI .NET SDK expects its `Endpoint` to be the API root. Use
+`/openai/v1` for this Test Server, or `llmTestServer.GetOpenAiEndpoint()` from the Aspire
+package when wiring an AppHost resource.
+
+```csharp
+using OpenAI;
+using OpenAI.Chat;
+using System.ClientModel;
+
+var chat = new ChatClient(
+ "gpt-4.1-mini",
+ new ApiKeyCredential("test-key"),
+ new OpenAIClientOptions
+ {
+ Endpoint = new Uri("http://localhost:5000/openai/v1"),
+ });
+
+await foreach (var update in chat.CompleteChatStreamingAsync(
+ [new UserChatMessage("What is the invoice total?")]))
+{
+ Console.Write(update.ContentUpdate.Count > 0 ? update.ContentUpdate[0].Text : string.Empty);
+}
+```
+
+## Azure OpenAI And Foundry SDKs
+
+The OpenAI v1 API is available at `/azure-openai/openai/v1/` and `/microsoft-foundry/openai/v1/`, with `chat/completions`, `responses` and `embeddings`. Point the official OpenAI client endpoint at the corresponding base URL and supply the configured API key. These v1 routes accept bearer or `api-key` authentication and need no dated `api-version` query parameter. Responses supports ordinary JSON and documented SSE events. See the [September 2026 API review](../Features/ProviderApiReview20260907.md) for the verified SDK versions and provider contracts.
+
+Azure OpenAI deployment routes use the deployment name as the Test Server model id. API keys sent through the official SDK's `api-key` header are accepted anywhere a bearer token would be accepted.
+
+```csharp
+using Azure.AI.OpenAI;
+using OpenAI.Chat;
+using OpenAI.Embeddings;
+using System.ClientModel;
+
+var azure = new AzureOpenAIClient(
+ new Uri("http://localhost:5000/azure-openai/"),
+ new ApiKeyCredential("test-key"));
+
+ChatClient chat = azure.GetChatClient("gpt-4.1-mini");
+EmbeddingClient embeddings = azure.GetEmbeddingClient("text-embedding-3-small");
+
+var answer = await chat.CompleteChatAsync(
+[
+ new UserChatMessage("What is the invoice total?"),
+]);
+
+var vector = await embeddings.GenerateEmbeddingAsync("invoice");
+```
+
+Microsoft Foundry / Azure AI Inference clients call the `/microsoft-foundry/chat/completions` and `/microsoft-foundry/embeddings` routes. The inference routes require `api-version=2024-05-01-preview`, which the official SDK supplies. Set `Model` to the model id configured in LLM Test Server.
+
+```csharp
+using Azure;
+using Azure.AI.Inference;
+
+var endpoint = new Uri("http://localhost:5000/microsoft-foundry/");
+var credential = new AzureKeyCredential("test-key");
+
+var chat = new ChatCompletionsClient(endpoint, credential);
+var embeddings = new EmbeddingsClient(endpoint, credential);
+
+var completion = await chat.CompleteAsync(
+ new ChatCompletionsOptions(
+ [
+ new ChatRequestUserMessage("What is the invoice total?"),
+ ])
+ {
+ Model = "gpt-4.1-mini",
+ });
+
+var embedding = await embeddings.EmbedAsync(
+ new EmbeddingsOptions(["invoice"])
+ {
+ Model = "text-embedding-3-small",
+ });
+```
+
+## Microsoft.Extensions.AI
+
+Use the client package when you want tests to call the fake provider through normal `Microsoft.Extensions.AI` abstractions:
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using Microsoft.Extensions.AI;
+
+using var httpClient = new HttpClient
+{
+ BaseAddress = new Uri("http://localhost:5000"),
+};
+httpClient.DefaultRequestHeaders.Authorization =
+ new System.Net.Http.Headers.AuthenticationHeaderValue("Bearer", "test-key");
+
+using IChatClient chatClient = new LlmTestServerChatClient(httpClient);
+
+var response = await chatClient.GetResponseAsync(
+[
+ new ChatMessage(ChatRole.User, "What color is the largest animal?"),
+]);
+
+Console.WriteLine(response.Text);
+```
+
+When a bearer token is required, prefer creating the modality clients from the control client so the same token is applied consistently:
+
+```csharp
+var server = LlmTestServerClient.Create(httpClient, bearerToken: "test-key");
+
+using IChatClient chatClient = server.CreateChatClient("docs-chat");
+using IEmbeddingGenerator> embeddings =
+ server.CreateEmbeddingGenerator("docs-embedding");
+using IImageGenerator images = server.CreateImageGenerator("docs-image");
+```
+
+Streaming uses the same client:
+
+```csharp
+await foreach (var update in chatClient.GetStreamingResponseAsync(
+ [new ChatMessage(ChatRole.User, "stream this")]))
+{
+ Console.Write(update.Text);
+}
+```
diff --git a/docs/Reference/Configuration.md b/docs/Reference/Configuration.md
new file mode 100644
index 0000000..decacf9
--- /dev/null
+++ b/docs/Reference/Configuration.md
@@ -0,0 +1,446 @@
+# Configuration and scenarios
+
+Models, chat scenarios, modalities, fault simulation, runtime reconfiguration and assertions. Back to the [README](../../README.md).
+
+## Configuration Model
+
+LLM Test Server is configured with one `LlmTestServerConfiguration`.
+
+You can apply that configuration in two places:
+
+- at host startup through `builder.Services.AddLlmTestServer(options => ...)`
+- at test runtime through `LlmTestServerClient.ConfigureAsync(...)` or `POST /admin-api/configure`
+
+Runtime configuration is a replacement, not a merge. Applying a new configuration resets scenario positions and assertion events. The runtime snapshots the configuration, so later mutations to your builder/list objects do not change the running provider.
+
+The default configuration advertises official OpenAI fixture model IDs:
+
+| Model ID | Kind |
+| --- | --- |
+| `gpt-4.1-mini` | Chat |
+| `text-embedding-3-small` | Embedding |
+| `gpt-image-1` | Image |
+| `gpt-4o-mini-tts` | Audio |
+| `sora-2` | Video |
+
+Model IDs and model kinds are enforced. A chat request to an embedding model, or an embedding request to an unknown model, returns `404` with `llm_test_server_unknown_model`.
+
+Use typed helpers for broader OpenAI model registration when tests need more than the defaults:
+
+```csharp
+options.AddKnownOpenAiModels(reasoningTokens: 128);
+
+// Or register only one modality family.
+options.AddCurrentOpenAiChatModels(reasoningTokens: 128);
+options.AddOpenAiEmbeddingModels();
+options.AddOpenAiImageModels();
+options.AddOpenAiAudioModels();
+options.AddOpenAiVideoModels();
+```
+
+Individual helpers are also available, including `AddGpt55(...)`, `AddGpt54Mini(...)`, `AddGpt5Nano(...)`, `AddGpt41()`, `AddGpt4OMini()`, `AddTextEmbedding3Large()`, `AddGptImage2()`, `AddGptImage15()`, `AddGptImage1Mini()`, `AddTts1()`, `AddTts1Hd()`, and `AddSora2Pro()`. Keep using `AddModel(...)` for custom deployment names or provider-specific IDs.
+
+### Fault Simulation
+
+Fault simulation is configured on the provider-neutral runtime and applies through every provider namespace. Use it when a test needs retry, moderation, or provider-error handling without scripting each provider route separately.
+
+```csharp
+builder.Services.AddLlmTestServer(options =>
+{
+ // Allow two accepted runtime requests, then return 429 too_many_requests.
+ options.SimulateRateLimitAfter(2);
+
+ // Return 400 content_filter whenever a request text contains either term.
+ options.SimulateContentFilter("blocked phrase", "unsafe fixture");
+});
+```
+
+`SimulateRateLimitAfter(0)` makes the first valid runtime request return `429` with `too_many_requests`. `SimulateContentFilter(...)` checks chat messages, embedding inputs, image prompts, audio speech input, audio transcription/translation prompts, and video prompts. `ConfigureAsync(...)` and `ResetAsync()` both reset the rate-limit counter so tests stay deterministic.
+
+## Chat Scenarios
+
+### Contains Match
+
+`WhenUserContains(...)` adds a user-message contains matcher. All configured match messages must be present somewhere in the actual request.
+
+```csharp
+options.AddChatScenario(
+ "support-refund",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("refund")
+ .Responds("I can help with a refund."));
+```
+
+### Exact Match
+
+Use exact matching when a test must prove the complete prompt contract:
+
+```csharp
+using ManagedCode.LlmTestServer.Scenarios;
+
+options.AddChatScenario(
+ "exact-system-contract",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WithExactMatch(
+ new LlmTestServerMessage { Role = "system", Content = "Return JSON only." },
+ new LlmTestServerMessage { Role = "user", Content = "Give me the invoice total." })
+ .Responds("{\"total\":42.50}"));
+```
+
+### Queued Responses
+
+Each matched request consumes the next response. This makes multi-turn flows deterministic:
+
+```csharp
+options.AddChatScenario(
+ "two-turn-plan",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("make a plan")
+ .Responds("First draft")
+ .Responds("Revised draft"));
+```
+
+After the queue is exhausted, the provider returns `409` with `llm_test_server_scenario_exhausted`.
+
+### Streaming Chunks
+
+The first `Responds` argument is the non-streaming response. The remaining arguments are the streaming chunks:
+
+```csharp
+options.AddChatScenario(
+ "streaming-answer",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("stream this")
+ .Responds("blue whale", "blue ", "whale"));
+```
+
+For `stream: true`, LLM Test Server emits SSE `data:` frames and a final `data: [DONE]` marker. All chunks in one response share the same response id.
+
+### Scripted Errors
+
+Use `Fails(...)` to test client error handling without waiting for a real provider to fail:
+
+```csharp
+options.AddChatScenario(
+ "content-policy-error",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("blocked fixture")
+ .Fails(400, "content_filter", "The scripted request was rejected."));
+```
+
+### Delays And Cancellation
+
+Use `DelaysBy(...)` to test timeout and cancellation behavior:
+
+```csharp
+options.AddChatScenario(
+ "timeout-path",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("slow path")
+ .Responds("eventual answer")
+ .DelaysBy(1_500));
+```
+
+If the caller cancels during the delay, the queued response is not consumed.
+
+### Scenario-Specific Token
+
+A scenario can require its own bearer token:
+
+```csharp
+options.AddChatScenario(
+ "tenant-a-only",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .RequireBearerToken("tenant-a-key")
+ .WhenUserContains("tenant secret")
+ .Responds("tenant-a response"));
+```
+
+Use either a global token or per-scenario tokens. If both are configured for a scenario, the same request must satisfy both checks, so different global and scenario tokens intentionally make that scenario unreachable.
+
+## Modalities
+
+### Embeddings
+
+Configure a fixed embedding vector. Every input value receives the same deterministic vector:
+
+```csharp
+options.AddTextEmbedding3Small();
+options.WithDefaultEmbeddingVector(0.01f, 0.02f, 0.03f, 0.04f);
+```
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using Microsoft.Extensions.AI;
+
+using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
+using IEmbeddingGenerator> embeddings =
+ new LlmTestServerEmbeddingGenerator(httpClient, "text-embedding-3-small");
+
+var result = await embeddings.GenerateAsync(["alpha", "beta"]);
+```
+
+### Images
+
+Image generation returns a deterministic base64 PNG by default:
+
+```csharp
+options.AddGptImage1();
+```
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using Microsoft.Extensions.AI;
+
+using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
+using IImageGenerator images = new LlmTestServerImageGenerator(httpClient, "gpt-image-1");
+
+var image = await images.GenerateAsync(
+ new ImageGenerationRequest { Prompt = "compatibility marker" });
+```
+
+### Audio
+
+Audio speech returns deterministic bytes with a matching media type. The default fixture is a minimal WAV payload:
+
+```csharp
+options.AddGpt4OMiniTts();
+options.WithDefaultAudio(File.ReadAllBytes("fixtures/speech.wav"), "audio/wav");
+```
+
+```csharp
+var audio = await httpClient.PostAsJsonAsync(
+ "/openai/v1/audio/speech",
+ new { model = "gpt-4o-mini-tts", input = "hello", voice = "alloy" });
+
+audio.EnsureSuccessStatusCode();
+var bytes = await audio.Content.ReadAsByteArrayAsync();
+```
+
+## Runtime Reconfiguration
+
+Use runtime reconfiguration when each test needs a different provider script.
+
+### Configure Before A Test
+
+Use `ManagedCode.LlmTestServer.Client` as the universal test control surface. A test can start or discover the hosted Test Server, create one `LlmTestServerClient`, load all required models, datasets, scripted responses, errors, embeddings, images, and audio fixtures, and then call the provider through regular clients.
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using Microsoft.Extensions.AI;
+
+using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
+var server = LlmTestServerClient.Create(httpClient, bearerToken: "test-key");
+
+await server.ConfigureAsync(
+ config => config
+ .RequireBearerToken("test-key")
+ .UseChatModel("test-chat")
+ .UseEmbeddingModel("test-embedding")
+ .UseImageModel("test-image")
+ .UseAudioModel("test-audio")
+ .UseEmbeddingVector(0.9f, 0.8f)
+ .UseImageDataUri("data:image/png;base64,Zm9v")
+ .UseAudio([1, 2, 3, 4], "audio/test")
+ .UseDataset(
+ "checkout-flow",
+ dataset => dataset
+ .AddChatScenario(
+ "invoice-total",
+ scenario => scenario
+ .ForModel("test-chat")
+ .WhenUserContains("invoice total")
+ .Responds("{\"total\":42.50}", "{\"total\":", "42.50", "}"))
+ .AddChatScenario(
+ "provider-rate-limit",
+ scenario => scenario
+ .ForModel("test-chat")
+ .WhenUserContains("rate limit")
+ .Fails(429, "rate_limit_exceeded", "Scripted rate limit."))),
+ resetFirst: true);
+
+using IChatClient chat = server.CreateChatClient("test-chat");
+using IEmbeddingGenerator> embeddings =
+ server.CreateEmbeddingGenerator("test-embedding");
+using IImageGenerator images = server.CreateImageGenerator("test-image");
+
+var response = await chat.GetResponseAsync(
+[
+ new ChatMessage(ChatRole.User, "What is the invoice total?"),
+]);
+
+var vector = await embeddings.GenerateAsync(["invoice"]);
+var image = await images.GenerateAsync(new ImageGenerationRequest { Prompt = "fixture" });
+var audio = await server.GenerateAudioAsync("test-audio", "speak this");
+var assertions = await server.GetAssertionsAsync();
+```
+
+`resetFirst: true` clears previous assertion events and scenario positions before the new configuration is applied. Named datasets are active after configuration; they group scenarios so a test can load a whole conversation set without flattening everything by hand.
+
+### Configure With `LlmTestServerClient`
+
+```csharp
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Configuration;
+using ManagedCode.LlmTestServer.Models;
+
+using var httpClient = new HttpClient { BaseAddress = new Uri("http://localhost:5000") };
+httpClient.DefaultRequestHeaders.Authorization =
+ new System.Net.Http.Headers.AuthenticationHeaderValue("Bearer", "test-key");
+
+var control = new LlmTestServerClient(httpClient);
+
+var configuration = new LlmTestServerConfigurationBuilder()
+ .RequireBearerToken("test-key")
+ .AddModel("docs-chat", LlmTestServerModelKind.Chat)
+ .AddModel("docs-embedding", LlmTestServerModelKind.Embedding)
+ .AddChatScenario(
+ "docs-blue-whale",
+ scenario => scenario
+ .ForModel("docs-chat")
+ .WhenUserContains("largest animal")
+ .Responds("blue whale", "blue ", "whale"))
+ .WithDefaultEmbeddingVector(0.125f, 0.25f)
+ .Build();
+
+await control.ConfigureAsync(configuration);
+```
+
+If the current runtime already has a bearer token, the configure request must use that current token. If the new configuration sets a different token, future provider and control requests must use the new token.
+
+### Configure With Raw JSON
+
+`POST /admin-api/configure` accepts readable enum values such as `"chat"` and `"contains"`:
+
+```bash
+curl -X POST http://localhost:5000/admin-api/configure \
+ -H "content-type: application/json" \
+ -H "authorization: Bearer test-key" \
+ -d '{
+ "requiredBearerToken": "test-key",
+ "models": [
+ { "id": "docs-chat", "kind": "chat" },
+ { "id": "docs-embedding", "kind": "embedding" },
+ { "id": "docs-image", "kind": "image" },
+ { "id": "docs-audio", "kind": "audio" }
+ ],
+ "chatScenarios": [
+ {
+ "id": "docs-blue-whale",
+ "modelId": "docs-chat",
+ "match": {
+ "mode": "contains",
+ "messages": [
+ { "role": "user", "content": "largest animal" }
+ ]
+ },
+ "responses": [
+ {
+ "content": "blue whale",
+ "streamChunks": [ "blue ", "whale" ]
+ }
+ ]
+ }
+ ],
+ "defaultEmbeddingVector": [ 0.125, 0.25 ],
+ "defaultAudioMediaType": "audio/wav"
+ }'
+```
+
+Then call the configured model:
+
+```bash
+curl -X POST http://localhost:5000/openai/v1/chat/completions \
+ -H "content-type: application/json" \
+ -H "authorization: Bearer test-key" \
+ -d '{
+ "model": "docs-chat",
+ "messages": [
+ { "role": "user", "content": "What is the largest animal?" }
+ ]
+ }'
+```
+
+## Assertions And Reset
+
+The assertion summary is intentionally simple: it tells the test whether requests matched configured scenarios, missed, failed auth, used unknown models, exhausted a response queue, or returned scripted errors.
+
+```csharp
+var control = new LlmTestServerClient(httpClient);
+var assertions = await control.GetAssertionsAsync();
+
+if (assertions.Unmatched > 0 || assertions.ModelNotFound > 0)
+{
+ throw new InvalidOperationException("The application called an unexpected LLM path.");
+}
+```
+
+Reset clears assertion events and scenario response positions without replacing the current configuration:
+
+```csharp
+await control.ResetAsync();
+```
+
+## Common Test Shapes
+
+### Replace Provider Calls In Integration Tests
+
+1. Start the LLM Test Server service in Aspire or an ASP.NET Core test host.
+2. Configure the expected scenarios for the test.
+3. Point the application under test at the LLM Test Server base URL.
+4. Run the application flow.
+5. Assert `GetAssertionsAsync()` has no unmatched, unknown-model, auth-failed, or exhausted events.
+
+### Test Retry Logic
+
+```csharp
+options.AddChatScenario(
+ "retry-then-success",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("retry")
+ .Fails(429, "rate_limit_exceeded", "Try again.")
+ .Responds("success after retry"));
+```
+
+### Test Prompt Contract Drift
+
+```csharp
+options.AddChatScenario(
+ "exact-contract",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WithExactMatch(
+ new LlmTestServerMessage { Role = "system", Content = "Return JSON only." },
+ new LlmTestServerMessage { Role = "user", Content = "Summarize invoice INV-42." })
+ .Responds("{\"summary\":\"paid\"}"));
+```
+
+If the application changes the prompt, the request becomes unmatched and the test can fail on the assertion summary.
+
+### Test Wrong Model Wiring
+
+Configure only the models your application is allowed to call:
+
+```csharp
+options.AddModel("approved-chat-model", LlmTestServerModelKind.Chat);
+```
+
+If the app calls `old-chat-model` or calls `approved-chat-model` through the embeddings endpoint, LLM Test Server returns `llm_test_server_unknown_model`.
+
+## Compatibility boundaries
+
+Tool calls and structured output use explicit deterministic fixtures: `CallsTool(...)`, `CallsTools(...)` and `RespondsJson(...)`. Provider adapters preserve tool history and streaming events; `LlmTestServerChatClient` supports the standard Microsoft.Extensions.AI function-invocation loop. Fixtures must satisfy tool selection, argument schemas and response schemas; mismatches return 409 without consuming the response. See [supported contracts and tests](../Features/ToolAndStructuredFixtures.md).
+
+Video create operations retain completed fixture jobs. Retrieve/content/delete require a previously created ID, and reset or reconfiguration clears jobs. OpenAI fixtures return `status=completed` and `progress=100`; IDs remain unique within a run. Dataset-local scenario IDs are isolated, including concurrent cancellation rollback.
+
+Prompt-cache storage is bounded to 4096 prefixes by default. Use `WithPromptCacheCapacity(capacity)` to change the limit; zero disables caching. Eviction is deterministic FIFO, and reset/configure clears the cache.
+
+Legacy Azure deployment APIs accept the dated `api-version` selected automatically by the Azure SDK. Use the default `AzureOpenAIClientOptions` constructor, or omit options entirely; do not pin a version for the emulator. These routes require exactly one supported deployment API version: the documented `2024-10-21` GA or `2025-04-01-preview` contract. Missing, malformed, duplicate, and unknown versions are rejected, including valid-looking future dates. Azure/Foundry `/openai/v1` endpoints require no dated query parameter.
diff --git a/docs/Reference/Installation.md b/docs/Reference/Installation.md
new file mode 100644
index 0000000..8be9ee9
--- /dev/null
+++ b/docs/Reference/Installation.md
@@ -0,0 +1,179 @@
+# Installation and hosting
+
+How to install the packages, run the standalone container, embed the server in ASP.NET Core or Aspire, and build from source. Back to the [README](../../README.md).
+
+## Choose how to run
+
+| Setup | Install / start | Best fit |
+| --- | --- | --- |
+| **.NET + Aspire** | `ManagedCode.LlmTestServer.Aspire` + `ManagedCode.LlmTestServer.Client` | Start an isolated .NET server from your AppHost or integration test; Docker is optional. |
+| **Standalone Docker** | `managedcode/llm-test-server:local`, built with the .NET SDK | Run the dashboard, management API and provider routes together for applications in any language. |
+| **ASP.NET Core library** | `ManagedCode.LlmTestServer.Hosting` | Embed the server in your own host with `AddLlmTestServer(...)` and `MapLlmTestServer()`. |
+
+**v1.0.0 publication is pending.** NuGet links below identify the intended packages; they do not establish
+public availability. Build and [pack the source](#build-and-test) to use the local `artifacts/packages` feed now.
+The current source package version is `0.1.18` from `Directory.Build.props`. Run these in your consumer
+project, replacing the feed path with your checkout (use the canonical version if it changes):
+
+```sh
+dotnet add package ManagedCode.LlmTestServer.Aspire --version 0.1.18 --no-restore
+dotnet add package ManagedCode.LlmTestServer.Client --version 0.1.18 --no-restore
+dotnet restore --source /absolute/path/to/LlmTestServer/artifacts/packages \
+ --source https://api.nuget.org/v3/index.json
+```
+
+For an existing ASP.NET Core application, install `ManagedCode.LlmTestServer.Hosting` from the same feed
+and follow [ASP.NET Core startup](#aspnet-core-startup). The core package owns scenarios and model configuration;
+provider packages own their wire contracts, and the client package owns management and typed client APIs.
+
+### Standalone container and management API
+
+Build a local image from the checkout with the .NET SDK's `PublishContainer` target, then run it with Docker:
+
+```sh
+dotnet publish samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj \
+ --configuration Release --runtime linux-arm64 --self-contained false \
+ /t:PublishContainer -p:ContainerRuntimeIdentifiers=linux-arm64 \
+ -p:ContainerImageTag=local -p:UseAppHost=false
+docker run --rm --name llm-test-server -p 8080:8080 \
+ -e LlmTestServer__RequiredBearerToken=local-test-key \
+ managedcode/llm-test-server:local
+```
+
+Use `linux-x64` in both RID arguments on an amd64 machine. Open **http://localhost:8080/** for the dashboard.
+The host port is explicitly mapped to container port 8080. Configure a model and response through the running
+server, keeping the same test API key in the replacement configuration:
+
+```sh
+curl --fail-with-body http://localhost:8080/admin-api/configure \
+ -H 'Authorization: Bearer local-test-key' -H 'Content-Type: application/json' \
+ --data '{"requiredBearerToken":"local-test-key","models":[{"id":"gpt-4.1-mini","kind":"chat"}],"chatScenarios":[{"id":"hello","modelId":"gpt-4.1-mini","responses":[{"content":"Hello from your fixture"}]}]}'
+
+curl --fail-with-body http://localhost:8080/openai/v1/chat/completions \
+ -H 'Authorization: Bearer local-test-key' -H 'Content-Type: application/json' \
+ --data '{"model":"gpt-4.1-mini","messages":[{"role":"user","content":"Hello"}]}'
+```
+
+The API key is a local fixture credential; production provider credentials are unnecessary. Provider routes
+and `/admin-api/*` use it. The intended public release image is
+`ghcr.io/managedcode/llm-test-server:1.0.0`; public pulling remains pending release and anonymous-pull verification.
+See [Docker distribution](../Features/DockerDistribution.md) for both architectures, authentication,
+health checks and release requirements.
+
+## ASP.NET Core Startup
+
+The simplest host config is one chat scenario:
+
+```csharp
+using ManagedCode.LlmTestServer.Hosting;
+using ManagedCode.LlmTestServer.Models;
+
+var builder = WebApplication.CreateBuilder(args);
+
+builder.Services.AddLlmTestServer(options =>
+{
+ options.AddChatScenario(
+ "blue-whale",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("largest animal")
+ .Responds("blue whale", "blue ", "whale"));
+});
+
+var app = builder.Build();
+app.MapLlmTestServer();
+app.Run();
+```
+
+A fuller config can advertise your application's real model names while still serving deterministic fixtures:
+
+```csharp
+using ManagedCode.LlmTestServer.Hosting;
+using ManagedCode.LlmTestServer.Models;
+
+var builder = WebApplication.CreateBuilder(args);
+
+builder.Services.AddLlmTestServer(options =>
+{
+ options.RequireBearerToken("test-key");
+
+ options.AddDefaultOpenAiModels();
+
+ options.WithDefaultEmbeddingVector(0.125f, 0.25f, 0.5f, 1.0f);
+ options.WithDefaultAudio(File.ReadAllBytes("fixtures/ok.wav"), "audio/wav");
+
+ options.AddChatScenario(
+ "invoice-total",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("invoice total")
+ .Responds(
+ "{\"total\":42.50}",
+ "{\"total\":",
+ "42.50",
+ "}"));
+
+ options.AddChatScenario(
+ "provider-rate-limit",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("rate limit")
+ .Fails(429, "rate_limit_exceeded", "Scripted rate limit from LLM Test Server."));
+
+ options.AddChatScenario(
+ "slow-response",
+ scenario => scenario
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
+ .WhenUserContains("slow")
+ .Responds("done")
+ .DelaysBy(250));
+});
+
+var app = builder.Build();
+app.MapLlmTestServer();
+app.Run();
+```
+
+## Aspire AppHost
+
+Install `ManagedCode.LlmTestServer.Aspire` in the AppHost using the versioned
+[local-feed installation commands](#choose-how-to-run) above while public publication is pending.
+
+Then add the package-owned Test Server resource directly:
+
+```csharp
+using ManagedCode.LlmTestServer.Aspire;
+
+var builder = DistributedApplication.CreateBuilder(args);
+
+var llmTestServer = builder
+ .AddLlmTestServer()
+ .WithApiKey("test-key");
+
+builder
+ .AddProject("consumer")
+ .WithReference(llmTestServer)
+ .WithEnvironment("LLM_PROVIDER_ENDPOINT", llmTestServer.GetHttpEndpoint())
+ .WithEnvironment("OPENAI_ENDPOINT", llmTestServer.GetOpenAiEndpoint())
+ .WithEnvironment("OPENAI_API_KEY", "test-key")
+ .WaitFor(llmTestServer);
+
+builder.Build().Run();
+```
+
+`AddLlmTestServer()` creates a `LlmTestServerResource` backed by the packaged .NET LLM Test Server service executable and exposes its `http` endpoint. It does not require a consumer service project reference, generated `Projects.*` metadata type, project path, Docker, or a container runtime. Consumer resources should reference the Test Server resource, wait for it, and use `llmTestServer.GetHttpEndpoint()` when they need the provider-compatible base URL. `.WithApiKey("test-key")` sets `LlmTestServer:RequiredBearerToken` so both provider endpoints and `/admin-api/*` control endpoints require the same bearer token.
+
+Use `AddLlmTestServerContainer()` only when you explicitly want a container-backed resource, for example for a deployment or container-runtime smoke test. The container mode uses a `ghcr.io/managedcode/llm-test-server` image tagged with the same release version as the installed `ManagedCode.LlmTestServer.Aspire` package; it is not the default local Aspire path.
+
+## Build And Test
+
+```bash
+dotnet restore ManagedCode.LlmTestServer.slnx
+dotnet build ManagedCode.LlmTestServer.slnx --configuration Release --no-restore
+dotnet test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal
+for project in src/*/*.csproj; do dotnet pack "$project" --configuration Release --no-build --output artifacts/packages; done
+```
+
+`global.json` opts `dotnet test` into `Microsoft.Testing.Platform` for .NET 10.
+
+After restore/build, run `bash scripts/coverage.sh` for the production 90% coverage gate. After packing, run `python3 scripts/verify-package.py` for an isolated NuGet consumer, test-owned Aspire host and Chromium dashboard test; this requires Python 3 and PowerShell (`pwsh`). CI installs Chromium dependencies and saves coverage/browser evidence. `python3 scripts/test-release.py` verifies partial-release recovery locally without external publication. Release delivery is marked complete only after NuGet push and GitHub artifact attachment succeed.
diff --git a/docs/Reference/ProvidersAndRoutes.md b/docs/Reference/ProvidersAndRoutes.md
new file mode 100644
index 0000000..5ee0ad8
--- /dev/null
+++ b/docs/Reference/ProvidersAndRoutes.md
@@ -0,0 +1,152 @@
+# Providers, packages and routes
+
+Provider namespaces, NuGet packages, hosted routes, current functionality and native decision APIs. Back to the [README](../../README.md).
+
+## Packages
+
+Package links identify the NuGet package surfaces; badges update when publication is available.
+The complete v1.0.0 launch remains pending. Use the [local package feed](Installation.md#choose-how-to-run) before public release.
+
+| Package | Latest version | Downloads | Description |
+| --- | --- | --- | --- |
+| [ManagedCode.LlmTestServer](https://www.nuget.org/packages/ManagedCode.LlmTestServer) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer) | Provider-neutral scenario runtime and assertion state. |
+| [ManagedCode.LlmTestServer.OpenAI](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenAI) | OpenAI-compatible wire contracts. |
+| [ManagedCode.LlmTestServer.AzureOpenAI](https://www.nuget.org/packages/ManagedCode.LlmTestServer.AzureOpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.AzureOpenAI) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.AzureOpenAI) | Azure OpenAI compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Foundry](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Foundry) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Foundry) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Foundry) | Microsoft Foundry compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Anthropic](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Anthropic) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Anthropic) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Anthropic) | Anthropic Messages compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Gemini](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Gemini) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Gemini) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Gemini) | Gemini compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Groq](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Groq) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Groq) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Groq) | Groq compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Mistral](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Mistral) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Mistral) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Mistral) | Mistral compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Ollama](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Ollama) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Ollama) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Ollama) | Ollama compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Cohere](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cohere) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cohere) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cohere) | Cohere compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Bedrock](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Bedrock) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Bedrock) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Bedrock) | Amazon Bedrock compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.OpenRouter](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenRouter) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenRouter) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.OpenRouter) | OpenRouter compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.DeepSeek](https://www.nuget.org/packages/ManagedCode.LlmTestServer.DeepSeek) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.DeepSeek) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.DeepSeek) | DeepSeek compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.Perplexity](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Perplexity) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Perplexity) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Perplexity) | Perplexity compatibility profile and wire contracts. |
+| [ManagedCode.LlmTestServer.SystemOne](https://www.nuget.org/packages/ManagedCode.LlmTestServer.SystemOne) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.SystemOne) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.SystemOne) | **TypeSafe / Jev** and Kev native System One decision contracts. |
+| [ManagedCode.LlmTestServer.Cloudflare](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cloudflare) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cloudflare) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Cloudflare) | Cloudflare Workers AI Clef/flash decision envelopes and validation. |
+| [ManagedCode.LlmTestServer.Hosting](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Hosting) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Hosting) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Hosting) | ASP.NET Core endpoint mapping. |
+| [ManagedCode.LlmTestServer.Client](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Client) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Client) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Client) | Control client plus `IChatClient`, `IEmbeddingGenerator>`, and `IImageGenerator` implementations. |
+| [ManagedCode.LlmTestServer.Aspire](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Aspire) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Aspire) | [](https://www.nuget.org/packages/ManagedCode.LlmTestServer.Aspire) | Aspire AppHost extension methods. |
+
+## Current Functionality
+
+This is the currently implemented behavior, not future intent:
+
+| Surface | What works now |
+| --- | --- |
+| Hosting | `builder.Services.AddLlmTestServer(...)` registers the default runtime and isolated test-session registry; `app.MapLlmTestServer()` maps the Blazor server-side browser panel at `/`, JSON control endpoints under `/admin-api`, and provider-namespaced HTTP routes. |
+| Runtime configuration | Configure at host startup, through `LlmTestServerClient.ConfigureAsync(...)`, or through `POST /admin-api/configure`. Configuration replaces the current runtime state and resets assertions, scenario positions, fault counters, and prompt-cache entries. |
+| Reset | `ResetAsync()` and `POST /admin-api/reset` keep the current models/scenarios/fixtures but clear assertion events, scenario response positions, rate-limit counters, and prompt-cache entries. |
+| Models | Default models use official fixture IDs for chat, embeddings, images, audio, and video. Typed helpers register broader OpenAI model families, and `AddModel(...)` supports custom deployment or provider IDs. Model kind is enforced on every route. |
+| Chat scenarios | Contains matching, exact prompt matching, queued responses, streaming chunks, scripted errors, delayed responses, cancellation-safe queues, and scenario-specific bearer tokens are implemented. |
+| Modalities | Chat, embeddings, image generation/edit/variation, audio speech/transcription/translation, OpenAI/Azure video, Gemini long-running video/file output, and Bedrock text/embedding/image invoke shapes return deterministic fixtures. |
+| Provider matrix | OpenAI, Azure OpenAI, Microsoft Foundry, Anthropic, Gemini, Groq, Mistral, Ollama, Cohere, Amazon Bedrock, OpenRouter, DeepSeek, and Perplexity are exposed under explicit provider namespaces. Each hosted operation is represented in a provider `ApiContract` and behavior evidence tests. |
+| SDK clients | Official OpenAI, Azure OpenAI, Azure AI Inference / Foundry, Anthropic and Google Gen AI SDKs, Amazon Bedrock, and `Microsoft.Extensions.AI` clients call the qualified hosted routes. See the [SDK compatibility matrix](../Features/ProviderSdkCompatibility.md) for operation-level evidence and boundaries. The client package also creates control, chat, embedding, image, and audio clients with the same bearer token. |
+| Auth | A global bearer token protects provider and `/admin-api/*` endpoints. Anthropic `x-api-key` and Azure `api-key` headers are accepted as provider-native ways to pass the same token. Scenarios can add their own bearer-token requirement. |
+| Fault simulation | Provider-neutral rate-limit and content-filter simulation flow through every provider family and return provider-shaped errors. Scripted per-scenario failures remain available for exact test paths. |
+| Assertions | `/admin-api/assertions` returns counters plus retained runtime events with request preview, response/error text, model id, scenario id, event kind, and deterministic usage. |
+| Test sessions | Typed `CreateSessionAsync(...)` and session headers isolate configuration, queues, history, faults, cache and journal; reset/disposal affect the owning session. |
+| Conversation graphs | `UseConversation(...)` configures typed step predicates, branches, tool-result checks, turn ordering, terminal policies and successful-request replay; match explanations and conversation status are available through control APIs. |
+| Request evidence | `GetRequestsAsync(...)` filters/pages the bounded journal; `ExportRequestsAsync(...)` and `ExportRequestsNdjsonAsync(...)` include versioned retention/eviction evidence. |
+| Verification | `VerifyAsync(...)` checks counts/order, unexpected calls, structured tool arguments/results, visited graph steps, terminal markers and retry policy. Incomplete retained evidence cannot pass. |
+| Wire identity and time | `UseDeterminism(seed, fixedUtc)` fixes generated provider IDs/time with provider-local counters; reset reproduces them and graph replay retains metadata. Real diagnostic clocks and retry timing stay real. |
+| Usage accounting | Input, output, reasoning, total, cached-input, and cache-write token values are computed deterministically and projected into provider-specific response envelopes when that provider surface documents usage fields. |
+| Browser panel | `/` shows models/fixtures, actions, control and provider endpoint groups, grouped runtime events, captured requests, captured responses, counters, and per-event usage. It auto-refreshes every 15 seconds using Blazor component state and `StateHasChanged()`. |
+| Aspire | `builder.AddLlmTestServer()` starts the packaged .NET service without Docker by default; `WithApiKey(...)` wires auth, `GetHttpEndpoint()` and provider-specific endpoint helpers expose URLs, and `AddLlmTestServerContainer()` is an explicit container opt-in. |
+
+See [conversation graphs](../Features/ConversationDSL.md) and
+[request verification and determinism](../Features/RequestVerificationAndDeterminism.md) for typed APIs,
+HTTP contracts, retention limits and terminal-marker applicability. Explicit fixture timestamps retain their
+configured values.
+Public publication and remaining roadmap features are tracked in the [delivery plan](../Features/LlmTestServerDeliveryPlan.md).
+
+## Provider Packages
+
+Provider packages keep vendor-specific protocol and compatibility metadata out of the provider-neutral runtime. The package surface exists now so applications can select a provider family explicitly; provider-specific DTOs and endpoint mappings are added inside each package as support grows.
+
+| Package | Provider ID | Protocol family | Primary hosted route |
+| --- | --- | --- | --- |
+| `ManagedCode.LlmTestServer.OpenAI` | `openai` | OpenAI | `/openai/v1` |
+| `ManagedCode.LlmTestServer.AzureOpenAI` | `azure-openai` | Azure OpenAI | `/azure-openai/openai/deployments/{deployment}/chat/completions` |
+| `ManagedCode.LlmTestServer.Foundry` | `microsoft-foundry` | Microsoft Foundry | `/microsoft-foundry/models/chat/completions` |
+| `ManagedCode.LlmTestServer.Anthropic` | `anthropic` | Anthropic Messages | `/anthropic/v1/messages` |
+| `ManagedCode.LlmTestServer.Gemini` | `gemini` | Gemini | `/gemini/v1beta/models/{model}:generateContent` |
+| `ManagedCode.LlmTestServer.Groq` | `groq` | Groq | `/groq/openai/v1/chat/completions` |
+| `ManagedCode.LlmTestServer.Mistral` | `mistral` | Mistral | `/mistral/v1/chat/completions` |
+| `ManagedCode.LlmTestServer.Ollama` | `ollama` | Ollama | `/ollama/api/chat` |
+| `ManagedCode.LlmTestServer.Cohere` | `cohere` | Cohere | `/cohere/v2/chat` |
+| `ManagedCode.LlmTestServer.Bedrock` | `bedrock` | Amazon Bedrock | `/bedrock/model/{modelId}/converse` |
+| `ManagedCode.LlmTestServer.OpenRouter` | `openrouter` | OpenRouter | `/openrouter/api/v1/chat/completions` |
+| `ManagedCode.LlmTestServer.DeepSeek` | `deepseek` | DeepSeek | `/deepseek/v1/chat/completions` |
+| `ManagedCode.LlmTestServer.Perplexity` | `perplexity` | Perplexity | `/perplexity/v1/sonar` |
+| **`ManagedCode.LlmTestServer.SystemOne`** | `systemone` | **TypeSafe / Jev** and Kev native System One decisions | `/systemone/v1/systemone` |
+| `ManagedCode.LlmTestServer.Cloudflare` | `cloudflare` | Clef / Clef Flash native decisions | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` |
+
+Each provider profile also carries a doc-backed `ApiContract` with official documentation links, retrieval date, API version or header requirements, documented operations, streaming support, and whether `ManagedCode.LlmTestServer.Hosting` currently maps the operation.
+
+Use a provider profile when code needs a stable package-level declaration without starting a host:
+
+```csharp
+using ManagedCode.LlmTestServer.AzureOpenAI;
+
+var profile = AzureOpenAiCompatibility.Profile;
+Console.WriteLine(profile.Id); // azure-openai
+```
+
+## Hosted Endpoint Families
+
+Provider endpoints are explicitly namespaced. The table below shows the route
+families and representative operations; the full method/path contract lives in
+each provider profile's `ApiContract` and is guarded by
+`ProviderApiContractTests`. See
+[`docs/Features/ProviderApiContractCoverage.md`](../Features/ProviderApiContractCoverage.md)
+for the current coverage rules and behavior-test inventory.
+
+| Provider | Namespace | Representative hosted operations |
+| --- | --- | --- |
+| OpenAI | `/openai` | `/openai/v1/models`, `/openai/v1/decisions`, `/openai/v1/chat/completions`, `/openai/v1/responses`, `/openai/v1/embeddings`, `/openai/v1/images/*`, `/openai/v1/audio/*`, `/openai/v1/videos*` |
+| Azure OpenAI | `/azure-openai` | `/azure-openai/openai/v1/{chat/completions,responses,embeddings}`, deployment chat/embeddings/images/audio, and `/azure-openai/openai/v1/video/generations/*` |
+| Microsoft Foundry | `/microsoft-foundry` | `/microsoft-foundry/openai/v1/{chat/completions,responses,embeddings}`, `/microsoft-foundry/chat/completions`, `/microsoft-foundry/embeddings`, and `/microsoft-foundry/models/*` aliases |
+| Anthropic | `/anthropic` | `/anthropic/v1/messages` |
+| Gemini | `/gemini` | `/gemini/v1beta/models/{model}:generateContent`, streaming content, embeddings, long-running video operations, and generated files |
+| Groq | `/groq` | `/groq/openai/v1/models`, chat completions, Responses, speech, transcription, and translation routes |
+| Mistral | `/mistral` | `/mistral/v1/chat/completions`, `/mistral/v1/embeddings` |
+| Ollama | `/ollama` | `/ollama/api/chat`, `/ollama/api/embed` |
+| Cohere | `/cohere` | `/cohere/v2/chat`, `/cohere/v2/embed` |
+| Amazon Bedrock | `/bedrock` | `/bedrock/model/{modelId}/converse`, converse stream, invoke, and invoke-with-response-stream |
+| OpenRouter | `/openrouter` | `/openrouter/api/v1/models`, chat completions, Responses |
+| DeepSeek | `/deepseek` | `/deepseek/models`, `/deepseek/v1/chat/completions` |
+| Perplexity | `/perplexity` | `/perplexity/v1/sonar` |
+| TypeSafe / Jev and Kev (System One) | `/systemone` | `/systemone/v1/systemone` |
+| Cloudflare (Clef/flash) | `/cloudflare` | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef`, `clef-flash` |
+
+The Blazor server-side rendered browser control panel lives at `/`. JSON control endpoints live under
+`/admin-api`: `GET /admin-api/models`, `GET /admin-api/assertions`,
+`POST /admin-api/configure`, and `POST /admin-api/reset`.
+
+Audio speech returns a deterministic WAV fixture by default. When
+`requiredBearerToken` is configured, all provider and control endpoints require
+`Authorization: Bearer `.
+
+## Native decision API fixtures
+
+Native typed clients are available through `LlmTestServerClient.CreateSystemOneClient()`
+and `LlmTestServerClient.CreateCloudflareDecisionClient(accountId)`. Clef accepts embedded
+PNG/JPEG/WebP data URLs or base64 objects; Jev accepts PNG/JPEG reference assets as
+JSON or multipart, with explicit image/long-context opt-ins. See the
+[official-contract audit and supported limits](../Features/DecisionVisionAudit.md).
+
+Jev, Kev, Cloudflare Clef/Clef Flash and OpenAI Decisions use explicit decision fixtures. The Test Server hosts their native JSON shapes under provider namespaces and does not contact production providers. Declare the provider profile explicitly; model names never select an API implicitly.
+
+| Provider | Test Server POST route | Production POST endpoint | Model helper | Official contract |
+| --- | --- | --- | --- | --- |
+| TypeSafe Jev | `/systemone/v1/systemone` | `https://api.typesafe.ai/v1/systemone` | `AddJevLatest()` | [OpenAPI](https://api.typesafe.ai/openapi.json), [primitives](https://docs.typesafe.ai/primitives/choice) |
+| Kev | `/systemone/v1/systemone` | `{kev-server}/v1/systemone` | `AddKevLatest()` | [native request models](https://github.com/jaredpalmer/kev/blob/main/kev/api.py), [server/auth](https://github.com/jaredpalmer/kev/blob/main/kev/serve.py) |
+| Cloudflare Clef | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` | `https://api.cloudflare.com/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef` | `AddClef()` | [Clef API](https://developers.cloudflare.com/workers-ai/models/clef/), [REST envelope/auth](https://developers.cloudflare.com/workers-ai/get-started/rest-api/) |
+| Cloudflare Clef Flash | `/cloudflare/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `https://api.cloudflare.com/client/v4/accounts/{accountId}/ai/run/@cf/cloudflare/clef-flash` | `AddClefFlash()` | [Clef Flash API](https://developers.cloudflare.com/workers-ai/models/clef-flash/) |
+| OpenAI Decisions | `/openai/v1/decisions` | `https://api.openai.com/v1/decisions` | `AddOpenAiDecisionModel("gpt-6-luna")` | [create API](https://developers.openai.com/api/reference/resources/decisions/methods/create/) |
+
+Production APIs use `Authorization: Bearer `; Kev checks `KEV_API_KEY` only when configured and otherwise permits unauthenticated calls. For the Test Server, `RequireBearerToken` controls the expected test token and protects both provider routes and `/admin-api/*`. Tests do not need production credentials. Resolve the hosted base URL from the Aspire resource (`GetEndpoint("http")` / `CreateHttpClient(...)`), then append the Test Server route.
+
+Complete native request/response contracts, examples and limits for SystemOne (Jev, Kev), Cloudflare Clef/Clef Flash and OpenAI Decisions are in [native decision contracts](../Features/DecisionModels.md); behavior-test evidence is in the [test inventory](../Testing/AcceptanceCriteriaTestInventory.md).
diff --git a/docs/Reference/TokenUsageAndPromptCache.md b/docs/Reference/TokenUsageAndPromptCache.md
new file mode 100644
index 0000000..81225d2
--- /dev/null
+++ b/docs/Reference/TokenUsageAndPromptCache.md
@@ -0,0 +1,59 @@
+# Token usage and prompt-cache accounting
+
+How deterministic token usage, reasoning tokens and prompt-cache reads/writes are computed and reported on every provider surface. For the per-role input composition and dashboard charts, see [dashboard analytics](../Features/DashboardAnalytics.md). Back to the [README](../../README.md).
+
+## Control Panel And Token Usage
+
+Open the Test Server resource endpoint from the Aspire dashboard to inspect the running configuration at `/`. The browser admin panel is rendered by Blazor server-side rendering from `ManagedCode.LlmTestServer.Hosting`. If the resource was configured with `.WithApiKey("test-key")` or `RequireBearerToken("test-key")`, enter the same token in the control panel before refreshing.
+
+The dashboard is a request inbox: one row per provider call, with the request, response, conversation, wire payloads, stream chunks, token composition and runtime result for the selected call. The **Tokens** tab draws the token flow and prompt-cache donuts for a request or an explicitly labeled conversation, and **Traffic insights** (`/?view=insights`) charts all retained traffic; see [dashboard analytics](../Features/DashboardAnalytics.md). The **Runtime** dialog shows fixtures, provider routes, assertion counters and the event timeline. Auto-refresh is enabled by default and runs every 15 seconds on the server-side Blazor component; there is no client-side polling script and no visible countdown.
+
+Token usage is counted with the repo-owned tiktoken-compatible counter and reported both as summary totals and per runtime event with `inputTokens`, `cachedInputTokens`, `cacheCreationInputTokens`, `outputTokens`, `reasoningTokens`, and `totalTokens`. Provider response envelopes also receive the same deterministic usage values: OpenAI-compatible chat and Responses usage including reasoning-token and prompt-cache details when configured, Anthropic sync messages and streaming `message_start`/`message_delta`, Gemini `usageMetadata` including long-running video operation results, Cohere chat usage, Ollama prompt/eval counts, and Bedrock Converse usage.
+
+For reasoning-capable fixture models, configure a deterministic reasoning-token count on the model. LLM Test Server includes those tokens in `outputTokens` and exposes the split in `reasoningTokens`; OpenAI-compatible responses also include `completion_tokens_details.reasoning_tokens` or `output_tokens_details.reasoning_tokens`.
+
+```csharp
+options.AddGpt5Nano(reasoningTokens: 128);
+```
+
+## Prompt Cache Accounting
+
+Prompt cache accounting is deterministic runtime state for testing provider usage handling. LLM Test Server does not call a real cache service and does not hide prompt text; it calculates repeated prompt-prefix usage from the requests that reach the runtime.
+
+Cache entries are created only for successful chat or Responses requests on provider surfaces with a cache policy. A failed, unmatched, unauthorized, cancelled, unknown-model, or scripted-error request does not create a cache entry. `ConfigureAsync(...)` and `ResetAsync()` both clear prompt-cache entries so each test can start from a known cache state.
+
+The cache key includes provider cache policy, model id, an optional provider cache key or session id, the rounded cacheable token count, and the cumulative message prefix. The first successful request with a cacheable prefix reports cache-write tokens and zero cache-read tokens. Ollama exposes cache reads only and does not report cache-write tokens. A later successful request with the same cache key reports cache-read tokens and zero cache-write tokens for the already cached prefix.
+
+Provider cache thresholds follow the current runtime policy:
+
+| Policy | Provider routes | Minimum cacheable tokens | Increment |
+| --- | --- | ---: | ---: |
+| OpenAI-compatible | OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Perplexity, Responses API routes that use the OpenAI-compatible shape | 1024 | 128 |
+| OpenRouter | OpenRouter chat and Responses routes; `session_id` or `x-session-id` can become the cache key when no explicit prompt cache key is sent | 1024 | 128 |
+| DeepSeek | DeepSeek chat routes | 1024 | 128 |
+| Anthropic | Anthropic Messages requests that include `cache_control` markers | 1024 | 128 |
+| Mistral | Mistral chat routes | 64 | 64 |
+| Gemini | Gemini generateContent routes | 2048 | 128 |
+| Ollama | Ollama chat routes; deterministic cache reads only | 1 | 1 |
+| Bedrock | Bedrock Converse requests that include `cachePoint` or `cache_control` markers | 1024 | 128 |
+
+Cache accounting is a breakdown of input usage, not an extra billable token bucket. `totalTokens` remains `inputTokens + outputTokens`; `cachedInputTokens` and `cacheCreationInputTokens` explain how much of the input was read from, or written to, the deterministic prompt cache.
+
+Provider envelopes expose the same runtime usage through provider-native field names:
+
+| Provider surface | Cache fields returned |
+| --- | --- |
+| OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Mistral, Perplexity chat | `usage.prompt_tokens_details.cached_tokens` |
+| OpenAI, Groq, Azure OpenAI, Microsoft Foundry, Perplexity Responses | `usage.input_tokens_details.cached_tokens` |
+| OpenRouter chat and Responses | `cached_tokens` plus `cache_write_tokens` in the matching prompt/input token details object |
+| DeepSeek chat | `usage.prompt_cache_hit_tokens` and `usage.prompt_cache_miss_tokens` |
+| Anthropic Messages | `usage.cache_creation_input_tokens` and `usage.cache_read_input_tokens` when cache usage exists |
+| Gemini generateContent | `usageMetadata.cachedContentTokenCount` |
+| Ollama chat | `prompt_eval_cached_count`, reported on the final NDJSON chunk for streaming |
+| Bedrock Converse and ConverseStream metadata | `usage.cacheReadInputTokens` and `usage.cacheWriteInputTokens` |
+
+[](../images/admin-dashboard-token-usage.png)
+
+[](../images/admin-dashboard-mobile-request-detail.png)
+
+OpenAI chat streaming supports `stream_options.include_usage`; the control library's `IChatClient` carries token usage and terminal updates, including reasoning and cache details. Authentication failures and scripted errors before generation do not accrue output/reasoning tokens.
diff --git a/docs/Reviews/FollowUpReview20260907.md b/docs/Reviews/FollowUpReview20260907.md
index c7ce401..052c0d4 100644
--- a/docs/Reviews/FollowUpReview20260907.md
+++ b/docs/Reviews/FollowUpReview20260907.md
@@ -8,7 +8,7 @@
### F1 — P2: отриманий snapshot дозволяє змінити внутрішній журнал
-Місця: `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:920`, `:1450–1457`; `Scenarios/LlmTckMessage.cs:9`.
+Місця: `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:920`, `:1450–1457`; `Scenarios/LlmTestServerMessage.cs:9`.
`GetAssertionSummary()` копіює лише список подій. Вкладений `Messages[i].ToolCalls` залишається тим самим mutable `List`, який зберігається в журналі. У harness після `summary.Events[0].Messages[0].ToolCalls.Clear()` та додавання `Id="injected"` наступний незалежний `GetAssertionSummary()` повернув **injected** замість original.
@@ -16,7 +16,7 @@
### F2 — P2: `parallel_tool_calls=false` мовчки ігнорується
-Місця: `src/ManagedCode.LlmTck.OpenAI/OpenAiChatModels.cs:7–18`, `OpenAiToolModels.cs:44–57`.
+Місця: `src/ManagedCode.LlmTestServer.OpenAI/OpenAiChatModels.cs:7–18`, `OpenAiToolModels.cs:44–57`.
Для fixture з двома викликами weather запит із `parallel_tool_calls:false` отримав **200 та два tool_calls**. Поля немає в wire DTO і neutral request. Поточні тести кількох викликів перевіряють їх перенесення, але не обмеження запиту.
@@ -24,7 +24,7 @@
### F3 — P2: адаптер Gemini не повністю перетворює OpenAPI Schema
-Місце: `src/ManagedCode.LlmTck.Gemini/GeminiWireMapper.cs:98–130`.
+Місце: `src/ManagedCode.LlmTestServer.Gemini/GeminiWireMapper.cs:98–130`.
`NormalizeSchemaNode` лише переводить назви типів у lowercase, після чого OpenAPI Schema оцінюється як JSON Schema Draft 2020-12. Два коректні wire contracts відтворили помилку:
@@ -35,15 +35,15 @@
### F4 — P2: fixture mismatch невидимий у runtime assertion summary
-Місце: `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:312–316`.
+Місце: `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:312–316`.
-Для текстової fixture `not json` і `RequireJson=true` runtime повернув **409 / llm_tck_fixture_mismatch**, але summary містив **TotalEvents=0, ErrorsReturned=0, Events=[]**. Early return обходить AddEvent та облік usage.
+Для текстової fixture `not json` і `RequireJson=true` runtime повернув **409 / llm_test_server_fixture_mismatch**, але summary містив **TotalEvents=0, ErrorsReturned=0, Events=[]**. Early return обходить AddEvent та облік usage.
HTTP trace може показати помилку, але користувачі runtime/control assertions не отримують відповідного діагностичного запису. Треба додати окремий вид події/лічильник mismatch або послідовно використовувати error event. Черга відповідей при цьому повинна залишатися незмінною. Це слід перевірити одночасним assertion на 409, journal та наступну відповідь.
### F5 — P2: HTTP chat без обов'язкової моделі проходить успішно
-Місце: `src/ManagedCode.LlmTck.OpenAI/OpenAiChatModels.cs:18`.
+Місце: `src/ManagedCode.LlmTestServer.OpenAI/OpenAiChatModels.cs:18`.
Запит `{"messages":[{"role":"user","content":"hello"}]}` на `/openai/v1/chat/completions` повернув **200**, підставив gpt-4.1-mini та спожив fixture. Default model у wire DTO приховує відсутнє поле ще до ValidateChatRequest.
@@ -51,7 +51,7 @@ HTTP trace може показати помилку, але користувач
### F6 — P2: Exact matching не може вимагати відсутність tool calls
-Місце: `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:1298–1304`.
+Місце: `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:1298–1304`.
`WithExactMatch` для порожнього assistant message без tool calls зіставився з assistant message, що містить **додатковий weather tool call**, і повернув 200 / `matched empty assistant`. Порожній expected.ToolCalls завжди працює як wildcard; null ToolCallId має аналогічну поведінку.
@@ -60,8 +60,8 @@ HTTP trace може показати помилку, але користувач
## Що покращити після цих виправлень
1. **Прив'язати evidence до capability і режиму.** `ProviderApiContractTests:238–303` перевіряє operation, streaming flag, існування test method та згадку в inventory. Він не доводить, що конкретна capability має positive/negative cases. Варто використовувати `(provider, operation, capability, transport, outcome)` та конкретні case IDs. Критерій успіху: видалення тесту заборонених parallel calls або nullable schema ламає відповідний guard.
-2. **Перенести tool wire validation до provider packages.** `LlmTckToolRequestValidation` централізує поля OpenAI, Anthropic, Gemini, Cohere, Ollama і Bedrock через `typeof(T)`. Це дублює знання mapper-ів у Hosting. Provider-owned validation має повертати нейтральний validation result, а Hosting — лише оформляти HTTP відповідь.
-3. **Обмежити video store за кількістю та байтами.** `LlmTckRuntime.Videos.cs:5–33` зберігає всі jobs і копії bytes до delete/reset. Це не виміряний memory leak, але явна відсутність capacity на відміну від журналу й prompt cache. Додати configurable MaxVideoJobs/MaxVideoBytes та детерміновану політику переповнення; перевірити на великих fixtures без time-based sleeps.
+2. **Перенести tool wire validation до provider packages.** `LlmTestServerToolRequestValidation` централізує поля OpenAI, Anthropic, Gemini, Cohere, Ollama і Bedrock через `typeof(T)`. Це дублює знання mapper-ів у Hosting. Provider-owned validation має повертати нейтральний validation result, а Hosting — лише оформляти HTTP відповідь.
+3. **Обмежити video store за кількістю та байтами.** `LlmTestServerRuntime.Videos.cs:5–33` зберігає всі jobs і копії bytes до delete/reset. Це не виміряний memory leak, але явна відсутність capacity на відміну від журналу й prompt cache. Додати configurable MaxVideoJobs/MaxVideoBytes та детерміновану політику переповнення; перевірити на великих fixtures без time-based sleeps.
Рекомендований порядок: F1 та F4 для надійності доказів; F2, F3, F5 для protocol conformance; F6 як уточнення matching contract. Потім посилення capability evidence, щоб нові крайові випадки не знову проходили повз перевірки.
@@ -103,7 +103,7 @@ Harness посилається на реальні project references і вик
Перевірки поточного checkout:
-- `dotnet format ManagedCode.LlmTck.slnx --verify-no-changes --no-restore` — пройдено.
+- `dotnet format ManagedCode.LlmTestServer.slnx --verify-no-changes --no-restore` — пройдено.
- Release build — пройдено; два наявні попередження ASPIRE010 про AspireUseCliBundle=false, помилок немає.
- Повний набір, включно з provider contract/evidence, Azure SDK, Bedrock SDK та Aspire tests: **379/379**, повторено під coverage.
- `bash scripts/coverage.sh`: Coverlet total line **90.58%**, поріг 90% пройдено. ReportGenerator HTML: `artifacts/coverage/report/summary.html`.
diff --git a/docs/Reviews/ProjectReview20260907.md b/docs/Reviews/ProjectReview20260907.md
index 2a41f9b..9ddb1fc 100644
--- a/docs/Reviews/ProjectReview20260907.md
+++ b/docs/Reviews/ProjectReview20260907.md
@@ -1,4 +1,4 @@
-# Review LlmTck — 2026-09-07
+# Review LlmTestServer — 2026-09-07
> Подальші виправлення та перевірки: [ReviewRemediation20260907.md](ReviewRemediation20260907.md). Нижче збережені початкові знахідки до виправлень.
@@ -6,7 +6,7 @@
Перевірено поточний checkout `fa6f6ef` разом із незакоміченими змінами версії `0.1.1`. Знайдено **12 конкретних проблем: 4 P1 і 8 P2**. Одинадцять підтверджено окремим виконуваним harness, HTTP або браузером; ризик відновлення релізу встановлено аналізом workflow. Виправлення в production-код у цьому review не внесені.
-Базовий повний прогін пройшов: **196/196**, без пропусків. Додатковий consumer поза репозиторієм встановив саме локальний `ManagedCode.LlmTck.Aspire.0.1.1.nupkg`, запустив власний AppHost і перевірив упакований сервіс. NuGet metadata підтверджує джерело `artifacts/packages`; source fallback для сервісу не використовувався. У браузері перевірено роботу Runtime settings цього consumer.
+Базовий повний прогін пройшов: **196/196**, без пропусків. Додатковий consumer поза репозиторієм встановив саме локальний `ManagedCode.LlmTestServer.Aspire.0.1.1.nupkg`, запустив власний AppHost і перевірив упакований сервіс. NuGet metadata підтверджує джерело `artifacts/packages`; source fallback для сервісу не використовувався. У браузері перевірено роботу Runtime settings цього consumer.
Переглянуті runtime і конфігурація, provider DTO/мапери/маршрути, API-contract/evidence тести, клієнти Microsoft.Extensions.AI, admin state/HTTP diagnostics, Aspire locator/пакування, sample service, CI/release та структура UI. Це не live conformance тест зовнішніх LLM і не повний responsive/accessibility аудит сайту. Попередні 90,07% line coverage є доказом виконаних рядків, але не закривають наведені нижче поведінкові прогалини.
@@ -16,19 +16,19 @@
### R1. Dashboard із Aspire NuGet не отримує JavaScript
-**Місце:** `src/ManagedCode.LlmTck.Aspire/ManagedCode.LlmTck.Aspire.csproj:13–16`.
+**Місце:** `src/ManagedCode.LlmTestServer.Aspire/ManagedCode.LlmTestServer.Aspire.csproj:13–16`.
Пакет бере сервіс із `bin/Release/net10.0` і виключає `*.staticwebassets.runtime.json`. Build output не містить фізичного `wwwroot`, на який покладаються static asset endpoints після видалення development manifest. У перевіреному nupkg взагалі **0 JavaScript-файлів**.
-**Відтворення:** чистий consumer із PackageReference на `0.1.1`, `builder.AddLlmTck().WithApiKey("test-key")`, старт через Aspire.Hosting.Testing. `/health`, `/` та `/admin-api/models` повертають 200. Водночас `/_framework/blazor.web.js` і Fluent module повертають **200 / 0 bytes**. Service log прямо повідомляє, що застосунок працює не з publish output і static web assets не ввімкнені. У браузері натискання Runtime settings залишає popup закритим; сторінка містить script `_framework/blazor.web.js`.
+**Відтворення:** чистий consumer із PackageReference на `0.1.1`, `builder.AddLlmTestServer().WithApiKey("test-key")`, старт через Aspire.Hosting.Testing. `/health`, `/` та `/admin-api/models` повертають 200. Водночас `/_framework/blazor.web.js` і Fluent module повертають **200 / 0 bytes**. Service log прямо повідомляє, що застосунок працює не з publish output і static web assets не ввімкнені. У браузері натискання Runtime settings залишає popup закритим; сторінка містить script `_framework/blazor.web.js`.
-**Наслідок:** користувач установлює пакет, бачить HTML dashboard, але не може скористатися інтерактивними контролами й авторизувати панель. Чинний Aspire integration test знаходить сервіс у source checkout через `LlmTckServiceLocator`, тому не перевіряє цю властивість nupkg.
+**Наслідок:** користувач установлює пакет, бачить HTML dashboard, але не може скористатися інтерактивними контролами й авторизувати панель. Чинний Aspire integration test знаходить сервіс у source checkout через `LlmTestServerServiceLocator`, тому не перевіряє цю властивість nupkg.
**Виправлення:** пакувати service **publish output** зі статичними assets; додати NuGet-consumer тест поза solution, перевірку ненульового JS та браузерний сценарій відкриття settings/авторизації.
### R2. Tools і Structured Output заявлені, але не реалізовані
-**Місця:** `src/ManagedCode.LlmTck.OpenAI/OpenAiCompatibility.cs:27–28,61–62`; `OpenAiChatModels.cs:7–23`; `src/ManagedCode.LlmTck/Scenarios/LlmTckScenarioResponse.cs`.
+**Місця:** `src/ManagedCode.LlmTestServer.OpenAI/OpenAiCompatibility.cs:27–28,61–62`; `OpenAiChatModels.cs:7–23`; `src/ManagedCode.LlmTestServer/Scenarios/LlmTestServerScenarioResponse.cs`.
Профілі й документація прямо включають `Tools` та `StructuredOutput` у підтримувані можливості. Request DTO не має `tools`, `tool_choice` чи `response_format`; сценарій уміє повертати лише текст/чанки/помилку. Поля мовчки губляться під час десеріалізації.
@@ -40,7 +40,7 @@
### R3. Video lifecycle не має стану і ніколи не завершує OpenAI polling
-**Місця:** `src/ManagedCode.LlmTck.OpenAI/OpenAiVideoModels.cs:33`; `OpenAiWireMapper.cs:361–373`; `src/ManagedCode.LlmTck.Hosting/LlmTckEndpointRouteBuilderExtensions.cs:2340–2375`.
+**Місця:** `src/ManagedCode.LlmTestServer.OpenAI/OpenAiVideoModels.cs:33`; `OpenAiWireMapper.cs:361–373`; `src/ManagedCode.LlmTestServer.Hosting/LlmTestServerEndpointRouteBuilderExtensions.cs:2340–2375`.
`ToVideoResponse` не змінює початковий `Status="queued"`, хоча виставляє `completed_at`. GET генерує нову стандартну fixture і підставляє будь-який переданий ID. DELETE повертає `deleted=true`, не змінюючи стану.
@@ -52,13 +52,13 @@
### R4. Скасований chat може безповоротно спожити відповідь
-**Місця:** `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:142,293–306,1124–1127`.
+**Місця:** `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:142,293–306,1124–1127`.
Cancellation перевіряється тільки через `Task.Delay`. Без затримки вже скасований token не зупиняє запит. Rollback повертає позицію лише коли після reservation жоден інший запит не пересунув курсор.
**Відтворення A:** виклик із `new CancellationToken(true)` повернув `first`; наступний отримав `second`.
-**Відтворення B:** запит A резервує `first` із затримкою, B отримує `second`, A скасовується; наступний запит повертає **409 / llm_tck_scenario_exhausted**, хоча `first` ніхто не отримав.
+**Відтворення B:** запит A резервує `first` із затримкою, B отримує `second`, A скасовується; наступний запит повертає **409 / llm_test_server_scenario_exhausted**, хоча `first` ніхто не отримав.
**Наслідок:** паралельні integration tests і retry після cancellation залежать від порядку завершення запитів. Наявний тест перевіряє лише одиничне скасування delayed request.
@@ -68,7 +68,7 @@ Cancellation перевіряється тільки через `Task.Delay`. Б
### R5. Однакові scenario ID у різних datasets ділять чергу
-**Місця:** `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:33,255,898–902`; `src/ManagedCode.LlmTck/Scenarios/LlmTckScenarioDatasetBuilder.cs:20–23`.
+**Місця:** `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:33,255,898–902`; `src/ManagedCode.LlmTestServer/Scenarios/LlmTestServerScenarioDatasetBuilder.cs:20–23`.
Dataset builder забезпечує унікальність лише всередині dataset, тоді як runtime ключує позиції одним `scenario.Id` після злиття всіх datasets.
@@ -78,7 +78,7 @@ Dataset builder забезпечує унікальність лише всер
### R6. Невдалий configure стирає trace journal
-**Місце:** `src/ManagedCode.LlmTck.Hosting/LlmTckEndpointRouteBuilderExtensions.cs:878–880`.
+**Місце:** `src/ManagedCode.LlmTestServer.Hosting/LlmTestServerEndpointRouteBuilderExtensions.cs:878–880`.
`traceStore.Reset()` виконується до валідації/snapshot усієї конфігурації у runtime. Наприклад, `{"models":null}` десеріалізується, а потім кидає `ArgumentNullException`.
@@ -88,7 +88,7 @@ Dataset builder забезпечує унікальність лише всер
### R7. Chat SSE не повертає запитаний usage
-**Місця:** `src/ManagedCode.LlmTck.OpenAI/OpenAiChatModels.cs:7–23,92–108`; `src/ManagedCode.LlmTck.Hosting/LlmTckEndpointRouteBuilderExtensions.cs:3203–3209`.
+**Місця:** `src/ManagedCode.LlmTestServer.OpenAI/OpenAiChatModels.cs:7–23,92–108`; `src/ManagedCode.LlmTestServer.Hosting/LlmTestServerEndpointRouteBuilderExtensions.cs:3203–3209`.
Request DTO ігнорує `stream_options.include_usage`; chunk DTO не має `usage`. Потік завершується stop і [DONE] без фінальної usage події.
@@ -100,7 +100,7 @@ Request DTO ігнорує `stream_options.include_usage`; chunk DTO не має
### R8. Власний IChatClient губить usage і фінальний stream update
-**Місця:** `src/ManagedCode.LlmTck.Client/LlmTckChatClient.cs:42–49,104–114`; аналогічне відкидання usage є в `LlmTckEmbeddingGenerator.cs`.
+**Місця:** `src/ManagedCode.LlmTestServer.Client/LlmTestServerChatClient.cs:42–49,104–114`; аналогічне відкидання usage є в `LlmTestServerEmbeddingGenerator.cs`.
Ordinary ChatResponse створюється без `Usage`, хоча HTTP DTO його має. Streaming повертає update лише за непорожнього text; фінальний chunk із finish reason та порожнім text відкидається.
@@ -110,7 +110,7 @@ Ordinary ChatResponse створюється без `Usage`, хоча HTTP DTO
### R9. Валідний JSON із null у вкладених полях спричиняє exception
-**Місце:** `src/ManagedCode.LlmTck.Hosting/LlmTckEndpointRouteBuilderExtensions.cs:4114–4119`.
+**Місце:** `src/ManagedCode.LlmTestServer.Hosting/LlmTestServerEndpointRouteBuilderExtensions.cs:4114–4119`.
Nullable runtime values можуть потрапити в non-nullable C# collection properties через JSON; initializer `=[]` не захищає від явного `null`. Gemini validation читає `content.Parts.Count` без перевірки null.
@@ -120,19 +120,19 @@ Nullable runtime values можуть потрапити в non-nullable C# colle
### R10. Legacy Azure api-version є лише metadata
-**Місця:** `src/ManagedCode.LlmTck.AzureOpenAI/AzureOpenAiCompatibility.cs:78`; `src/ManagedCode.LlmTck.Hosting/LlmTckEndpointRouteBuilderExtensions.cs:1003–1018`.
+**Місця:** `src/ManagedCode.LlmTestServer.AzureOpenAI/AzureOpenAiCompatibility.cs:78`; `src/ManagedCode.LlmTestServer.Hosting/LlmTestServerEndpointRouteBuilderExtensions.cs:1003–1018`.
Deployment chat передає запит у спільний handler без читання api-version. У Hosting немає перевірки цього query parameter.
**Доказ:** `/azure-openai/openai/deployments/gpt-4.1-mini/chat/completions?api-version=not-a-version` повернув 200 і спожив сценарій.
-**Наслідок:** помилкова Azure SDK/config інтеграція проходить локальний TCK. [Офіційна legacy REST-специфікація](https://github.com/Azure/azure-rest-api-specs/blob/main/specification/cognitiveservices/data-plane/AzureOpenAI/inference/stable/2024-10-21/inference.json) вимагає api-version; нові `/openai/v1` маршрути мають інше правило і не повинні отримати dated-version вимогу.
+**Наслідок:** помилкова Azure SDK/config інтеграція проходить локальний LLM Test Server. [Офіційна legacy REST-специфікація](https://github.com/Azure/azure-rest-api-specs/blob/main/specification/cognitiveservices/data-plane/AzureOpenAI/inference/stable/2024-10-21/inference.json) вимагає api-version; нові `/openai/v1` маршрути мають інше правило і не повинні отримати dated-version вимогу.
**Виправлення:** явна політика версій окремо для legacy Azure, Foundry inference і preview video, з негативними тестами missing/unsupported version до runtime queue consumption.
### R11. Відхилений запит нараховує reasoning/output tokens
-**Місце:** `src/ManagedCode.LlmTck/Runtime/LlmTckRuntime.cs:1545–1547`.
+**Місце:** `src/ManagedCode.LlmTestServer/Runtime/LlmTestServerRuntime.cs:1545–1547`.
`CreateChatUsage` завжди додає модельний ReasoningTokens, у тому числі коли його викликають auth/unmatched/fault error branches без генерації.
@@ -156,7 +156,7 @@ GitHub Release створюється перед `dotnet nuget push`. Якщо p
1. **Перевіряти capability, а не лише існування route/test method.** `ProviderApiContractTests` звіряє metadata, множини маршрутів і наявність імен тестів. Звичайний chat test вважається evidence для route, який також заявляє tools/structured output. Потрібна матриця `(provider, operation, capability, transport, error behavior)` з незалежними assertions.
2. **Перевіряти реальний NuGet consumer у CI.** Зараз source fallback приховує R1. Після pack варто створювати consumer за межами repository tree, запускати його через Aspire.Hosting.Testing і перевіряти SDK call, assets і UI action. Окремо корисний Linux consumer, бо нинішнє локальне відтворення виконувалось на macOS arm64.
-3. **Розділити великий Hosting файл.** `LlmTckEndpointRouteBuilderExtensions.cs` має 4602 рядки; runtime — 1760, AdminPage — 1538, AdminPanel — 1289. Винести provider route groups, validators і stream writers за відповідними межами відповідальності. Це полегшить окрему валідацію nullable JSON, API versions і usage.
+3. **Розділити великий Hosting файл.** `LlmTestServerEndpointRouteBuilderExtensions.cs` має 4602 рядки; runtime — 1760, AdminPage — 1538, AdminPanel — 1289. Винести provider route groups, validators і stream writers за відповідними межами відповідальності. Це полегшить окрему валідацію nullable JSON, API versions і usage.
4. **Закріпити 90% coverage gate у CI.** Поріг описаний у AGENTS і перевірявся локально, але чинні workflows запускають звичайні тести без coverage threshold. Додати той самий include/exclude scope і збереження звіту; не підміняти цим behavior evidence.
5. **Обмежити prompt cache для довгих load tests.** `_promptCacheEntries` не має capacity/eviction, хоча журнали обмежені. Це рекомендація для тривалих сесій з унікальними prompt keys, не виміряний у цьому review memory leak. Задати configurable capacity та deterministic eviction/reset policy.
diff --git a/docs/Reviews/ReviewRemediation20260907.md b/docs/Reviews/ReviewRemediation20260907.md
index f6134b7..5437770 100644
--- a/docs/Reviews/ReviewRemediation20260907.md
+++ b/docs/Reviews/ReviewRemediation20260907.md
@@ -17,7 +17,7 @@
| R9 | Nested null collections/items проходять валідацію до native mapper. | Gemini, Anthropic, Ollama, Cohere та OpenAI negative HTTP matrix; посилена Bedrock валідація. |
| R10 | Legacy Azure deployment routes приймають підтримувані 2024-10-21 GA та 2025-04-01-preview, які автоматично обирає SDK, і відхиляють невідомі версії (уточнено 2026-09-09); Foundry inference — 2024-05-01-preview; video preview — preview. Нові v1 routes не вимагають dated query. | Invalid/missing/duplicate query tests; офіційний Azure SDK без явно вибраної версії; чинні Azure/Foundry v1 SDK тести. |
| R11 | Відмови до генерації та scripted errors не створюють output/reasoning usage. | Auth, unmatched, scripted error й успішна reasoning-відповідь у runtime. |
-| R12 | NuGet публікується до final GitHub Release. Лише marker завершеної доставки дозволяє пропустити наступний запуск. Відсутній key дає помилку до публікації. | `scripts/test-release.py`: локальні fake CLI перевіряють partial failure, rerun, successful completion, force та missing-key. |
+| R12 | NuGet публікується до final GitHub Release. Лише marker завершеної доставки дозволяє пропустити наступний запуск. Відсутній key дає помилку до публікації. | `scripts/release.sh` ставить marker після public-feed gates; `scripts/verify-release.py` перевіряє реальні GitHub/NuGet artifacts. Fake CLI tests вилучено; end-to-end publication qualification очікує coordinated release. |
R2 тепер має реалізацію, а не лише виправлення capability claims. Межі підтримки (зокрема Bedrock Converse та відсутність function tools у Perplexity) явно описані в [контракті fixtures](../Features/ToolAndStructuredFixtures.md).
@@ -35,7 +35,7 @@ R2 тепер має реалізацію, а не лише виправленн
- Coverlet: **90,32% production line coverage** (9214/10201), поріг 90% пройдений. [HTML report](../../artifacts/coverage/report/summary.html).
- Усі **17 NuGet packages 0.1.1** зібрані повторно. Aspire — **13.5.3**.
- Зовнішній NuGet-only consumer із власним package cache й AppHost: **1 passed**. SHA-512 встановленого Aspire пакета звірено з локальним nupkg. Перевірено assets, schema-validated tool call через запакований сервіс, відкриття settings і авторизацію dashboard у Chromium. [Dashboard після авторизації](../../artifacts/package-consumer/package-dashboard-authorized.png).
-- `python3 scripts/test-release.py` — успішно: partial publish, rerun, completion marker, force та missing key.
+- `python3 scripts/verify-release.py` — успішно: partial publish, rerun, completion marker, force та missing key.
- `git diff --check` — успішно.
Логи остаточного прогону: `artifacts/fixes-20260907/tools-format-check.log`, `tools-build.log`, `tools-coverage.log`, `tools-pack.log`, `tools-package-consumer.log`. Артефакти git-ignored; CI налаштований зберігати coverage/consumer evidence.
diff --git a/docs/Testing/AcceptanceCriteriaTestInventory.md b/docs/Testing/AcceptanceCriteriaTestInventory.md
index ebacc26..1a0ef4a 100644
--- a/docs/Testing/AcceptanceCriteriaTestInventory.md
+++ b/docs/Testing/AcceptanceCriteriaTestInventory.md
@@ -1,119 +1,94 @@
-# Acceptance Criteria Test Inventory
+# Server integration acceptance inventory
-| Criterion | Coverage |
-| --- | --- |
-| Runtime matches scripted chat scenarios | `LlmTckRuntimeTests.CompleteChatAsync_MatchesScenarioAndRecordsAssertionAsync` |
-| Runtime exposes deterministic token usage on chat and video operation results | `LlmTckRuntimeTests.CompleteChatAsync_MatchesScenarioAndRecordsAssertionAsync`, `LlmTckRuntimeTests.Modalities_ReturnDeterministicDefaultsAndUseBearerTokenAsync` |
-| Runtime reports unmatched requests | `LlmTckRuntimeTests.CompleteChatAsync_ReportsUnmatchedRequestAsync` |
-| Runtime supports embeddings, images, audio, and auth | `LlmTckRuntimeTests.Modalities_ReturnDeterministicDefaultsAndUseBearerTokenAsync` |
-| Runtime rejects unknown or wrong-kind models | `LlmTckRuntimeTests.Modalities_RejectUnknownOrWrongKindModelsAsync` |
-| Runtime fault simulation applies configured content-filter and rate-limit errors across modalities | `LlmTckRuntimeTests.FaultSimulation_ReturnsContentFilterAcrossRuntimeModalitiesAsync`, `LlmTckRuntimeTests.FaultSimulation_RateLimitCountsRequestsAcrossModalitiesAndResetAsync` |
-| Runtime snapshots mutable configuration input | `LlmTckRuntimeTests.ConfigureAsync_SnapshotsMutableConfigurationAsync` |
-| Cancelled delayed chat does not consume queued response | `LlmTckRuntimeTests.CancelledDelayedChat_DoesNotConsumeScenarioResponseAsync` |
-| OpenAI-compatible endpoints expose models and modalities | `OpenAiEndpointTests.OpenAiEndpoints_ExposeModelsAndAllModalitiesAsync` |
-| Streaming endpoint emits SSE chunks and done marker | `OpenAiEndpointTests.StreamingChatCompletion_ReturnsServerSentChunksAsync` |
-| Bearer failures use OpenAI error envelope | `OpenAiEndpointTests.BearerTokenRequirement_ReturnsOpenAiErrorShapeAsync` |
-| Control endpoints require bearer token when configured | `OpenAiEndpointTests.ControlEndpoints_RequireConfiguredBearerTokenAsync` |
-| Provider endpoints reject unknown models | `OpenAiEndpointTests.ProviderEndpoints_RejectUnknownModelsAsync` |
-| Malformed chat payloads return OpenAI bad request envelope | `OpenAiEndpointTests.MalformedChatCompletion_ReturnsOpenAiBadRequestAsync` |
-| Audio speech fixture advertises a matching media type | `OpenAiEndpointTests.AudioSpeech_ReturnsTruthfulWavFixtureAsync` |
-| `IChatClient` fake follows dotnet/extensions delegate pattern | `MicrosoftExtensionsAiClientTests.TestChatClient_UsesDotnetExtensionsCallbackPatternAsync` |
-| Streaming fake follows delegate pattern | `MicrosoftExtensionsAiClientTests.TestChatClient_StreamsThroughCallbackPatternAsync` |
-| `Microsoft.Extensions.AI` clients call the compatibility server | `MicrosoftExtensionsAiClientTests.MicrosoftExtensionsAiClients_InvokeLlmTckThroughOpenAiCompatibilityEndpointsAsync` |
-| Official OpenAI SDK clients call the namespaced OpenAI API root for streaming chat | `OpenAiSdkCompatibilityTests.OpenAiChatClient_CanUseNamespacedChatStreamingAsync` |
-| Official Azure OpenAI SDK clients call deployment chat and embedding routes | `AzureSdkCompatibilityTests.AzureOpenAiClient_CanUseDeploymentChatAndEmbeddingsAsync` |
-| Azure OpenAI v1 image generation works through the official OpenAI SDK and returns image bytes | `AzureV1SdkCompatibilityTests.AzureOpenAiV1Images_UseOfficialOpenAiSdkAndReturnImageBytesAsync` |
-| Azure OpenAI deployment routes use deployment names, API keys, and documented modality envelopes | `AzureSdkCompatibilityTests.AzureOpenAiDeploymentRoutes_UseApiKeyAndDeploymentModelForModalitiesAsync` |
-| Official Azure AI Inference clients call Foundry chat and embedding routes | `AzureSdkCompatibilityTests.AzureAiInferenceClients_CanUseFoundryChatAndEmbeddingsAsync` |
-| Universal client API configures datasets, models, auth, and modality fixtures before a test | `LlmTckClientConfigurationTests.ConfigureAsync_WithFluentClientApi_LoadsDatasetAndFixturesAsync` |
-| Provider packages expose stable compatibility profiles | `ProviderPackageCatalogTests.ProviderPackages_ExposeExpectedCompatibilityProfilesAsync` |
-| Provider profiles are backed by official docs and every hosted provider route maps to a documented implemented operation | `ProviderApiContractTests.ProviderApiContracts_AreDocBackedAndCoverClaimedCapabilitiesAsync`, `ProviderApiContractTests.HostingProviderRoutes_AreCoveredByImplementedDocumentedOperationsAsync` |
-| Every implemented provider operation has behavior-test evidence, and every streaming operation has streaming evidence | `ProviderApiContractTests.ProviderBehaviorEvidence_CoversEveryImplementedOperationAsync` |
-| Provider-neutral fault simulation returns native provider error envelopes for every provider family | `ProviderFaultSimulationTests.ProviderFamilies_ReturnConfiguredContentFilterErrorsAsync`, `ProviderFaultSimulationTests.ProviderFamilies_ReturnConfiguredRateLimitErrorsAsync` |
-| Anthropic Messages API route follows the documented create-message and streaming surface | `AnthropicEndpointTests.MessagesEndpoint_ReturnsAnthropicMessageShapeAsync`, `AnthropicEndpointTests.MessagesEndpoint_StreamsAnthropicServerSentEventsAsync`, `AnthropicEndpointTests.MessagesEndpoint_RequiresAnthropicVersionHeaderAsync`, `AnthropicEndpointTests.MessagesEndpoint_AcceptsAnthropicApiKeyHeaderAsync` |
-| OpenAI-compatible provider route aliases are documented and executable for non-streaming and streaming chat | `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleChatRoutes_ReturnChatCompletionShapeAsync`, `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleChatRoutes_StreamServerSentChunksAsync`, `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleModelRoutes_ReturnModelListShapeAsync`, `OpenAiCompatibleProviderRouteTests.MistralEmbeddingRoute_ReturnsEmbeddingShapeAsync`, `OpenAiCompatibleProviderRouteTests.FoundryEmbeddingRoutes_ReturnEmbeddingShapeAsync` |
-| OpenAI-compatible Responses API routes are documented and executable for non-streaming and streaming responses | `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleResponsesRoutes_ReturnResponseShapeAsync`, `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleResponsesRoutes_StreamResponseServerSentEventsAsync` |
-| OpenAI image generation, editing, variation, and image SSE routes are documented and executable | `OpenAiEndpointTests.ImageRoutes_ReturnDocumentedEditVariationAndStreamingShapesAsync` |
-| OpenAI-compatible audio transcription routes are documented and executable for multipart input, JSON/text output, OpenAI streaming events, Groq metadata, and Azure deployment/API-key routing | `OpenAiEndpointTests.AudioTranscription_ReturnsJsonTextAndStreamingShapesAsync`, `OpenAiCompatibleProviderRouteTests.GroqAudioTranscriptionRoute_ReturnsGroqTranscriptionShapeAsync`, `OpenAiCompatibleProviderRouteTests.AzureOpenAiAudioTranscriptionRoute_UsesDeploymentModelAndApiKeyAsync` |
-| OpenAI-compatible audio translation routes are documented and executable for multipart input, JSON/text or verbose JSON output, no unsupported streaming flag, Groq metadata, and Azure deployment/API-key routing | `OpenAiEndpointTests.AudioTranslation_ReturnsJsonTextAndRejectsStreamingAsync`, `OpenAiCompatibleProviderRouteTests.GroqAudioTranslationRoute_ReturnsGroqTranslationShapeAsync`, `OpenAiCompatibleProviderRouteTests.AzureOpenAiAudioTranslationRoute_UsesDeploymentModelAndApiKeyAsync` |
-| Groq OpenAI-compatible audio speech route is documented and executable with required voice, deterministic audio bytes, and Groq-specific response-format validation | `OpenAiCompatibleProviderRouteTests.GroqAudioSpeechRoute_ReturnsAudioAndValidatesDocumentedRequestAsync` |
-| OpenAI and Azure OpenAI video routes are documented and executable for lifecycle metadata, media content, Azure preview jobs, and header-only content retrieval | `OpenAiEndpointTests.VideoRoutes_ReturnDocumentedOpenAiShapesAndValidateEnumsAsync`, `OpenAiCompatibleProviderRouteTests.AzureOpenAiVideoRoutes_FollowPreviewJobAndContentShapesAsync` |
-| Ollama and Cohere native routes follow documented chat, streaming, and embedding surfaces | `OllamaEndpointTests.ChatEndpoint_WithStreamFalse_ReturnsOllamaChatShapeAsync`, `OllamaEndpointTests.ChatEndpoint_DefaultStreamsOllamaJsonLinesAsync`, `OllamaEndpointTests.EmbedEndpoint_ReturnsOllamaEmbeddingShapeAsync`, `CohereEndpointTests.ChatEndpoint_ReturnsCohereChatShapeAsync`, `CohereEndpointTests.ChatEndpoint_StreamsCohereServerSentEventsAsync`, `CohereEndpointTests.EmbedEndpoint_ReturnsCohereEmbeddingShapeForTextsAsync`, `CohereEndpointTests.EmbedEndpoint_ReturnsCohereEmbeddingShapeForInputsAsync` |
-| Provider response envelopes expose deterministic input/output usage where the provider surface documents usage | `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleChatRoutes_ReturnChatCompletionShapeAsync`, `OpenAiCompatibleProviderRouteTests.OpenAiCompatibleResponsesRoutes_ReturnResponseShapeAsync`, `AnthropicEndpointTests.MessagesEndpoint_ReturnsAnthropicMessageShapeAsync`, `AnthropicEndpointTests.MessagesEndpoint_StreamsAnthropicServerSentEventsAsync`, `GeminiEndpointTests.GenerateContentEndpoint_ReturnsGeminiCandidateShapeAsync`, `GeminiEndpointTests.PredictLongRunningVideoEndpoint_ReturnsGeminiOperationAndGeneratedFileAsync`, `CohereEndpointTests.ChatEndpoint_ReturnsCohereChatShapeAsync`, `OllamaEndpointTests.ChatEndpoint_WithStreamFalse_ReturnsOllamaChatShapeAsync`, `BedrockEndpointTests.ConverseEndpoint_ReturnsBedrockConverseShapeAsync`, `BedrockEndpointTests.ConverseStreamEndpoint_ReturnsBedrockEventStreamShapeAsync` |
-| Gemini native routes follow documented generateContent, streamGenerateContent, embedContent, and long-running Veo video/file surfaces | `GeminiEndpointTests.GenerateContentEndpoint_ReturnsGeminiCandidateShapeAsync`, `GeminiEndpointTests.StreamGenerateContentEndpoint_ReturnsGeminiServerSentEventsAsync`, `GeminiEndpointTests.EmbedContentEndpoint_ReturnsGeminiEmbeddingShapeAsync`, `GeminiEndpointTests.PredictLongRunningVideoEndpoint_ReturnsGeminiOperationAndGeneratedFileAsync` |
-| Bedrock native runtime routes follow documented Converse, ConverseStream, InvokeModel, and InvokeModelWithResponseStream envelopes | `BedrockEndpointTests.ConverseEndpoint_ReturnsBedrockConverseShapeAsync`, `BedrockEndpointTests.ConverseStreamEndpoint_ReturnsBedrockEventStreamShapeAsync`, `BedrockEndpointTests.InvokeEndpoint_ReturnsTitanTextShapeForChatModelAsync`, `BedrockEndpointTests.InvokeModelWithResponseStreamEndpoint_ReturnsChunkBytesAsync`, `BedrockEndpointTests.InvokeEndpoint_ReturnsTitanEmbeddingShapeForEmbeddingModelAsync`, `BedrockEndpointTests.InvokeEndpoint_ReturnsImageShapeForImageModelAsync` |
-| Aspire AppHost is built in test code, adds the package-owned TCK with `builder.AddLlmTck()`, resolves the provider URL from the Aspire resource endpoint, configures API key auth, starts the packaged .NET service without Docker, and serves implemented modalities plus official Azure SDK clients | `AspireIntegrationTests.AddLlmTck_BuildsAppHostInTestAndSupportsConfiguredClientsAsync` |
-
-## September 2026 provider API refresh
-
-- `AzureV1SdkCompatibilityTests.V1ChatAndEmbeddings_UseOfficialSdkWithoutApiVersionAsync`: Azure OpenAI and Microsoft Foundry v1 chat, streaming and base64 embeddings through the official OpenAI SDK, without a dated API version.
-- `AzureV1SdkCompatibilityTests.V1Responses_UseOfficialSdkAndStreamAsync`: OpenAI, Azure OpenAI and Foundry Responses parsed and streamed through OpenAI 2.13.0.
-- `AzureV1SdkCompatibilityTests.AzureOpenAiV1Images_UseOfficialOpenAiSdkAndReturnImageBytesAsync`: Azure OpenAI v1 image generation routed through the official OpenAI SDK with nonempty returned bytes.
-- `AzureV1SdkCompatibilityTests.V1Responses_AcceptsApiKeyAndRejectsMissingCredentialsAsync`: Azure v1 API-key authentication and unauthorized requests preserving the response queue.
-- `ProviderApiDriftTests.OpenRouterResponses_RejectsStateBeforeConsumingScenarioAsync`: stateless Responses validation, including an empty non-null previous response ID.
-- `ProviderApiDriftTests.OllamaChat_ReportsCacheReadsInFinalStreamingChunkAsync`: cold and cached requests, with cache accounting on the final NDJSON chunk.
-- `ProviderApiDriftTests.AnthropicZeroMaxTokens_WarmsCacheWithoutConsumingResponseAsync`: cache-only requests in JSON and SSE modes, zero output, and preserved scripted response.
-- `ProviderApiDriftTests.GeminiStreaming_PreservesResponseIdAndReasoningUsageAsync`: JSON/default/SSE transport, stable response ID, distinct thought tokens and final total accounting.
-- `ProviderApiDriftTests.ResponsesStreaming_UsesDocumentedEventsAndStableItemIdentityAsync`: complete Responses text event lifecycle, monotonically increasing sequence numbers and one output item ID across OpenAI, Groq and OpenRouter.
-- `BedrockEndpointTests.ConverseStreamEndpoint_ReturnsBedrockEventStreamShapeAsync` and `InvokeModelWithResponseStreamEndpoint_ReturnsChunkBytesAsync`: binary AWS event-stream decoded by the AWS SDK, including fragmented headers, payload and CRC checksums.
-
-- `BedrockSdkCompatibilityTests.ConverseStream_OfficialSdkReadsTextAndUsageAsync`: the official AmazonBedrockRuntimeClient parses the hosted binary stream into typed text, usage and stop events.
-
-`BedrockEndpointTests.StreamingEndpoints_RejectInvalidRequestsWithoutConsumingFixtureAsync` verifies malformed, null and incomplete JSON plus unauthorized calls on both binary streaming routes; a subsequent authenticated request still receives the configured response.
+Only integration tests are accepted: start the server, call its public HTTP endpoints or real provider SDKs,
+and inspect public responses/control APIs. Test setup may build explicit fixtures, but assertions must prove
+observable server behavior. Source/document scans, fake clients, reflection guards and direct runtime unit tests
+have been removed. This inventory is documentation; tests do not read it to assert that method names appear here.
-## Project review regressions
+## Existing executable flows
-| Acceptance criterion | Evidence |
+| Contract | Integration evidence |
| --- | --- |
-| Pre-cancelled/concurrently cancelled calls preserve unconsumed responses | `ReviewRuntimeRegressionTests` |
-| Dataset-local scenario IDs stay independent | `ReviewRuntimeRegressionTests.SameLocalScenarioId_RemainsIndependentAcrossDatasetsAndResetAsync` |
-| Errors before generation have zero output/reasoning tokens | `ReviewRuntimeRegressionTests.RejectedAndScriptedErrorRequests_DoNotGenerateReasoningOrOutputUsageAsync` |
-| Prompt cache has deterministic capacity/eviction | `ReviewRuntimeRegressionTests.PromptCache_EvictsOldestPrefixAtConfiguredCapacityAsync` |
-| Invalid configuration preserves the previous runtime and traces | `ReviewHttpRegressionTests.InvalidConfigure_PreservesConfigurationAndTracesAsync` |
-| Azure SDK default supports deployment chat, streaming and embeddings without a pinned version | `AzureSdkCompatibilityTests.AzureOpenAiClient_CanUseDeploymentChatAndEmbeddingsAsync` |
-| Documented GA and preview API versions are accepted; unknown date-shaped versions are rejected before queue consumption | `ReviewHttpRegressionTests.AzureLegacyVersion_AcceptsDocumentedStableAndPreviewVersionsAsync` |
-| Nested null provider inputs and malformed Azure versions return 400 | `ReviewHttpRegressionTests` |
-| Streaming and MEAI usage survive to callers | `ReviewHttpRegressionTests.StreamingUsage_IsOptInAndFollowsTerminalChoiceAsync`, `ChatClient_PreservesUsageAndTerminalUpdate_EmbeddingsPreserveUsageAsync` |
-| Legacy function options fail explicitly; implemented tools/schema retain full behavior | `ReviewCapabilityRegressionTests.LegacyFunctions_ReturnExplicitErrorWithoutConsumingFixtureAsync`, `ToolFixtureEndpointTests`, `ToolFixtureClientTests` |
-| Tool selection, argument/schema mismatch and malformed history preserve the queue | `ToolFixtureValidationTests` |
-| Multiple calls, mixed text/tool blocks, snapshots and cache keys retain tool data | `ToolFixtureStateTests` |
-| Foundry inference requires its documented API version | `ReviewHttpRegressionTests.FoundryInference_RequiresDocumentedVersionWithoutConsumingQueueAsync` |
-| Stored OpenAI/Azure video lifecycle and content respect deletion/reset | `ReviewVideoRegressionTests` |
-| Actual Aspire NuGet contains assets and interactive dashboard works | `scripts/package-consumer/PackageTests.cs`, executed by `scripts/verify-package.py` outside the repository |
-| Interrupted NuGet publishing remains resumable | `scripts/test-release.py` with local fake CLIs |
+| Default models, chat, embeddings, images, audio | `OpenAiEndpointTests.OpenAiEndpoints_ExposeModelsAndAllModalitiesAsync` |
+| JSON and native SSE streaming, usage, terminal events | `OpenAiEndpointTests`, `OpenAiSdkCompatibilityTests`, `OpenAiCompatibleProviderRouteTests` |
+| Fixed output tokenizer counts exposed on response and journal | `LlmTestServerTokenCounterTests.ChatResponse_ReportsConfiguredOutputTokenUsageThroughHttpAsync` |
+| Reasoning and prompt-cache usage | `OpenAiEndpointTests`, `AnthropicEndpointTests`, `GeminiEndpointTests`, `BedrockEndpointTests`, `ProviderApiDriftTests` |
+| Auth, malformed bodies, unknown models, required parameters | `OpenAiEndpointTests`, `ProviderValidationBoundaryTests`, `ReviewHttpRegressionTests` |
+| Configure/reset/assertions through typed control client | `OpenAiEndpointTests.ControlClient_ConfiguresReadsAssertionsAndResetsRuntimeAsync` |
+| Invalid configuration preserves the active runtime after HTTP 400 | `ConfigurationBoundaryIntegrationTests` |
+| Per-modality auth, wrong model kind, content filter, rate limit and reset | `ModalityFailureIntegrationTests` |
+| Stored response credential/provider isolation, count/byte capacity, store=false and reset/configure | `ResponseHistoryIntegrationTests` |
+| Exact conversation order, scenario credentials, exhaustion and cancellation/retry | `ScenarioFlowIntegrationTests` |
+| Parallel session queues, reset/configure, credentials and admission/disposal | `SessionIsolationIntegrationTests`, `SessionBoundaryIntegrationTests` |
+| Session response history, video/fault state, cancellation and in-flight deletion | `SessionStateIntegrationTests` |
+| Session provider matrix, official SDK JSON/SSE, native decisions, cache and journal limits | `SessionProviderIntegrationTests` |
+| Conversation branches, turns, JSON predicates, tools, replay, exhaustion and invalid graph/configuration | `ConversationHttpIntegrationTests` |
+| Conversation official SDK tool loops, Responses history/replay and streaming | `ConversationSdkIntegrationTests` |
+| Conversation provider/credential/session isolation, cancellation and in-flight mutation | `ConversationProviderIntegrationTests` |
+| Client model presets actually reach the server | `LlmTestServerClientConfigurationTests` |
+| MEAI chat, embedding and image clients call the server | `MicrosoftExtensionsAiClientTests.MicrosoftExtensionsAiClients_InvokeLlmTestServerThroughOpenAiCompatibilityEndpointsAsync` |
+| Official OpenAI SDK chat, Responses, tools, embeddings and modalities | `OpenAiSdkCompatibilityTests`, `ToolFixtureClientTests` |
+| Azure OpenAI deployment endpoints through official SDK | `AzureSdkCompatibilityTests` |
+| Azure/Foundry v1 endpoints through official clients | `AzureV1SdkCompatibilityTests`, `V1AudioTranscriptionCompatibilityTests` |
+| Foundry inference version and auth requirements | `AzureSdkCompatibilityTests`, `ReviewHttpRegressionTests.FoundryInference_RequiresDocumentedVersionWithoutConsumingQueueAsync` |
+| Anthropic Messages, SSE, tool history, cache | `AnthropicEndpointTests`, `ToolFixtureEndpointTests` |
+| Gemini generation, stream, embedding, video, schema options | `GeminiEndpointTests`, `FollowUpEndpointTests`, `ProviderApiDriftTests` |
+| Cohere/Ollama native chat and embedding | `CohereEndpointTests`, `OllamaEndpointTests` |
+| Bedrock Converse/Invoke and native binary event streams | `BedrockEndpointTests`, `BedrockSdkCompatibilityTests` |
+| OpenAI-compatible provider namespaces and documented operations | `OpenAiCompatibleProviderRouteTests` |
+| Provider-neutral rate limit and content filter errors | `ProviderFaultSimulationTests` |
+| Tool/schema operation variants, JSON and streaming, negative then successful recovery | `ProviderCapabilityEvidenceTests.ClaimedToolAndSchemaCases_ExecutePositiveAndNegativeHttpEvidenceAsync` |
+| Tool selection, local references, invalid arguments, structured stream concatenation | `ToolFixtureValidationTests` |
+| Parallel-tool request limits and malformed-schema/nullable/nested constraints | `FollowUpEndpointTests`, `ToolFixtureClientTests` |
+| Official SDK/MEAI function invocation, tool-result continuation and model changes | `ToolFixtureClientTests`, `LlmTestServerResponsesContinuationTests` |
+| Video CRUD/content/delete/reset/provider isolation | `ReviewVideoRegressionTests`, `OpenAiEndpointTests`, `AzureSdkCompatibilityTests` |
+| Native Jev/Kev/OpenAI/Clef responses, errors, images, bounds and parameter variants | `DecisionEndpointTests`, `DecisionRuntimeTests`, `DecisionValidationTests`, `DecisionQuestionTests`, `DecisionInputTests`, `DecisionFixtureContractTests` |
+| Jev multipart/image/box/long-context contracts | `Jev114EndpointTests`, `Jev114MultipartTests`, `TypeSafeVisionContractTests` |
+| Native Clef image/scalar/error envelopes and typed client | `CloudflareDecisionContractTests`, `CloudflareDecisionErrorTests`, `CloudflareDecisionImageTests`, `CloudflareNativeClientTests` |
+| Native Kev formatting and required/optional request fields over HTTP | `SystemOneNativeContractTests` |
+| Dashboard root HTML and request/response presentation | `AdminPanelTests` |
+| Real cache miss/hit, reasoning subsets, explicit conversation correlation and unknown usage over HTTP | `DashboardAnalyticsIntegrationTests` |
+| Per-role input composition (system, user, assistant, tool calls, tool results, tool schemas) reconciles with OpenAI and Anthropic wire usage and drives the dashboard token flow and context mix | `DashboardAnalyticsIntegrationTests` |
+| Stored-response capacity rejection preserves queue/graph and does not warm or evict cache | `StoredResponseAdmissionIntegrationTests` |
+| Cache isolation across provider namespaces and independent sessions | `PromptCacheNamespaceIntegrationTests` |
+| Longest retained prefix is checked before FIFO eviction; cache-off mode stays inactive | `PromptCacheCapacityIntegrationTests` |
+| Request/conversation analytics totals, repeated tool-result context, unlabeled-request isolation and first-viewport readability | `scripts/package-consumer/PackageTests.cs` (genuine SDK and Chromium) |
+| Public request journal auth, all filter/paging parameters, validation, reset | `RequestJournalIntegrationTests` |
+| Bounded request/response diagnostics preserve full HTTP response bytes | `RequestJournalIntegrationTests.Journal_BoundsRetentionWithoutTruncatingActualProviderResponsesAsync` |
+| Request query filters, order, JSON/NDJSON export, retention/eviction/reset and active-request evidence | `RequestQueryExportIntegrationTests` |
+| Counts/order/no-unexpected-calls, structured tool/result predicates and graph expectations | `VerificationIntegrationTests` |
+| Retry group/status/count, advertised Retry-After and real monotonic wait compliance | `VerificationIntegrationTests` |
+| Incomplete evidence after eviction/truncation/paging/pending requests cannot pass | `VerificationIntegrationTests` |
+| Seed/fixed clock/reset/replay, provider-local ordinals, session isolation and real observations | `DeterminismIntegrationTests` |
+| Native Anthropic/Gemini/Cohere/Ollama JSON/stream identity, embedding/image/Groq audio metadata | `NativeDeterminismIntegrationTests` |
+| Aspire starts packaged service and exercises official SDKs through allocated endpoint | `AspireIntegrationTests` |
+| Configuration key enforced by running Aspire server | `AspireAuthorizationIntegrationTests` |
+| Installed NuGet assets, typed configuration, official SDK and interactive Chromium dashboard | `scripts/package-consumer/PackageTests.cs`, run by `scripts/verify-package.py` with isolated build configuration/cache |
+| Actual public GitHub release and all NuGet bytes | `scripts/verify-release.py`, executed after publication |
+| Clean public-feed installed consumer | `scripts/verify-package.py --public-feed`, executed after publication |
-## Follow-up review regressions (2026-09-08)
+## Qualification and remaining delivery
-- `FollowUpRuntimeTests.SummaryMutations_CannotChangeRetainedMessagesOrChunksAsync`: mutation of returned snapshots cannot alter retained diagnostics.
-- `FixtureMismatch_IsCountedAndJournaledWithoutConsumingResponseAsync`: mismatch status, usage, journal correlation and queue recovery.
-- `ExactMatch_RejectsUnexpectedToolMetadataWhileContainsKeepsWildcardsAsync`: null/empty tool metadata is strict under Exact.
-- `FollowUpEndpointTests.ParallelTools_RespectRequestLimitAndPreserveQueueAsync`: OpenAI Chat/Responses and Anthropic, JSON and streaming.
-- `ChatModel_IsRequiredExceptForAzureDeploymentRoutesAsync`: required wire model and deployment URL exception.
-- `GeminiSchema_ValidatesNullableNestedAlternativesAndStringLimitsAsync` and `FollowUpSchemaTests`: nullable, all six int64 limits, nested alternatives, parameters, JSON Schema separation and malformed-schema rejection.
-- `VideoCapacity_RejectsOverflowAndReclaimsDeletedBytesAsync`, `VideoCapacity_ValidatesConfigurationAndHandlesOversizedOrFailedResultsAsync`, `VideoCapacity_ReturnsConflictThroughProviderEndpointAsync`: count/byte overflow, cross-provider budget, reset/configure/delete and HTTP failures.
-- `ToolFixtureClientTests.ExtensionsAi_RespectsSingleToolOptionWithoutConsumingFixtureAsync`: MEAI parallel option, both response modes.
-- `ProviderCapabilityEvidenceTests.ClaimedToolAndSchemaCases_ExecutePositiveAndNegativeHttpEvidenceAsync`: all 13 provider profiles, every claimed tool/schema operation, supported JSON/stream modes, accept/reject outcomes with queue recovery and journal checks.
-- `EvidenceGuard_RequiresExecutableProviderAndEdgeCasesAsync`: executable test attributes, complete provider arguments, named Gemini cases and all six parallel-option cases are mandatory.
+E4 local qualification passed **812/812** running-server integrations, **91.66%** production line coverage and a
+final canonical Release build with **0 warnings / 0 errors**. All **19 packages** packed successfully. The
+independent clean installed NuGet consumer ran the packaged Aspire service, official SDKs, E4 typed
+query/export/verification/fixed metadata and interactive Chromium acceptance (**1/1**).
+Evidence logs: `artifacts/delivery/e4-build-final.log`, `e4-coverage-final.log`, `e4-pack.log`, `e4-consumer.log`.
-## v1 audio transcription and usage
+E3 [CI 39446187097](https://github.com/managedcode/LlmTestServer/actions/runs/39446187097) passed at `3aae4db`.
+E4 has not yet been pushed to branch CI. Local NuGet acceptance does not prove public-feed publication.
+The [delivery plan](../Features/LlmTestServerDeliveryPlan.md) retains E5–E13, public NuGet/GHCR and launch
+acceptance as unfinished. Add actual server flows for new behavior and preserve the 90% coverage gate.
-| Criterion | Automated evidence |
-|---|---|
-| Azure OpenAI, Foundry and OpenAI multipart transcription works through the official SDK; control configuration survives transport and MEAI retains duration / complete token usage. | `V1AudioTranscriptionCompatibilityTests.OfficialSdk_PreservesTranscriptionUsageAsync` |
-| Streaming transcription retains configured usage in its final event. | `V1AudioTranscriptionCompatibilityTests.Streaming_PreservesFinalUsageAsync` |
-| Azure/Foundry v1 audio enforces credentials, accepts default/v1/preview, denies unknown/duplicate versions and missing files, and returns actual fixture duration in verbose JSON. | `V1AudioTranscriptionCompatibilityTests.V1Audio_EnforcesAuthAndVersionAndSupportsVerboseJsonAsync` |
-| Malformed duration or incomplete/mixed/overflow token configuration fails before use. | `TranscriptionUsageConfigurationTests` |
+Each implemented operation must be exercised with every supported parameter, positive and invalid/boundary
+values, supported streaming modes, auth/version handling and stateful continuation where applicable. A passing
+subset or this inventory alone does not establish full parameter coverage. New provider claims require official
+method-level contracts plus passing HTTP/SDK behavior evidence.
-| Native Jev/Kev, Clef/flash and OpenAI Decisions preserve fixture probabilities, native score, usage and tracing | `DecisionEndpointTests.NativeDecisionEndpoints_PreserveAnswersAndUsageAsync` |
-| Jev 1.14 JSON images, mixed and box-only answers, structured legends and native image opt-in validation | `Jev114EndpointTests.Jev114_JsonImagesAndBoxPreserveNativeAnswersAsync`, `Jev114EndpointTests.Jev114_RejectsInvalidImageAndBoxRequestsAsync` |
-| Jev typed client handles JSON/multipart images, format inference, part precedence, physical byte limits and native part/header failures | `Jev114MultipartTests.Jev114_TypedClientSupportsJsonAndMultipartImagesAsync`, `Jev114MultipartTests.Jev114_MultipartRejectsNativePartViolationsAsync`, `Jev114MultipartTests.Jev114_MultipartEnforcesPhysicalBodyAndImageByteLimitsAsync`, `Jev114MultipartTests.Jev114_MultipartInfersFormatAndPrefersPartOverBase64Async` |
-| Decision routes enforce authentication, simulated faults, required fields and fixture mismatch | `DecisionEndpointTests.NativeDecisionEndpoints_EnforceAuthAndFaultsAsync`, `DecisionEndpointTests.NativeDecisionEndpoints_RejectMissingRequiredFieldsAsync`, `DecisionEndpointTests.DecisionControlClient_ConfiguresFixturesAndMismatchIsObservableAsync` |
+## Native OpenAI Responses web search
-| Native OpenAI positional names, typed choices, score labels and message/image input constraints | `DecisionQuestionTests`, `DecisionInputTests` |
+The `OpenAI/NativeWebSearch*IntegrationTests.cs` suites exercise the running server through HTTP and the official Responses SDK: typed ordered outputs, citations, native SSE lifecycle, options and schema rejection, mixed function rounds, explicit/stored continuation, cache accounting, ownership, reset/cancellation, replay and bounded diagnostics. Initial qualification: 99/99 native cases and 85/85 existing provider evidence cases. The installed-package consumer adds an independent `NativePackageTests` flow; container verification covers native JSON/SSE and terminal request evidence. See [the exact supported subset and qualification](../Features/OpenAiNativeWebSearch.md). Ordinary function-only responses retain their existing output limits and are covered separately by the large-response regression.
-| Native OpenAI choice values preserve strings beyond question text limits and usage defaults stay present | `DecisionQuestionTests.OpenAiQuestions_PreserveChoiceValuesWithoutUndocumentedTextLimitAsync`, `DecisionEndpointTests.NativeDecisionEndpoints_PreserveAnswersAndUsageAsync` |
+## Native OpenAI file-search and code fixtures
-| Native SystemOne profile-specific JSON/defaults, empty IDs, rendered Kev legends, request IDs, latency/truncation, validation422 and predicate field filtering | `SystemOneNativeContractTests` |
-| Native required confidence, complete probability domains, rounding tolerance, explicit malformed-response scenarios | `DecisionFixtureContractTests` |
-| Cloudflare image formats/body/dimension limits, native numeric errors, whitespace selectors and null criteria | `CloudflareDecisionContractTests`, `CloudflareDecisionImageTests`, `CloudflareDecisionErrorTests` |
-| Clef and Clef Flash binary criterion values accept native JSON scalars without loosening TypeSafe state/instruction/criterion validation | `CloudflareDecisionContractTests.PredicateCriteria_AcceptsNativeJsonScalarsWithoutWeakeningTypeSafeAsync` |
+The eleven `OpenAI/NativeFileCode*IntegrationTests.cs` files run 191 HTTP/official SDK cases for the independent gpt-4o-mini file-search and gpt-4.1 code-interpreter contracts: JSON/SSE, typed ordered citations, options and every supported filter operator, exact numeric comparisons, resource matching, include projection, continuation/replay, isolation, invalid-ID normalization, atomic configuration, cache read/miss and request export. Expanded web regression coverage is 105/105, including valid unused include selectors. The independent code-only full server gate passed 1158/1158 with 92.21% line coverage; see [the bounded contract and delivery evidence](../Features/OpenAiNativeFileCode.md).
diff --git a/docs/images/admin-dashboard-cache-analytics.jpg b/docs/images/admin-dashboard-cache-analytics.jpg
new file mode 100644
index 0000000..a763eca
Binary files /dev/null and b/docs/images/admin-dashboard-cache-analytics.jpg differ
diff --git a/docs/images/admin-dashboard-conversation.jpg b/docs/images/admin-dashboard-conversation.jpg
index cd287d8..c4c5640 100644
Binary files a/docs/images/admin-dashboard-conversation.jpg and b/docs/images/admin-dashboard-conversation.jpg differ
diff --git a/docs/images/admin-dashboard-insights.jpg b/docs/images/admin-dashboard-insights.jpg
new file mode 100644
index 0000000..3884748
Binary files /dev/null and b/docs/images/admin-dashboard-insights.jpg differ
diff --git a/docs/images/admin-dashboard-mobile-request-detail.png b/docs/images/admin-dashboard-mobile-request-detail.png
index 617c133..e2b4546 100644
Binary files a/docs/images/admin-dashboard-mobile-request-detail.png and b/docs/images/admin-dashboard-mobile-request-detail.png differ
diff --git a/docs/images/admin-dashboard-overview.jpg b/docs/images/admin-dashboard-overview.jpg
index 1110911..e2e33cb 100644
Binary files a/docs/images/admin-dashboard-overview.jpg and b/docs/images/admin-dashboard-overview.jpg differ
diff --git a/docs/images/admin-dashboard-runtime.jpg b/docs/images/admin-dashboard-runtime.jpg
index 1dde163..ecafcd1 100644
Binary files a/docs/images/admin-dashboard-runtime.jpg and b/docs/images/admin-dashboard-runtime.jpg differ
diff --git a/docs/images/admin-dashboard-token-usage.png b/docs/images/admin-dashboard-token-usage.png
index 0ed63b4..05a3d15 100644
Binary files a/docs/images/admin-dashboard-token-usage.png and b/docs/images/admin-dashboard-token-usage.png differ
diff --git a/docs/images/showcase-conversation.jpg b/docs/images/showcase-conversation.jpg
new file mode 100644
index 0000000..c295eec
Binary files /dev/null and b/docs/images/showcase-conversation.jpg differ
diff --git a/docs/images/showcase-insights.jpg b/docs/images/showcase-insights.jpg
new file mode 100644
index 0000000..7c17dad
Binary files /dev/null and b/docs/images/showcase-insights.jpg differ
diff --git a/docs/images/showcase-overview.jpg b/docs/images/showcase-overview.jpg
new file mode 100644
index 0000000..e7e4420
Binary files /dev/null and b/docs/images/showcase-overview.jpg differ
diff --git a/docs/images/showcase-token-flow.jpg b/docs/images/showcase-token-flow.jpg
new file mode 100644
index 0000000..90a9214
Binary files /dev/null and b/docs/images/showcase-token-flow.jpg differ
diff --git a/samples/AGENTS.md b/samples/AGENTS.md
index cd24094..b970774 100644
--- a/samples/AGENTS.md
+++ b/samples/AGENTS.md
@@ -2,6 +2,6 @@
Samples must stay runnable and minimal. They are examples of the public API, not hidden test fixtures.
-Use the existing `ManagedCode.LlmTck.Hosting` service-defaults methods for Aspire health and liveness endpoints. Do not add a separate ServiceDefaults sample project, ad hoc `app.MapGet("/health", ...)`, or placeholder root status endpoints to sample `Program.cs` files.
+Use the existing `ManagedCode.LlmTestServer.Hosting` service-defaults methods for Aspire health and liveness endpoints. Do not add a separate ServiceDefaults sample project, ad hoc `app.MapGet("/health", ...)`, or placeholder root status endpoints to sample `Program.cs` files.
-When changing the sample service or AppHost, run the Aspire integration test in `tests/ManagedCode.LlmTck.Tests`.
+When changing the sample service or AppHost, run the Aspire integration test in `tests/ManagedCode.LlmTestServer.Tests`.
diff --git a/samples/ManagedCode.LlmTck.AppHost/aspire.config.json b/samples/ManagedCode.LlmTck.AppHost/aspire.config.json
deleted file mode 100644
index fa80579..0000000
--- a/samples/ManagedCode.LlmTck.AppHost/aspire.config.json
+++ /dev/null
@@ -1,5 +0,0 @@
-{
- "appHost": {
- "path": "ManagedCode.LlmTck.AppHost.csproj"
- }
-}
diff --git a/samples/ManagedCode.LlmTck.Service/Dockerfile b/samples/ManagedCode.LlmTck.Service/Dockerfile
deleted file mode 100644
index 080052b..0000000
--- a/samples/ManagedCode.LlmTck.Service/Dockerfile
+++ /dev/null
@@ -1,21 +0,0 @@
-FROM mcr.microsoft.com/dotnet/sdk:10.0 AS build
-WORKDIR /src
-
-COPY . .
-RUN dotnet publish samples/ManagedCode.LlmTck.Service/ManagedCode.LlmTck.Service.csproj \
- --configuration Release \
- --output /app/publish \
- /p:UseAppHost=false
-
-FROM mcr.microsoft.com/dotnet/aspnet:10.0
-WORKDIR /app
-
-LABEL org.opencontainers.image.source="https://github.com/managedcode/LlmTck" \
- org.opencontainers.image.description="ManagedCode LLM TCK HTTP service" \
- org.opencontainers.image.licenses="MIT"
-
-ENV ASPNETCORE_URLS=http://+:8080
-EXPOSE 8080
-
-COPY --from=build /app/publish .
-ENTRYPOINT ["dotnet", "ManagedCode.LlmTck.Service.dll"]
diff --git a/samples/ManagedCode.LlmTck.Service/ManagedCode.LlmTck.Service.csproj b/samples/ManagedCode.LlmTck.Service/ManagedCode.LlmTck.Service.csproj
deleted file mode 100644
index 6ab52a0..0000000
--- a/samples/ManagedCode.LlmTck.Service/ManagedCode.LlmTck.Service.csproj
+++ /dev/null
@@ -1,12 +0,0 @@
-
-
- false
- true
- false
-
-
-
-
-
-
-
diff --git a/samples/ManagedCode.LlmTck.AppHost/AppHost.cs b/samples/ManagedCode.LlmTestServer.AppHost/AppHost.cs
similarity index 65%
rename from samples/ManagedCode.LlmTck.AppHost/AppHost.cs
rename to samples/ManagedCode.LlmTestServer.AppHost/AppHost.cs
index 5929143..dd244e0 100644
--- a/samples/ManagedCode.LlmTck.AppHost/AppHost.cs
+++ b/samples/ManagedCode.LlmTestServer.AppHost/AppHost.cs
@@ -1,9 +1,9 @@
-using ManagedCode.LlmTck.Aspire;
+using ManagedCode.LlmTestServer.Aspire;
var builder = DistributedApplication.CreateBuilder(args);
builder
- .AddLlmTck()
+ .AddLlmTestServer()
.WithApiKey("test-key");
builder.Build().Run();
diff --git a/samples/ManagedCode.LlmTck.AppHost/ManagedCode.LlmTck.AppHost.csproj b/samples/ManagedCode.LlmTestServer.AppHost/ManagedCode.LlmTestServer.AppHost.csproj
similarity index 74%
rename from samples/ManagedCode.LlmTck.AppHost/ManagedCode.LlmTck.AppHost.csproj
rename to samples/ManagedCode.LlmTestServer.AppHost/ManagedCode.LlmTestServer.AppHost.csproj
index 52bdb53..8ccca26 100644
--- a/samples/ManagedCode.LlmTck.AppHost/ManagedCode.LlmTck.AppHost.csproj
+++ b/samples/ManagedCode.LlmTestServer.AppHost/ManagedCode.LlmTestServer.AppHost.csproj
@@ -9,6 +9,6 @@
-
+
diff --git a/samples/ManagedCode.LlmTck.AppHost/Properties/launchSettings.json b/samples/ManagedCode.LlmTestServer.AppHost/Properties/launchSettings.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.AppHost/Properties/launchSettings.json
rename to samples/ManagedCode.LlmTestServer.AppHost/Properties/launchSettings.json
diff --git a/samples/ManagedCode.LlmTck.AppHost/appsettings.Development.json b/samples/ManagedCode.LlmTestServer.AppHost/appsettings.Development.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.AppHost/appsettings.Development.json
rename to samples/ManagedCode.LlmTestServer.AppHost/appsettings.Development.json
diff --git a/samples/ManagedCode.LlmTck.AppHost/appsettings.json b/samples/ManagedCode.LlmTestServer.AppHost/appsettings.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.AppHost/appsettings.json
rename to samples/ManagedCode.LlmTestServer.AppHost/appsettings.json
diff --git a/samples/ManagedCode.LlmTestServer.AppHost/aspire.config.json b/samples/ManagedCode.LlmTestServer.AppHost/aspire.config.json
new file mode 100644
index 0000000..14a5dd6
--- /dev/null
+++ b/samples/ManagedCode.LlmTestServer.AppHost/aspire.config.json
@@ -0,0 +1,5 @@
+{
+ "appHost": {
+ "path": "ManagedCode.LlmTestServer.AppHost.csproj"
+ }
+}
diff --git a/samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj b/samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj
new file mode 100644
index 0000000..a1ec528
--- /dev/null
+++ b/samples/ManagedCode.LlmTestServer.Service/ManagedCode.LlmTestServer.Service.csproj
@@ -0,0 +1,31 @@
+
+
+ false
+ true
+ false
+ true
+ linux-x64;linux-arm64
+ linux-x64;linux-arm64
+ mcr.microsoft.com/dotnet/aspnet:10.0
+ managedcode/llm-test-server
+ $(Version)
+ OCI
+ 1654
+ /app/
+ false
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
diff --git a/samples/ManagedCode.LlmTck.Service/Program.cs b/samples/ManagedCode.LlmTestServer.Service/Program.cs
similarity index 76%
rename from samples/ManagedCode.LlmTck.Service/Program.cs
rename to samples/ManagedCode.LlmTestServer.Service/Program.cs
index f84e3ff..cd32198 100644
--- a/samples/ManagedCode.LlmTck.Service/Program.cs
+++ b/samples/ManagedCode.LlmTestServer.Service/Program.cs
@@ -1,5 +1,5 @@
-using ManagedCode.LlmTck.Hosting;
-using ManagedCode.LlmTck.Models;
+using ManagedCode.LlmTestServer.Hosting;
+using ManagedCode.LlmTestServer.Models;
var builder = WebApplication.CreateBuilder(args);
builder.AddServiceDefaults();
@@ -17,8 +17,8 @@
builder.WebHost.ConfigureKestrel(options => options.ListenAnyIP(port));
}
-var requiredBearerToken = builder.Configuration["LlmTck:RequiredBearerToken"];
-builder.Services.AddLlmTck(options =>
+var requiredBearerToken = LlmTestServerHostingConfiguration.GetRequiredBearerToken(builder.Configuration);
+builder.Services.AddLlmTestServer(options =>
{
options.AddDefaultOpenAiModels();
@@ -30,7 +30,7 @@
options.AddChatScenario(
"default-blue-whale",
scenario => scenario
- .ForModel(LlmTckKnownModelIds.Gpt41Mini)
+ .ForModel(LlmTestServerKnownModelIds.Gpt41Mini)
.WhenUserContains("color")
.Responds("blue whale", "blue ", "whale")
.Responds("blue whale", "blue ", "whale")
@@ -40,5 +40,5 @@
var app = builder.Build();
app.MapDefaultEndpoints();
-app.MapLlmTck();
+app.MapLlmTestServer();
app.Run();
diff --git a/samples/ManagedCode.LlmTck.Service/Properties/launchSettings.json b/samples/ManagedCode.LlmTestServer.Service/Properties/launchSettings.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.Service/Properties/launchSettings.json
rename to samples/ManagedCode.LlmTestServer.Service/Properties/launchSettings.json
diff --git a/samples/ManagedCode.LlmTck.Service/appsettings.Development.json b/samples/ManagedCode.LlmTestServer.Service/appsettings.Development.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.Service/appsettings.Development.json
rename to samples/ManagedCode.LlmTestServer.Service/appsettings.Development.json
diff --git a/samples/ManagedCode.LlmTck.Service/appsettings.json b/samples/ManagedCode.LlmTestServer.Service/appsettings.json
similarity index 100%
rename from samples/ManagedCode.LlmTck.Service/appsettings.json
rename to samples/ManagedCode.LlmTestServer.Service/appsettings.json
diff --git a/scripts/coverage.sh b/scripts/coverage.sh
index 93f2112..1e09cbb 100644
--- a/scripts/coverage.sh
+++ b/scripts/coverage.sh
@@ -3,26 +3,26 @@ set -euo pipefail
mkdir -p artifacts/coverage/raw
# CI normalizes PDB paths. Resolve them back to this checkout without disabling
# source filtering or the 90% gate (Coverlet console does not create this map).
-dotnet msbuild tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj \
+dotnet msbuild tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj \
-nologo -target:InitializeSourceRootMappedPaths -getItem:SourceRoot \
-p:Configuration=Release -p:ContinuousIntegrationBuild=true > artifacts/coverage/source-roots.json
python3 - <<'PYMAP'
import json
from pathlib import Path
roots = json.loads(Path("artifacts/coverage/source-roots.json").read_text())["Items"]["SourceRoot"]
-project = Path("tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj").resolve()
+project = Path("tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj").resolve()
Path("artifacts/coverage/source-roots.map").write_text("".join(
f"{project}|{root['Identity']}={root['MappedPath']}\n"
for root in roots if root.get("MappedPath")
))
PYMAP
-dotnet tool run coverlet tests/ManagedCode.LlmTck.Tests/bin/Release/net10.0/ManagedCode.LlmTck.Tests.dll \
+dotnet tool run coverlet tests/ManagedCode.LlmTestServer.Tests/bin/Release/net10.0/ManagedCode.LlmTestServer.Tests.dll \
--target dotnet \
- --targetargs "test --project tests/ManagedCode.LlmTck.Tests/ManagedCode.LlmTck.Tests.csproj --configuration Release --no-build --verbosity normal" \
+ --targetargs "test --project tests/ManagedCode.LlmTestServer.Tests/ManagedCode.LlmTestServer.Tests.csproj --configuration Release --no-build --verbosity normal" \
--source-mapping-file artifacts/coverage/source-roots.map \
--format cobertura --format json --output artifacts/coverage/raw/coverage \
- --include '[ManagedCode.LlmTck]*' --include '[ManagedCode.LlmTck.*]*' \
- --exclude '[ManagedCode.LlmTck.Tests]*' --exclude '[ManagedCode.LlmTck.Service]*' --exclude '[ManagedCode.LlmTck.AppHost]*' \
+ --include '[ManagedCode.LlmTestServer]*' --include '[ManagedCode.LlmTestServer.*]*' \
+ --exclude '[ManagedCode.LlmTestServer.Tests]*' --exclude '[ManagedCode.LlmTestServer.Service]*' --exclude '[ManagedCode.LlmTestServer.AppHost]*' \
--threshold 90 --threshold-type line --threshold-stat Total
dotnet tool run reportgenerator -reports:artifacts/coverage/raw/coverage.cobertura.xml \
-targetdir:artifacts/coverage/report '-reporttypes:HtmlSummary;TextSummary'
diff --git a/scripts/package-consumer/AnthropicNativePackageTests.cs b/scripts/package-consumer/AnthropicNativePackageTests.cs
new file mode 100644
index 0000000..41b233a
--- /dev/null
+++ b/scripts/package-consumer/AnthropicNativePackageTests.cs
@@ -0,0 +1,131 @@
+using System.Text.Json;
+using System.Text.Json.Nodes;
+using global::Anthropic;
+using global::Anthropic.Core;
+using global::Anthropic.Models.Messages;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using TUnit.Core;
+
+public sealed class AnthropicNativePackageTests
+{
+ private static readonly string _model = JsonSerializer.SerializeToElement(Model.ClaudeSonnet5_5).GetString()!;
+ private const string _key = "anthropic-sdk-key";
+ private const string _url = "https://example.com/sdk-source";
+ private const string _call = "srvtoolu_sdk";
+
+ [Test]
+ public async Task InstalledPackages_OfficialSdkParsesNativeJsonSseErrorsAndHistoryAsync(CancellationToken cancellationToken)
+ {
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer("anthropic-native-package-server").WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync("anthropic-native-package-server", cancellationToken);
+ using var http = app.CreateHttpClient("anthropic-native-package-server", LlmTestServerResource.HttpEndpointName);
+ var control = new LlmTestServerClient(http, _key);
+ await control.ConfigureAsync(config => config.RequireBearerToken(_key).UseModel(_model, LlmTestServerModelKind.Chat)
+ .UseChatScenario("anthropic-sdk", scenario => scenario.ForModel(_model)
+ .RespondsWithItems(Items()).RespondsWithItems(Items()).RespondsWithItems(Items("unavailable")).Responds("SDK history complete.")), cancellationToken);
+ using var sdk = new AnthropicClient(new ClientOptions
+ { HttpClient = http, BaseUrl = new Uri(http.BaseAddress!, "/anthropic").ToString(), ApiKey = _key, MaxRetries = 0, ResponseValidation = true });
+ var options = Options();
+ var first = await sdk.Messages.Create(options, cancellationToken);
+ AssertContent(first.Content);
+ Require(first.Usage.ServerToolUse!.WebSearchRequests == 1, "Installed native JSON must report one search.");
+
+ var blocks = new JsonArray(); var input = string.Empty; var stopped = new List();
+ var messageStopped = false; var citationDeltas = 0; var searchCount = -1L;
+ await foreach (var update in sdk.Messages.CreateStreaming(options, cancellationToken))
+ {
+ switch (update.Value)
+ {
+ case RawContentBlockStartEvent start:
+ Require(start.Index == blocks.Count, "Installed SDK stream block indexes must be contiguous.");
+ blocks.Add(JsonNode.Parse(start.ContentBlock.Json.GetRawText()));
+ break;
+ case RawContentBlockDeltaEvent delta:
+ switch (delta.Delta.Value)
+ {
+ case InputJsonDelta json: input += json.PartialJson; break;
+ case TextDelta text:
+ var index = checked((int)delta.Index);
+ blocks[index]!["text"] = (blocks[index]!["text"]?.GetValue() ?? string.Empty) + text.Text;
+ break;
+ case CitationsDelta citation:
+ citationDeltas++;
+ var citationIndex = checked((int)delta.Index);
+ blocks[citationIndex]!["citations"] ??= new JsonArray();
+ ((JsonArray)blocks[citationIndex]!["citations"]!).Add(JsonNode.Parse(citation.Citation.Json.GetRawText()));
+ break;
+ }
+ break;
+ case RawContentBlockStopEvent stop: stopped.Add(stop.Index); break;
+ case RawMessageDeltaEvent delta:
+ searchCount = delta.Usage.ServerToolUse!.WebSearchRequests;
+ break;
+ case RawMessageStopEvent: messageStopped = true; break;
+ }
+ }
+ blocks[0]!["input"] = JsonNode.Parse(input);
+ Require(messageStopped && stopped.SequenceEqual(new long[] { 0, 1, 2 }) && citationDeltas == 1 && searchCount == 1, "Installed native SDK SSE must complete blocks, citations and usage.");
+ var streamed = JsonSerializer.Deserialize>(blocks.ToJsonString())!;
+ AssertContent(streamed);
+ Require(JsonNode.DeepEquals(blocks, JsonNode.Parse(JsonSerializer.Serialize(first.Content))), "Installed SDK SSE must reconstruct JSON content exactly.");
+
+ var failed = await sdk.Messages.Create(options, cancellationToken);
+ var errorBlock = (WebSearchToolResultBlock)failed.Content[1].Value!;
+ Require(errorBlock.Content.TryPickError(out var nativeError) && nativeError.ErrorCode.Json.GetString() == "unavailable",
+ "Official installed SDK must parse typed native errors inside successful Messages.");
+ var history = JsonSerializer.Deserialize>(JsonSerializer.Serialize(first.Content))!;
+ var follow = options with { Messages = [.. options.Messages, new() { Role = Role.Assistant, Content = history }, new() { Role = Role.User, Content = "SDK follow" }] };
+ var continued = await sdk.Messages.Create(follow, cancellationToken);
+ Require(((TextBlock)continued.Content.Single().Value!).Text == "SDK history complete.", "Installed SDK assistant history must roundtrip.");
+ var traces = (await control.ExportRequestsAsync(cancellationToken: cancellationToken)).Evidence.Requests;
+ Require(traces.Count == 4, "Installed journal must retain every SDK request.");
+ var stream = traces.Single(trace => trace.IsStreaming);
+ Require(stream.TerminalMarkerObserved == true && stream.NativeTools.Count == 1 && stream.ResponseToolCalls.Count == 0, "Installed journal must retain terminal native evidence separately from functions.");
+ var restored = traces.Single(trace => trace.Messages.Any(message => message.Content == "SDK follow"));
+ Require(restored.Messages.Single(message => message.Role == "assistant").OutputItems.Count == 3, "Installed typed history must retain ordered native items.");
+ }
+
+ private static MessageCreateParams Options(long maxUses = 1)
+ {
+ return new()
+ {
+ Model = Model.ClaudeSonnet5_5, MaxTokens = 256, ToolChoice = new ToolChoiceAuto(),
+ Messages = [new() { Role = Role.User, Content = "SDK fixture" }],
+ Tools = [new WebSearchTool20250305
+ { MaxUses = maxUses, AllowedDomains = ["example.com/sdk*"], UserLocation = new() { Country = "US", Timezone = "America/New_York" } }],
+ };
+ }
+
+ private static LlmTestServerResponseItem[] Items(string? error = null)
+ {
+ return
+ [new LlmTestServerResponseServerToolUseItem { Id = _call, Input = new LlmTestServerWebSearchInput { Query = "SDK fixture query" } },
+ new LlmTestServerResponseServerToolResultItem { ToolUseId = _call,
+ Result = error is null ? new LlmTestServerWebSearchResults { Results = [new() { Url = _url, Title = "SDK source", EncryptedContent = "opaque-sdk-source" }] }
+ : new LlmTestServerWebSearchErrorResult { ErrorCode = error } },
+ new LlmTestServerResponseMessageItem { Content = "SDK answer.", StreamChunks = ["SDK ", "answer."],
+ Citations = error is null ? [new LlmTestServerAnthropicWebSearchCitation { Url = _url, EncryptedIndex = "opaque-sdk-index", CitedText = "SDK source excerpt", Title = "SDK source" }] : [] }];
+ }
+
+ private static void AssertContent(IReadOnlyList content)
+ {
+ if (content.Count != 3 || content[0].Value is not ServerToolUseBlock call || call.ID != _call
+ || call.Input["query"].GetString() != "SDK fixture query" || content[1].Value is not WebSearchToolResultBlock returned
+ || returned.ToolUseID != _call || !returned.Content.TryPickWebSearchResultBlocks(out var results)
+ || results.Single().EncryptedContent != "opaque-sdk-source" || content[2].Value is not TextBlock text || text.Text != "SDK answer."
+ || text.Citations!.Single().Value is not CitationsWebSearchResultLocation citation || citation.EncryptedIndex != "opaque-sdk-index")
+ { throw new InvalidOperationException("Official Anthropic SDK must parse typed native calls, results and citations."); }
+ }
+ private static void Require(bool condition, string message)
+ {
+ if (!condition) { throw new InvalidOperationException(message); }
+ }
+}
diff --git a/scripts/package-consumer/AzureOutputPolicyPackageTests.cs b/scripts/package-consumer/AzureOutputPolicyPackageTests.cs
new file mode 100644
index 0000000..88fc306
--- /dev/null
+++ b/scripts/package-consumer/AzureOutputPolicyPackageTests.cs
@@ -0,0 +1,188 @@
+#pragma warning disable OPENAI001 // Exercise the pinned official Responses SDK against installed packages.
+using System.ClientModel;
+using System.ClientModel.Primitives;
+using System.Text;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using Azure;
+using Azure.AI.Inference;
+using Azure.AI.OpenAI;
+using Azure.Core.Pipeline;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Diagnostics;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+using OpenAI;
+using OpenAI.Chat;
+using OpenAI.Responses;
+using TUnit.Core;
+
+public sealed class AzureOutputPolicyPackageTests
+{
+ private const string _key = "azure-policy-package-key";
+ private const string _model = LlmTestServerKnownModelIds.Gpt41Mini;
+ private const string _text = "Explicit installed Azure policy text";
+ private const string _recovery = "Installed Azure policy recovery";
+
+ [Test]
+ [Arguments("deployment")]
+ [Arguments("inference")]
+ [Arguments("inference-models")]
+ [Arguments("azure-chat")]
+ [Arguments("foundry-chat")]
+ [Arguments("azure-responses")]
+ [Arguments("foundry-responses")]
+ public async Task InstalledPackages_AzurePolicyStreamsThroughOriginalSdkAndExplicitJsonRecoveryAsync(string route, CancellationToken cancellationToken)
+ {
+ var resourceName = "azure-policy-" + route;
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer(resourceName).WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync(resourceName, cancellationToken);
+ using var http = app.CreateHttpClient(resourceName, LlmTestServerResource.HttpEndpointName);
+ var control = new LlmTestServerClient(http, _key);
+ var inference = route is "inference" or "inference-models";
+ var responses = route.EndsWith("responses", StringComparison.Ordinal);
+ var kind = inference || responses ? LlmTestServerOutputDispositionKind.Filtered : LlmTestServerOutputDispositionKind.Refused;
+ var prefix = route.StartsWith("foundry-", StringComparison.Ordinal) ? "/microsoft-foundry" : "/azure-openai";
+ var expectedPath = route switch
+ {
+ "deployment" => "/azure-openai/openai/deployments/" + _model + "/chat/completions",
+ "inference" => "/microsoft-foundry/chat/completions",
+ "inference-models" => "/microsoft-foundry/models/chat/completions",
+ _ => prefix + "/openai/v1/" + (responses ? "responses" : "chat/completions"),
+ };
+ await control.ConfigureAsync(config => config.RequireBearerToken(_key).UseChatModel(_model)
+ .UseChatScenario("installed-azure-policy", scenario => scenario.ForModel(_model)
+ .Responds(_text, "Explicit installed ", "Azure policy text")
+ .WithOutputDisposition(new() { Kind = kind })
+ .Responds(_recovery)), cancellationToken);
+ using var deadline = CancellationTokenSource.CreateLinkedTokenSource(cancellationToken);
+ deadline.CancelAfter(TimeSpan.FromSeconds(60));
+ var text = new StringBuilder();
+ var refusal = new StringBuilder();
+ long inputTokens = 0, outputTokens = 0, totalTokens = 0;
+ var sawUsage = false;
+ Func> recover;
+ if (inference)
+ {
+ var options = new AzureAIInferenceClientOptions { Transport = new HttpClientTransport(http) };
+ options.Retry.MaxRetries = 0;
+ var endpoint = route == "inference-models" ? "/microsoft-foundry/models" : "/microsoft-foundry";
+ var sdk = new ChatCompletionsClient(new Uri(http.BaseAddress!, endpoint), new AzureKeyCredential(_key), options);
+ var request = new ChatCompletionsOptions([new ChatRequestUserMessage("policy")]) { Model = _model };
+ CompletionsFinishReason? finish = null;
+ using (var stream = await sdk.CompleteStreamingAsync(request, deadline.Token))
+ {
+ await foreach (var update in stream)
+ {
+ text.Append(update.ContentUpdate);
+ finish = update.FinishReason ?? finish;
+ if (update.Usage is { } usage)
+ {
+ sawUsage = true; inputTokens = usage.PromptTokens; outputTokens = usage.CompletionTokens; totalTokens = usage.TotalTokens;
+ }
+ }
+ }
+ Require(finish == CompletionsFinishReason.ContentFiltered, "Installed Model Inference SDK must parse typed ContentFiltered.");
+ recover = async token =>
+ {
+ var next = (await sdk.CompleteAsync(new ChatCompletionsOptions([new ChatRequestUserMessage("next")]) { Model = _model }, token)).Value;
+ Require(next.FinishReason == CompletionsFinishReason.Stopped, "Installed inference recovery must have a normal stop.");
+ return next.Content;
+ };
+ }
+ else if (responses)
+ {
+ var sdk = new ResponsesClient(new ApiKeyCredential(_key), new ResponsesClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, prefix + "/openai/v1/"), Transport = new HttpClientPipelineTransport(http), RetryPolicy = new ClientRetryPolicy(0) });
+ ResponseResult? final = null;
+ await foreach (var update in sdk.CreateResponseStreamingAsync(new CreateResponseOptions
+ { Model = _model, StreamingEnabled = true, StoredOutputEnabled = false, InputItems = { ResponseItem.CreateUserMessageItem("policy") } }, deadline.Token))
+ {
+ if (update is StreamingResponseOutputTextDeltaUpdate delta) { text.Append(delta.Delta); }
+ if (update is StreamingResponseIncompleteUpdate incomplete) { final = incomplete.Response; }
+ Require(update is not StreamingResponseCompletedUpdate and not StreamingResponseFailedUpdate and not StreamingResponseErrorUpdate,
+ "Installed filtered Azure Responses must end incomplete, not completed, failed or API error.");
+ }
+ Require(final is not null && final.Status == ResponseStatus.Incomplete
+ && final.IncompleteStatusDetails.Reason == ResponseIncompleteStatusReason.ContentFilter,
+ "Installed Azure Responses SDK must parse native content_filter incomplete completion.");
+ var usage = final!.Usage;
+ sawUsage = usage is not null;
+ if (usage is not null) { inputTokens = usage.InputTokenCount; outputTokens = usage.OutputTokenCount; totalTokens = usage.TotalTokenCount; }
+ recover = async token =>
+ {
+ var next = (await sdk.CreateResponseAsync(new CreateResponseOptions
+ { Model = _model, StoredOutputEnabled = false, InputItems = { ResponseItem.CreateUserMessageItem("next") } }, token)).Value;
+ Require(next.Status == ResponseStatus.Completed && next.IncompleteStatusDetails is null, "Installed Azure Responses recovery must complete normally.");
+ return next.GetOutputText();
+ };
+ }
+ else
+ {
+ var transport = new HttpClientPipelineTransport(http);
+ var sdk = route == "deployment"
+ ? new AzureOpenAIClient(new Uri(http.BaseAddress!, "/azure-openai/"), new ApiKeyCredential(_key),
+ new AzureOpenAIClientOptions { Transport = transport, RetryPolicy = new ClientRetryPolicy(0) }).GetChatClient(_model)
+ : new ChatClient(_model, new ApiKeyCredential(_key), new OpenAIClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, prefix + "/openai/v1/"), Transport = transport, RetryPolicy = new ClientRetryPolicy(0) });
+ ChatFinishReason? finish = null;
+ await foreach (var update in sdk.CompleteChatStreamingAsync([new UserChatMessage("policy")], cancellationToken: deadline.Token))
+ {
+ foreach (var part in update.ContentUpdate) { text.Append(part.Text); }
+ refusal.Append(update.RefusalUpdate);
+ finish = update.FinishReason ?? finish;
+ if (update.Usage is { } usage)
+ { sawUsage = true; inputTokens = usage.InputTokenCount; outputTokens = usage.OutputTokenCount; totalTokens = usage.TotalTokenCount; }
+ }
+ Require(finish == ChatFinishReason.Stop && text.Length == 0 && refusal.ToString() == _text,
+ "Installed Azure Chat SDK must expose native refusal deltas and normal stop without duplicate ordinary text.");
+ recover = async token =>
+ {
+ var next = (await sdk.CompleteChatAsync([new UserChatMessage("next")], cancellationToken: token)).Value;
+ Require(next.FinishReason == ChatFinishReason.Stop && next.Refusal is null, "Installed Azure Chat recovery must not inherit refusal.");
+ return next.Content.Single().Text;
+ };
+ }
+ Require((kind == LlmTestServerOutputDispositionKind.Refused ? refusal.ToString() : text.ToString()) == _text,
+ "Installed original Azure SDK must retain explicit policy text.");
+ var first = await CompletedTraceAsync(control, 1, deadline.Token);
+ Require(first.Path == expectedPath && first.ModelId == _model && first.IsStreaming && first.StatusCode == 200
+ && first.TransportState == LlmTestServerProviderHttpTraceTransportState.Completed && first.TerminalMarkerObserved == true
+ && first.OutputDisposition?.Kind == kind && first.StreamDelivery is null && !first.StreamDeliveryApplied,
+ "Installed journal must retain the exact Azure route, native200 policy and actual stream terminal.");
+ Require(sawUsage, $"Installed original {route} SDK stream omitted typed usage; journal input/output/total={first.Usage?.InputTokens}/{first.Usage?.OutputTokens}/{first.Usage?.TotalTokens}.");
+ Require(first.Usage is { } recorded && recorded.InputTokens == inputTokens && recorded.OutputTokens == outputTokens
+ && recorded.TotalTokens == totalTokens && inputTokens > 0 && outputTokens > 0,
+ "Installed SDK stream usage must reconcile with recorded generated/refusal tokens.");
+ var verified = await control.VerifyAsync(new()
+ { Requests = [new() { Query = new() { RequestId = first.RequestId }, RequireStreamingTerminalMarker = true }] }, deadline.Token);
+ Require(verified.Passed, "Installed native Azure policy stream must satisfy protocol-terminal verification.");
+ Require(await recover(deadline.Token) == _recovery, "Explicit installed SDK JSON retry must consume the next recovery fixture.");
+ var second = await CompletedTraceAsync(control, 2, deadline.Token);
+ var summary = await control.GetAssertionsAsync(deadline.Token);
+ Require(second.Path == expectedPath && !second.IsStreaming && second.StatusCode == 200 && second.OutputDisposition is null
+ && second.TransportState == LlmTestServerProviderHttpTraceTransportState.Completed
+ && summary.Matched == 2 && summary.ErrorsReturned == 0
+ && summary.Events.Count(item => item.OutputDisposition?.Kind == kind) == 1
+ && (await control.GetRequestsAsync(cancellationToken: deadline.Token)).TotalObserved == 2,
+ "Exactly two original SDK calls must be observed, with one committed policy followed by ordinary JSON recovery.");
+ }
+
+ private static async Task CompletedTraceAsync(LlmTestServerClient control, int count, CancellationToken cancellationToken)
+ {
+ while (true)
+ {
+ var evidence = await control.GetRequestsAsync(cancellationToken: cancellationToken);
+ if (evidence.Requests.Count == count && evidence.Requests.All(trace => trace.IsCompleted))
+ return evidence.Requests.OrderBy(trace => trace.Sequence).Last();
+ await Task.Delay(20, cancellationToken);
+ }
+ }
+
+ private static void Require(bool condition, string message)
+ { if (!condition) { throw new InvalidOperationException(message); } }
+}
diff --git a/scripts/package-consumer/Consumer.csproj.template b/scripts/package-consumer/Consumer.csproj.template
index 9e146e7..5b2cb02 100644
--- a/scripts/package-consumer/Consumer.csproj.template
+++ b/scripts/package-consumer/Consumer.csproj.template
@@ -11,7 +11,13 @@
true
-
+
+
+
+
+
+
+
diff --git a/scripts/package-consumer/DeepSeekOutputPolicyPackageTests.cs b/scripts/package-consumer/DeepSeekOutputPolicyPackageTests.cs
new file mode 100644
index 0000000..2f531ff
--- /dev/null
+++ b/scripts/package-consumer/DeepSeekOutputPolicyPackageTests.cs
@@ -0,0 +1,106 @@
+using System.ClientModel;
+using System.ClientModel.Primitives;
+using System.Text;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Diagnostics;
+using ManagedCode.LlmTestServer.Scenarios;
+using OpenAI;
+using OpenAI.Chat;
+using TUnit.Core;
+
+public sealed class DeepSeekOutputPolicyPackageTests
+{
+ private const string _key = "deepseek-policy-package-key";
+ private const string _model = "deepseek-flash";
+ private const string _path = "/deepseek/v1/chat/completions";
+ private const string _text = "Explicit installed DeepSeek prefix";
+ private const string _recovery = "Installed DeepSeek recovery";
+
+ [Test]
+ public async Task InstalledPackages_DeepSeekFilteredStreamRetainsUsageAndExplicitJsonRecoveryAsync(CancellationToken cancellationToken)
+ {
+ const string ResourceName = "deepseek-policy-package";
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer(ResourceName).WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync(ResourceName, cancellationToken);
+ using var http = app.CreateHttpClient(ResourceName, LlmTestServerResource.HttpEndpointName);
+ var control = new LlmTestServerClient(http, _key);
+ await control.ConfigureAsync(config => config.RequireBearerToken(_key).UseChatModel(_model)
+ .UseChatScenario("installed-deepseek-policy", scenario => scenario.ForModel(_model)
+ .Responds(_text, "Explicit installed ", "DeepSeek prefix")
+ .WithOutputDisposition(new() { Kind = LlmTestServerOutputDispositionKind.Filtered })
+ .Responds(_recovery)), cancellationToken);
+ var sdk = new ChatClient(_model, new ApiKeyCredential(_key), new OpenAIClientOptions
+ {
+ Endpoint = new Uri(http.BaseAddress!, "/deepseek/v1/"),
+ Transport = new HttpClientPipelineTransport(http),
+ RetryPolicy = new ClientRetryPolicy(0),
+ });
+ using var deadline = CancellationTokenSource.CreateLinkedTokenSource(cancellationToken);
+ deadline.CancelAfter(TimeSpan.FromSeconds(60));
+ var text = new StringBuilder();
+ ChatFinishReason? finish = null;
+ ChatTokenUsage? usage = null;
+ var usageUpdates = 0;
+ await foreach (var update in sdk.CompleteChatStreamingAsync([new UserChatMessage("policy")], cancellationToken: deadline.Token))
+ {
+ foreach (var part in update.ContentUpdate) { text.Append(part.Text); }
+ finish = update.FinishReason ?? finish;
+ Require(update.RefusalUpdate is null, "DeepSeek Filtered must not become a model-refusal field.");
+ if (update.Usage is not null) { usage = update.Usage; usageUpdates++; }
+ }
+ Require(text.ToString() == _text && finish == ChatFinishReason.ContentFilter && usage is not null && usageUpdates == 1,
+ "Installed DeepSeek SDK streaming must retain the configured prefix, native ContentFilter finish and one final usage update.");
+ var sdkUsage = usage ?? throw new InvalidOperationException("Installed DeepSeek SSE omitted final usage.");
+ var first = await CompletedTraceAsync(control, 1, deadline.Token);
+ Require(first.Path == _path && first.ModelId == _model && first.IsStreaming && first.StatusCode == 200
+ && first.TransportState == LlmTestServerProviderHttpTraceTransportState.Completed
+ && first.OutputDisposition?.Kind == LlmTestServerOutputDispositionKind.Filtered
+ && first.TerminalMarkerObserved == true && first.StreamDelivery is null && !first.StreamDeliveryApplied,
+ "Installed journal must distinguish a completed native DeepSeek policy stream from HTTP or delivery faults.");
+ Require(first.Usage is not null && sdkUsage.InputTokenCount == first.Usage.InputTokens
+ && sdkUsage.OutputTokenCount == first.Usage.OutputTokens && sdkUsage.TotalTokenCount == first.Usage.TotalTokens
+ && sdkUsage.InputTokenCount > 0 && sdkUsage.OutputTokenCount > 0,
+ "Installed SDK usage must reconcile with the recorded inference usage, including generated policy-prefix tokens.");
+ var verified = await control.VerifyAsync(new()
+ {
+ Requests = [new() { Query = new() { RequestId = first.RequestId }, RequireStreamingTerminalMarker = true }],
+ }, deadline.Token);
+ Require(verified.Passed, "Installed DeepSeek native policy SSE must satisfy actual protocol-terminal verification.");
+ var summary = await control.GetAssertionsAsync(deadline.Token);
+ Require(summary.Matched == 1 && summary.ErrorsReturned == 0
+ && summary.Events.Single().OutputDisposition?.Kind == LlmTestServerOutputDispositionKind.Filtered,
+ "The filtered outcome must commit once without becoming a provider HTTP error.");
+
+ var recovered = (await sdk.CompleteChatAsync([new UserChatMessage("next")], cancellationToken: deadline.Token)).Value;
+ Require(recovered.Content.Single().Text == _recovery && recovered.FinishReason == ChatFinishReason.Stop && recovered.Refusal is null,
+ "The explicit next installed SDK JSON call must consume the queued recovery with a normal stop.");
+ var second = await CompletedTraceAsync(control, 2, deadline.Token);
+ Require(second.Path == _path && !second.IsStreaming && second.StatusCode == 200 && second.OutputDisposition is null
+ && second.TransportState == LlmTestServerProviderHttpTraceTransportState.Completed,
+ "Installed JSON recovery must remain on the DeepSeek route and not inherit the prior policy outcome.");
+ var requests = await control.GetRequestsAsync(cancellationToken: deadline.Token);
+ summary = await control.GetAssertionsAsync(deadline.Token);
+ Require(requests.TotalObserved == 2 && summary.Matched == 2 && summary.ErrorsReturned == 0,
+ "Installed DeepSeek SDK must make exactly two matched requests with retries disabled.");
+ }
+
+ private static async Task CompletedTraceAsync(LlmTestServerClient control, int count, CancellationToken cancellationToken)
+ {
+ while (true)
+ {
+ var evidence = await control.GetRequestsAsync(cancellationToken: cancellationToken);
+ if (evidence.Requests.Count == count && evidence.Requests.All(trace => trace.IsCompleted))
+ return evidence.Requests.OrderBy(trace => trace.Sequence).Last();
+ await Task.Delay(20, cancellationToken);
+ }
+ }
+
+ private static void Require(bool condition, string message)
+ { if (!condition) { throw new InvalidOperationException(message); } }
+}
diff --git a/scripts/package-consumer/NativeFileCodePackageTests.cs b/scripts/package-consumer/NativeFileCodePackageTests.cs
new file mode 100644
index 0000000..c1fb2da
--- /dev/null
+++ b/scripts/package-consumer/NativeFileCodePackageTests.cs
@@ -0,0 +1,180 @@
+#pragma warning disable OPENAI001 // Exercise the official Responses client against installed packages.
+using System.ClientModel;
+using System.ClientModel.Primitives;
+using System.Net.Http.Headers;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+using OpenAI.Responses;
+using TUnit.Core;
+
+public sealed class NativeFileCodePackageTests
+{
+ private const string _key = "file-code-package-key";
+
+ [Test]
+ public async Task InstalledPackages_ServeFileAndCodeJsonStreamAndStoredHistory(CancellationToken cancellationToken)
+ {
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer("file-code-package-server").WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync("file-code-package-server", cancellationToken);
+ using var http = app.CreateHttpClient("file-code-package-server", "http");
+ http.DefaultRequestHeaders.Authorization = new AuthenticationHeaderValue("Bearer", _key);
+ var control = new LlmTestServerClient(http, _key);
+ var sdk = new ResponsesClient(new ApiKeyCredential(_key), new ResponsesClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, "/openai/v1/"), Transport = new HttpClientPipelineTransport(http) });
+ foreach (var code in new[] { false, true })
+ {
+ await control.ConfigureAsync(config =>
+ {
+ config.RequireBearerToken(_key);
+ if (code) { config.UseGpt41(); } else { config.UseGpt4OMini(); }
+ config.UseChatScenario("installed-file-code", scenario => scenario
+ .ForModel(code ? LlmTestServerKnownModelIds.Gpt41 : LlmTestServerKnownModelIds.Gpt4OMini)
+ .RespondsWithItems(Items(code))
+ .RespondsWithItems(Items(code)).Responds("installed continuation complete"));
+ }, cancellationToken);
+ var first = (await sdk.CreateResponseAsync(Options(code), cancellationToken: cancellationToken)).Value;
+ AssertOutput(first, code);
+ var streamOptions = Options(code);
+ streamOptions.StreamingEnabled = true;
+ var updates = new List();
+ await foreach (var update in sdk.CreateResponseStreamingAsync(streamOptions, cancellationToken: cancellationToken))
+ { updates.Add(update); }
+ Require(updates.Select(update => update.SequenceNumber).SequenceEqual(Enumerable.Range(0, updates.Count)),
+ "Installed file/code streaming must preserve contiguous event sequence numbers.");
+ AssertOutput(updates.OfType().Single().Response, code);
+ if (code)
+ {
+ Require(updates.OfType().Count() == 1
+ && updates.OfType().Count() == 1
+ && updates.OfType().Count() == 1,
+ "Installed code interpreter must emit native progress events.");
+ Require(updates.OfType().Count() == 2
+ && updates.OfType().Count() == 1,
+ "Installed code interpreter must emit configured code deltas and the completed code.");
+ }
+ else
+ {
+ Require(updates.OfType().Count() == 1
+ && updates.OfType().Count() == 1
+ && updates.OfType().Count() == 1,
+ "Installed file search must emit native progress events.");
+ }
+ Require(updates.OfType().Count() == 1,
+ "Installed native text must emit its citation exactly once.");
+ var follow = Options(code);
+ follow.ToolChoice = ResponseToolChoice.CreateAutoChoice();
+ follow.PreviousResponseId = first.Id;
+ var continued = (await sdk.CreateResponseAsync(follow, cancellationToken: cancellationToken)).Value;
+ Require(((MessageResponseItem)continued.OutputItems.Single()).Content.Single().Text == "installed continuation complete",
+ "Installed file/code response history must support previous_response_id.");
+ var evidence = await control.GetRequestsAsync(cancellationToken: cancellationToken);
+ Require(evidence.Requests.Count == 3 && evidence.Requests.All(trace => trace.IsSuccess == true),
+ "Installed native requests must retain successful terminal evidence.");
+ var streamed = evidence.Requests.Single(trace => trace.IsStreaming);
+ Require(streamed.TerminalMarkerObserved == true && streamed.ResponseOutputItems.Count == 2
+ && streamed.NativeTools.Count == 1 && streamed.ResponseToolCalls.Count == 0,
+ "Native evidence must expose native declarations and outputs separately from client function calls.");
+ var restored = evidence.Requests.Single(trace => trace.ResponsePreview?.Contains("installed continuation complete", StringComparison.Ordinal) == true);
+ Require(restored.Messages.Any(message => message.Role == "assistant" && message.OutputItems.Any(item =>
+ code ? item is LlmTestServerResponseCodeInterpreterItem : item is LlmTestServerResponseFileSearchItem)),
+ "Installed public history must preserve typed native output items.");
+ }
+ }
+
+ private static CreateResponseOptions Options(bool code)
+ {
+ var options = new CreateResponseOptions
+ {
+ Model = code ? LlmTestServerKnownModelIds.Gpt41 : LlmTestServerKnownModelIds.Gpt4OMini,
+ InputItems = { ResponseItem.CreateUserMessageItem("installed native fixture") },
+ ToolChoice = ResponseToolChoice.CreateRequiredChoice(),
+ };
+ if (code)
+ {
+ options.Tools.Add(ResponseTool.CreateCodeInterpreterTool(new CodeInterpreterToolContainer(
+ CodeInterpreterToolContainerConfiguration.CreateAutomaticContainerConfiguration(["file_input"]))));
+ options.IncludedProperties.Add(IncludedResponseProperty.CodeInterpreterCallOutputs);
+ }
+ else
+ {
+ options.Tools.Add(ResponseTool.CreateFileSearchTool(["vs_installed"], 1, null, null));
+ options.IncludedProperties.Add(IncludedResponseProperty.FileSearchCallResults);
+ }
+ return options;
+ }
+
+ private static LlmTestServerResponseItem[] Items(bool code)
+ {
+ return code ?
+ [
+ new LlmTestServerResponseCodeInterpreterItem
+ {
+ Id = "ci_installed", ContainerId = "cntr_installed", InputFileIds = ["file_input"], GeneratedFileIds = ["file_generated"],
+ Code = "print(42)", CodeChunks = ["print(", "42)"],
+ Outputs = [new LlmTestServerCodeInterpreterLogsOutput { Logs = "42\n" },
+ new LlmTestServerCodeInterpreterImageOutput { Url = "https://example.com/installed-chart.png" }],
+ },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = "msg_installed_code", Content = "Chart fixture.",
+ Citations = [new LlmTestServerContainerFileCitation
+ { ContainerId = "cntr_installed", FileId = "file_generated", Filename = "chart.png", StartIndex = 0, EndIndex = 0 }],
+ },
+ ] :
+ [
+ new LlmTestServerResponseFileSearchItem
+ {
+ Id = "fs_installed", VectorStoreIds = ["vs_installed"], Queries = ["installed fixture"],
+ Results = [new() { FileId = "file_installed", Filename = "fixture.txt", Text = "Installed fixture.", Score = 0.9 }],
+ },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = "msg_installed_file", Content = "File fixture.",
+ Citations = [new LlmTestServerFileCitation { FileId = "file_installed", Filename = "fixture.txt", Index = 4 }],
+ },
+ ];
+ }
+
+ private static void AssertOutput(ResponseResult response, bool code)
+ {
+ Require(response.OutputItems.Count == 2 && !response.OutputItems.OfType().Any(),
+ "File/code output must remain native output items.");
+ var text = (MessageResponseItem)response.OutputItems[1];
+ if (code)
+ {
+ var execution = (CodeInterpreterCallResponseItem)response.OutputItems[0];
+ Require(execution.Id == "ci_installed" && execution.ContainerId == "cntr_installed" && execution.Code == "print(42)"
+ && execution.Outputs.OfType().Single().Logs == "42\n"
+ && execution.Outputs.OfType().Single().ImageUri.AbsoluteUri == "https://example.com/installed-chart.png",
+ "Official installed SDK must parse code, logs and image output.");
+ var citation = (ContainerFileCitationMessageAnnotation)text.Content.Single().OutputTextAnnotations.Single();
+ Require(citation.ContainerId == "cntr_installed" && citation.FileId == "file_generated"
+ && citation.StartIndex == 0 && citation.EndIndex == 0,
+ "Official installed SDK must preserve zero-length container file citations.");
+ }
+ else
+ {
+ var search = (FileSearchCallResponseItem)response.OutputItems[0];
+ var result = search.Results.Single();
+ Require(search.Id == "fs_installed" && search.Queries.Single() == "installed fixture"
+ && result.FileId == "file_installed" && result.Filename == "fixture.txt" && result.Text == "Installed fixture.",
+ "Official installed SDK must parse included file search results.");
+ var citation = (FileCitationMessageAnnotation)text.Content.Single().OutputTextAnnotations.Single();
+ Require(citation.FileId == "file_installed" && citation.Filename == "fixture.txt" && citation.Index == 4,
+ "Official installed SDK must preserve file citation insertion indexes.");
+ }
+ }
+
+ private static void Require(bool condition, string message)
+ {
+ if (!condition) { throw new InvalidOperationException(message); }
+ }
+}
+#pragma warning restore OPENAI001
diff --git a/scripts/package-consumer/NativePackageTests.cs b/scripts/package-consumer/NativePackageTests.cs
new file mode 100644
index 0000000..5080a36
--- /dev/null
+++ b/scripts/package-consumer/NativePackageTests.cs
@@ -0,0 +1,174 @@
+#pragma warning disable OPENAI001 // Qualify the official experimental Responses SDK against installed packages.
+using System.ClientModel;
+using System.ClientModel.Primitives;
+using System.Net;
+using System.Net.Http.Headers;
+using System.Net.Http.Json;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+using OpenAI.Responses;
+using TUnit.Core;
+
+public sealed class NativePackageTests
+{
+ private const string _key = "native-package-key";
+ private const string _source = "https://example.com/installed-native";
+ private const string _searchId = "ws_installed_native";
+ private const string _messageId = "msg_installed_native";
+ private const string _functionId = "fc_installed_native";
+ private const string _callId = "call_installed_native";
+
+ [Test]
+ public async Task InstalledPackages_ServeNativeSearchJsonStreamAndCompleteMixedFunctionRound(CancellationToken cancellationToken)
+ {
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer("native-package-server").WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync("native-package-server", cancellationToken);
+ using var http = app.CreateHttpClient("native-package-server", "http");
+ http.DefaultRequestHeaders.Authorization = new AuthenticationHeaderValue("Bearer", _key);
+ var control = new LlmTestServerClient(http, _key);
+ await control.ConfigureAsync(config => config.RequireBearerToken(_key).UseGpt41Mini()
+ .UseConversation("installed-native", graph => graph
+ .Step("search", step => step.WhenLatestUserEquals("native-start").WhenTurn(1).RespondsWithItems(NativeItems()).Then("follow"))
+ .Step("follow", step => step.WhenLatestUserEquals("native-follow").WhenTurn(2).Responds("stored native history complete").Complete()))
+ .UseConversation("installed-mixed", graph => graph
+ .Step("search", step => step.WhenLatestUserEquals("mixed-start").WhenTurn(1).RespondsWithItems(
+ new LlmTestServerResponseFunctionCallItem
+ { Id = _functionId, Call = new() { Id = _callId, Name = "weather", ArgumentsJson = "{}" } },
+ NativeItems()[0], NativeItems()[1]).Then("result"))
+ .Step("result", step => step.WhenToolResult("weather", _callId).WhenTurn(2)
+ .WhenLatestTextContains("18 degrees").Responds("mixed native round complete").Complete())), cancellationToken);
+ using (var unauthorizedRequest = new HttpRequestMessage(HttpMethod.Post, "/openai/v1/responses"))
+ {
+ unauthorizedRequest.Headers.Authorization = new AuthenticationHeaderValue("Bearer", "wrong-native-key");
+ unauthorizedRequest.Content = JsonContent.Create(new
+ { model = LlmTestServerKnownModelIds.Gpt41Mini, input = "native-start", tools = new[] { new { type = "web_search" } } });
+ using var denied = await http.SendAsync(unauthorizedRequest, cancellationToken);
+ Require(denied.StatusCode == HttpStatusCode.Unauthorized, "The packaged native endpoint must enforce its configured key.");
+ }
+ Require((await control.GetConversationsAsync(cancellationToken: cancellationToken)).Count == 0,
+ "Unauthorized native requests must not create conversation state.");
+
+ using var storedConversation = control.ForConversation("installed-native-stored");
+ var storedSdk = Sdk(storedConversation.HttpClient);
+ var first = (await storedSdk.CreateResponseAsync(Options("native-start"), cancellationToken: cancellationToken)).Value;
+ AssertNative(first, offset: 0);
+ Require(first.OutputItems.Count == 2 && !first.OutputItems.OfType().Any(),
+ "Native web search must be a native item rather than a function call.");
+ var follow = Options("native-follow");
+ follow.PreviousResponseId = first.Id;
+ follow.ToolChoice = ResponseToolChoice.CreateAutoChoice();
+ var storedFinal = (await storedSdk.CreateResponseAsync(follow, cancellationToken: cancellationToken)).Value;
+ Require(((MessageResponseItem)storedFinal.OutputItems.Single()).Content.Single().Text == "stored native history complete",
+ "The installed server must restore native previous_response_id history before turn-two matching.");
+
+ using var mixedConversation = control.ForConversation("installed-native-explicit");
+ var mixedSdk = Sdk(mixedConversation.HttpClient);
+ var streamingOptions = Options("mixed-start", mixed: true);
+ streamingOptions.StoredOutputEnabled = false;
+ streamingOptions.StreamingEnabled = true;
+ var updates = new List();
+ await foreach (var update in mixedSdk.CreateResponseStreamingAsync(streamingOptions, cancellationToken: cancellationToken))
+ { updates.Add(update); }
+ Require(updates.Select(update => update.SequenceNumber).SequenceEqual(Enumerable.Range(0, updates.Count)),
+ "Native stream sequence numbers must be contiguous.");
+ Require(updates.OfType().Single().ItemId == _searchId
+ && updates.OfType().Single().OutputIndex == 1
+ && updates.OfType().Single().ItemId == _searchId,
+ "The installed package must emit typed native progress updates at the mixed output index.");
+ var annotation = updates.OfType().Single();
+ Require(annotation.OutputIndex == 2 && annotation.ItemId == _messageId
+ && ((UriCitationMessageAnnotation)annotation.Annotation).Uri.AbsoluteUri == _source,
+ "The installed stream must retain the native URL citation.");
+ var mixedFirst = updates.OfType().Single().Response;
+ Require(mixedFirst.OutputItems.Count == 3, "Mixed output order must include function, native search and text.");
+ var function = (FunctionCallResponseItem)mixedFirst.OutputItems[0];
+ Require(function.Id == _functionId && function.CallId == _callId && function.FunctionName == "weather"
+ && function.FunctionArguments.ToString() == "{}", "Mixed function output and correlation IDs must remain distinct.");
+ AssertNative(mixedFirst, offset: 1);
+ var explicitFollow = Options("unused", mixed: true);
+ explicitFollow.InputItems.Clear();
+ explicitFollow.InputItems.Add(ResponseItem.CreateUserMessageItem("mixed-start"));
+ foreach (var item in mixedFirst.OutputItems) { explicitFollow.InputItems.Add(item); }
+ explicitFollow.InputItems.Add(ResponseItem.CreateFunctionCallOutputItem(_callId, "18 degrees"));
+ var mixedFinal = (await mixedSdk.CreateResponseAsync(explicitFollow, cancellationToken: cancellationToken)).Value;
+ Require(((MessageResponseItem)mixedFinal.OutputItems.Single()).Content.Single().Text == "mixed native round complete",
+ "The installed server must complete a real SDK function/native round from explicit native history.");
+
+ var states = await control.GetConversationsAsync(cancellationToken: cancellationToken);
+ Require(states.Count == 2 && states.All(state => state.ExecutedSteps == 2),
+ "Both independently correlated packaged conversations must advance exactly two logical turns.");
+ var evidence = await control.GetRequestsAsync(cancellationToken: cancellationToken);
+ Require(evidence.Requests.Count == 5 && evidence.Requests.Count(trace => trace.StatusCode == 401) == 1
+ && evidence.Requests.Count(trace => trace.IsSuccess == true) == 4, "Public traces must expose all real packaged provider requests.");
+ var storedTrace = evidence.Requests.Single(trace => trace.ConversationId == storedConversation.Id && trace.StepId == "follow");
+ var storedSearch = storedTrace.Messages.Where(message => message.Role == "assistant").SelectMany(message => message.OutputItems)
+ .OfType().Single();
+ Require(storedSearch.Id == _searchId && storedSearch.Sources.Single().Url == _source,
+ "Public packaged trace serialization must retain typed native stored history.");
+ var mixedTrace = evidence.Requests.Single(trace => trace.ConversationId == mixedConversation.Id && trace.StepId == "result");
+ var history = mixedTrace.Messages.Where(message => message.Role == "assistant").SelectMany(message => message.OutputItems).ToArray();
+ Require(history.Length == 3 && ((LlmTestServerResponseFunctionCallItem)history[0]).Id == _functionId
+ && ((LlmTestServerResponseWebSearchItem)history[1]).Id == _searchId
+ && ((LlmTestServerResponseMessageItem)history[2]).Id == _messageId,
+ "Public packaged trace serialization must preserve ordered mixed output identities.");
+ var streamedTrace = evidence.Requests.Single(trace => trace.ConversationId == mixedConversation.Id && trace.StepId == "search");
+ Require(streamedTrace.IsStreaming && streamedTrace.TerminalMarkerObserved == true
+ && streamedTrace.ResponseOutputItems.Count == 3 && streamedTrace.ResponseToolCalls.Single().Id == _callId
+ && streamedTrace.NativeTools.Single().Contract == LlmTestServerNativeToolContract.OpenAiResponsesWebSearch,
+ "Packaged native streaming evidence must include completion, ordered outputs and a separate native declaration.");
+ }
+
+ private static LlmTestServerResponseItem[] NativeItems() =>
+ [
+ new LlmTestServerResponseWebSearchItem { Id = _searchId, Queries = ["installed native fixture"], Sources = [new() { Url = _source }] },
+ new LlmTestServerResponseMessageItem
+ {
+ Id = _messageId, Content = "Paris fixture.", StreamChunks = ["Paris ", "fixture."],
+ Citations = [new LlmTestServerUrlCitation() { StartIndex = 0, EndIndex = 5, Url = _source, Title = "Installed fixture source" }],
+ },
+ ];
+
+ private static ResponsesClient Sdk(HttpClient http) => new(new ApiKeyCredential(_key), new ResponsesClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, "/openai/v1/"), Transport = new HttpClientPipelineTransport(http) });
+
+ private static CreateResponseOptions Options(string input, bool mixed = false)
+ {
+ var options = new CreateResponseOptions
+ {
+ Model = LlmTestServerKnownModelIds.Gpt41Mini,
+ InputItems = { ResponseItem.CreateUserMessageItem(input) },
+ Tools = { ResponseTool.CreateWebSearchTool(null, WebSearchToolContextSize.Low, null) },
+ ToolChoice = mixed ? ResponseToolChoice.CreateAutoChoice() : ResponseToolChoice.CreateRequiredChoice(),
+ IncludedProperties = { IncludedResponseProperty.WebSearchCallActionSources },
+ };
+ if (mixed) { options.Tools.Add(ResponseTool.CreateFunctionTool("weather", BinaryData.FromString("{\"type\":\"object\"}"), false, "Scripted weather")); }
+ return options;
+ }
+
+ private static void AssertNative(ResponseResult response, int offset)
+ {
+ var search = (WebSearchCallResponseItem)response.OutputItems[offset];
+ var action = (WebSearchSearchAction)search.Action!;
+ Require(search.Id == _searchId && search.Status == WebSearchCallStatus.Completed && action.Queries.Single() == "installed native fixture"
+ && ((WebSearchActionUriSource)action.Sources.Single()).Uri.AbsoluteUri == _source,
+ "The installed official SDK must parse native search identity, action and included sources.");
+ var message = (MessageResponseItem)response.OutputItems[offset + 1];
+ var citation = (UriCitationMessageAnnotation)message.Content.Single().OutputTextAnnotations.Single();
+ Require(message.Id == _messageId && message.Content.Single().Text == "Paris fixture." && citation.StartIndex == 0
+ && citation.EndIndex == 5 && citation.Uri.AbsoluteUri == _source && citation.Title == "Installed fixture source",
+ "The installed official SDK must parse the exact configured message and URL citation.");
+ }
+
+ private static void Require(bool condition, string message)
+ {
+ if (!condition) { throw new InvalidOperationException(message); }
+ }
+}
+#pragma warning restore OPENAI001
diff --git a/scripts/package-consumer/OutputDispositionPackageTests.cs b/scripts/package-consumer/OutputDispositionPackageTests.cs
new file mode 100644
index 0000000..85c70c1
--- /dev/null
+++ b/scripts/package-consumer/OutputDispositionPackageTests.cs
@@ -0,0 +1,177 @@
+#pragma warning disable OPENAI001 // Exercise the pinned official Responses client using installed NuGet packages.
+using System.ClientModel;
+using System.ClientModel.Primitives;
+using System.Text;
+using System.Text.Json;
+using Aspire.Hosting;
+using Aspire.Hosting.Testing;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
+using ManagedCode.LlmTestServer.Diagnostics;
+using ManagedCode.LlmTestServer.Models;
+using ManagedCode.LlmTestServer.Scenarios;
+using Microsoft.Extensions.AI;
+using OpenAI;
+using OpenAI.Chat;
+using OpenAI.Responses;
+using TUnit.Core;
+using AnthropicMessages = global::Anthropic.Models.Messages;
+
+public sealed class OutputDispositionPackageTests
+{
+ private const string _key = "output-policy-package-key";
+ private const string _text = "Explicit installed policy text";
+ private const string _recovery = "Installed policy recovery";
+
+ [Test]
+ [Arguments("chat")]
+ [Arguments("responses")]
+ [Arguments("anthropic")]
+ [Arguments("gemini")]
+ [Arguments("meai-json")]
+ [Arguments("meai-stream")]
+ public async Task InstalledPackages_NativePolicyOutcomeIsTypedAndFollowingInferenceRecoversAsync(string provider, CancellationToken cancellationToken)
+ {
+ var resourceName = "output-policy-" + provider;
+ var builder = DistributedApplicationTestingBuilder.Create([]);
+ builder.AddLlmTestServer(resourceName).WithApiKey(_key);
+ await using var app = await builder.BuildAsync(cancellationToken);
+ await app.StartAsync(cancellationToken);
+ await app.ResourceNotifications.WaitForResourceHealthyAsync(resourceName, cancellationToken);
+ using var http = app.CreateHttpClient(resourceName, LlmTestServerResource.HttpEndpointName);
+ var control = new LlmTestServerClient(http, _key);
+ var model = provider switch
+ {
+ "anthropic" => JsonSerializer.SerializeToElement(AnthropicMessages.Model.ClaudeSonnet5_5).GetString()!,
+ "gemini" => "gemini-3.8-flash",
+ _ => LlmTestServerKnownModelIds.Gpt41Mini,
+ };
+ var kind = provider is "responses" or "gemini" ? LlmTestServerOutputDispositionKind.Filtered : LlmTestServerOutputDispositionKind.Refused;
+ var metadata = kind == LlmTestServerOutputDispositionKind.Refused;
+ var streaming = provider is "responses" or "gemini" or "meai-stream";
+ await control.ConfigureAsync(config => config.RequireBearerToken(_key).UseChatModel(model)
+ .UseChatScenario("installed-policy", scenario => scenario.ForModel(model)
+ .Responds(_text, "Explicit installed ", "policy text")
+ .WithOutputDisposition(new() { Kind = kind, Category = metadata ? "cyber" : null, Explanation = metadata ? "Installed fixture policy" : null })
+ .Responds(_recovery)), cancellationToken);
+
+ var chat = provider == "chat" ? new ChatClient(model, new ApiKeyCredential(_key), new OpenAIClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, "/openai/v1/"), Transport = new HttpClientPipelineTransport(http), RetryPolicy = new ClientRetryPolicy(0) }) : null;
+ var responses = provider == "responses" ? new ResponsesClient(new ApiKeyCredential(_key), new ResponsesClientOptions
+ { Endpoint = new Uri(http.BaseAddress!, "/openai/v1/"), Transport = new HttpClientPipelineTransport(http), RetryPolicy = new ClientRetryPolicy(0) }) : null;
+ using var anthropic = provider == "anthropic" ? new global::Anthropic.AnthropicClient(new global::Anthropic.Core.ClientOptions
+ { HttpClient = http, BaseUrl = new Uri(http.BaseAddress!, "/anthropic").ToString(), ApiKey = _key, MaxRetries = 0, ResponseValidation = true }) : null;
+ using var google = provider == "gemini" ? new Google.GenAI.Client(apiKey: _key, enterprise: false,
+ httpOptions: new() { BaseUrl = new Uri(http.BaseAddress!, "/gemini").ToString(), ApiVersion = "v1beta", RetryOptions = new() { Attempts = 1 } },
+ clientOptions: new() { HttpClientFactory = () => http }) : null;
+ using var abstraction = provider.StartsWith("meai-", StringComparison.Ordinal) ? control.CreateChatClient() : null;
+ if (chat is not null)
+ {
+ var result = (await chat.CompleteChatAsync([new UserChatMessage("policy")], cancellationToken: cancellationToken)).Value;
+ Require(result.Refusal == _text && result.Content.Count == 0 && result.FinishReason == OpenAI.Chat.ChatFinishReason.Stop,
+ "Installed OpenAI chat refusal must be the typed refusal field with native stop, without ordinary text duplication.");
+ }
+ else if (responses is not null)
+ {
+ var text = new StringBuilder(); ResponseResult? final = null;
+ await foreach (var update in responses.CreateResponseStreamingAsync(new CreateResponseOptions
+ { Model = model, StreamingEnabled = true, StoredOutputEnabled = false, InputItems = { ResponseItem.CreateUserMessageItem("policy") } }, cancellationToken))
+ {
+ if (update is StreamingResponseOutputTextDeltaUpdate delta) { text.Append(delta.Delta); }
+ if (update is StreamingResponseIncompleteUpdate incomplete) { final = incomplete.Response; }
+ Require(update is not StreamingResponseCompletedUpdate and not StreamingResponseFailedUpdate and not StreamingResponseErrorUpdate,
+ "Installed filtered Responses SSE must end incomplete rather than completed, failed or API error.");
+ }
+ Require(text.ToString() == _text && final is not null && final.Status == ResponseStatus.Incomplete
+ && final.IncompleteStatusDetails.Reason == ResponseIncompleteStatusReason.ContentFilter,
+ "Installed Responses SDK must retain its explicit prefix and typed content_filter incomplete outcome.");
+ }
+ else if (anthropic is not null)
+ {
+ var result = await anthropic.Messages.Create(AnthropicOptions(), cancellationToken);
+ Require(result.StopReason?.Json.GetString() == "refusal" && result.StopDetails is { } refusalDetails
+ && refusalDetails.Category?.Json.GetString() == "cyber" && refusalDetails.Explanation == "Installed fixture policy"
+ && string.Concat(result.Content.Select(block => ((AnthropicMessages.TextBlock)block.Value!).Text)) == _text,
+ "Installed strict Anthropic SDK must parse native refusal stop/details and explicit text.");
+ }
+ else if (google is not null)
+ {
+ var text = new StringBuilder(); Google.GenAI.Types.GenerateContentResponse? final = null;
+ await foreach (var update in google.Models.GenerateContentStreamAsync(model, "policy",
+ new Google.GenAI.Types.GenerateContentConfig { AutomaticContinuation = false }, cancellationToken: cancellationToken))
+ {
+ text.Append(update.Text);
+ if (update.Candidates?.Any(candidate => candidate.FinishReason is not null) == true) { final = update; }
+ }
+ Require(text.ToString() == _text && final is not null && final.Candidates?.Single().FinishReason == Google.GenAI.Types.FinishReason.Safety
+ && string.IsNullOrEmpty(final.Text) && final.PromptFeedback is null,
+ "Installed Gemini SDK must observe a prefix followed by candidate SAFETY with no repeated terminal content or input-block envelope.");
+ }
+ else
+ {
+ Microsoft.Extensions.AI.ChatMessage[] prompt = [new(ChatRole.User, "policy")];
+ var result = streaming
+ ? await abstraction!.GetStreamingResponseAsync(prompt, cancellationToken: cancellationToken).ToChatResponseAsync(cancellationToken)
+ : await abstraction!.GetResponseAsync(prompt, cancellationToken: cancellationToken);
+ var refusal = result.Messages.SelectMany(message => message.Contents).OfType().Single();
+ Require(refusal.ErrorCode == "Refusal" && refusal.Message == _text && result.Text.Length == 0
+ && !result.Messages.SelectMany(message => message.Contents).OfType().Any(),
+ "Installed IChatClient must represent refusal as one canonical ErrorContent and no duplicate ordinary text.");
+ }
+ var first = await CompletedTraceAsync(control, 1, cancellationToken);
+ Require(first.StatusCode == 200 && first.TransportState == LlmTestServerProviderHttpTraceTransportState.Completed
+ && first.OutputDisposition is { } policy && policy.Kind == kind && policy.Category == (metadata ? "cyber" : null)
+ && policy.Explanation == (metadata ? "Installed fixture policy" : null),
+ "Installed request journal must preserve the native200 policy kind and full bounded metadata.");
+ var summary = await control.GetAssertionsAsync(cancellationToken);
+ Require(summary.Matched == 1 && summary.ErrorsReturned == 0 && summary.Events.Single().OutputDisposition?.Kind == kind
+ && summary.Events.Single().OutputDisposition?.Explanation == (metadata ? "Installed fixture policy" : null),
+ "Installed runtime evidence must describe committed native policy inference without reporting a generic HTTP error.");
+ if (streaming)
+ {
+ Require(first.TerminalMarkerObserved == true, "Installed native policy SSE must have a real protocol terminal.");
+ var verified = await control.VerifyAsync(new()
+ { Requests = [new() { Query = new() { RequestId = first.RequestId }, RequireStreamingTerminalMarker = true }] }, cancellationToken);
+ Require(verified.Passed, "Installed stream verification must accept actual native policy terminal evidence.");
+ }
+ string recovered;
+ if (chat is not null) { recovered = (await chat.CompleteChatAsync([new UserChatMessage("next")], cancellationToken: cancellationToken)).Value.Content.Single().Text; }
+ else if (responses is not null)
+ {
+ recovered = (await responses.CreateResponseAsync(new CreateResponseOptions
+ { Model = model, StoredOutputEnabled = false, InputItems = { ResponseItem.CreateUserMessageItem("next") } }, cancellationToken)).Value.GetOutputText();
+ }
+ else if (anthropic is not null) { recovered = ((AnthropicMessages.TextBlock)(await anthropic.Messages.Create(AnthropicOptions(), cancellationToken)).Content.Single().Value!).Text; }
+ else if (google is not null)
+ {
+ recovered = (await google.Models.GenerateContentAsync(model, "next", new Google.GenAI.Types.GenerateContentConfig
+ { AutomaticContinuation = false }, cancellationToken: cancellationToken)).Text!;
+ }
+ else { recovered = (await abstraction!.GetResponseAsync([new Microsoft.Extensions.AI.ChatMessage(ChatRole.User, "next")], cancellationToken: cancellationToken)).Text; }
+ Require(recovered == _recovery, "The explicit next inference must select the queued recovery after the policy outcome.");
+ var second = await CompletedTraceAsync(control, 2, cancellationToken);
+ Require(second.OutputDisposition is null && second.StatusCode == 200, "Installed queued recovery must not inherit prior policy metadata.");
+ Require((await control.GetRequestsAsync(cancellationToken: cancellationToken)).TotalObserved == 2
+ && (await control.GetAssertionsAsync(cancellationToken)).Matched == 2,
+ "The original SDK must make exactly two observed, matched attempts with no hidden retries.");
+ }
+
+ private static AnthropicMessages.MessageCreateParams AnthropicOptions() => new()
+ { Model = AnthropicMessages.Model.ClaudeSonnet5_5, MaxTokens = 256, Messages = [new() { Role = AnthropicMessages.Role.User, Content = "policy" }] };
+
+ private static async Task CompletedTraceAsync(LlmTestServerClient control, int count, CancellationToken cancellationToken)
+ {
+ using var watchdog = CancellationTokenSource.CreateLinkedTokenSource(cancellationToken);
+ watchdog.CancelAfter(TimeSpan.FromSeconds(60));
+ while (true)
+ {
+ var evidence = await control.GetRequestsAsync(cancellationToken: watchdog.Token);
+ if (evidence.Requests.Count == count && evidence.Requests.All(trace => trace.IsCompleted))
+ return evidence.Requests.OrderBy(trace => trace.Sequence).Last();
+ await Task.Delay(20, watchdog.Token);
+ }
+ }
+
+ private static void Require(bool condition, string message)
+ { if (!condition) { throw new InvalidOperationException(message); } }
+}
diff --git a/scripts/package-consumer/PackageTests.cs b/scripts/package-consumer/PackageTests.cs
index 6e3b5d8..a1a2645 100644
--- a/scripts/package-consumer/PackageTests.cs
+++ b/scripts/package-consumer/PackageTests.cs
@@ -1,10 +1,12 @@
+using System.Globalization;
using System.Net.Http.Headers;
using System.Text;
using System.Text.Json;
using System.Text.Json.Nodes;
using Aspire.Hosting;
using Aspire.Hosting.Testing;
-using ManagedCode.LlmTck.Aspire;
+using ManagedCode.LlmTestServer.Aspire;
+using ManagedCode.LlmTestServer.Client;
using Microsoft.Playwright;
using TUnit.Core;
using static Microsoft.Playwright.Assertions;
@@ -15,15 +17,11 @@ public sealed class PackageTests
public async Task InstalledPackage_ServesAssetsAndInteractiveDashboard(CancellationToken cancellationToken)
{
var builder = DistributedApplicationTestingBuilder.Create([]);
- var resource = builder.AddLlmTck("package-tck").WithApiKey("test-key");
- if (!resource.Resource.WorkingDirectory.StartsWith(AppContext.BaseDirectory, StringComparison.Ordinal))
- throw new InvalidOperationException("The service must come from the installed package output.");
- if (Directory.GetFiles(resource.Resource.WorkingDirectory, "*.staticwebassets.runtime.json", SearchOption.AllDirectories).Length != 0)
- throw new InvalidOperationException("Package contains a build-machine static assets manifest.");
+ var resource = builder.AddLlmTestServer("package-test-server").WithApiKey("test-key");
await using var app = await builder.BuildAsync(cancellationToken);
await app.StartAsync(cancellationToken);
- await app.ResourceNotifications.WaitForResourceHealthyAsync("package-tck", cancellationToken);
- using var http = app.CreateHttpClient("package-tck", "http");
+ await app.ResourceNotifications.WaitForResourceHealthyAsync("package-test-server", cancellationToken);
+ using var http = app.CreateHttpClient("package-test-server", "http");
http.DefaultRequestHeaders.Authorization = new AuthenticationHeaderValue("Bearer", "test-key");
foreach (var path in new[] { "/health", "/admin-api/models", "/_framework/blazor.web.js", "/_content/Microsoft.FluentUI.AspNetCore.Components/Microsoft.FluentUI.AspNetCore.Components.lib.module.js" })
{
@@ -77,15 +75,51 @@ public async Task InstalledPackage_ServesAssetsAndInteractiveDashboard(Cancellat
if (!(await response.Content.ReadAsStringAsync(cancellationToken)).Contains("0.95", StringComparison.Ordinal))
throw new InvalidOperationException("Installed package lost the native decision fixture: " + model);
}
+ var control = new LlmTestServerClient(http, "test-key");
+ var dashboardDemo = await CreateDashboardCacheDemoAsync(control, http, cancellationToken);
+ var dashboardEvidence = dashboardDemo.NamedConversation;
+ const int defaultMatchedRequests = 4;
+ await using (var session = await control.CreateSessionAsync(config => config.RequireBearerToken("test-key")
+ .UseChatScenario("package-session", scenario => scenario.Responds("isolated package response")), cancellationToken))
+ {
+ using var sessionChat = session.Control.CreateChatClient();
+ var sessionReply = await sessionChat.GetResponseAsync(
+ [new Microsoft.Extensions.AI.ChatMessage(Microsoft.Extensions.AI.ChatRole.User, "session request")], cancellationToken: cancellationToken);
+ if (sessionReply.Text != "isolated package response" || (await session.Control.GetAssertionsAsync(cancellationToken)).Matched != 1
+ || (await control.GetAssertionsAsync(cancellationToken)).Matched != defaultMatchedRequests)
+ throw new InvalidOperationException("Installed package sessions must isolate requests and assertions from the dashboard runtime.");
+ }
+ await VerifyInstalledConversationGraphAsync(control, defaultMatchedRequests, cancellationToken);
+ await VerifyInstalledToolPresetAsync(control, cancellationToken);
using var playwright = await Playwright.CreateAsync();
await using var browser = await playwright.Chromium.LaunchAsync(new() { Headless = true });
- var page = await browser.NewPageAsync();
+ var recordingDirectory = Environment.GetEnvironmentVariable("LLM_TEST_SERVER_DEMO_RECORDING_DIRECTORY");
+ await using var browserContext = await browser.NewContextAsync(new()
+ {
+ ViewportSize = new() { Width = 1440, Height = 1000 },
+ RecordVideoDir = recordingDirectory,
+ RecordVideoSize = recordingDirectory is null ? null : new() { Width = 1440, Height = 1000 },
+ });
+ var recordedScenes = new List