diff --git a/.github/workflows/toc.yaml b/.github/workflows/toc.yaml
deleted file mode 100644
index 28dac912..00000000
--- a/.github/workflows/toc.yaml
+++ /dev/null
@@ -1,10 +0,0 @@
-on: push
-name: TOC Generator
-jobs:
- generateTOC:
- name: TOC Generator
- runs-on: ubuntu-latest
- steps:
- - uses: technote-space/toc-generator@v4
- with:
- TOC_TITLE: ""
diff --git a/README.md b/README.md
index 906b33ea..961d5ca3 100644
--- a/README.md
+++ b/README.md
@@ -1,70 +1,42 @@
-
#  *Adaptive*: Parallel Active Learning of Mathematical Functions
-[](https://mybinder.org/v2/gh/python-adaptive/adaptive/main?filepath=example-notebook.ipynb)
-[](https://anaconda.org/conda-forge/adaptive)
+[](https://github.com/python-adaptive/adaptive/actions/workflows/nox.yml)
+[](https://pypi.org/project/adaptive/)
+[](https://anaconda.org/conda-forge/adaptive)
+[](https://pypi.org/project/adaptive/)
+[](https://adaptive.readthedocs.io/en/latest/)
[](https://codecov.io/gh/python-adaptive/adaptive)
+[](https://anaconda.org/conda-forge/adaptive)
[](https://doi.org/10.5281/zenodo.1182437)
-[](https://adaptive.readthedocs.io/en/latest/?badge=latest)
-[](https://anaconda.org/conda-forge/adaptive)
-[](https://github.com/python-adaptive/adaptive/stargazers)
-[](https://pypi.python.org/pypi/adaptive)
-[](https://pypi.python.org/pypi/adaptive)
+[](https://mybinder.org/v2/gh/python-adaptive/adaptive/main?filepath=example-notebook.ipynb)
-Adaptive is an open-source Python library that streamlines adaptive parallel function evaluations.
-Rather than calculating all points on a dense grid, it intelligently selects the "best" points in the parameter space based on your provided function and bounds.
-With minimal code, you can perform evaluations on a computing cluster, display live plots, and optimize the adaptive sampling algorithm.
-
-Adaptive is most efficient for computations where each function evaluation takes at least ≈50ms due to the overhead of selecting potentially interesting points.
-
-To see Adaptive in action, try the [example notebook on Binder](https://mybinder.org/v2/gh/python-adaptive/adaptive/main?filepath=example-notebook.ipynb) or explore the [tutorial on Read the Docs](https://adaptive.readthedocs.io/en/latest/tutorial/tutorial/).
-
-
-
-Table of contents
-
-
-
-
-- [Key features](#key-features)
-- [Example usage](#example-usage)
- - [Exporting Data](#exporting-data)
-- [Implemented Algorithms](#implemented-algorithms)
-- [Installation](#installation)
- - [Faster triangulation (optional)](#faster-triangulation-optional)
-- [Development](#development)
- - [Documentation](#documentation)
-- [Citing](#citing)
-- [Draft Paper](#draft-paper)
-- [Credits](#credits)
-
-
+`adaptive` is an open-source Python library for adaptive parallel function evaluation.
+You supply a function and its bounds, and `adaptive` evaluates it at the "best" points in parameter space, instead of at *all* points of a dense grid.
+With a few lines of code you can run the evaluations on a computing cluster, live-plot the data as it comes in, and fine-tune the sampling algorithm.
-
+ 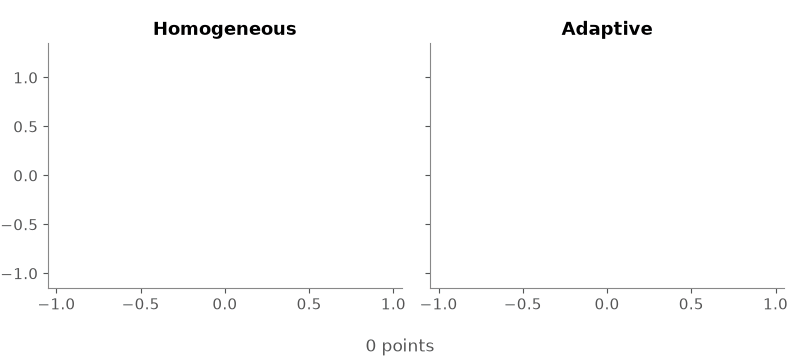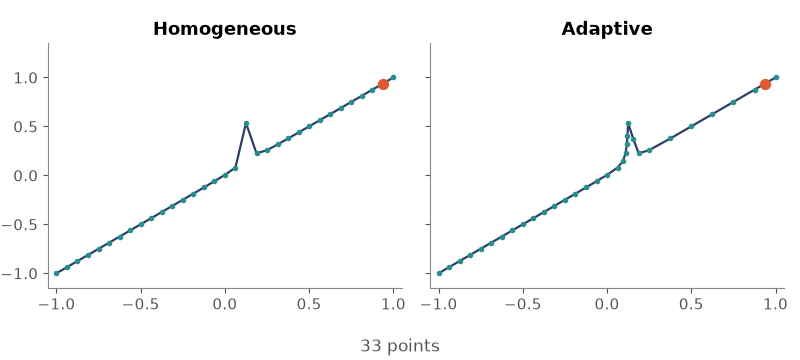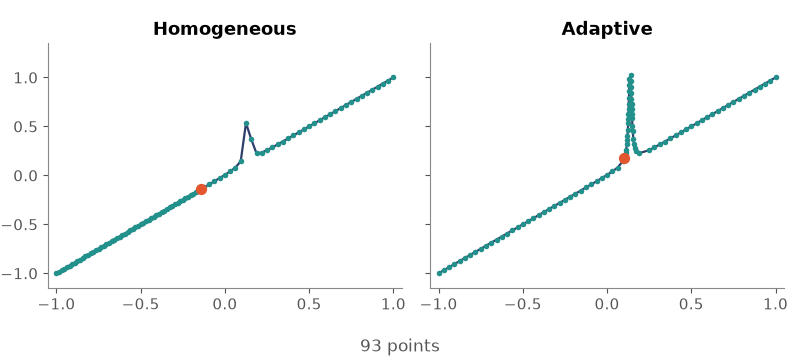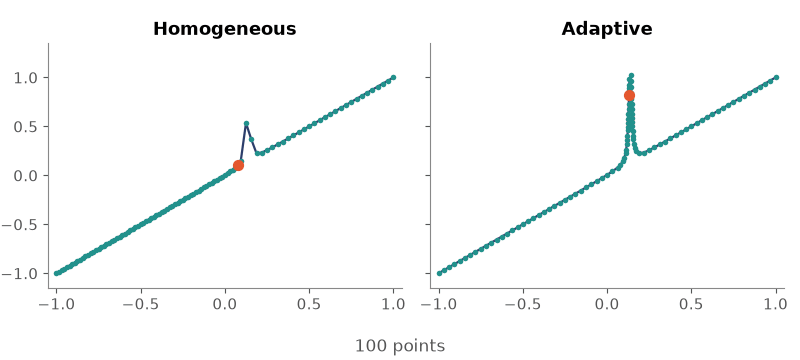 +
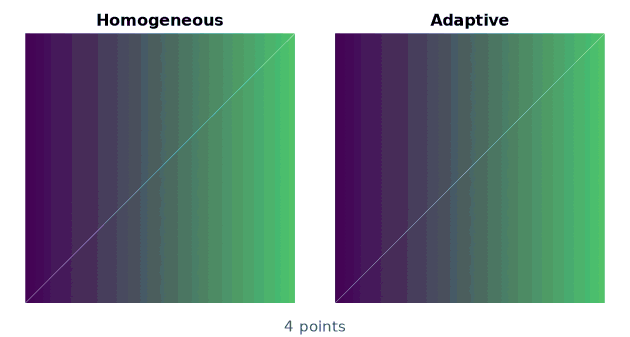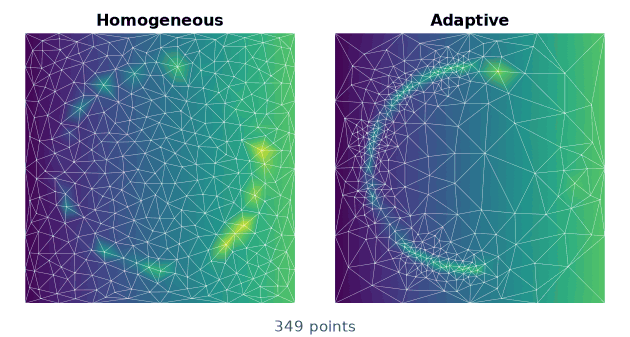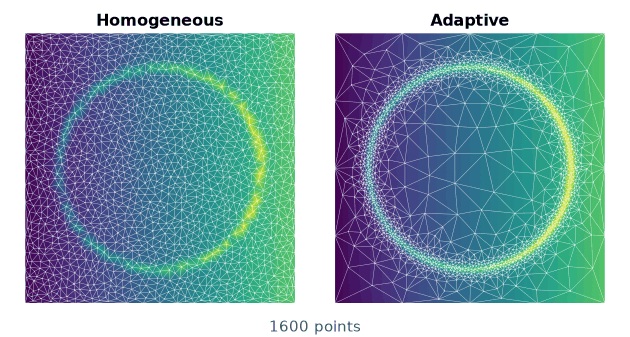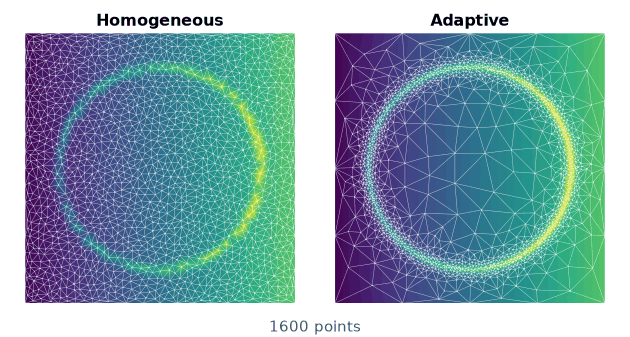 +
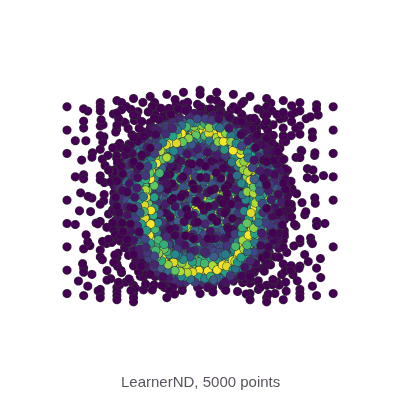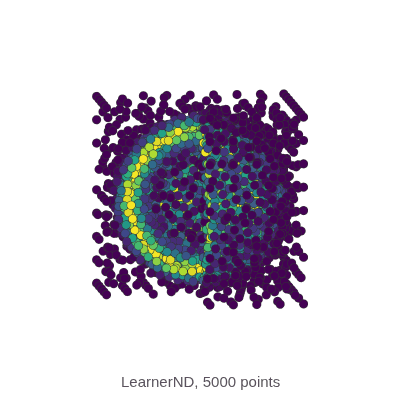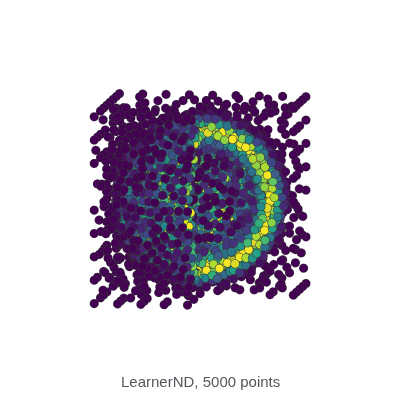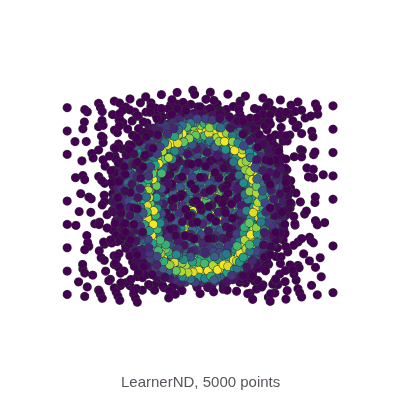 +
-## Example usage
+## Example
-Adaptively learning a 1D function and live-plotting the process in a Jupyter notebook:
+Learning a 1D function and live-plotting the process in a Jupyter notebook:
```python
from adaptive import notebook_extension, Runner, Learner1D
@@ -82,82 +54,82 @@ runner.live_info()
runner.live_plot()
```
-With the same number of points, adaptive sampling resolves features that a homogeneous grid misses:
+The `Runner` works in the background, so the notebook stays usable while it runs.
+In a script, use `BlockingRunner`, which returns once the goal is reached:
-
-
-
-
-
-
-### Exporting Data
+```python
+from adaptive import BlockingRunner, Learner1D
-You can export the learned data as a NumPy array:
-```python
-data = learner.to_numpy()
-```
+def peak(x, a=0.01):
+ return x + a**2 / (a**2 + x**2)
-If you have Pandas installed, you can also export the data as a DataFrame:
-```python
-df = learner.to_dataframe()
+learner = Learner1D(peak, bounds=(-1, 1))
+BlockingRunner(learner, loss_goal=0.01)
+data = learner.to_numpy() # array with columns x, y
```
+`learner.to_dataframe()` returns the same data as a pandas DataFrame (pandas comes with the `[notebook]` extra).
+
-## Implemented Algorithms
+## Implemented algorithms
The core concept in `adaptive` is the *learner*.
-A *learner* samples a function at the most interesting locations within its parameter space, allowing for optimal sampling of the function.
-As the function is evaluated at more points, the learner improves its understanding of the best locations to sample next.
+A learner samples a function at the points in its parameter space that tell it the most about the function.
+As it evaluates more points, it gets a better idea of where to sample next.
-The definition of the "best locations" depends on your application domain.
-While `adaptive` provides sensible default choices, the adaptive sampling process can be fully customized.
+What the "best" points are depends on your application.
+Each learner ranks candidate points with a *loss function*.
+The default losses put more points where the function changes quickly; you can pass a built-in alternative, such as `curvature_loss_function()` or `resolution_loss_function()`, or write your own (see the [custom loss tutorial](https://adaptive.readthedocs.io/en/latest/tutorial/tutorial.custom_loss/)).
The following learners are implemented:
-- `Learner1D`: for 1D functions `f: ℝ → ℝ^N`,
-- `Learner2D`: for 2D functions `f: ℝ^2 → ℝ^N`,
-- `LearnerND`: for ND functions `f: ℝ^N → ℝ^M`,
-- `AverageLearner`: for random variables, allowing averaging of results over multiple evaluations,
-- `AverageLearner1D`: for stochastic 1D functions, estimating the mean value at each point,
-- `IntegratorLearner`: for integrating a 1D function `f: ℝ → ℝ`,
-- `SequenceLearner`: for evaluating a fixed sequence of points while still using the runners, parallelism, and data export of Adaptive.
+- `Learner1D`, for 1D functions `f: ℝ → ℝ^N`,
+- `Learner2D`, for 2D functions `f: ℝ^2 → ℝ^N`,
+- `LearnerND`, for ND functions `f: ℝ^N → ℝ^M`,
+- `AverageLearner`, for random variables where you want to average the result over many evaluations,
+- `AverageLearner1D`, for stochastic 1D functions where you want to estimate the mean value of the function at each point,
+- `IntegratorLearner`, for when you want to integrate a 1D function `f: ℝ → ℝ`,
+- `SequenceLearner`, for when you want to evaluate a fixed sequence of points while still using the runners and data export of `adaptive`.
Meta-learners (to be used with other learners):
-- `BalancingLearner`: for running several learners at once, selecting the "most optimal" one each time you get more points,
-- `DataSaver`: for when your function doesn't return just a scalar or a vector.
+- `BalancingLearner`, for when you want to run several learners at once, selecting the "best" one each time you get more points,
+- `DataSaver`, for when your function doesn't just return a scalar or a vector.
-In addition to learners, `adaptive` offers primitives for parallel sampling across multiple cores or machines, with built-in support for:
+In addition to the learners, `adaptive` provides primitives for running the sampling across several cores and even several machines, with built-in support for
[concurrent.futures](https://docs.python.org/3/library/concurrent.futures.html),
[mpi4py](https://mpi4py.readthedocs.io/en/stable/mpi4py.futures.html),
[loky](https://loky.readthedocs.io/en/stable/),
[ipyparallel](https://ipyparallel.readthedocs.io/en/latest/), and
[distributed](https://distributed.readthedocs.io/en/latest/).
+By default, both runners evaluate the function in parallel on all cores of the local machine, using loky.
+To use one of the others, pass it as `executor`, for example `Runner(learner, executor=distributed.Client())`; the [parallelism tutorial](https://adaptive.readthedocs.io/en/latest/tutorial/tutorial.parallelism/) has an example for each.
+
## Installation
-`adaptive` works with Python 3.11 and higher on Linux, Windows, or Mac, and provides optional extensions for working with Jupyter.
+`adaptive` works with Python 3.11 and higher on Linux, Windows, and macOS.
-The recommended way to install adaptive is using `conda`:
+Install it with `conda`:
```bash
conda install -c conda-forge adaptive
```
-`adaptive` is also available on PyPI:
+or from PyPI:
```bash
-pip install "adaptive[notebook]"
+pip install adaptive
```
-The `[notebook]` above also installs the optional dependencies for live plotting and widgets in JupyterLab and Jupyter Notebook; no extra Jupyter extensions need to be installed.
+Add the `[notebook]` extra (`pip install "adaptive[notebook]"`) for live plotting and widgets in JupyterLab and Jupyter Notebook, and for `to_dataframe()`; no Jupyter extensions are needed.
### Faster triangulation (optional)
@@ -167,7 +139,7 @@ Installing the optional [adaptive-triangulation](https://github.com/python-adapt
pip install "adaptive[rust]"
```
-No code changes are needed — the Rust backend is detected and used automatically.
+No code changes are needed. The Rust backend is detected and used automatically.
To control the selection, pass `LearnerND(..., triangulation_backend="python" | "rust" | "auto")` per learner, or set the environment variable `ADAPTIVE_TRIANGULATION_BACKEND=python` to force the pure-Python implementation globally (or to `rust` to make a missing Rust backend an error instead of a silent fallback).
## Development
@@ -175,30 +147,24 @@ To control the selection, pass `LearnerND(..., triangulation_backend="python" |
Clone the repository and install it in editable mode with the optional dependencies:
```bash
-git clone git@github.com:python-adaptive/adaptive.git
+git clone https://github.com/python-adaptive/adaptive.git
cd adaptive
pip install -e ".[notebook,test,other]"
```
We recommend a virtual environment, for example with [uv](https://docs.astral.sh/uv/) (`uv sync --extra notebook --extra test --extra other`) or Conda.
-To avoid polluting the history with notebook output, set up the git filter by running:
-
-```bash
-python ipynb_filter.py
-```
-
-in the repository.
-
-To maintain consistent code style, we use [pre-commit](https://pre-commit.com). Install it by running:
+We use [pre-commit](https://pre-commit.com) for a consistent code style; install the hooks with
```bash
pre-commit install
```
-in the repository.
+Run the tests with `pytest`.
-### Documentation
+If you edit `example-notebook.ipynb`, install `nbconvert` and run `python ipynb_filter.py` once, so git strips the notebook output on commit.
+
+### Building the documentation
The documentation is built with [Zensical](https://zensical.org).
The executable pages in `docs/notebooks/` are Jupyter notebooks in [jupytext's MyST Markdown format](https://jupytext.readthedocs.io/en/latest/formats-markdown.html).
@@ -209,11 +175,11 @@ uv run --group docs python docs/build_notebooks.py
uv run --group docs zensical serve # preview on http://localhost:8000
```
-The animations in this README are rendered from real learner runs with `uv run --group docs python docs/make_animations.py` (requires `ffmpeg` and Chrome or Chromium).
+The README animations are made from real learner runs with `uv run --group docs python docs/make_animations.py`, which needs `ffmpeg` and Chrome or Chromium.
## Citing
-If you used Adaptive in a scientific work, please cite it as follows.
+If you used `adaptive` in a scientific work, please cite it as follows.
```bib
@misc{Nijholt2019,
@@ -225,22 +191,19 @@ If you used Adaptive in a scientific work, please cite it as follows.
}
```
-## Draft Paper
-
-If you're interested in the scientific background and principles behind Adaptive, we recommend taking a look at the [draft paper](https://github.com/python-adaptive/paper) that is currently being written.
-This paper provides a comprehensive overview of the concepts, algorithms, and applications of the Adaptive library.
+The algorithms are described in more detail in a [draft paper](https://github.com/python-adaptive/paper).
## Credits
We would like to give credits to the following people:
-- Pedro Gonnet for his implementation of [CQUAD](https://www.gnu.org/software/gsl/manual/html_node/CQUAD-doubly_002dadaptive-integration.html), “Algorithm 4” as described in “Increasing the Reliability of Adaptive Quadrature Using Explicit Interpolants”, P. Gonnet, ACM Transactions on Mathematical Software, 37 (3), art. no. 26, 2010.
-- Pauli Virtanen for his `AdaptiveTriSampling` script (no longer available online since SciPy Central went down) which served as inspiration for the `adaptive.Learner2D`.
+- Pedro Gonnet for his implementation of [CQUAD](https://www.gnu.org/software/gsl/doc/html/integration.html#cquad-doubly-adaptive-integration), "Algorithm 4" as described in "Increasing the Reliability of Adaptive Quadrature Using Explicit Interpolants", P. Gonnet, ACM Transactions on Mathematical Software, 37 (3), art. no. 26, 2010.
+- Pauli Virtanen for his `AdaptiveTriSampling` script (no longer available online since SciPy Central went down), which served as inspiration for `adaptive.Learner2D`.
For general discussion, we have a [Gitter chat channel](https://gitter.im/python-adaptive/adaptive).
-If you find any bugs or have any feature suggestions please file a GitHub [issue](https://github.com/python-adaptive/adaptive/issues/new) or submit a [pull request](https://github.com/python-adaptive/adaptive/pulls).
+If you find any bugs or have any feature suggestions, please file a GitHub [issue](https://github.com/python-adaptive/adaptive/issues/new) or submit a [pull request](https://github.com/python-adaptive/adaptive/pulls).
diff --git a/docs/_static/extra.css b/docs/_static/extra.css
index cc89dcd4..d1473e0a 100644
--- a/docs/_static/extra.css
+++ b/docs/_static/extra.css
@@ -44,6 +44,12 @@
[data-md-color-scheme="slate"] .md-typeset .nb-output:has([data-root-id]:not(:empty)),
[data-md-color-scheme="slate"] .md-typeset .nb-output:has(.plotly-graph-div),
[data-md-color-scheme="slate"] .md-typeset .nb-output:has(.jupyter-widgets) {
+ /* light theme colors, so e.g. the `live_info` table is not dark inside */
+ --md-default-bg-color: #ffffff;
+ --md-default-fg-color: #000000de;
+ --md-typeset-color: #000000de;
+ --md-typeset-table-color: #0000001f;
+ --md-typeset-table-color--light: #00000009;
background: #ffffff;
color: #000000;
border-radius: 0.4rem;
diff --git a/docs/index.md b/docs/index.md
index d8d64d9d..fb89608c 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -22,5 +22,3 @@ hide:
[Start the tutorial](tutorial/tutorial.Learner1D.md){ .md-button .md-button--primary }
[See the examples](algorithms_and_examples.md){ .md-button }
[API reference](reference/adaptive.md){ .md-button }
-
---8<-- "README.md:key-features"
diff --git a/docs/notebooks/tutorial/tutorial.parallelism.md b/docs/notebooks/tutorial/tutorial.parallelism.md
index f6daeefd..782b8b3c 100644
--- a/docs/notebooks/tutorial/tutorial.parallelism.md
+++ b/docs/notebooks/tutorial/tutorial.parallelism.md
@@ -45,8 +45,6 @@ runner.live_plot()
## `distributed.Client`
-On Windows by default [`adaptive.Runner`][adaptive.Runner] uses a `distributed.Client`.
-
```python
import distributed
diff --git a/zensical.toml b/zensical.toml
index e51cdc87..b88f8831 100644
--- a/zensical.toml
+++ b/zensical.toml
@@ -134,6 +134,9 @@ code = "JetBrains Mono"
[project.theme.icon]
repo = "fontawesome/brands/github"
+[project.extra]
+generator = false # no "Made with Zensical" in the footer
+
[[project.extra.social]]
icon = "fontawesome/brands/github"
link = "https://github.com/python-adaptive/adaptive"